Cached at:
10/01/26, 02:55 PM
# Generalization Dynamics of LM Pre-training
Source: [https://www.alphaxiv.org/abs/2609.33150](https://www.alphaxiv.org/abs/2609.33150)
During pre\-training, language models are often judged by smoothly falling training loss and improving scores on familiar benchmarks\. Those trends can conceal abrupt changes in*how*a model answers\. A model may follow a tempting pattern in a prompt rather than infer the task, then switch back a nearby checkpoint later\. On an "answer\+1" arithmetic prompt, OLMo3\-32B scores 81% at 2\.17T pre\-training tokens, 0% at 2\.19T, and 81\.7% at 2\.21T\. On this eval, a success means the answer consistent with the arithmetic beats the tempting successive\-pattern answer\. The authors call this behavior**mode\-hopping**\. The arithmetic reversal is one task\-specific illustration, and it does not show that every kind of generalization reverses this way\.
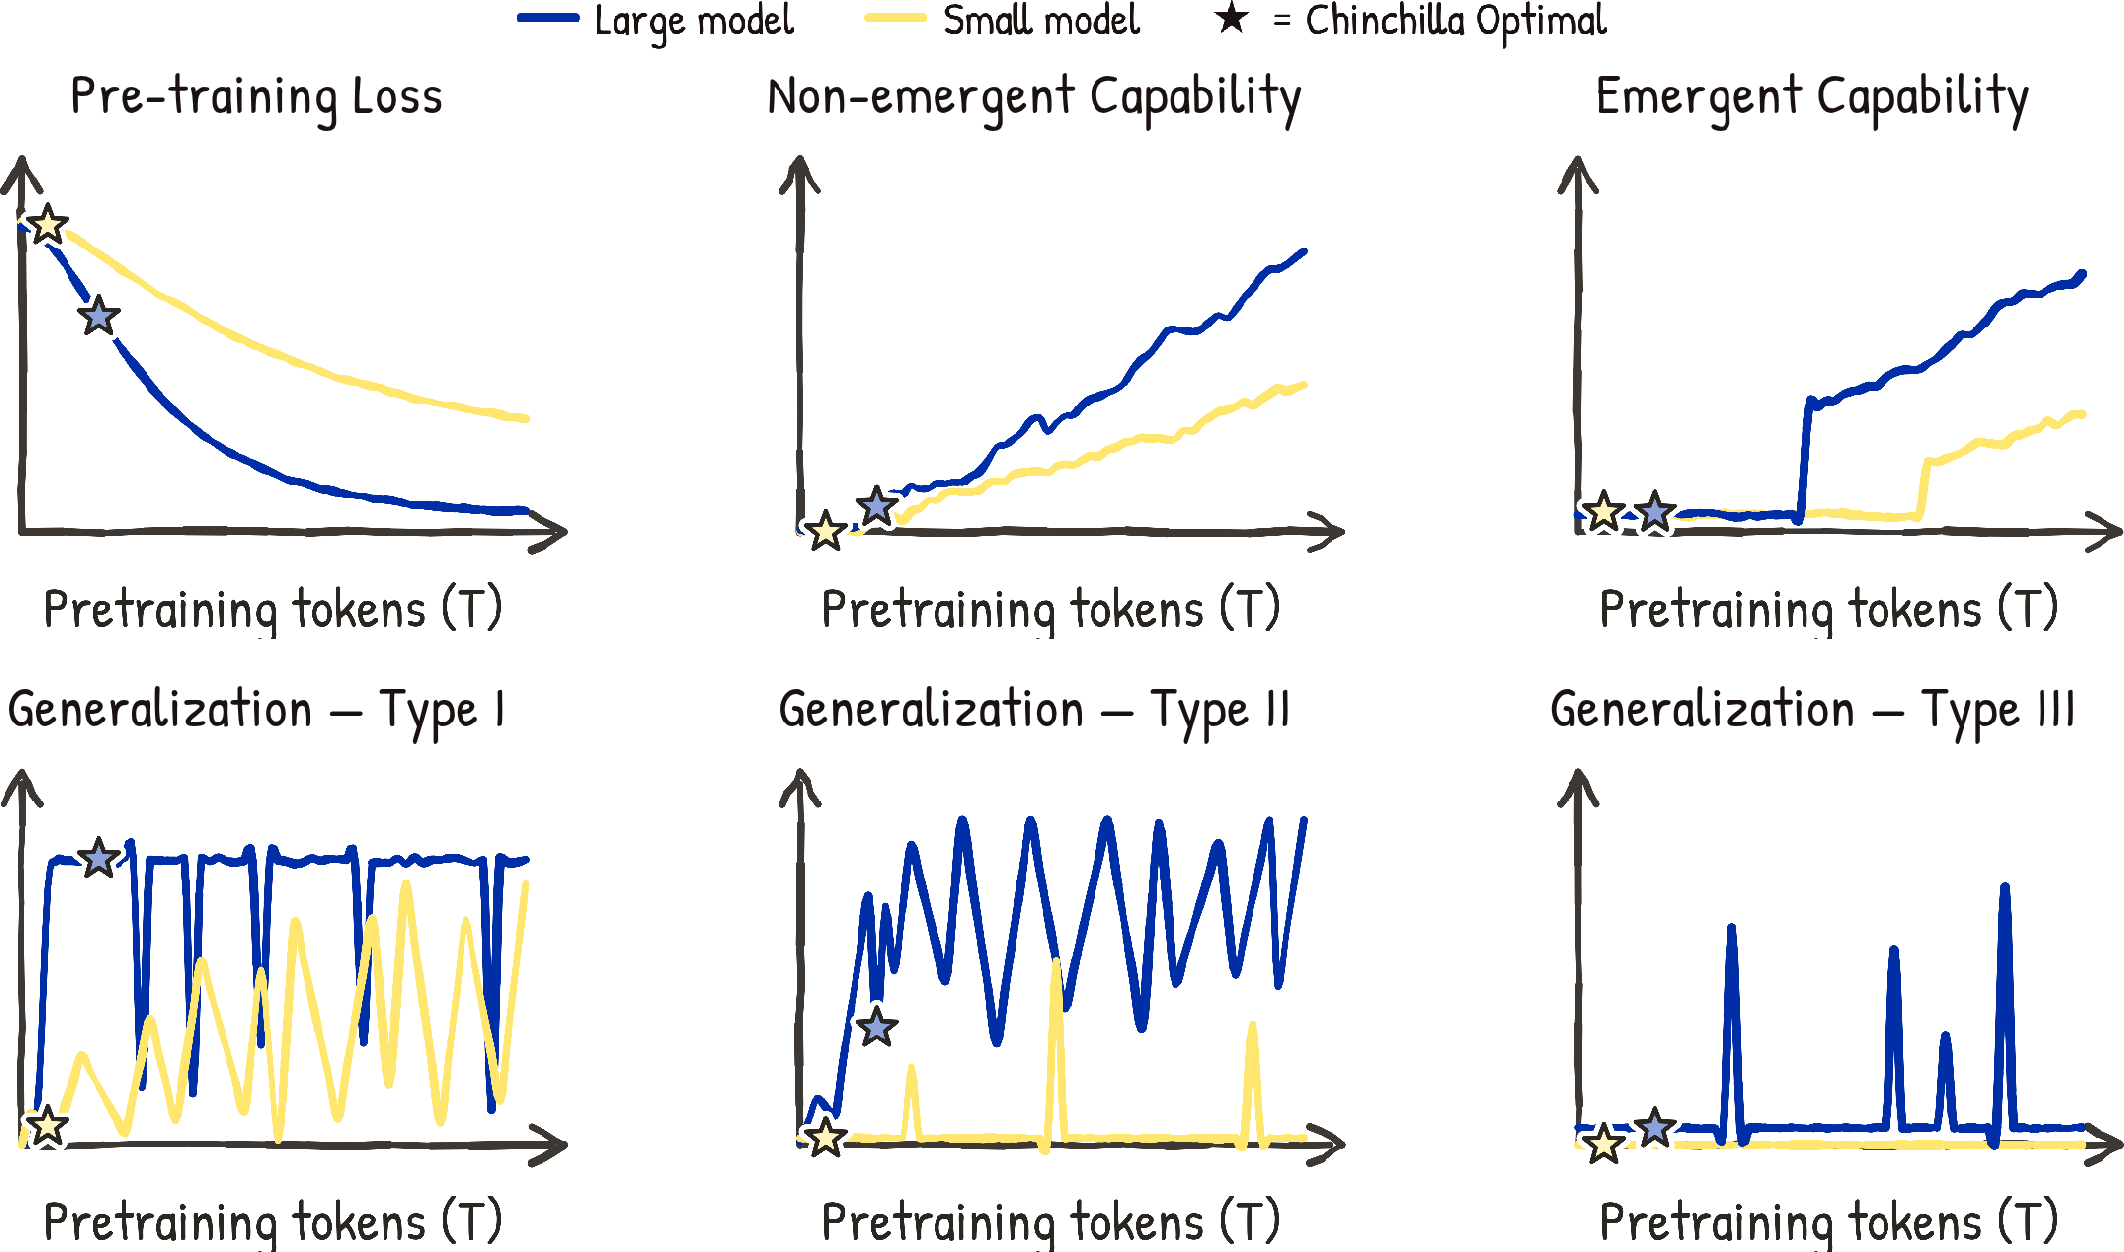Schematic\. Top row: pre\-training loss, non\-emergent downstream capability, and emergent downstream capability\. Bottom row: three generalization types\.Here, generalization means inferring the task or transferable structure rather than following a shallow cue\. The authors built a suite of six cheap, zero\- or few\-shot behavioral tests, plus two fine\-tuning generalization tests\. The tests contrast:
- flipped labels versus familiar sentiment patterns;
- repeated or successive prompt answers versus solving the presented problem;
- truth versus truthiness;
- intuitive wrong answers versus reflective reasoning;
- disconnected facts versus a coherent persona\.
In the arithmetic case, the demonstrations yield 1, 2, 3\. The test arithmetic answer is 8, and the tempting continuation is 4\.
The prompt\-based tests compare probabilities of predefined answer spans instead of relying on the model to generate extractable answers\. Their results are averaged over four random seeds\. Multi\-hop persona QA works differently because it is generative\. It has only five test questions per persona, which are sampled repeatedly\.
The study tracks general pre\-training checkpoints of OLMo3 and Apertus and excludes mid\-training and long\-context stages\. The authors report that these models had trained for 9×–90× Chinchilla\-optimal budgets\.
Schaeffer et al\., in["Are Emergent Abilities of Large Language Models a Mirage?"](https://www.alphaxiv.org/abs/2304.15004), argue that discontinuous or nonlinear evaluation metrics can make smooth output changes look like sudden emergence\. Wen et al\. rule out that simple reading in two ways:
- They find mode\-hopping in hard accuracy and also in the soft probability marginP\(correct\)−P\(incorrect\)P\(\\text\{correct\}\) \- P\(\\text\{incorrect\}\)\.
- They find it when plotting against pre\-training FLOPs as well as against tokens\.
Common benchmark performance, by contrast, stays stable across pre\-training\.
A second check tests whether single updates cause the hopping\. The authors take one OLMo3\-32B optimization step on randomly sampled pre\-training data, varying batch size and learning rate\. Suite probabilities change negligibly, even at learning rate 1e\-2\. Averaging five checkpoints along an oscillating curve mitigates mode\-hopping but leaves it in place\.
These tests argue against a simple explanation in terms of local optimization fluctuations, but they do not identify the cause\. The results are also dataset\-specific: the average correlation across dataset pairs is usually low, though larger models have higher correlations\.
Using their toy suite, the authors select OLMo3\-32B checkpoints at 4\.5T and 4\.9T tokens\. After math SFT, the 4\.5T checkpoint scores 36\.3% on GPQA versus 29\.8% for the 4\.9T checkpoint\. After general post\-training, its robustness to prefilling attacks is 53% versus 21%\. The 4\.5T checkpoint also beats the other sampled checkpoints in this comparison, even though later pre\- or mid\-training can improve in\-distribution performance\. Under these post\-training setups, an intermediate checkpoint can be a better starting point\. The results do not show that earlier checkpoints win in general\.
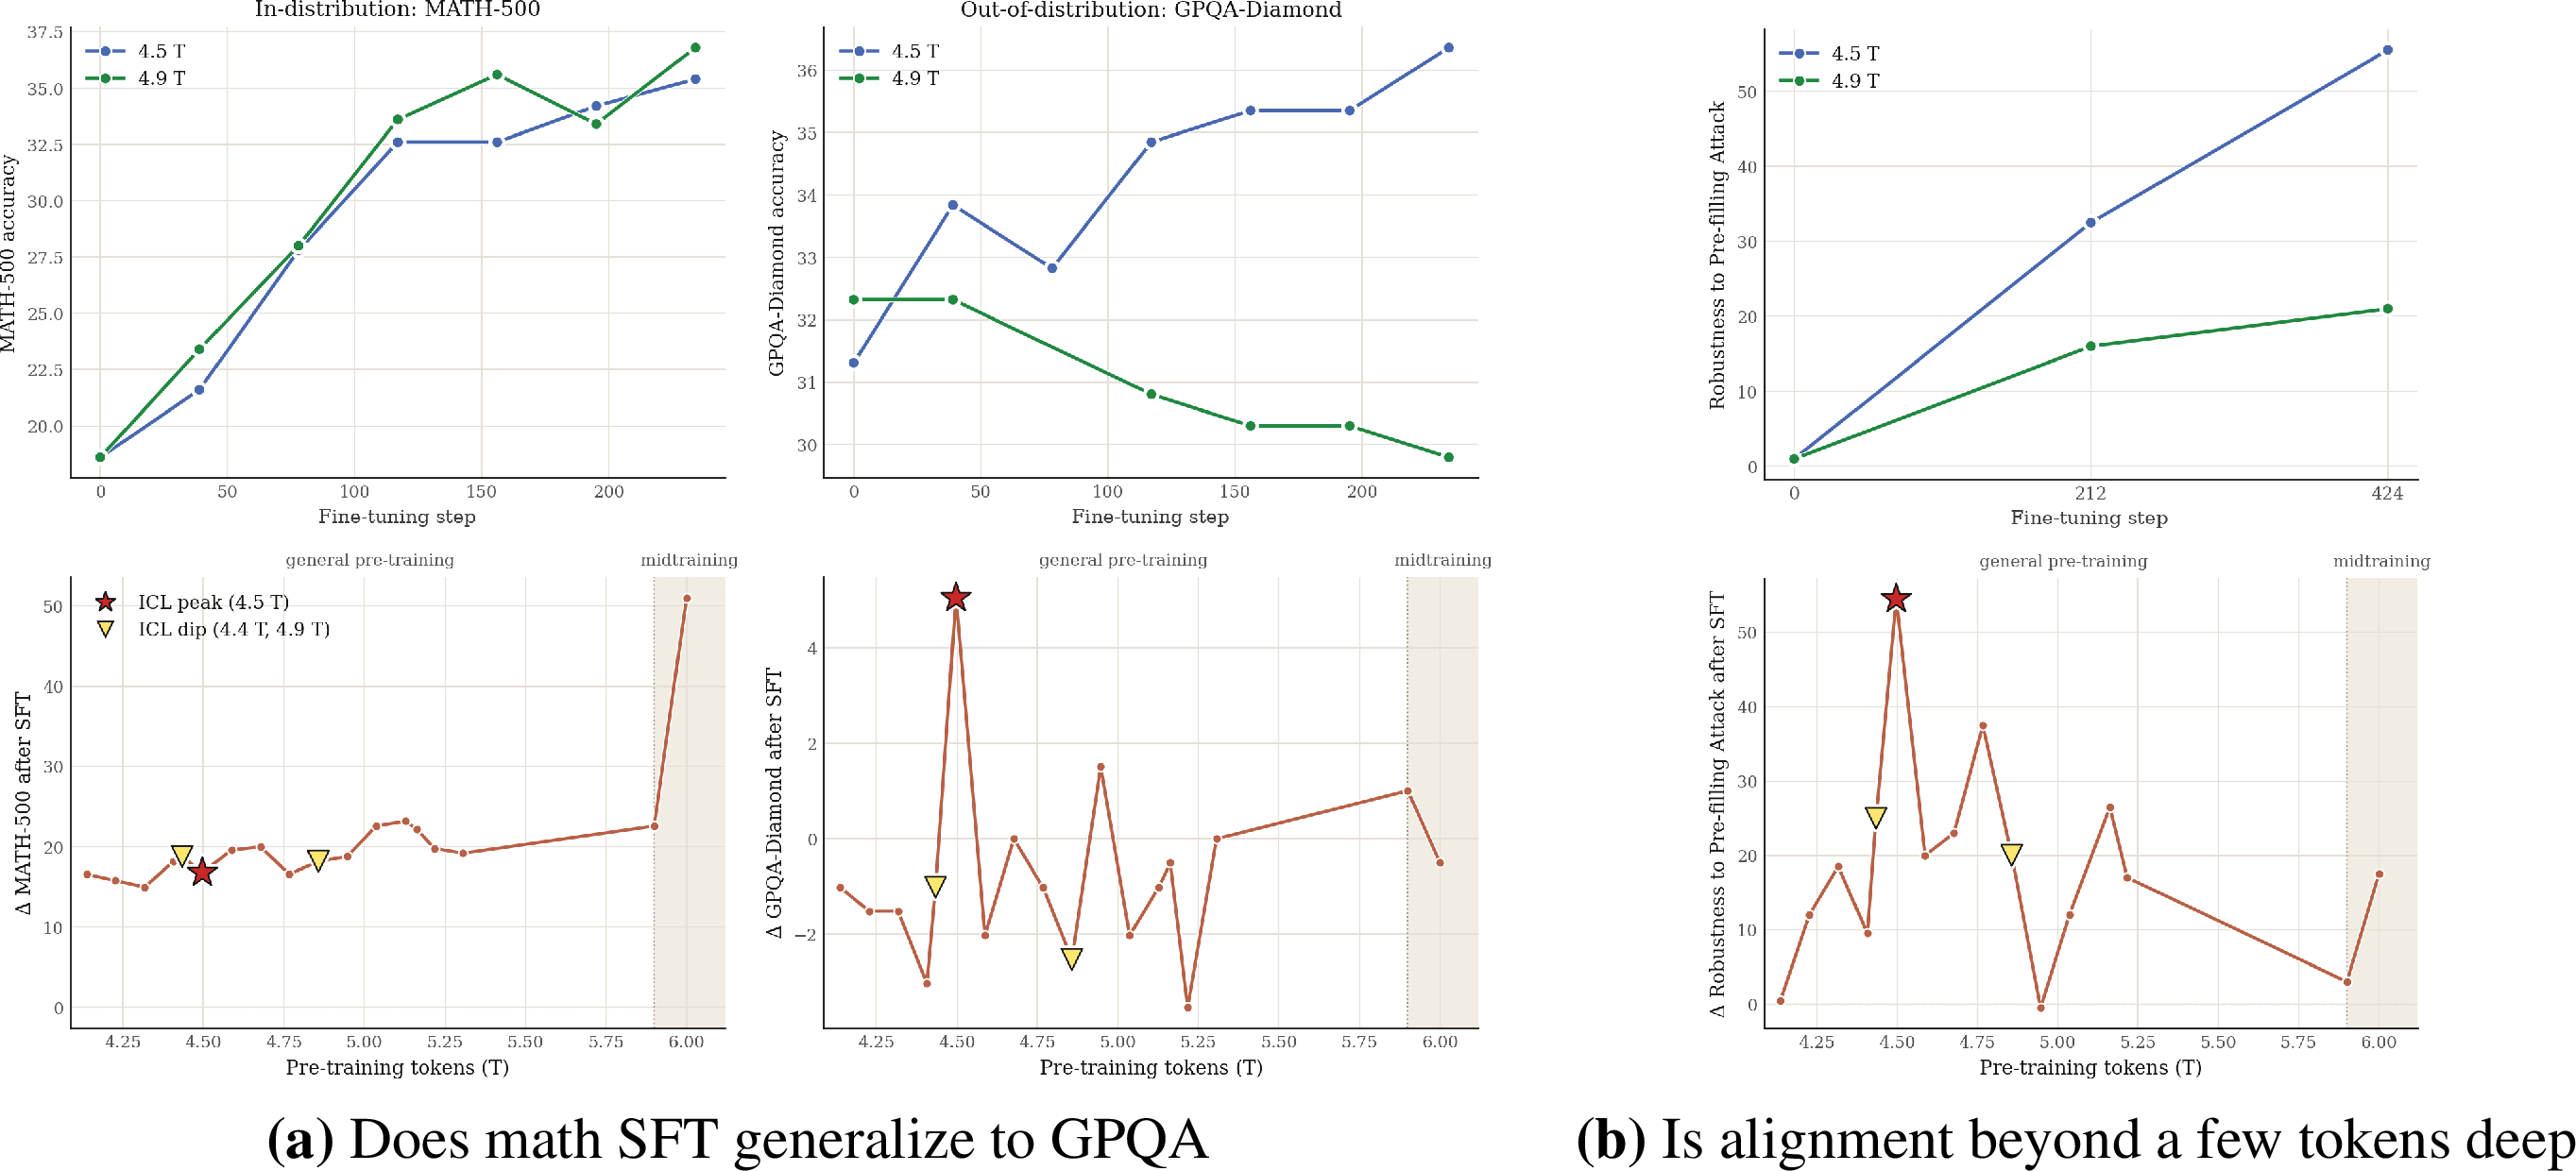Top: fine\-tuning step against MATH\-500 accuracy, GPQA\-Diamond accuracy, and robustness to prefilling attack, comparing 4\.5T and 4\.9T checkpoints\. Bottom: the corresponding measures against pre\-training tokens \(T\), marking the selected high/low in\-context\-learning checkpoints\.A preliminary, small\-scale experiment on one eval tested whether training data can steer this behavior\. Starting from an intermediate OLMo3\-32B checkpoint, the authors continued training on three kinds of data:
- randomly sampled data \(the uncontrolled run\);
- subsets chosen because earlier windows favored pattern\-matching on the answer\+1 eval;
- subsets chosen because earlier windows favored generalization on that eval\.
The controlled runs stabilize toward their intended behavior, while the uncontrolled run hops\.
The authors interpret these findings as competition between shallow and generalizable circuits in capacity\-bounded models\. This is their hypothesis\. The experiments demonstrate behavioral changes, not the circuits themselves\.
Generalization is not guaranteed to mature steadily with more training\. The suite is a cheap behavioral monitor that reveals reversals\. In the reported applications, it helped choose a checkpoint and, with data selection, steer one targeted behavior\. The suite is available in a[GitHub repository](https://github.com/Jiaxin-Wen/GDsuite)\.