netease-youdao/Confucius4-R2T2
Summary
Confucius4-R2T2 is a low-latency, high-accuracy real-time speech recognition model developed by NetEase Youdao, featuring configurable chunking and stable output for applications like live captioning.
View Cached Full Text
Cached at: 09/21/26, 08:55 AM
netease-youdao/Confucius4-R2T2 · Hugging Face
Source: https://huggingface.co/netease-youdao/Confucius4-R2T2
Confucius4-R2T2: A Low Latency and High Accuracy Real-Time Speech Recognition Model
Real Real-Time Transcription



Confucius4-R2T2 is a low-latency and high-accuracy true streaming Automatic Speech Recognition (ASR) model that features fine-grained and configurable decoding chunks from 80 ms to 2 s. The model operates in append-only output mode: committing transcript text permanently without revising previous words, which is critical for applications where text must be processed or acted upon instantly. This results in a smoother user experience, avoiding disruptive text revisions and visual flickering in real-time applications, such as Real-Time Live Captioning & Subtitling, Downstream NLP Pipelines & LLM Agents, Simultaneous Speech Translation, etc.
R2T2, short for Real Real-Time Transcription, is built upon the Qwen3-ASR model. And it is trained with a unique set of data construction techniques including stable-prefix data, forced time-alignment data, and token-level audio segmentation. Combined with a Longest Stable Prefix (LSP) learning paradigm (tech report will be released soon), R2T2 can dynamically determine when a stable prefix can be safely emitted and when additional audio context is needed. By exposing only stable prefixes, the model provides high-quality context that conditions subsequent predictions while guaranteeing that previously emitted text remains unchanged. Despite its streaming design, R2T2 maintains strong accuracy in offline recognition.
- Low-latency and high accuracy streaming recognition— The model achieves accuracy close to that of offline recognition, with only 200 to 600 milliseconds average latency.
- Stable streaming output— Emitted text is committed as it arrives and remains unchanged.
- Configurable low-latency chunking- Supports decoding chunks from 80 ms to 2 s for different latency/accuracy trade-offs.
- No loss in offline accuracy— Adding streaming support does not degrade offline recognition accuracy.
- vLLM backend— Provides high-throughput inference. A Hugging Face
transformersbackend is also available. - Context and hotword prompts— Natively supported.
- Multilingual support— Optimized forChinese and English, while also supporting a broad range of additional languages.
Experimental results show that R2T2 achieves state-of-the-art (SOTA) performance in both latency and recognition quality among a range of open-source models, while remaining competitive with leading closed-source systems. TheGitHub repositoryprovides inference code, a minimal usage example, and a vLLM-based backend supporting both offline and real-time streaming inference.
https://huggingface.co/netease-youdao/Confucius4-R2T2#table-of-contentsTable of Contents
- Overview
- Demo- Side-by-side comparison with GPT-Live-Transcribe - Additional resources
- Evaluation- Streaming performance - Accuracy- English - Chinese
- Installation- Clone the repository - Option 1: Conda - Option 2: uv
- Docker (recommended)- 1. Start a container - 2. Run the example inside the container - 3. Manage the container
- Quick Start- Configuration
- Python API- Offline transcription (vLLM backend) - Streaming transcription (vLLM backend)
- WebSocket Server- Start and stop the server - WebSocket endpoint - Message format - Example client
- Supported Languages
- Community & Contact- WeChat Group - Discord Server - Business contact - GitHub Issues
- Acknowledgements
- Citation
- License
https://huggingface.co/netease-youdao/Confucius4-R2T2#overviewOverview
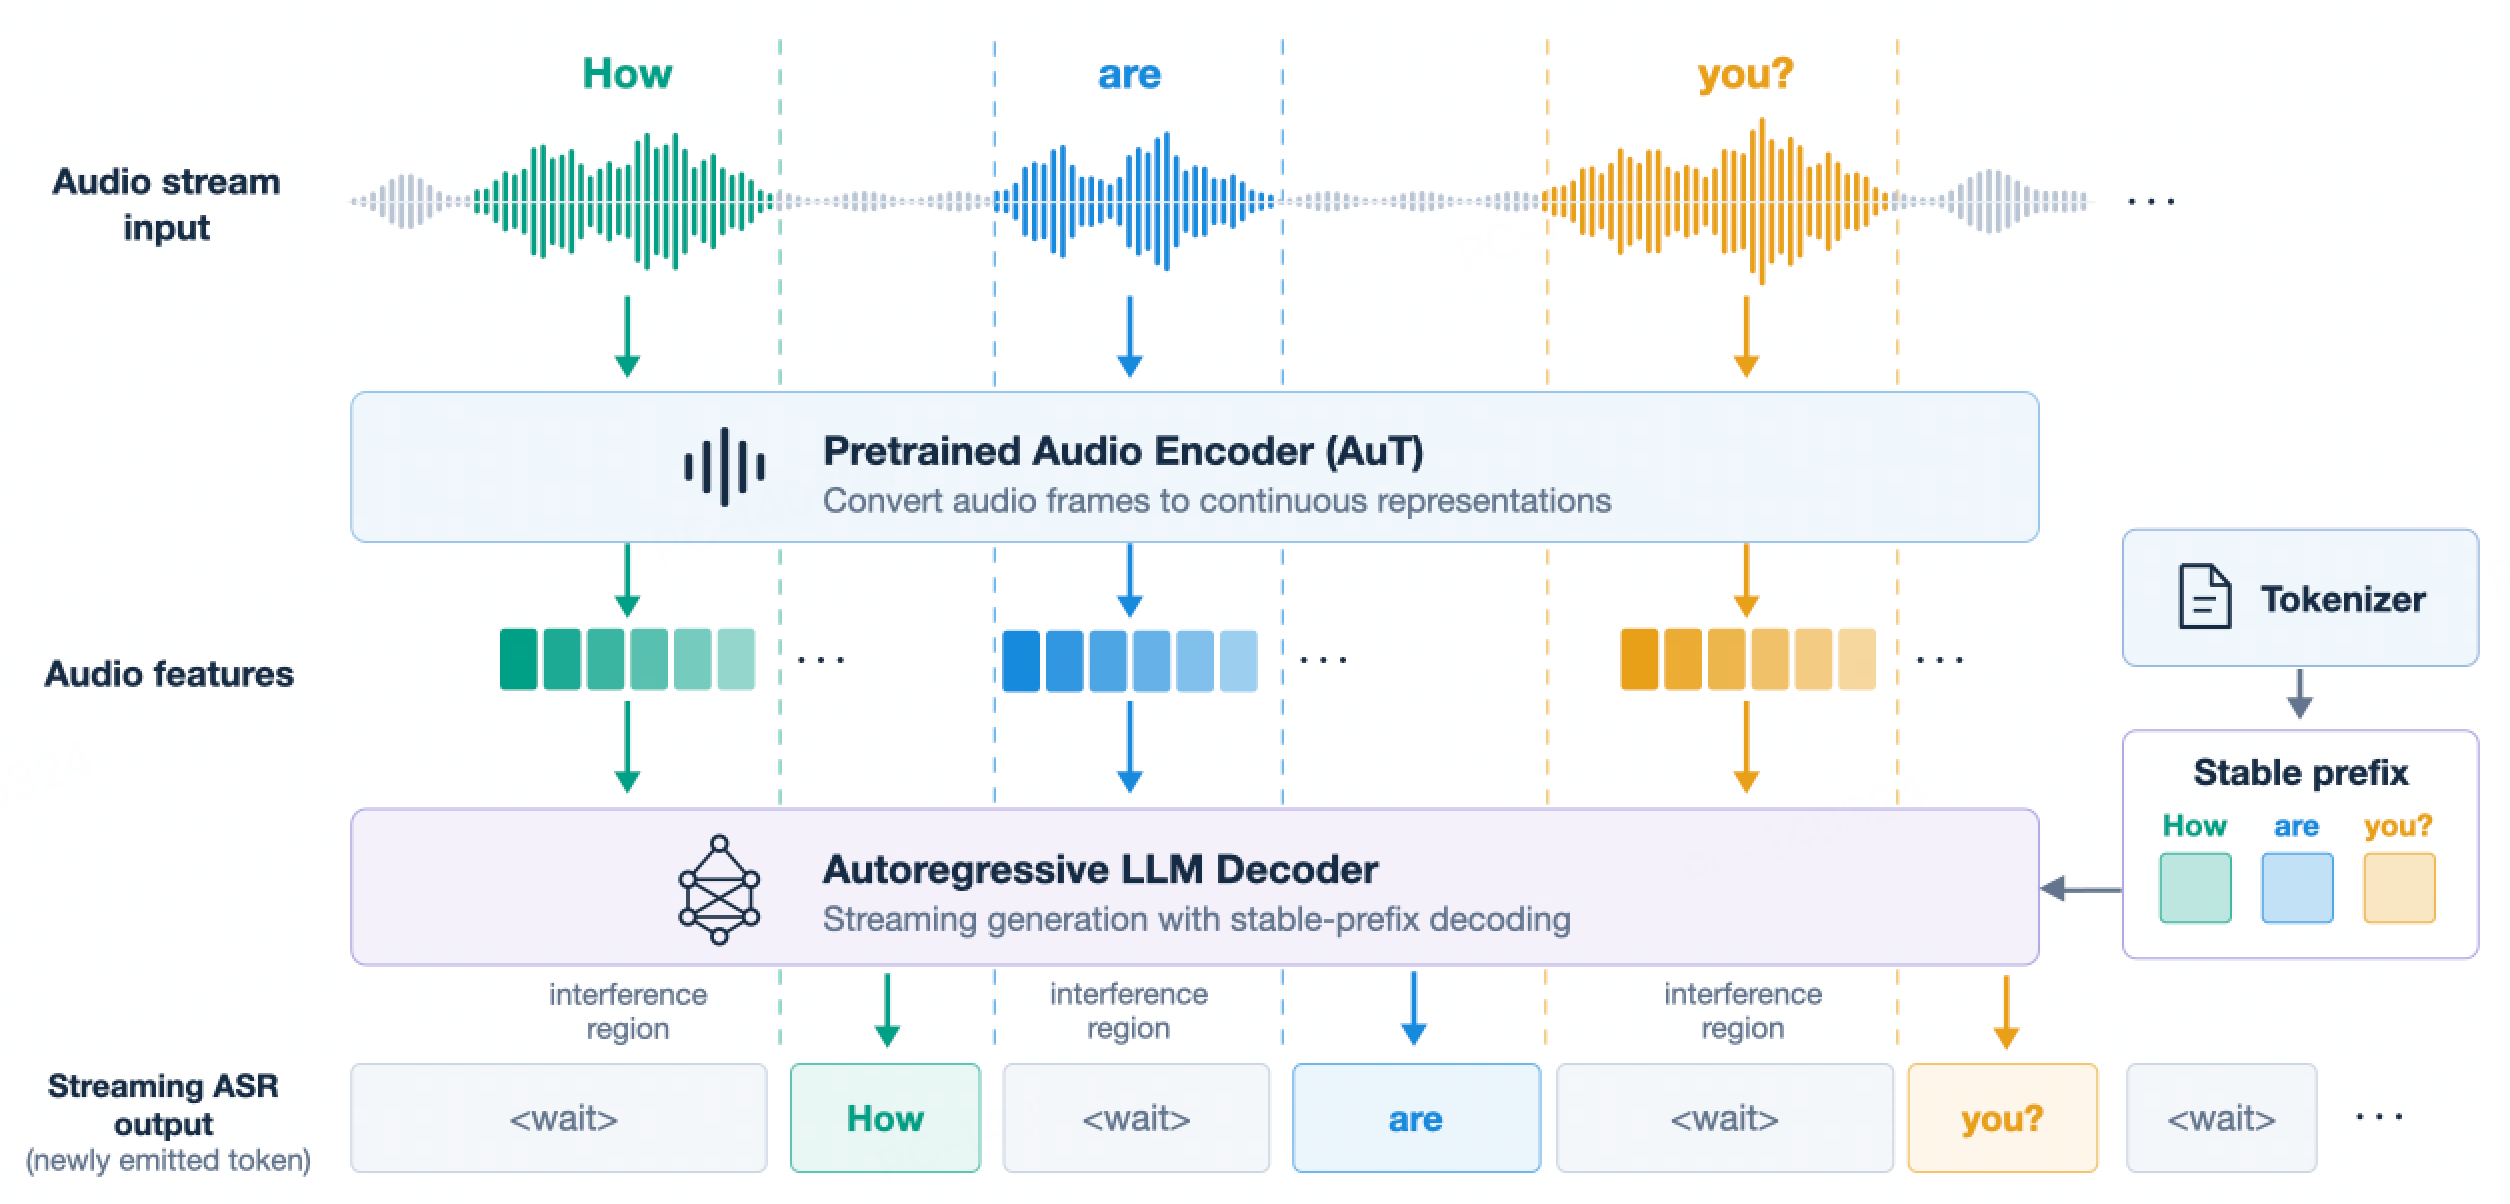
Figure 1. Overall framework of R2T2.
https://huggingface.co/netease-youdao/Confucius4-R2T2#demoDemo
https://huggingface.co/netease-youdao/Confucius4-R2T2#side-by-side-comparison-with-gpt-live-transcribeSide-by-side comparison with GPT-Live-Transcribe
Your browser does not support embedded video.Watch the comparison video
Figure 2. GPT-Live-Transcribe and R2T2 processing the same audio, shown together in real time — a side-by-side comparison.
https://huggingface.co/netease-youdao/Confucius4-R2T2#additional-resourcesAdditional resources
More demonstrations, comparisons, and supporting resources will be added here.
https://huggingface.co/netease-youdao/Confucius4-R2T2#evaluationEvaluation
If you are an author or maintainer of a model included in these comparisons and have questions or concerns about the results, please feel free to contact us through theGitHub issue tracker. We are happy to share evaluation details and work with you to verify or correct them.
https://huggingface.co/netease-youdao/Confucius4-R2T2#streaming-performanceStreaming performance
The streaming API supports decoding chunks from 80 ms to 2 s; the figures below show representative WER/latency trade-offs at 160 ms.
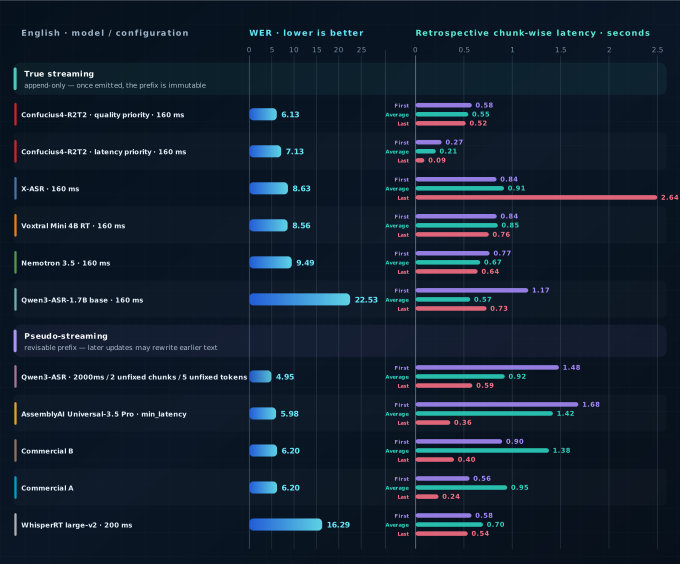
Figure 3. English WER and retrospective chunk-wise latency across model and configuration settings.
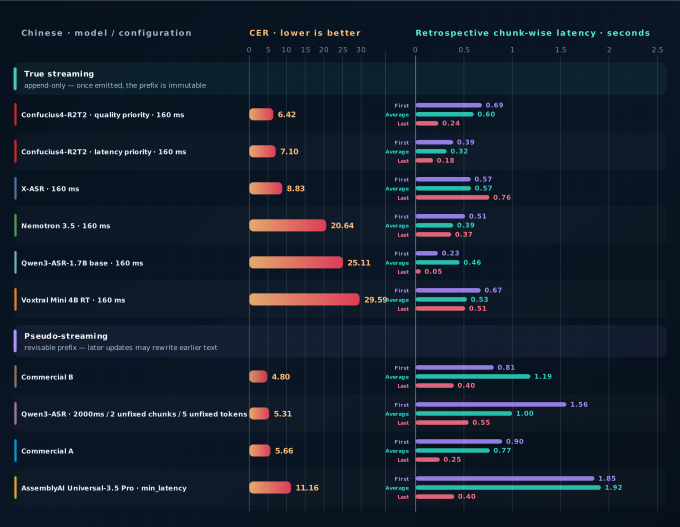
Figure 4. Chinese CER and retrospective chunk-wise latency across model and configuration settings.
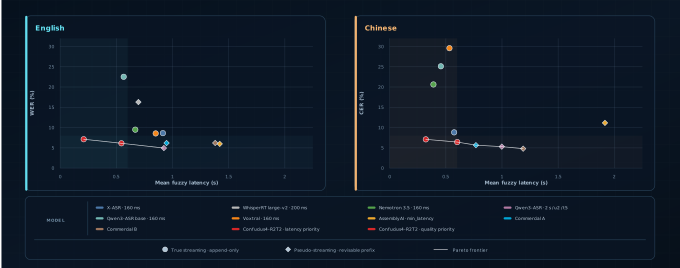
Figure 5. Accuracy-latency Pareto frontier. Lower-left is better; the frontier uses retrospective chunk-wise mean fuzzy latency.
https://huggingface.co/netease-youdao/Confucius4-R2T2#accuracyAccuracy
English results use WER (%), and Chinese results use CER (%); lower is better.
※ Pseudo-streaming model: its partial transcript may revise previously emitted text; unmarked models use true streaming, append-only output.
https://huggingface.co/netease-youdao/Confucius4-R2T2#englishEnglish
DatasetQwenR2T2 (Ours) 160msOpen-sourceProprietaryQwen3-ASR※ 2s/u2/t5Qwen3-ASR base 160msX-ASR 160msWhisperRT※ 200msNemotron 160msVoxtral 160msAssemblyAI※ min_latencyCommercial A※Commercial B※AMI9.2524.7911.3714.4124.1918.1115.9412.0013.278.44Giga-clean8.6124.379.6010.2613.8112.6711.139.218.849.46LS-clean1.6722.302.133.864.703.712.491.891.731.25LS-other3.5425.744.889.649.868.277.153.373.572.48SPGI2.9022.253.005.148.663.933.062.143.061.74VoxPopuli3.0220.713.075.688.285.696.304.753.173.14Earnings226.6829.729.3615.9535.0817.2211.667.4710.328.96TED-LIUM2.3319.183.343.756.675.114.603.233.083.30EN-RealSI6.5413.758.408.9735.3610.6914.759.738.7317.05
https://huggingface.co/netease-youdao/Confucius4-R2T2#chineseChinese
DatasetQwenR2T2 (Ours) 160msOpen-sourceProprietaryQwen3-ASR※ 2s/u2/t5Qwen3-ASR base 160msX-ASR 160msWhisperRT※ 200msNemotron 160msVoxtral 160msAssemblyAI※ min_latencyCommercial A※Commercial B※Wenet-net4.9419.795.878.81U24.7023.5312.915.134.79Wenet-meeting5.9720.387.2711.33U20.1860.5411.847.073.75SPEECHIO-066.1024.507.307.86U22.5232.1615.085.675.34SPEECHIO-076.1921.168.2011.22U24.2822.9710.846.456.46CN-RealSI3.3439.723.484.92U11.528.745.153.993.64
https://huggingface.co/netease-youdao/Confucius4-R2T2#installationInstallation
We recommend using afresh, isolated environment. For local development and source installation, use theCondaoruvenvironment below.Dockeris recommended for quickly running the project with a preconfigured CUDA and runtime environment — seeDocker.
https://huggingface.co/netease-youdao/Confucius4-R2T2#clone-the-repositoryClone the repository
git clone https://github.com/netease-youdao/Confucius4-R2T2.git
cd Confucius4-R2T2
https://huggingface.co/netease-youdao/Confucius4-R2T2#option-1-condaOption 1: Conda
conda create -n confucius4-r2t2 python=3.12 -y
conda activate confucius4-r2t2

# Install the package with the vLLM backend
pip install -e .
https://huggingface.co/netease-youdao/Confucius4-R2T2#option-2-uvOption 2: uv
uv venv --python 3.12
source .venv/bin/activate

# Install the package with the vLLM backend
uv pip install -e .
Python 3.10+ is supported. Python 3.12 is the version we test against.
vLLM has strict CUDA / PyTorch compatibility requirements. If the install fails to resolve, check the version matrix on thevLLM websiteand pin a combination that matches your CUDA runtime.
https://huggingface.co/netease-youdao/Confucius4-R2T2#docker-recommendedDocker (recommended)
R2T2 runs out of the box on the officialQwen3-ASRDocker image, which already ships every runtime library we need.
Pre-built image:qwenllm/qwen3-asr.
Before you begin, install theNVIDIA Container Toolkitto enable GPU access from Docker. If Docker Hub access is slow or unreliable in your region, you may need to configure a registry mirror.
https://huggingface.co/netease-youdao/Confucius4-R2T2#1-start-a-container1. Start a container
LOCAL_WORKDIR=/path/to/your/workspace   # host path that will be mounted into the container
HOST_PORT=8000
CONTAINER_PORT=80

docker run --gpus all --name confucius4-r2t2 \
    -v /var/run/docker.sock:/var/run/docker.sock \
    -p $HOST_PORT:$CONTAINER_PORT \
    --mount type=bind,source=$LOCAL_WORKDIR,target=/data/shared/confucius4-r2t2 \
    --shm-size=4gb \
    -it qwenllm/qwen3-asr:latest
Your local workspace ($LOCAL\_WORKDIR) — including a checkout of this repository and the R2T2 checkpoint — will be mounted inside the container at/data/shared/confucius4\-r2t2. Host port8000is mapped to container port80; services running inside the container must bind to0\.0\.0\.0(not127\.0\.0\.1) for port forwarding to work.
https://huggingface.co/netease-youdao/Confucius4-R2T2#2-run-the-example-inside-the-container2. Run the example inside the container
Once inside the container’s shell:
cd /data/shared/confucius4-r2t2/Confucius4-R2T2
MODEL_PATH=/data/shared/confucius4-r2t2/Confucius4-R2T2 \
    ./run_example.sh /path/to/audio.wav
https://huggingface.co/netease-youdao/Confucius4-R2T2#3-manage-the-container3. Manage the container
# re-enter after exiting
docker start confucius4-r2t2
docker exec -it confucius4-r2t2 bash

# remove completely
docker rm -f confucius4-r2t2
https://huggingface.co/netease-youdao/Confucius4-R2T2#quick-startQuick Start
Grab any audio file (mono or stereo, any sample rate — it is resampled to 16 kHz internally) and run:
./run_example.sh /path/to/audio.wav \
    --model_path /path/to/Confucius4-R2T2 \
    --infer_mode stream_vllm \
    --language Chinese \
    --chunk_size_ms 160
Logs are written torun\_example\.logby default. Run\./run\_example\.sh \-\-helpto see the full flag list.
https://huggingface.co/netease-youdao/Confucius4-R2T2#configurationConfiguration
run\_example\.shreads the following environment variables (all optional):
VariableDefaultDescriptionMODEL\_PATH(required)Path or HF repo id of the R2T2 checkpointAUDIOfirst CLI argumentPath to the input audio fileINFER\_MODE``stream\_vllm``stream\_vllmoronetime\_vllm``LANGUAGE``ChineseLanguage hint (e.g.Chinese,English, …)CHUNK\_SIZE\_MS``160Streaming chunk size (80 ms–2 s supported)UNFIXED\_TOKEN\_NUM``1Number of unfixed trailing tokens (rollback window)CONTEXT``""Context / hotword hint prepended to the promptCUDA\_VISIBLE\_DEVICES``0GPU id(s) to exposeLOG\_FILE``run\_example\.logWhere to write logs
You can also callexample\.pydirectly and pass any of these as flags (\-\-audio,\-\-model\_path,\-\-infer\_mode,\-\-language,\-\-chunk\_size\_ms,\-\-lookahead\_ms,\-\-unfixed\_token\_num,\-\-context).
https://huggingface.co/netease-youdao/Confucius4-R2T2#python-apiPython API
Audio inputs can be passed as a local path, a URL, base64 data, or a\(np\.ndarray, sr\)tuple. Batched inference is supported. Remember to wrap vLLM code underif \_\_name\_\_ == '\_\_main\_\_':to avoid thespawnerror described invLLM Troubleshooting.
https://huggingface.co/netease-youdao/Confucius4-R2T2#offline-transcription-vllm-backendOffline transcription (vLLM backend)
import librosa
from qwen_asr import Qwen3ASRModel

if __name__ == "__main__":
    asr = Qwen3ASRModel.LLM(
        model="/path/to/Confucius4-R2T2",
        gpu_memory_utilization=0.5,
        max_inference_batch_size=32,
        max_new_tokens=4096,
    )

    wav, sr = librosa.load("path/to/audio.wav", sr=16000, mono=True)

    results = asr.transcribe(
        audio=[(wav, 16000)],
        language=["Chinese"],       # or [None]
        return_time_stamps=False,
    )
    print(results[0].language, results[0].text)
https://huggingface.co/netease-youdao/Confucius4-R2T2#streaming-transcription-vllm-backendStreaming transcription (vLLM backend)
import librosa
from qwen_asr import Qwen3ASRModel

if __name__ == "__main__":
    asr = Qwen3ASRModel.LLM(
        model="/path/to/Confucius4-R2T2",
        gpu_memory_utilization=0.4,
        max_new_tokens=4,           # keep small for low-latency streaming
    )

    wav, sr = librosa.load("path/to/audio.wav", sr=16000, mono=True)

    state = asr.init_streaming_state(
        context="",                 # optional hotword / topic hint
        language="Chinese",         # or None
        unfixed_chunk_num=0,
        unfixed_token_num=1,
        chunk_size_sec=0.16,
    )

    step = int(0.16 * 16000)
    for pos in range(0, len(wav), step):
        seg = wav[pos : pos + step]
        _, text = asr.streaming_transcribe(seg, state, max_new_tokens=2)
        print("text:", text)

    asr.finish_streaming_transcribe(state)
    print("final:", state.text)
For a complete streaming example with adaptivemax\_new\_tokensand initial-chunk lookahead handling, seeexample\.py.
https://huggingface.co/netease-youdao/Confucius4-R2T2#websocket-serverWebSocket Server
For real-time, multi-client streaming ASR, theGitHub repositoryships a ready-to-run WebSocket server (ws\_server\.py), a launcher script (run\_start\_server\.sh), and a reference Python client (ws\_client\.py).
https://huggingface.co/netease-youdao/Confucius4-R2T2#start-and-stop-the-serverStart and stop the server
# Start with a VAD model
./run_start_server.sh start \
    --model_path /path/to/Confucius4-R2T2 \
    --vad_model_path /path/to/Stream-VAD \
    --port 8272 \
    --gpu 0

# Stop
./run_start_server.sh kill

# Restart in one step
./run_start_server.sh restart \
    --model_path /path/to/Confucius4-R2T2 \
    --vad_model_path /path/to/Stream-VAD \
    --port 8272 \
    --gpu 0
FlagEnv varDefaultDescription\-m,\-\-model\_path``ASR\_MODEL\_PATH(required)Path or HF repo id of the R2T2 checkpoint\-v,\-\-vad\_model\_path``VAD\_MODEL\_PATH``checkpoints/vad/Stream\-VADPath to the FireRedVAD Stream-VAD model\-p,\-\-port``PORT``8272Port the WebSocket server binds to\-g,\-\-gpu``CUDA\_VISIBLE\_DEVICES``0GPU id(s) exposed to the server process\-h,\-\-host``HOST\_TAG``localhostHost tag used only in the log file name
The launcher resolves its own directory, so it can be invoked from anywhere. Logs are written tonohup\_service\_ws\_<host\_tag\>\_<port\>\.login the current directory. The FireRedVAD model is available fromHugging Face. We recommend downloading the model files into this repository’scheckpointsdirectory:
# The FireRedVAD repo ships several detectors, but only the streaming one is
# needed. Both commands below keep the `Stream-VAD/` folder name, so the files
# land in checkpoints/vad/Stream-VAD with no extra nesting.

# Option A — hf CLI (pip install -U "huggingface_hub[cli]")
hf download FireRedTeam/FireRedVAD \
    --include "Stream-VAD/*" \
    --local-dir checkpoints/vad

# Option B — git clone
git clone https://huggingface.co/FireRedTeam/FireRedVAD
cp -r FireRedVAD/Stream-VAD checkpoints/vad/
Either command leaves the model atcheckpoints/vad/Stream\-VAD, which is exactly what\-\-vad\_model\_pathdefaults to — so you can drop the flag entirely.
https://huggingface.co/netease-youdao/Confucius4-R2T2#websocket-endpointWebSocket endpoint
PathBehavior/asr\_stream\_api\_v1Streaming ASR. Each message’stextis the**new (incremental)**chunk.
https://huggingface.co/netease-youdao/Confucius4-R2T2#message-formatMessage format
Client → Server:
- Send raw 16 kHz mono PCM as
int16binary frames (the reference client uses ≈160 ms per frame, i.e. 2560 samples × 2 bytes). - Send the string
"YOUDAO\_ONETIME\_ASR\_STREAM\_EOS"to signal end-of-audio; the server will emit any final text and close.
**Server → Client:**JSON messages of the form
{
  "status": "success",
  "requestId": "<uuid>",
  "msg": {
    "text": "hello",
    "reset": false,
    "asr_cost_ms": 35.4,
    "total_cost_ms": 42.0
  }
}
textis the newly recognized (incremental) segment since the previous message. Concatenate them client-side to get the full transcript.
https://huggingface.co/netease-youdao/Confucius4-R2T2#example-clientExample client
ws\_client\.pyis a minimal example that streams a WAV file to the server and prints the responses.
# Uses the default URI (ws://localhost:8272/asr_stream_api_v1) and built-in sample audio
python ws_client.py

# Point at a custom endpoint and audio file
python ws_client.py \
    --uri wss://your.host/asr_stream_api_v1 \
    --audio resources/test.wav \
    --save service_ws_test \
    --audio-id test.wav
Command-line options:
FlagEnv varDefaultDescription\-\-uri/\-u``ASR\_WS\_URI``ws://localhost:8272/asr\_stream\_api\_v1WebSocket endpoint to connect to.\-\-audio/\-a—built-in sample pathInput audio file (WAV, 16 kHz mono recommended).\-\-save/\-s—service\_ws\_testFile to append the final transcript to.\-\-audio\-id—basename of\-\-audioIdentifier written next to the result in\-\-save.
https://huggingface.co/netease-youdao/Confucius4-R2T2#supported-languagesSupported Languages
R2T2 is optimized for streaming recognition in Chinese and English. Beyond these primary languages, it retains useful cross-lingual streaming capability on languages such as French, German, Italian, Japanese, Korean, Portuguese, Russian, Spanish, Arabic, etc.
https://huggingface.co/netease-youdao/Confucius4-R2T2#community–contactCommunity & Contact
Join our community to ask questions, share ideas, and connect with other users and developers.
https://huggingface.co/netease-youdao/Confucius4-R2T2#wechat-groupWeChat Group
Scan the QR code below to join our WeChat group:
https://huggingface.co/netease-youdao/Confucius4-R2T2#discord-serverDiscord Server
https://huggingface.co/netease-youdao/Confucius4-R2T2#business-contactBusiness contact
For high-concurrency, production-grade, domestically deployable, or private deployment solutions, as well as business inquiries and partnership opportunities, please feel free to contact us through the channels below.
- Phone:+86 010-82558901
- Email:[email protected]
https://huggingface.co/netease-youdao/Confucius4-R2T2#github-issuesGitHub Issues
We also welcome discussions in this repository’sIssuessection. Feel free to ask questions, report bugs, or suggest improvements!
https://huggingface.co/netease-youdao/Confucius4-R2T2#acknowledgementsAcknowledgements
We sincerely thank the Alibaba Qwen team for open-sourcing theQwen3-ASRmodeling code, which provides the architectural foundation for R2T2.
https://huggingface.co/netease-youdao/Confucius4-R2T2#citationCitation
If you use this repository or the R2T2 checkpoint in your research, please citeConfucius4-R2T2(this project):
@misc{Confucius4-R2T2,
  title        = {Confucius4-R2T2: A Low Latency and High Accuracy Real-Time Speech Recognition Model},
  author       = {NetEase Youdao},
  year         = {2026},
  howpublished = {https://github.com/netease-youdao/Confucius4-R2T2}
}
https://huggingface.co/netease-youdao/Confucius4-R2T2#licenseLicense
R2T2 usesdual licensingto distinguish the source code from the model weights:
- Codein the accompanying GitHub repository is released under theApache License 2.0and is free to use, modify, and redistribute (including commercially) under the terms of that license.
- Model weightsare released under theNetEase Model Use License Agreement.
Similar Articles
@NetEaseYouDaoAI: Most streaming ASR gives you text fast. R2T2 gives you text you can act on. We’re open-sourcing Confucius4-R2T2, a 1.7B…
NetEase Youdao AI is open-sourcing Confucius4-R2T2, a 1.7B frontier real-time streaming ASR model designed for voice agents, featuring low latency, high accuracy, and configurable decoding chunks.
@rohanpaul_ai: Voice agents should consume speech incrementally but only act on committed text, because a fast transcript that mutates…
NetEase Youdao open-sourced Confucius4-R2T2, a streaming ASR model for voice agents that incrementally processes speech and emits only committed text to prevent state corruption.
@Gorden_Sun: NetEase Youdao open-sources Confucius4-TTS, a 1.3B TTS model, supports multilingual, supports voice cloning, good results, very fast. Github: https://github.com/netease-youdao/Confucius4-TTS… Online demo: …
NetEase Youdao open-sourced the 1.3B parameter Confucius4-TTS model, supporting zero-shot voice cloning and cross-lingual speech synthesis in 14 languages, fast and with excellent results.
@svpino: This new model does something really cool: It turns speech into text as you speak. This is different from every other a…
R2T2 is a low-latency and high-accuracy real-time speech recognition model that processes audio in small chunks and commits text without revision, suitable for applications like live captioning and translation.
@DataChaz: @NVIDIA just quietly dropped an incredibly impressive speech recognition model that completely changes the math for loc…
NVIDIA quietly released Nemotron-3.5-ASR, a lightweight 0.6B parameter open-source speech recognition model designed for real-time streaming with support for 40+ languages, low latency, and cache-aware architecture.