Shoehorn is a developer tool that quantizes language models to perfectly fit within a machine's available memory, achieving up to 99.99% memory usage efficiency for local inference.
Working on Mac, Linux, and Windows now. I include a simple GUI to find new models and get things built and set up. It is working quite well across a few models for me. The GitHub README and DESIGN.md files go into detail of the how/why and it's working remarkably well so far. <a href="https://github.com/notactuallytreyanastasio/shoehorn" rel="nofollow">https://github.com/notactuallytreyanastasio/shoehorn</a>
# shoehorn — make any language model fit your machine
Source: [https://notactuallytreyanastasio.github.io/shoehorn/](https://notactuallytreyanastasio.github.io/shoehorn/)
Make any language model fit the memory you actually have\.
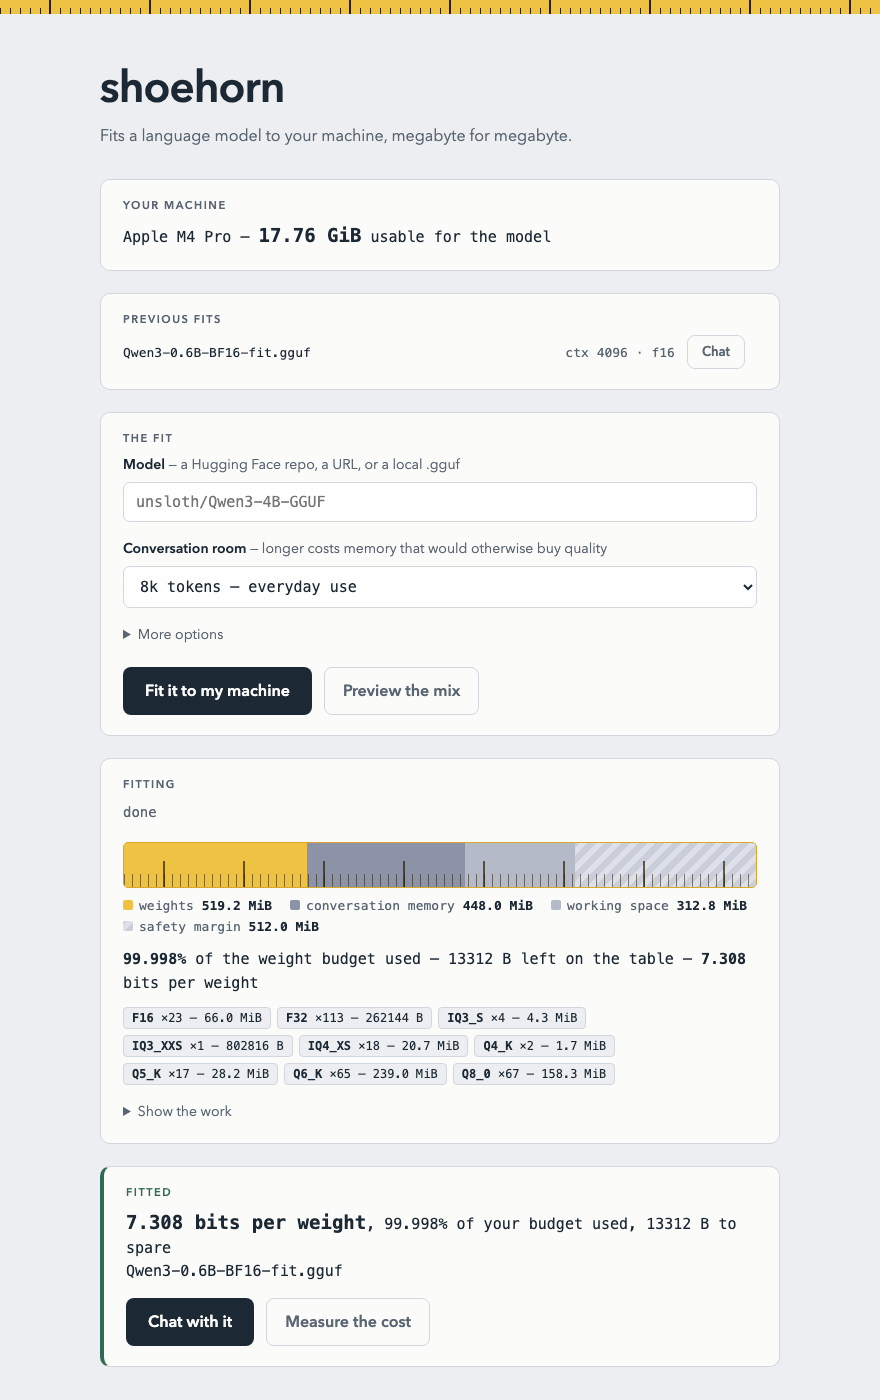
Preset quantizations ignore your hardware: pick one that fits and you either waste hundreds of megabytes of quality headroom or find out at load time it didn't fit after all\. shoehorn starts from the memory you actually have, subtracts what inference itself needs, and solves a per\-tensor mixed\-precision assignment that lands within a rounding error of the remainder — routinely using**99\.99%**of the budget, sometimes to the byte\.
$ shoehorn fit unsloth/Qwen3\-4B\-GGUF \-\-serve**weights: 519\.2 MiB of 519\.2 MiB budget \(99\.998% used, 13 KB slack\)**
Before you download
## What fits your machine?
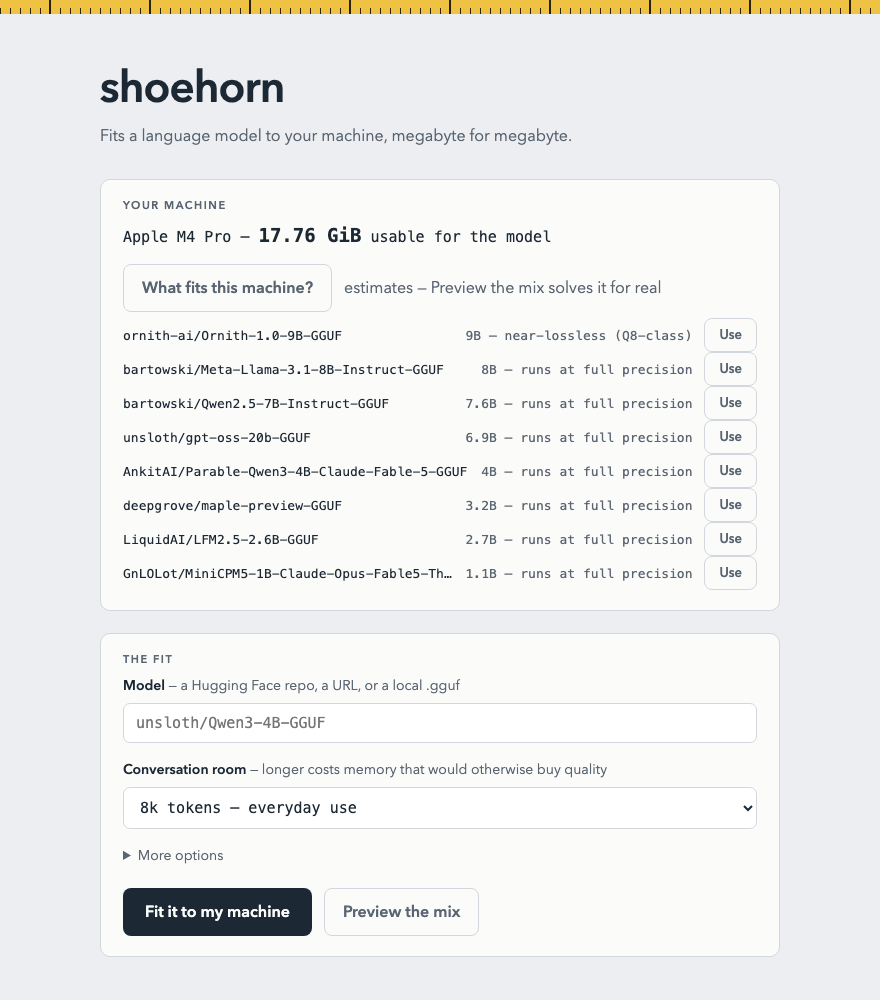
Pick your hardware and this page scans Hugging Face's most\-downloaded models for ones shoehorn can fit to your budget — ranked by the quality your memory affords\. Runs entirely in your browser\.
Your machine
Conversation room
Get shoehorn
## Install
shoehorn needs[llama\.cpp](https://github.com/ggml-org/llama.cpp)on your PATH as the inference backend \(the Homebrew install pulls it in for you\)\. Then`shoehorn ui`opens the local app — pick a model, press one button, chat\.
`brew install notactuallytreyanastasio/shoehorn/shoehorn`
Or from source:`cargo install \-\-path \.`after cloning[the repo](https://github.com/notactuallytreyanastasio/shoehorn)\. All[releases](https://github.com/notactuallytreyanastasio/shoehorn/releases)\.
The app
## One button, your whole budget
The local web app measures your machine, streams the fit, renders the budget as a tape measure, puts a perplexity number on what the fit cost, and ends at a Chat button\.
Soup is an open-source CLI that simplifies LLM fine-tuning and post-training with a single command, enabling QLoRA-based training on consumer GPUs with as little as 4 GB VRAM via layer streaming. The latest version adds preference losses like DPO, ORPO, SimPO, and KTO without doubling memory requirements.
Demonstrates running an 80B Qwen model in just 4.3 GB of RAM on a Mac and a 35B model on an iPhone, showcasing extreme memory optimization for local LLM inference.
A user shares early impressions of Dwarfstar, a tool offering bespoke quantization techniques for running large language models locally, reporting fast performance for Qwen3-8B on an M3 Ultra 96GB Mac Studio with leftover memory headroom.
slotstream is an open-source tool that enables running large AI models like Qwen3.8-Flash-Next on Macs with limited memory by streaming model weights from SSD, achieving approximately 12 tokens per second on a 48GB Mac.