GLM-5.3 is now open-weight
Summary
GLM-5.3, an enhanced open-weight AI model for agentic coding and cyber defense, is now available for download and customization, with significant improvements over GLM-5.2 and state-of-the-art performance on multiple benchmarks.
View Cached Full Text
Cached at: 08/28/26, 06:29 PM
GLM-5.3 is now open-weight.
Our most capable model for agentic coding and cyber defense is now available to download, run, and customize.
Weights: https://t.co/v1IbWMXxg4 Tech blog: https://t.co/ekQkO83jCv https://t.co/f8XlJksKyf
zai-org/GLM-5.3 · Hugging Face
Source: https://huggingface.co/zai-org/GLM-5.3 GLM-5.3 uses the same base model as GLM-5.2 — every gain comes from post-training. Compared with GLM-5.2, it is much better at complex coding and long-horizon tasks:
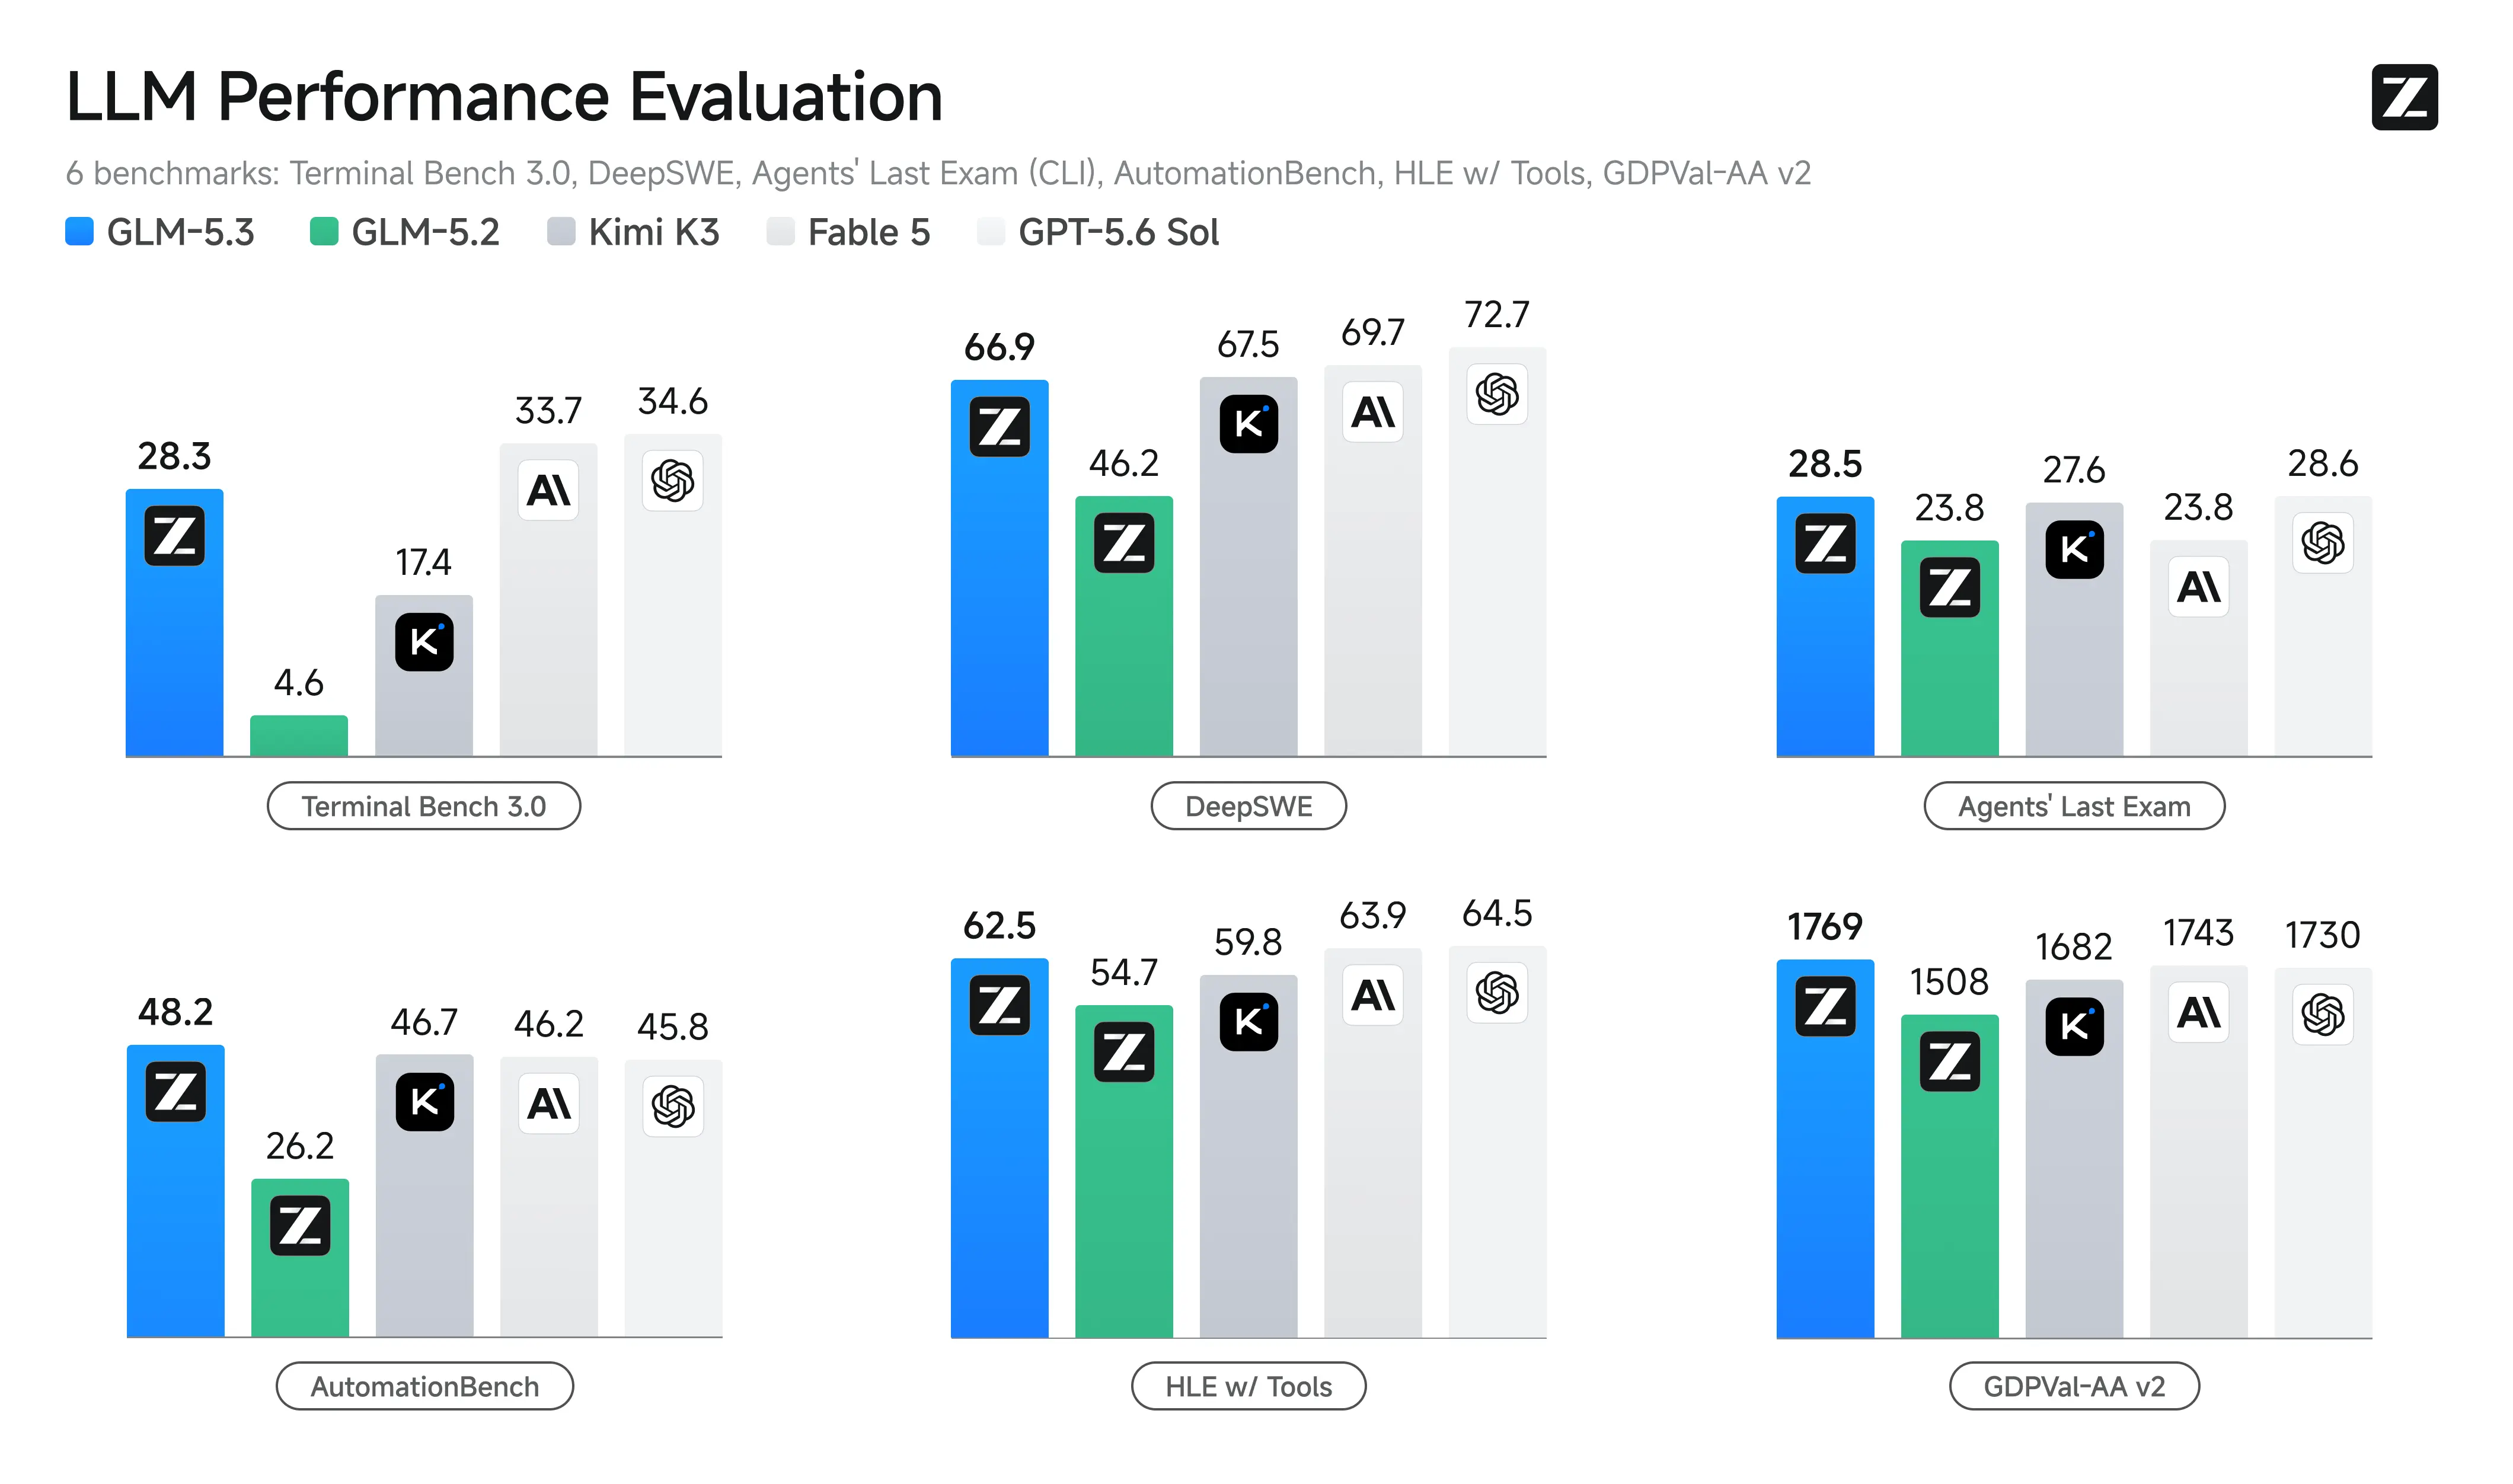
- Stronger Coding: GLM-5.3 is the most capable open-weights model for coding, with a 50% improvement over GLM-5.2 on our in-house Z.ai Code Bench. It also achieve open-source SOTA on public benchmarks including Terminal Bench 3.0 and Agents’ Last Exam.
- Emergent Cyber Capability: As we scaled post-training, cyber capability developed faster than we expected. GLM-5.3 is state of the art on CyberGym for vulnerability discovery, and its gains are largest further up the exploitation chain, where it more than doubles GLM-5.2 on exploitation benchmarks.
https://huggingface.co/zai-org/GLM-5.3#benchmarkBenchmark
BenchmarkGLM-5.3GLM-5.2Kimi K3DeepSeek-V4 Pro-0813Qwen3.8-MaxOpus 4.8Fable 5 (w/ fallback)GPT-5.6 SolTerminal Bench 2.188.281.088.387.986.685.088.088.8Terminal Bench 3.028.34.617.4––21.133.734.6DeepSWE (v1.1)66.946.267.562.756.658.069.772.7NL2Repo58.048.958.061.155.969.7––ProgramBench (Almost Solved)19.09.517.5–10.515.533.023.0FrontierSWE78.167.5–––66.588.2–SWE-Marathon (v1.1)42.519.448.1––48.833.142.5PostTrainBench39.831.732.0––32.941.836.2CyberGym84.577.280.083.378.578.183.883.6ExploitGym (2h / 6h)105 / 13029 / 3936 / 70–14 / 2680 / 120181 / 247216 / 293ExploitBench54.424.432.2–28.840.078.076.5Toolathlon Verified73.059.976.574.172.576.274.774.9AutomationBench (v1.0.6)48.226.246.743.239.841.046.245.8Agents’ Last Exam (ALE-CLI)28.523.827.625.727.025.723.828.6HLE w/ Tools62.554.759.860.056.257.963.964.5GDPval-AA v217691508168215901739158817431730
https://huggingface.co/zai-org/GLM-5.3#serve-glm-53-locallyServe GLM-5.3 Locally
GLM-5.3 supports deployment with the following frameworks. Feel free to try them out:
- SGLang— seecookbook
- vLLM— seerecipes
- TokenSpeed— seehere
- Transformers— seetransformers docs
- KTransformers— seetutorial
- Unsloth— seeguide
- For deployment on the
Ascend NPUplatform, inference frameworks such as vLLM-Ascend, xLLM and SGLang are supported — seehere.
https://huggingface.co/zai-org/GLM-5.3#noteNote
- GLM-5.3 supports controlling the thinking budget through the
reasoning\_effortparameter, which accepts three levels:low,high, andmax. It defaults tomaxif not passed (or if set to any other value). To useloworhigh, pass them explicitly. For benchmark and leaderboard reproduction, keep the defaultmax. - In the chat template for GLM-5.3,
clear\_thinkingdefaults tofalseif not passed. For chat scenarios, explicitly passclear\_thinking=true.
https://huggingface.co/zai-org/GLM-5.3#footnotesFootnotes
- HLE w/ tools: We use sampling parameters of
temperature=1\.0andtop\_p=0\.95for evaluation, with a maximum generation length of163,840tokens. The evaluation is conducted with a maximum context length of300,000tokens, using a context management strategy. We use GPT-5.6-luna (medium) as the judge model. - NL2Repo: We evaluated NL2Repo with
temperature=1\.0,top\_p=1\.0, andmax\_new\_tokens=64kunder 1M context. To prevent hacking, we use rule-based and a LLM-based judgement to prevent malicious behaviors (e.g., unauthorized pip or curl operations). - DeepSWE: We run DeepSWE using the mini-swe-agent harness with
temperature=0\.95,top\_p=1\.0,timeout=6hand 400K context. - Terminal-Bench 2.1: We evaluate in Claude Code 2.1.207 with
temperature=1\.0,top\_p=1,max\_new\_tokens=65536with 6h timeout. - Terminal-Bench 3.0: We evaluate Terminal-Bench-3 tasks with the Claude Code 2.1.207 harness (reasoning effort=max, 400K context, and 128K maximum output), reporting avg@3 over three rollouts per task. Each rollout runs in an isolated container built from the task’s official image, and is capped at 600 agent turns with a 10-hour timeout. Tool Search is disabled, and the artifacts each agent produces are scored by the task’s official separate verifier.
- Agent’s Last Exam (CLI): We evaluate ALE using the official evaluation protocol with the Claude Code harness (reasoning effort=max, 1M context, and 64K maximum output). Each of the 105 tasks runs in an isolated Docker container using the resources declared in its Task Card. The default timeout is 4 hours, with task-specific limits taking precedence (up to 8 hours). Tool Search is disabled, and results are scored by the official ALE evaluators.
- Toolathlon Verified: We obtain all results via the official evaluation service and report pass@1 averaged over 3 independent runs.
- AutomationBench: We evaluate on AutomationBenchv1.0.6, incorporating the fix for the
null-type handling issue introduced inPR #13. - GDPval-AA v2: Models are evaluated by Artificial Analysis.
- CyberGym: We evaluate GLM-5.3 in Claude Code 2.1.207 (max reasoning effort, no web tools with
temperature=1\.0,top\_p=1\.0,max\_new\_tokens=128000). All evaluations are under unlimited timeout per task and results are single-run Pass@1 over 1,507 tasks. To simulate real-world usage scenarios, we place the agent inside the task container. We also remove all Git-related information and apply a domain whitelist (allowing only essential domains such as pypi.org and deb.debian.org for basic tool installation) to prevent the agent from cheating. - ExploitGym: We evaluate GLM-5.3, Kimi-K3 and Qwen3.8 Max in Claude Code 2.1.207 (max reasoning effort, no web tools with
temperature=1\.0,top\_p=1\.0,max\_new\_tokens=128000). The reported results are single-run Pass@1 on 869 tasks under two timeout budgets: 2 hours and 6 hours, which are calculated as the API inference time rescaled by per-model tokens per second rate (per-model TPS sourced from Artificial Analysis; that is, we rescale GLM-5.3’s results by 115 TPS, Kimi K3’s results by 40 TPS and Qwen3.8 Max’s results by 47 TPS), plus the non-API overhead. We also apply a domain whitelist (allowing only essential domains such as pypi.org and deb.debian.org for basic tool installation) to prevent the agent from cheating. - ExploitBench: We evaluate GLM-5.3 in Claude Code 2.1.207 (max reasoning effort, no web tools with
temperature=1\.0,top\_p=1\.0,max\_new\_tokens=128000). Following the official evaluation settings, we limit the maximum number of interaction rounds between the agent and the environment to 300, and compute the average coverage score over all 41 tasks across 3 revisions. The coverage result of a task is determined by taking the union of capabilities achieved across all revisions, and the average score is obtained by averaging the results. We also apply a domain whitelist (allowing only essential domains such as pypi.org and deb.debian.org for basic tool installation) to prevent the agent from cheating. - FrontierSWE: The evaluation was conducted byProximalwith 1M context length, max effort level, and 128K maximum output tokens. Dominance score reported as of 2026/08/14.
- PostTrainBench: We evaluate GLM-5.3 using Claude Code 2.1.207 with max effort level,
temperature = 1\.0,top\_p = 1\.0,max\_new\_tokens = 128000, and a 1M-token context window. We report the weighted average over 3 runs. Runs that fail to produce a score fall back to the official zero-shot base-model baseline score. For checks intended to prevent the use of third-party APIs, we removed the original pattern-matching-based checks, as they produced false positives when a local vLLM endpoint was accessed through the OpenAI SDK. Instead, we use an LLM agent to inspect solutions for external API usage. - SWE-Marathon: We evaluate GLM-5.3 using Claude Code 2.1.207 with maximum effort level,
temperature = 1\.0,top\_p = 0\.95,max\_new\_tokens = 128000, and a 1M-token context window. Forstrip\-clone, the original anti-cheat checks used overly broad import detection that could reject valid implementations. We removed the affected checks and performed llm-based inspection instead to avoid false positives. Forparameter\-golfandtrimul\-cuda, changes to the NVIDIA wheels caused the Docker image builds to fail, so we added\-\-extra\-index\-url https://pypi\.org/simpleto restore successful builds.
https://huggingface.co/zai-org/GLM-5.3#citationCitation
If you find GLM-5.3 useful in your research, please cite our technical report:
@misc{glm5team2026glm5vibecodingagentic,
      title={GLM-5: from Vibe Coding to Agentic Engineering},
      author={GLM-5-Team and : and Aohan Zeng and Xin Lv and Zhenyu Hou and Zhengxiao Du and Qinkai Zheng and Bin Chen and Da Yin and Chendi Ge and Chenghua Huang and Chengxing Xie and Chenzheng Zhu and Congfeng Yin and Cunxiang Wang and Gengzheng Pan and Hao Zeng and Haoke Zhang and Haoran Wang and Huilong Chen and Jiajie Zhang and Jian Jiao and Jiaqi Guo and Jingsen Wang and Jingzhao Du and Jinzhu Wu and Kedong Wang and Lei Li and Lin Fan and Lucen Zhong and Mingdao Liu and Mingming Zhao and Pengfan Du and Qian Dong and Rui Lu and Shuang-Li and Shulin Cao and Song Liu and Ting Jiang and Xiaodong Chen and Xiaohan Zhang and Xuancheng Huang and Xuezhen Dong and Yabo Xu and Yao Wei and Yifan An and Yilin Niu and Yitong Zhu and Yuanhao Wen and Yukuo Cen and Yushi Bai and Zhongpei Qiao and Zihan Wang and Zikang Wang and Zilin Zhu and Ziqiang Liu and Zixuan Li and Bojie Wang and Bosi Wen and Can Huang and Changpeng Cai and Chao Yu and Chen Li and Chengwei Hu and Chenhui Zhang and Dan Zhang and Daoyan Lin and Dayong Yang and Di Wang and Ding Ai and Erle Zhu and Fangzhou Yi and Feiyu Chen and Guohong Wen and Hailong Sun and Haisha Zhao and Haiyi Hu and Hanchen Zhang and Hanrui Liu and Hanyu Zhang and Hao Peng and Hao Tai and Haobo Zhang and He Liu and Hongwei Wang and Hongxi Yan and Hongyu Ge and Huan Liu and Huanpeng Chu and Jia'ni Zhao and Jiachen Wang and Jiajing Zhao and Jiamin Ren and Jiapeng Wang and Jiaxin Zhang and Jiayi Gui and Jiayue Zhao and Jijie Li and Jing An and Jing Li and Jingwei Yuan and Jinhua Du and Jinxin Liu and Junkai Zhi and Junwen Duan and Kaiyue Zhou and Kangjian Wei and Ke Wang and Keyun Luo and Laiqiang Zhang and Leigang Sha and Liang Xu and Lindong Wu and Lintao Ding and Lu Chen and Minghao Li and Nianyi Lin and Pan Ta and Qiang Zou and Rongjun Song and Ruiqi Yang and Shangqing Tu and Shangtong Yang and Shaoxiang Wu and Shengyan Zhang and Shijie Li and Shuang Li and Shuyi Fan and Wei Qin and Wei Tian and Weining Zhang and Wenbo Yu and Wenjie Liang and Xiang Kuang and Xiangmeng Cheng and Xiangyang Li and Xiaoquan Yan and Xiaowei Hu and Xiaoying Ling and Xing Fan and Xingye Xia and Xinyuan Zhang and Xinze Zhang and Xirui Pan and Xu Zou and Xunkai Zhang and Yadi Liu and Yandong Wu and Yanfu Li and Yidong Wang and Yifan Zhu and Yijun Tan and Yilin Zhou and Yiming Pan and Ying Zhang and Yinpei Su and Yipeng Geng and Yong Yan and Yonglin Tan and Yuean Bi and Yuhan Shen and Yuhao Yang and Yujiang Li and Yunan Liu and Yunqing Wang and Yuntao Li and Yurong Wu and Yutao Zhang and Yuxi Duan and Yuxuan Zhang and Zezhen Liu and Zhengtao Jiang and Zhenhe Yan and Zheyu Zhang and Zhixiang Wei and Zhuo Chen and Zhuoer Feng and Zijun Yao and Ziwei Chai and Ziyuan Wang and Zuzhou Zhang and Bin Xu and Minlie Huang and Hongning Wang and Juanzi Li and Yuxiao Dong and Jie Tang},
      year={2026},
      eprint={2602.15763},
      archivePrefix={arXiv},
      primaryClass={cs.LG},
      url={https://arxiv.org/abs/2602.15763},
}
Model tree forzai-org/GLM-5.3https://huggingface.co/docs/hub/model-cards#specifying-a-base-model
Spaces usingzai-org/GLM-5.32
Collection includingzai-org/GLM-5.3
Paper forzai-org/GLM-5.3
Evaluation resultshttps://huggingface.co/docs/hub/eval-results
Similar Articles
GLM-5.2 is a step change for open agents
Z.ai released GLM-5.2, an open-weight AI model that represents a step change for open agents, with strong benchmark performance and community hype, positioning it as the only open model competing with top closed models from OpenAI and Anthropic.
@svpino: GLM-5.3 is now open-weight! You can download it from HuggingFace or run it using Atomic Agent. No matter what Big AI sa…
GLM-5.3 has been released as an open-weight model, downloadable from HuggingFace or runnable via Atomic Agent, with cost comparisons showing efficiency improvements.
GLM-5.2 is the new leading open weights model on Artificial Analysis
Z ai's GLM-5.2 has become the new leading open weights model on the Artificial Analysis Intelligence Index, scoring 51 and outperforming competitors like MiniMax-M3 and DeepSeek V4 Pro. The model features 744B total parameters, 40B active, MIT license, and 1M context window.
@baseten: Today, we're releasing GLM-5.3 Fast: one of the most intelligent open-weight models ever at an even higher TPS. Designe…
Z.AI releases GLM-5.3 Fast, an advanced open-weight AI model optimized for agentic coding and cybersecurity, featuring a 744B-A40B MoE architecture with substantial benchmark improvements.
GLM-5.2 is a win for local AI
GLM-5.2, a 753B parameter open-source model with MIT license, offers frontier-level coding capabilities and massive context window. Its distillation potential promises significant improvements for local AI setups.