NVIDIA发布开放的Nemotron 3.5 Super VL(120亿参数级多模态模型)及两款边缘模型Bolt 74B-A9B 24GB与Bolt E4B 4GB,覆盖从数据中心到本地边缘设备的全场景智能体部署需求。
<div id="bsf_rt_marker"></div><p><span style="font-weight: 400;">NVIDIA today released Nemotron 3.5 Super VL, an open 120-billion-parameter model that delivers the fastest task completion and highest accuracy for specialized always-on agents.</span></p>
<p><span style="font-weight: 400;">Joining it are two new edge models: Nemotron 3.5 Bolt 74B-A9B 24GB, optimized to balance intelligence and speed per GB for local agentic workloads, and Nemotron 3.5 Bolt E4B 4GB, optimized for intelligence per GB for fast conversational agents.</span></p>
<p><span style="font-weight: 400;">Super VL and Bolt 74B-A9B are available now, with Bolt E4B coming Oct. 23.</span><b><i><br />
</i></b><b><br />
</b><span style="font-weight: 400;">The three </span><a target="_blank" href="https://www.nvidia.com/en-us/glossary/open-models/"><span style="font-weight: 400;">open models</span></a><span style="font-weight: 400;"> together cover the full range of agent deployments, from large enterprise servers down to edge devices and local hardware. </span></p>
<p><span style="font-weight: 400;">Any organization that wants to run agents on NVIDIA infrastructure now has an open, optimized model for their tier, without having to choose between capability and deployability. </span></p>
<p><span style="font-weight: 400;">Super VL and Bolt join the Nemotron family alongside </span><a href="https://blogs.nvidia.com/blog/nemotron-lightning-switchyard-rtx-dgx/"><span style="font-weight: 400;">Lightning</span></a><span style="font-weight: 400;"> and Ultra. </span></p>
<p><span style="font-weight: 400;">Lightning, released in August, handles high-throughput workloads; Ultra handles the hardest reasoning tasks; and Bolt brings intelligence to the edge. </span></p>
<h2><b>Nemotron 3.5 Super VL: Frontier Accuracy at One-Fifth the Size</b></h2>
<p><span style="font-weight: 400;">Super VL, built in collaboration with the </span><a target="_blank" href="https://nvidianews.nvidia.com/news/nvidia-launches-nemotron-coalition-of-leading-global-ai-labs-to-advance-open-frontier-models"><span style="font-weight: 400;">Nemotron Coalition</span></a><span style="font-weight: 400;">, delivers leading accuracy on multimodal agentic tasks — instruction following, tool use, multistep business workflows, and visual understanding — comparable with NVIDIA’s largest reasoning model at roughly one-fifth the parameter count.<br />
</span></p>
<figure id="attachment_98924" aria-describedby="caption-attachment-98924" style="width: 960px" class="wp-caption aligncenter"><img decoding="async" class="size-medium wp-image-98924" src="https://blogs.nvidia.com/wp-content/uploads/2026/10/SECOND-Artificial-Analysis-Index-960x408.png" alt="" width="960" height="408" srcset="https://blogs.nvidia.com/wp-content/uploads/2026/10/SECOND-Artificial-Analysis-Index-960x408.png 960w, https://blogs.nvidia.com/wp-content/uploads/2026/10/SECOND-Artificial-Analysis-Index-1680x714.png 1680w, https://blogs.nvidia.com/wp-content/uploads/2026/10/SECOND-Artificial-Analysis-Index-1280x544.png 1280w, https://blogs.nvidia.com/wp-content/uploads/2026/10/SECOND-Artificial-Analysis-Index-1536x653.png 1536w, https://blogs.nvidia.com/wp-content/uploads/2026/10/SECOND-Artificial-Analysis-Index-scaled.png 2048w, https://blogs.nvidia.com/wp-content/uploads/2026/10/SECOND-Artificial-Analysis-Index-630x268.png 630w" sizes="(max-width: 960px) 100vw, 960px" /><figcaption id="caption-attachment-98924" class="wp-caption-text">Nemotron 3.5 Super VL delivers frontier-level intelligence in its class for high-volume agentic workflows.</figcaption></figure>
<p><span style="font-weight: 400;">As the fastest open agentic model in its class — 5x faster than the next best — it helps enterprise agents complete high-volume tasks faster across workflows that span days or weeks. </span></p>
<figure id="attachment_98926" aria-describedby="caption-attachment-98926" style="width: 960px" class="wp-caption aligncenter"><img loading="lazy" decoding="async" class="wp-image-98926 size-medium" src="https://blogs.nvidia.com/wp-content/uploads/2026/10/THIRD-Intelligence-Index-Output-Latest-960x449.jpeg" alt="" width="960" height="449" srcset="https://blogs.nvidia.com/wp-content/uploads/2026/10/THIRD-Intelligence-Index-Output-Latest-960x449.jpeg 960w, https://blogs.nvidia.com/wp-content/uploads/2026/10/THIRD-Intelligence-Index-Output-Latest-1680x786.jpeg 1680w, https://blogs.nvidia.com/wp-content/uploads/2026/10/THIRD-Intelligence-Index-Output-Latest-1280x599.jpeg 1280w, https://blogs.nvidia.com/wp-content/uploads/2026/10/THIRD-Intelligence-Index-Output-Latest-1536x719.jpeg 1536w, https://blogs.nvidia.com/wp-content/uploads/2026/10/THIRD-Intelligence-Index-Output-Latest-scaled.jpeg 2048w, https://blogs.nvidia.com/wp-content/uploads/2026/10/THIRD-Intelligence-Index-Output-Latest-630x295.jpeg 630w" sizes="auto, (max-width: 960px) 100vw, 960px" /><figcaption id="caption-attachment-98926" class="wp-caption-text">Nemotron 3.5 Super VL, on Artificial Analysis Intelligence Index leadboard, achieves up to 5x faster throughput compared to other models in its class.</figcaption></figure>
<p><span style="font-weight: 400;">Unlike closed frontier models, organizations can post-train Super VL on their own data, deploy it on their own infrastructure and oversee what they build.</span><span style="font-weight: 400;"><br />
</span></p>
<h2>Nemotron 3.5 Bolt: Agentic Intelligence at the Edge</h2>
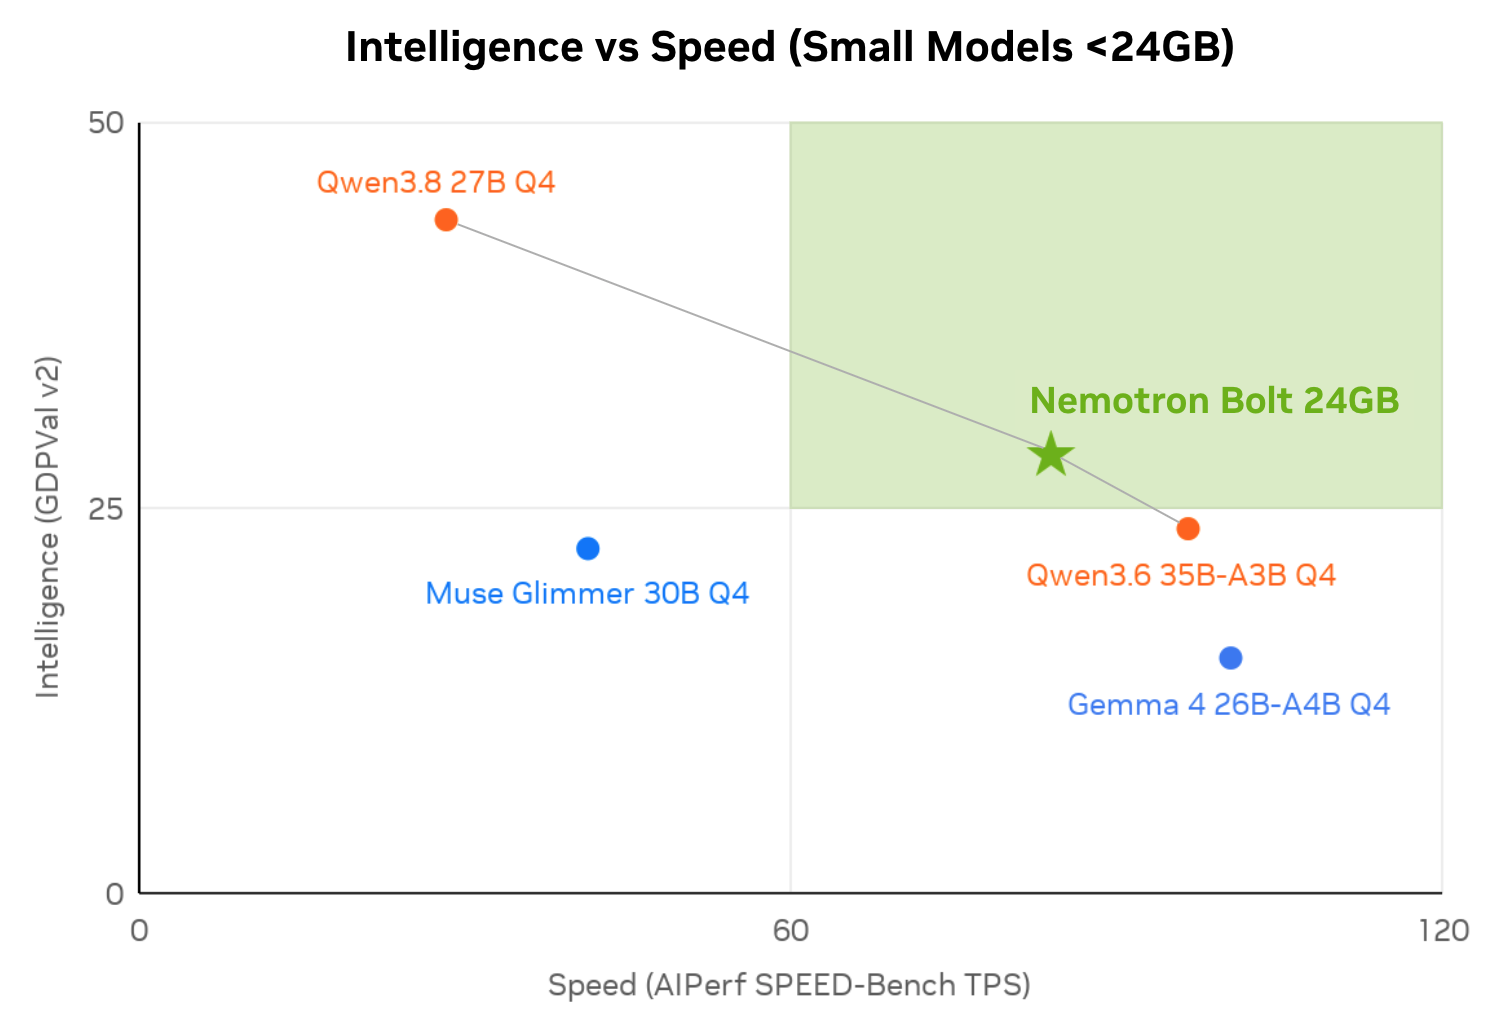
<p><span style="font-weight: 400;">Bolt 74B-A9B 24GB is designed to run everyday agentic tasks locally on NVIDIA RTX/DGX Spark, using a native 2-bit quantization to fit in 24GB of memory and run alongside other applications.</span></p>
<p><span style="font-weight: 400;">Relative to other models with a similar memory footprint, it provides a good balance of intelligence and speed: smart enough to get most jobs done, yet much faster than the smartest models.</span></p>
<p><img loading="lazy" decoding="async" class="aligncenter size-full wp-image-98941" src="https://blogs.nvidia.com/wp-content/uploads/2026/10/GDPVal_TPS_v3.png" alt="" width="1498" height="1032" srcset="https://blogs.nvidia.com/wp-content/uploads/2026/10/GDPVal_TPS_v3.png 1498w, https://blogs.nvidia.com/wp-content/uploads/2026/10/GDPVal_TPS_v3-960x661.png 960w, https://blogs.nvidia.com/wp-content/uploads/2026/10/GDPVal_TPS_v3-1280x882.png 1280w, https://blogs.nvidia.com/wp-content/uploads/2026/10/GDPVal_TPS_v3-630x434.png 630w" sizes="auto, (max-width: 1498px) 100vw, 1498px" /></p>
<p> </p>
<p><span style="font-weight: 400;">With Bolt 74B-A9B 24GB, users can delegate their projects to popular local agent harnesses — from researching the web to writing to debugging code — all without sending those workloads to the cloud. It is the #1 open model in its class on </span><a target="_blank" href="https://pinchbench.com/?slm=true"><span style="font-weight: 400;">PinchBench</span></a><span style="font-weight: 400;">, and the #2 open model for </span><a target="_blank" href="https://leaderboard.steel.dev/leaderboards/browsecomp/?weights=open&sizes=tiny%2Csmall%2Cmedium"><span style="font-weight: 400;">BrowseComp</span></a><span style="font-weight: 400;">.</span><span style="font-weight: 400;"><br />
</span><span style="font-weight: 400;"><br />
</span><span style="font-weight: 400;">Bolt E4B 4GB is built for physical and conversational agents on GeForce RTX, Jetson, and RTX/DGX Spark. It combines natural conversation with multi-turn agentic capabilities to power fast local voice assistants, interactive characters and embedded interfaces. </span></p>
<h2><b>Adoption of Custom Super Intelligence</b></h2>
<p><span style="font-weight: 400;">Dozens of organizations across industries are post-training Super VL on their own data, tools, policies and workflows to push accuracy higher on the specialized tasks that define their agent deployments. </span></p>
<p><span style="font-weight: 400;">Super VL is being post-trained and customized by organizations across industries. </span><a target="_blank" href="https://scale.com/blog/scale-partners-with-nvidia"><span style="font-weight: 400;">Scale AI</span></a><span style="font-weight: 400;"> post-trained the model for Skydance’s vendor credit finance agent and for EY’s M&A due diligence agent.</span> <span style="font-weight: 400;">AfterQuery</span><span style="font-weight: 400;"> customized the model for Hebbia for credit agreement analysis. </span><span style="font-weight: 400;"><a target="_blank" href="https://www.ai21.com/blog/ai21-post-trains-nvidia-nemotron-35-super-vl/">AI21</a> and <a target="_blank" href="http://alice.io/blog/nemotron-ai21">Alice</a></span><span style="font-weight: 400;"> post-trained the model for cybersecurity attack resilience.</span> <span style="font-weight: 400;">Mercor </span><span style="font-weight: 400;">post-trained the model on APEX-SWE coding benchmark, for coding agents that plan, write and debug code. </span><span style="font-weight: 400;"><a target="_blank" href="https://modelscope.ai/collections/nv-community/Nemotron-35-Super-VL">ModelScope</a> enables developers to fine-tune the model through its <a target="_blank" href="https://github.com/modelscope/ms-swift">ms-swift </a>framework for specialized multimodal applications.</span></p>
<p><span style="font-weight: 400;">Additional organizations customizing Nemotron 3.5 Super VL include </span><span style="font-weight: 400;">Ramp </span><span style="font-weight: 400;">for financial document intelligence; </span><span style="font-weight: 400;">Dream</span><span style="font-weight: 400;">, sovereign AI-powered cybersecurity research and vulnerability analysis;</span><span style="font-weight: 400;"> Lila Sciences </span><span style="font-weight: 400;">for scientific discovery and search, and</span> <a target="_blank" href="http://www.r1rcm.com/resources/long-context-medical-reasoning-to-reduce-denials-post-training-nvidia-nemotron-3-5-super"><span style="font-weight: 400;">R1</span></a> <span style="font-weight: 400;">for medical claims analysis and revenue cycle management. </span><span style="font-weight: 400;">TrainLoop</span><span style="font-weight: 400;"> post-trained the model with dermatology data from Nolla, which just became the first company approved for AI to write initial patient prescriptions.</span><span style="font-weight: 400;"><br />
</span><span style="font-weight: 400;"><br />
</span><span style="font-weight: 400;">Software platform companies integrating Nemotron 3.5 Super VL include: </span></p>
<ul>
<li style="font-weight: 400;" aria-level="1"><b>Atlassian</b><b>, </b><span style="font-weight: 400;">for tasks like agentic search across apps such as Jira and Confluence.</span></li>
<li style="font-weight: 400;" aria-level="1"><b>CrowdStrike</b><span style="font-weight: 400;">, which is customizing the model for agentic blue teaming in enterprise security.</span></li>
<li style="font-weight: 400;" aria-level="1"><b>Dassault Systèmes</b><span style="font-weight: 400;">, powering engineering design and simulation. </span></li>
<li style="font-weight: 400;" aria-level="1"><b>Perplexity</b><span style="font-weight: 400;">, for search and agentic tasks in Perplexity Search and Computer.</span></li>
<li style="font-weight: 400;" aria-level="1"><strong><a target="_blank" href="https://www.salesforce.com/news/press-releases/2026/09/15/koa-reasoning-model/">Salesforce</a></strong><span style="font-weight: 400;">, which is customizing Nemotron to power AI agents that digitize and automate complex government workflows in secure customer environments through Missionforce Operations.</span></li>
<li style="font-weight: 400;" aria-level="1"><b>Synopsys</b><span style="font-weight: 400;"> software for semiconductor design verification interoperates with the model.<img loading="lazy" decoding="async" class="aligncenter size-medium wp-image-98923" src="https://blogs.nvidia.com/wp-content/uploads/2026/10/LAST-post-training-delivers-leading-accuracy--960x540.png" alt="" width="960" height="540" srcset="https://blogs.nvidia.com/wp-content/uploads/2026/10/LAST-post-training-delivers-leading-accuracy--960x540.png 960w, https://blogs.nvidia.com/wp-content/uploads/2026/10/LAST-post-training-delivers-leading-accuracy--1680x945.png 1680w, https://blogs.nvidia.com/wp-content/uploads/2026/10/LAST-post-training-delivers-leading-accuracy--1280x720.png 1280w, https://blogs.nvidia.com/wp-content/uploads/2026/10/LAST-post-training-delivers-leading-accuracy--1536x864.png 1536w, https://blogs.nvidia.com/wp-content/uploads/2026/10/LAST-post-training-delivers-leading-accuracy--scaled.png 2048w, https://blogs.nvidia.com/wp-content/uploads/2026/10/LAST-post-training-delivers-leading-accuracy--1290x725.png 1290w, https://blogs.nvidia.com/wp-content/uploads/2026/10/LAST-post-training-delivers-leading-accuracy--630x354.png 630w, https://blogs.nvidia.com/wp-content/uploads/2026/10/LAST-post-training-delivers-leading-accuracy--300x169.png 300w, https://blogs.nvidia.com/wp-content/uploads/2026/10/LAST-post-training-delivers-leading-accuracy--400x225.png 400w" sizes="auto, (max-width: 960px) 100vw, 960px" /></span></li>
</ul>
<h2>What Nemotron 3.5 Super VL Actually Sees</h2>
<p><span style="font-weight: 400;">Nemotron 3.5 Super VL’s </span><a target="_blank" href="https://www.nvidia.com/en-us/glossary/vision-language-models/"><span style="font-weight: 400;">vision language</span></a><span style="font-weight: 400;"> strengths are targeted at what agents encounter in practice: optical character recognition, tables, charts and structured information in visual documents. </span></p>
<p><span style="font-weight: 400;">It processes a web page, extracts text, reads graphs and charts, and returns insights from what it finds. The same applies to PDFs and other documents agents commonly work with.</span></p>
<p><span style="font-weight: 400;">Nemotron 3.5 Super VL understands images, webpages and PDFs and acts on that understanding. Combining text and visual understanding in one model means agents don’t need to route tasks between separate systems — context carries through as work moves from document to data to decision. </span></p>
<h2><b>Open for Maximum Control, Security, and Privacy</b></h2>
<p><span style="font-weight: 400;">Openness and customizability reinforce each other. The model ships with open weights, open datasets and training recipes.</span></p>
<p><span style="font-weight: 400;">Control runs in two directions. Organizations can run the model wherever their security and data-residency requirements dictate. They also choose to adopt a model they can adapt, rather than one subject to a provider’s restrictions.</span></p>
<p><span style="font-weight: 400;">In insurance, for example, a customized agent can scan claims for fraud markers on repeat. In financial services, an agent can review credit scores and flag activity against an organization’s own lending criteria. The model stays on premises. The data stays private.</span></p>
<p><span style="font-weight: 400;">Customization is supported through NVIDIA NeMo, Python-based pipelines and open datasets.</span></p>
<p><span style="font-weight: 400;">Nemotron 3.5 Super VL was trained on about 26 trillion tokens across </span><a target="_blank" href="https://huggingface.co/collections/nvidia/nemotron-pre-training-datasets"><span style="font-weight: 400;">pretraining</span></a><span style="font-weight: 400;"> and continued pretraining, then post-trained with roughly 3.8 million samples and reinforcement learning across dozens of environments. </span></p>
<p><span style="font-weight: 400;">NVIDIA is also releasing open datasets on Hugging Face spanning </span><a target="_blank" href="https://huggingface.co/collections/nvidia/nemotron-post-training-v3"><span style="font-weight: 400;">agentic tool use</span></a><span style="font-weight: 400;">, finance, instruction following, long context, fairness and vision-language understanding, along with the reinforcement learning environments in NeMo Gym.</span></p>
<p><a target="_blank" href="https://www.nvidia.com/en-us/ai-data-science/products/nim-microservices/"><span style="font-weight: 400;">NVIDIA NIM</span></a><span style="font-weight: 400;"> packages the model as a production-ready microservice with performance-optimized, validated configurations and enterprise-grade support, refreshed every two weeks with security patches and performance improvements.</span></p>
<p><span style="font-weight: 400;">And with the model running on NVIDIA Dynamo, organizations can serve up to 8x more users with 85% lower latency.</span></p>
<p><span style="font-weight: 400;">Nemotron 3.5 Super VL is available now on Hugging Face, Open Router, </span><a target="_blank" href="https://modelscope.ai/collections/nv-community/Nemotron-35-Super-VL"><span style="font-weight: 400;">ModelScope</span><span style="font-weight: 400;"> community</span></a><span style="font-weight: 400;"> and as NVIDIA NIM.</span></p>
<h2><b>Runs on DGX Spark, DGX Station, and RTX </b></h2>
<p><span style="font-weight: 400;">Nemotron 3.5 Super VL runs across NVIDIA’s full hardware stack: on </span><a target="_blank" href="https://www.nvidia.com/en-us/products/workstations/dgx-spark/"><span style="font-weight: 400;">DGX Spark</span></a><span style="font-weight: 400;">, </span><a target="_blank" href="https://www.nvidia.com/en-us/products/workstations/dgx-station/"><span style="font-weight: 400;">DGX Station</span></a><span style="font-weight: 400;">, RTX PRO and RTX systems for local intelligence at the desktop, on </span><a target="_blank" href="https://www.nvidia.com/en-us/autonomous-machines/embedded-systems/"><span style="font-weight: 400;">NVIDIA Jetson</span></a><span style="font-weight: 400;"> at the edge, and across data center and cloud environments.</span></p>
<p><a target="_blank" href="https://research.nvidia.com/labs/nemotron/Nemotron-3.5-Bolt-24GB/"><span style="font-weight: 400;">Nemotron 3.5 Bolt 74B-A9B 24G</span><span style="font-weight: 400;">B</span></a><span style="font-weight: 400;"> is available now on Hugging Face, with support for llama.cpp, <a target="_blank" href="https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Bolt-74B-A9B-24GB-GGUF">Ollama</a>, <a target="_blank" href="https://lmstudio.ai/models/nvidia/nemotron-3.5-bolt-74b-a9b">LM Studio</a>, <a target="_blank" href="https://unsloth.ai/docs/models/nemotron-3.5-bolt">Unsloth</a>, and <a target="_blank" href="https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Bolt-74B-A9B-24GB">vLLM</a>. Built for </span><a target="_blank" href="https://www.nvidia.com/en-us/products/rtx-spark/"><span style="font-weight: 400;">NVIDIA RTX Spark laptops</span></a><span style="font-weight: 400;"> arriving Oct. 16, it also runs on </span><a target="_blank" href="https://www.nvidia.com/en-us/ai-on-rtx/"><span style="font-weight: 400;">GeForce RTX PCs</span></a><span style="font-weight: 400;">, </span><a target="_blank" href="https://www.nvidia.com/en-us/products/workstations/dgx-spark/"><span style="font-weight: 400;">DGX Spark</span></a><span style="font-weight: 400;">, </span><a target="_blank" href="https://www.nvidia.com/en-us/products/workstations/dgx-station/"><span style="font-weight: 400;">DGX Station</span></a><span style="font-weight: 400;"> and </span><a target="_blank" href="https://www.nvidia.com/en-us/products/workstations/"><span style="font-weight: 400;">RTX PRO workstations</span></a><span style="font-weight: 400;">.</span></p>
<p><i><span style="font-weight: 400;">Download the </span></i><a target="_blank" href="https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Super-VL-120B-A12B-NVFP4"><i><span style="font-weight: 400;">open weights</span></i></a><i><span style="font-weight: 400;">, explore customization resources with NVIDIA NeMo, or read the </span></i><a target="_blank" href="https://developer.nvidia.com/blog/nvidia-nemotron-3-5-super-vl-powers-specialized-agents-with-multimodal-reasoning/"><i><span style="font-weight: 400;">technical blog</span></i></a><i><span style="font-weight: 400;"> for the full architecture breakdown.</span></i></p>
<p><i><span style="font-weight: 400;">Stay up to date on agents, NVIDIA</span></i><a target="_blank" href="https://www.nvidia.com/en-us/ai-data-science/foundation-models/nemotron/"> <i><span style="font-weight: 400;">Nemotron</span></i></a><i><span style="font-weight: 400;"> and more by subscribing to</span></i><a target="_blank" href="https://www.nvidia.com/en-us/executive-insights/generative-ai-tools/?modal=stay-inf"> <i><span style="font-weight: 400;">NVIDIA news</span></i></a><i><span style="font-weight: 400;">,</span></i><a target="_blank" href="https://developer.nvidia.com/community"> <i><span style="font-weight: 400;">joining the community</span></i></a><i><span style="font-weight: 400;">, and following NVIDIA AI on</span></i><a target="_blank" href="https://www.linkedin.com/showcase/nvidia-ai/posts/?feedView=all"> <i><span style="font-weight: 400;">LinkedIn</span></i></a><i><span style="font-weight: 400;">,</span></i><a target="_blank" href="https://www.instagram.com/nvidiaai/?hl=en"> <i><span style="font-weight: 400;">Instagram</span></i></a><i><span style="font-weight: 400;">,</span></i><a target="_blank" href="https://x.com/NVIDIAAIDev"> <i><span style="font-weight: 400;">X</span></i></a><i><span style="font-weight: 400;"> and</span></i><a target="_blank" href="https://www.facebook.com/NVIDIAAI"> <i><span style="font-weight: 400;">Facebook</span></i></a><i><span style="font-weight: 400;">.</span></i></p>
<p><i><span style="font-weight: 400;">Explore</span></i><a target="_blank" href="https://youtube.com/playlist?list=PL5B692fm6--vdRKB14FImVi7MTJ77zjn4&feature=shared"> <i><span style="font-weight: 400;">self-paced video tutorials and livestreams</span></i></a><i><span style="font-weight: 400;">.</span></i></p>
<p><i><span style="font-weight: 400;">See</span></i><a target="_blank" href="https://www.nvidia.com/en-eu/about-nvidia/terms-of-service/"> <i><span style="font-weight: 400;">notice</span></i></a><i><span style="font-weight: 400;"> regarding software product information.</span></i></p>
# Open From Data Center to Desktop: NVIDIA Expands Nemotron Family With Highest Efficiency Super VL and Bolt Models
Source: [https://blogs.nvidia.com/blog/nemotron-3-5-super-vl/](https://blogs.nvidia.com/blog/nemotron-3-5-super-vl/)
NVIDIA today released Nemotron 3\.5 Super VL, an open 120\-billion\-parameter model that delivers the fastest task completion and highest accuracy for specialized always\-on agents\.
Joining it are two new edge models: Nemotron 3\.5 Bolt 74B\-A9B 24GB, optimized to balance intelligence and speed per GB for local agentic workloads, and Nemotron 3\.5 Bolt E4B 4GB, optimized for intelligence per GB for fast conversational agents\.
Super VL and Bolt 74B\-A9B are available now, with Bolt E4B coming Oct\. 23\.The three[open models](https://www.nvidia.com/en-us/glossary/open-models/)together cover the full range of agent deployments, from large enterprise servers down to edge devices and local hardware\.
Any organization that wants to run agents on NVIDIA infrastructure now has an open, optimized model for their tier, without having to choose between capability and deployability\.
Super VL and Bolt join the Nemotron family alongside[Lightning](https://blogs.nvidia.com/blog/nemotron-lightning-switchyard-rtx-dgx/)and Ultra\.
Lightning, released in August, handles high\-throughput workloads; Ultra handles the hardest reasoning tasks; and Bolt brings intelligence to the edge\.
## **Nemotron 3\.5 Super VL: Frontier Accuracy at One\-Fifth the Size**
Super VL, built in collaboration with the[Nemotron Coalition](https://nvidianews.nvidia.com/news/nvidia-launches-nemotron-coalition-of-leading-global-ai-labs-to-advance-open-frontier-models), delivers leading accuracy on multimodal agentic tasks — instruction following, tool use, multistep business workflows, and visual understanding — comparable with NVIDIA’s largest reasoning model at roughly one\-fifth the parameter count\.
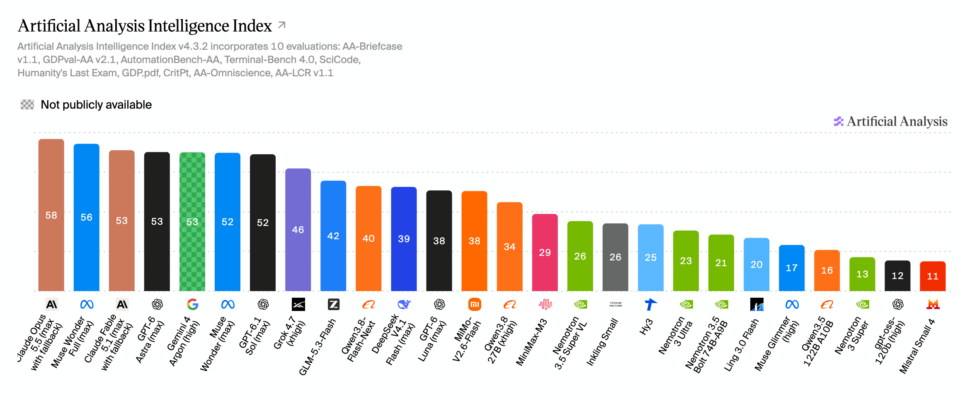Nemotron 3\.5 Super VL delivers frontier\-level intelligence in its class for high\-volume agentic workflows\.As the fastest open agentic model in its class — 5x faster than the next best — it helps enterprise agents complete high\-volume tasks faster across workflows that span days or weeks\.
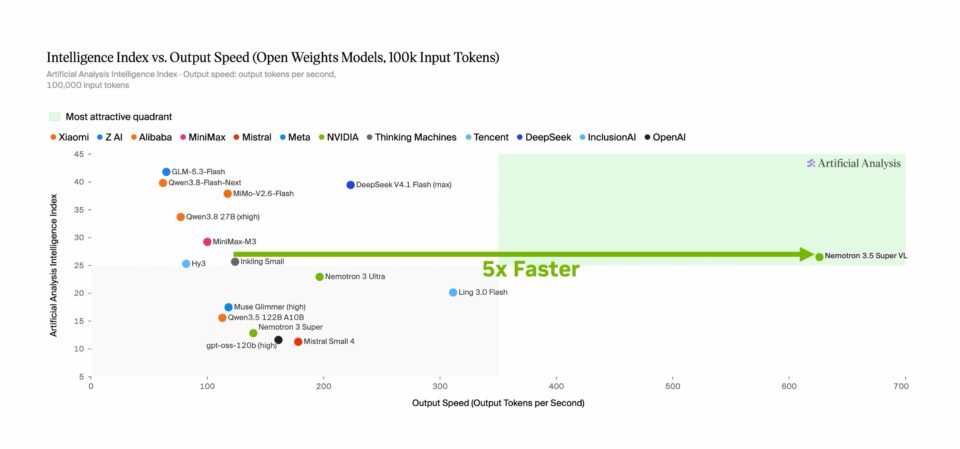Nemotron 3\.5 Super VL, on Artificial Analysis Intelligence Index leadboard, achieves up to 5x faster throughput compared to other models in its class\.Unlike closed frontier models, organizations can post\-train Super VL on their own data, deploy it on their own infrastructure and oversee what they build\.
## Nemotron 3\.5 Bolt: Agentic Intelligence at the Edge
Bolt 74B\-A9B 24GB is designed to run everyday agentic tasks locally on NVIDIA RTX/DGX Spark, using a native 2\-bit quantization to fit in 24GB of memory and run alongside other applications\.
Relative to other models with a similar memory footprint, it provides a good balance of intelligence and speed: smart enough to get most jobs done, yet much faster than the smartest models\.
With Bolt 74B\-A9B 24GB, users can delegate their projects to popular local agent harnesses — from researching the web to writing to debugging code — all without sending those workloads to the cloud\. It is the \#1 open model in its class on[PinchBench](https://pinchbench.com/?slm=true), and the \#2 open model for[BrowseComp](https://leaderboard.steel.dev/leaderboards/browsecomp/?weights=open&sizes=tiny%2Csmall%2Cmedium)\. Bolt E4B 4GB is built for physical and conversational agents on GeForce RTX, Jetson, and RTX/DGX Spark\. It combines natural conversation with multi\-turn agentic capabilities to power fast local voice assistants, interactive characters and embedded interfaces\.
## **Adoption of Custom Super Intelligence**
Dozens of organizations across industries are post\-training Super VL on their own data, tools, policies and workflows to push accuracy higher on the specialized tasks that define their agent deployments\.
Super VL is being post\-trained and customized by organizations across industries\.[Scale AI](https://scale.com/blog/scale-partners-with-nvidia)post\-trained the model for Skydance’s vendor credit finance agent and for EY’s M&A due diligence agent\.AfterQuerycustomized the model for Hebbia for credit agreement analysis\.[AI21](https://www.ai21.com/blog/ai21-post-trains-nvidia-nemotron-35-super-vl/)and[Alice](http://alice.io/blog/nemotron-ai21)post\-trained the model for cybersecurity attack resilience\.Mercorpost\-trained the model on APEX\-SWE coding benchmark, for coding agents that plan, write and debug code\.[ModelScope](https://modelscope.ai/collections/nv-community/Nemotron-35-Super-VL)enables developers to fine\-tune the model through its[ms\-swift](https://github.com/modelscope/ms-swift)framework for specialized multimodal applications\.
Additional organizations customizing Nemotron 3\.5 Super VL includeRampfor financial document intelligence;Dream, sovereign AI\-powered cybersecurity research and vulnerability analysis;Lila Sciencesfor scientific discovery and search, and[R1](http://www.r1rcm.com/resources/long-context-medical-reasoning-to-reduce-denials-post-training-nvidia-nemotron-3-5-super)for medical claims analysis and revenue cycle management\.TrainLooppost\-trained the model with dermatology data from Nolla, which just became the first company approved for AI to write initial patient prescriptions\. Software platform companies integrating Nemotron 3\.5 Super VL include:
- **Atlassian****,**for tasks like agentic search across apps such as Jira and Confluence\.
- **CrowdStrike**, which is customizing the model for agentic blue teaming in enterprise security\.
- **Dassault Systèmes**, powering engineering design and simulation\.
- **Perplexity**, for search and agentic tasks in Perplexity Search and Computer\.
- **[Salesforce](https://www.salesforce.com/news/press-releases/2026/09/15/koa-reasoning-model/)**, which is customizing Nemotron to power AI agents that digitize and automate complex government workflows in secure customer environments through Missionforce Operations\.
- **Synopsys**software for semiconductor design verification interoperates with the model\.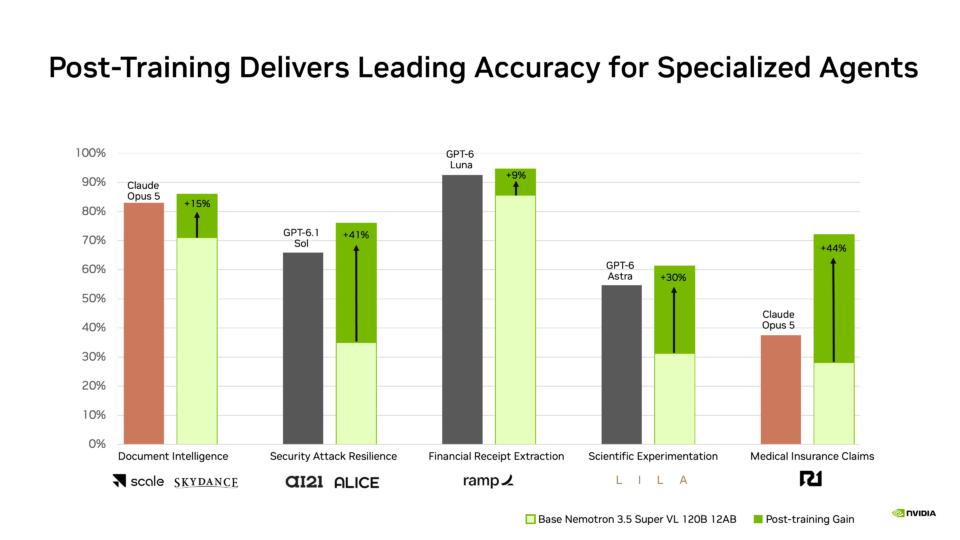
## What Nemotron 3\.5 Super VL Actually Sees
Nemotron 3\.5 Super VL’s[vision language](https://www.nvidia.com/en-us/glossary/vision-language-models/)strengths are targeted at what agents encounter in practice: optical character recognition, tables, charts and structured information in visual documents\.
It processes a web page, extracts text, reads graphs and charts, and returns insights from what it finds\. The same applies to PDFs and other documents agents commonly work with\.
Nemotron 3\.5 Super VL understands images, webpages and PDFs and acts on that understanding\. Combining text and visual understanding in one model means agents don’t need to route tasks between separate systems — context carries through as work moves from document to data to decision\.
## **Open for Maximum Control, Security, and Privacy**
Openness and customizability reinforce each other\. The model ships with open weights, open datasets and training recipes\.
Control runs in two directions\. Organizations can run the model wherever their security and data\-residency requirements dictate\. They also choose to adopt a model they can adapt, rather than one subject to a provider’s restrictions\.
In insurance, for example, a customized agent can scan claims for fraud markers on repeat\. In financial services, an agent can review credit scores and flag activity against an organization’s own lending criteria\. The model stays on premises\. The data stays private\.
Customization is supported through NVIDIA NeMo, Python\-based pipelines and open datasets\.
Nemotron 3\.5 Super VL was trained on about 26 trillion tokens across[pretraining](https://huggingface.co/collections/nvidia/nemotron-pre-training-datasets)and continued pretraining, then post\-trained with roughly 3\.8 million samples and reinforcement learning across dozens of environments\.
NVIDIA is also releasing open datasets on Hugging Face spanning[agentic tool use](https://huggingface.co/collections/nvidia/nemotron-post-training-v3), finance, instruction following, long context, fairness and vision\-language understanding, along with the reinforcement learning environments in NeMo Gym\.
[NVIDIA NIM](https://www.nvidia.com/en-us/ai-data-science/products/nim-microservices/)packages the model as a production\-ready microservice with performance\-optimized, validated configurations and enterprise\-grade support, refreshed every two weeks with security patches and performance improvements\.
And with the model running on NVIDIA Dynamo, organizations can serve up to 8x more users with 85% lower latency\.
Nemotron 3\.5 Super VL is available now on Hugging Face, Open Router,[ModelScopecommunity](https://modelscope.ai/collections/nv-community/Nemotron-35-Super-VL)and as NVIDIA NIM\.
## **Runs on DGX Spark, DGX Station, and RTX**
Nemotron 3\.5 Super VL runs across NVIDIA’s full hardware stack: on[DGX Spark](https://www.nvidia.com/en-us/products/workstations/dgx-spark/),[DGX Station](https://www.nvidia.com/en-us/products/workstations/dgx-station/), RTX PRO and RTX systems for local intelligence at the desktop, on[NVIDIA Jetson](https://www.nvidia.com/en-us/autonomous-machines/embedded-systems/)at the edge, and across data center and cloud environments\.
[Nemotron 3\.5 Bolt 74B\-A9B 24GB](https://research.nvidia.com/labs/nemotron/Nemotron-3.5-Bolt-24GB/)is available now on Hugging Face, with support for llama\.cpp,[Ollama](https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Bolt-74B-A9B-24GB-GGUF),[LM Studio](https://lmstudio.ai/models/nvidia/nemotron-3.5-bolt-74b-a9b),[Unsloth](https://unsloth.ai/docs/models/nemotron-3.5-bolt), and[vLLM](https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Bolt-74B-A9B-24GB)\. Built for[NVIDIA RTX Spark laptops](https://www.nvidia.com/en-us/products/rtx-spark/)arriving Oct\. 16, it also runs on[GeForce RTX PCs](https://www.nvidia.com/en-us/ai-on-rtx/),[DGX Spark](https://www.nvidia.com/en-us/products/workstations/dgx-spark/),[DGX Station](https://www.nvidia.com/en-us/products/workstations/dgx-station/)and[RTX PRO workstations](https://www.nvidia.com/en-us/products/workstations/)\.
*Download the*[*open weights*](https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Super-VL-120B-A12B-NVFP4)*, explore customization resources with NVIDIA NeMo, or read the*[*technical blog*](https://developer.nvidia.com/blog/nvidia-nemotron-3-5-super-vl-powers-specialized-agents-with-multimodal-reasoning/)*for the full architecture breakdown\.*
*Stay up to date on agents, NVIDIA*[*Nemotron*](https://www.nvidia.com/en-us/ai-data-science/foundation-models/nemotron/)*and more by subscribing to*[*NVIDIA news*](https://www.nvidia.com/en-us/executive-insights/generative-ai-tools/?modal=stay-inf)*,*[*joining the community*](https://developer.nvidia.com/community)*, and following NVIDIA AI on*[*LinkedIn*](https://www.linkedin.com/showcase/nvidia-ai/posts/?feedView=all)*,*[*Instagram*](https://www.instagram.com/nvidiaai/?hl=en)*,*[*X*](https://x.com/NVIDIAAIDev)*and*[*Facebook*](https://www.facebook.com/NVIDIAAI)*\.*
*Explore*[*self\-paced video tutorials and livestreams*](https://youtube.com/playlist?list=PL5B692fm6--vdRKB14FImVi7MTJ77zjn4&feature=shared)*\.*
*See*[*notice*](https://www.nvidia.com/en-eu/about-nvidia/terms-of-service/)*regarding software product information\.*
NVIDIA released the Nemotron 3 open model, offering three sizes: Nano, Super, and Ultra. It optimizes hardware efficiency through architectural innovations such as hybrid Mamba Transformer, latent MoE, and multi-token prediction, and adopts the Open MDW 1.1 open license.