<div id="bsf_rt_marker"></div><p><span style="font-weight: 400;">At GTC Berlin, NVIDIA is showcasing its full lineup of local AI hardware. </span><a target="_blank" href="https://www.nvidia.com/en-us/products/rtx-spark/"><span style="font-weight: 400;">RTX Spark</span></a><span style="font-weight: 400;">, which </span><a target="_blank" href="https://nvidianews.nvidia.com/news/nvidia-rtx-spark-pcs-available-today-a-new-beginning-for-windows-pcs"><span style="font-weight: 400;">launched last week</span></a><span style="font-weight: 400;">, powers personal agents on Windows PCs; </span><a target="_blank" href="https://www.nvidia.com/en-us/products/workstations/dgx-spark/"><span style="font-weight: 400;">DGX Spark</span></a><span style="font-weight: 400;"> supports developers building and scaling applications on Linux; and </span><a target="_blank" href="https://www.nvidia.com/en-us/products/workstations/dgx-station/"><span style="font-weight: 400;">DGX Station</span></a><span style="font-weight: 400;"> serves enterprise teams running frontier workloads on Linux, with a Windows version arriving in December.</span></p>
<p><span style="font-weight: 400;">Announcements include:</span></p>
<ul>
<li style="font-weight: 400;" aria-level="1"><span style="font-weight: 400;">Underdog Desktop Agent now available for RTX Spark</span></li>
<li style="font-weight: 400;" aria-level="1"><span style="font-weight: 400;">DGX Spark 64GB available on Friday, Oct. 23</span></li>
<li style="font-weight: 400;" aria-level="1"><span style="font-weight: 400;">NVIDIA Sync to support eight DGX Sparks and add Model Launcher this month</span></li>
<li style="font-weight: 400;" aria-level="1"><span style="font-weight: 400;">October DGX Spark software update adds Wi-Fi Assistant and updates DGX Spark Skills</span></li>
<li style="font-weight: 400;" aria-level="1"><span style="font-weight: 400;">DGX Station improves manageability with seven new integrations</span></li>
<li style="font-weight: 400;" aria-level="1"><span style="font-weight: 400;">DGX Station for Windows launches in December with support for many manufacturing apps and agent harnesses</span></li>
<li style="font-weight: 400;" aria-level="1"><span style="font-weight: 400;">Three new open source reference workflows for robotics on DGX Station</span></li>
<li style="font-weight: 400;" aria-level="1"><span style="font-weight: 400;">NVIDIA Cloud Functions is coming in early access to DGX Station</span></li>
<li style="font-weight: 400;" aria-level="1"><span style="font-weight: 400;">Recursive Flint, a new local coding model, is now available for NVIDIA local hardware</span></li>
<li style="font-weight: 400;" aria-level="1"><span style="font-weight: 400;">Day-0 support for new Nemotron, GLM, DeepSeek, Qwen, MiniMax and FLUX.3 AI models</span></li>
<li style="font-weight: 400;" aria-level="1"><span style="font-weight: 400;">New accelerations for llama.cpp and vLLM inference engines and a new collection of checkpoints optimized for local AI hardware.</span></li>
</ul>
<p><span style="font-weight: 400;">Learn more about these local AI announcements below, and check out the demos and </span><a target="_blank" href="https://www.nvidia.com/en-eu/gtc/session-catalog/"><span style="font-weight: 400;">sessions at GTC Berlin</span></a><span style="font-weight: 400;">.</span></p>
<div style="margin: 0 !important; padding: 0 !important; text-align: center; line-height: 1;"><a style="display: inline-flex; align-items: center; justify-content: center; margin: 0 !important; padding: 10px !important; background-color: #76b900; color: #ffffff !important; font-family: 'NVIDIA Sans', Arial, sans-serif; font-size: 16px; font-weight: bold; line-height: 1 !important; text-align: center; text-decoration: none !important; white-space: nowrap; vertical-align: top;" href="https://blogs.nvidia.com/gtc-berlin-2026-news/">Read All NVIDIA in Europe Announcements</a></div>
<p> </p>
<h2><b>RTX Spark Brings Personal Agents to the Windows PC</b></h2>
<p><span style="font-weight: 400;">RTX Spark is a new beginning for the PC — running personal agents, accelerated content creation and 1440p 100 frames-per-second gaming with up to 128GB of unified memory and 1 petaflop of AI compute.</span></p>
<p><span style="font-weight: 400;">Here’s what early reviewers are saying about the platform since its October 16 release:</span></p>
<p><i><span style="font-weight: 400;">“A dream machine for serious creators … ”</span></i><span style="font-weight: 400;"> — CGMag</span></p>
<p><i><span style="font-weight: 400;">“Designed for the future of AI … ”</span></i><span style="font-weight: 400;"> — The Verge</span></p>
<p><i><span style="font-weight: 400;">“An extremely capable, surprisingly portable and efficient machine … ”</span></i><span style="font-weight: 400;"> — PCMag</span></p>
<p><img fetchpriority="high" decoding="async" class="aligncenter size-large wp-image-99246" src="https://blogs.nvidia.com/wp-content/uploads/2026/10/topagentsoptimized-1680x945.png" alt="" width="1200" height="675" srcset="https://blogs.nvidia.com/wp-content/uploads/2026/10/topagentsoptimized-1680x945.png 1680w, https://blogs.nvidia.com/wp-content/uploads/2026/10/topagentsoptimized-960x540.png 960w, https://blogs.nvidia.com/wp-content/uploads/2026/10/topagentsoptimized-1280x720.png 1280w, https://blogs.nvidia.com/wp-content/uploads/2026/10/topagentsoptimized-1536x864.png 1536w, https://blogs.nvidia.com/wp-content/uploads/2026/10/topagentsoptimized-1290x725.png 1290w, https://blogs.nvidia.com/wp-content/uploads/2026/10/topagentsoptimized-630x355.png 630w, https://blogs.nvidia.com/wp-content/uploads/2026/10/topagentsoptimized-300x169.png 300w, https://blogs.nvidia.com/wp-content/uploads/2026/10/topagentsoptimized-400x225.png 400w, https://blogs.nvidia.com/wp-content/uploads/2026/10/topagentsoptimized.png 1999w" sizes="(max-width: 1200px) 100vw, 1200px" /></p>
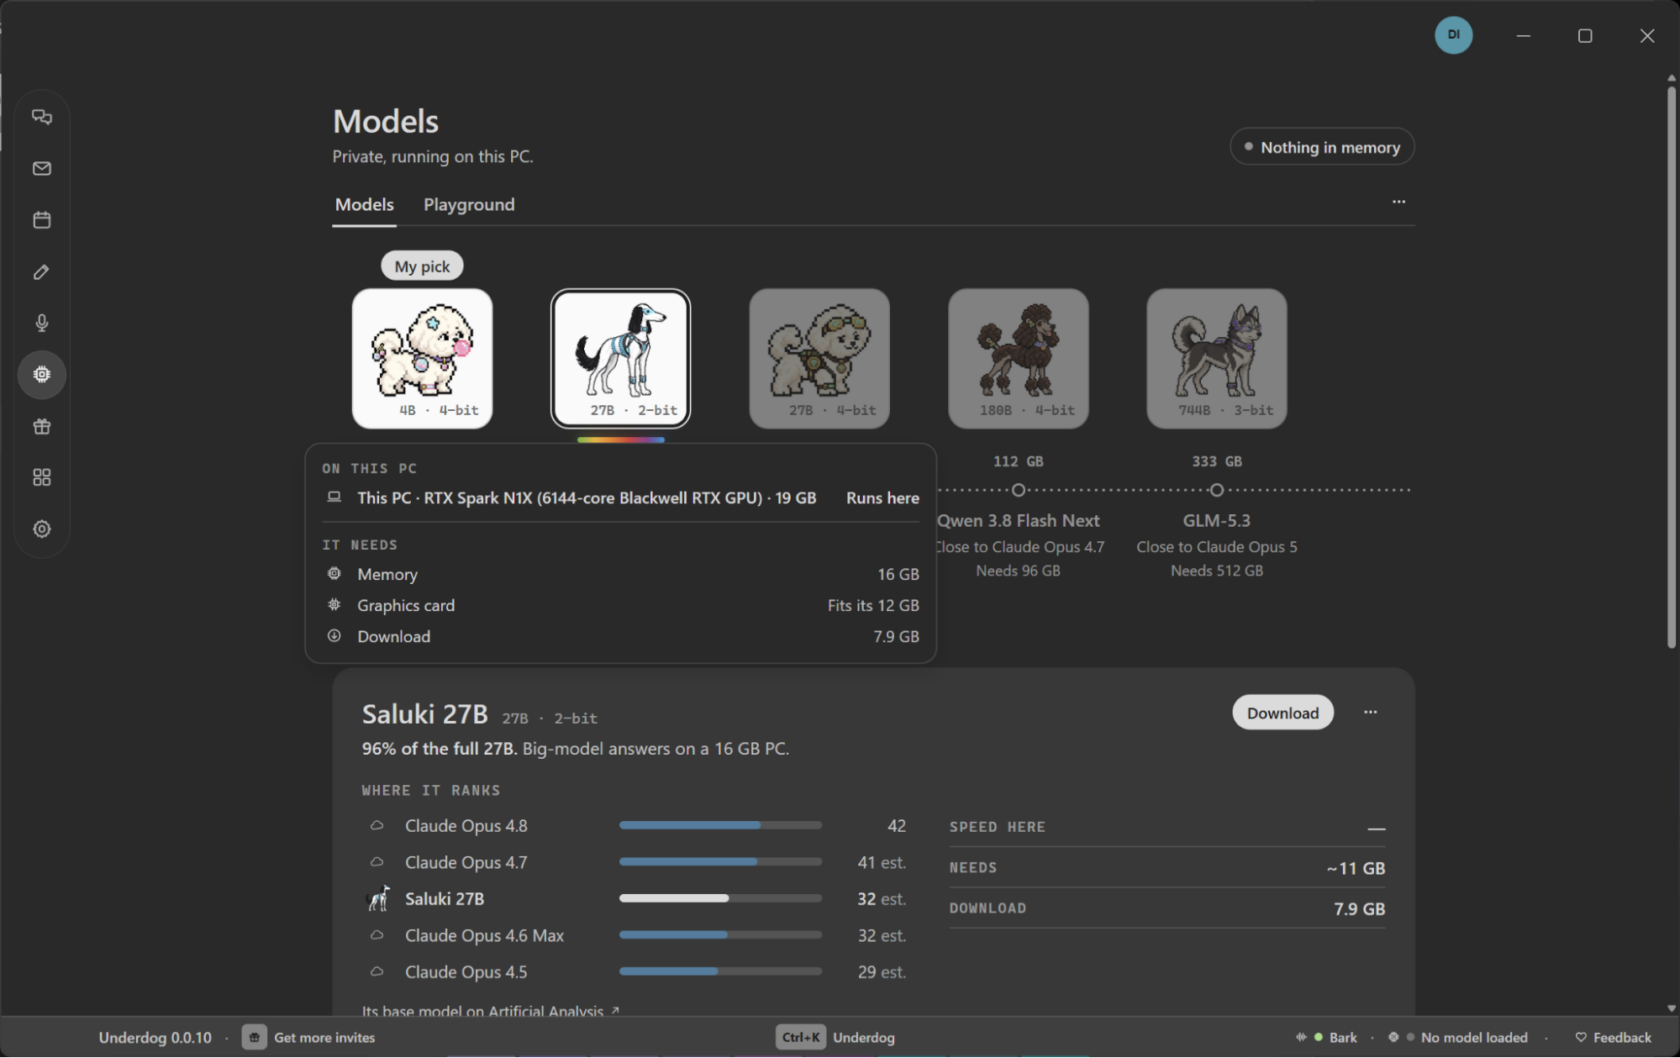
<p><span style="font-weight: 400;">Underdog</span><span style="font-weight: 400;">, a new desktop agent app built for fully local, private AI, is also bringing its experience to RTX Spark. Powered by its Husky model-specific inference engine, Underdog runs models entirely on device, so personal agents can get work done without user data ever leaving the PC. Underdog is available now for </span><a target="_blank" href="https://underdog.ai/download"><span style="font-weight: 400;">download</span></a><span style="font-weight: 400;">.</span></p>
<p><img decoding="async" class="aligncenter size-large wp-image-99247" src="https://blogs.nvidia.com/wp-content/uploads/2026/10/underdog-1680x1058.png" alt="" width="1200" height="756" srcset="https://blogs.nvidia.com/wp-content/uploads/2026/10/underdog-1680x1058.png 1680w, https://blogs.nvidia.com/wp-content/uploads/2026/10/underdog-960x605.png 960w, https://blogs.nvidia.com/wp-content/uploads/2026/10/underdog-1280x806.png 1280w, https://blogs.nvidia.com/wp-content/uploads/2026/10/underdog-1536x967.png 1536w, https://blogs.nvidia.com/wp-content/uploads/2026/10/underdog-630x397.png 630w, https://blogs.nvidia.com/wp-content/uploads/2026/10/underdog.png 1999w" sizes="(max-width: 1200px) 100vw, 1200px" /></p>
<p><span style="font-weight: 400;">To better enable developers and enthusiasts to build and customize local agents, many RTX Spark laptops come with an unlocked bootloader.</span></p>
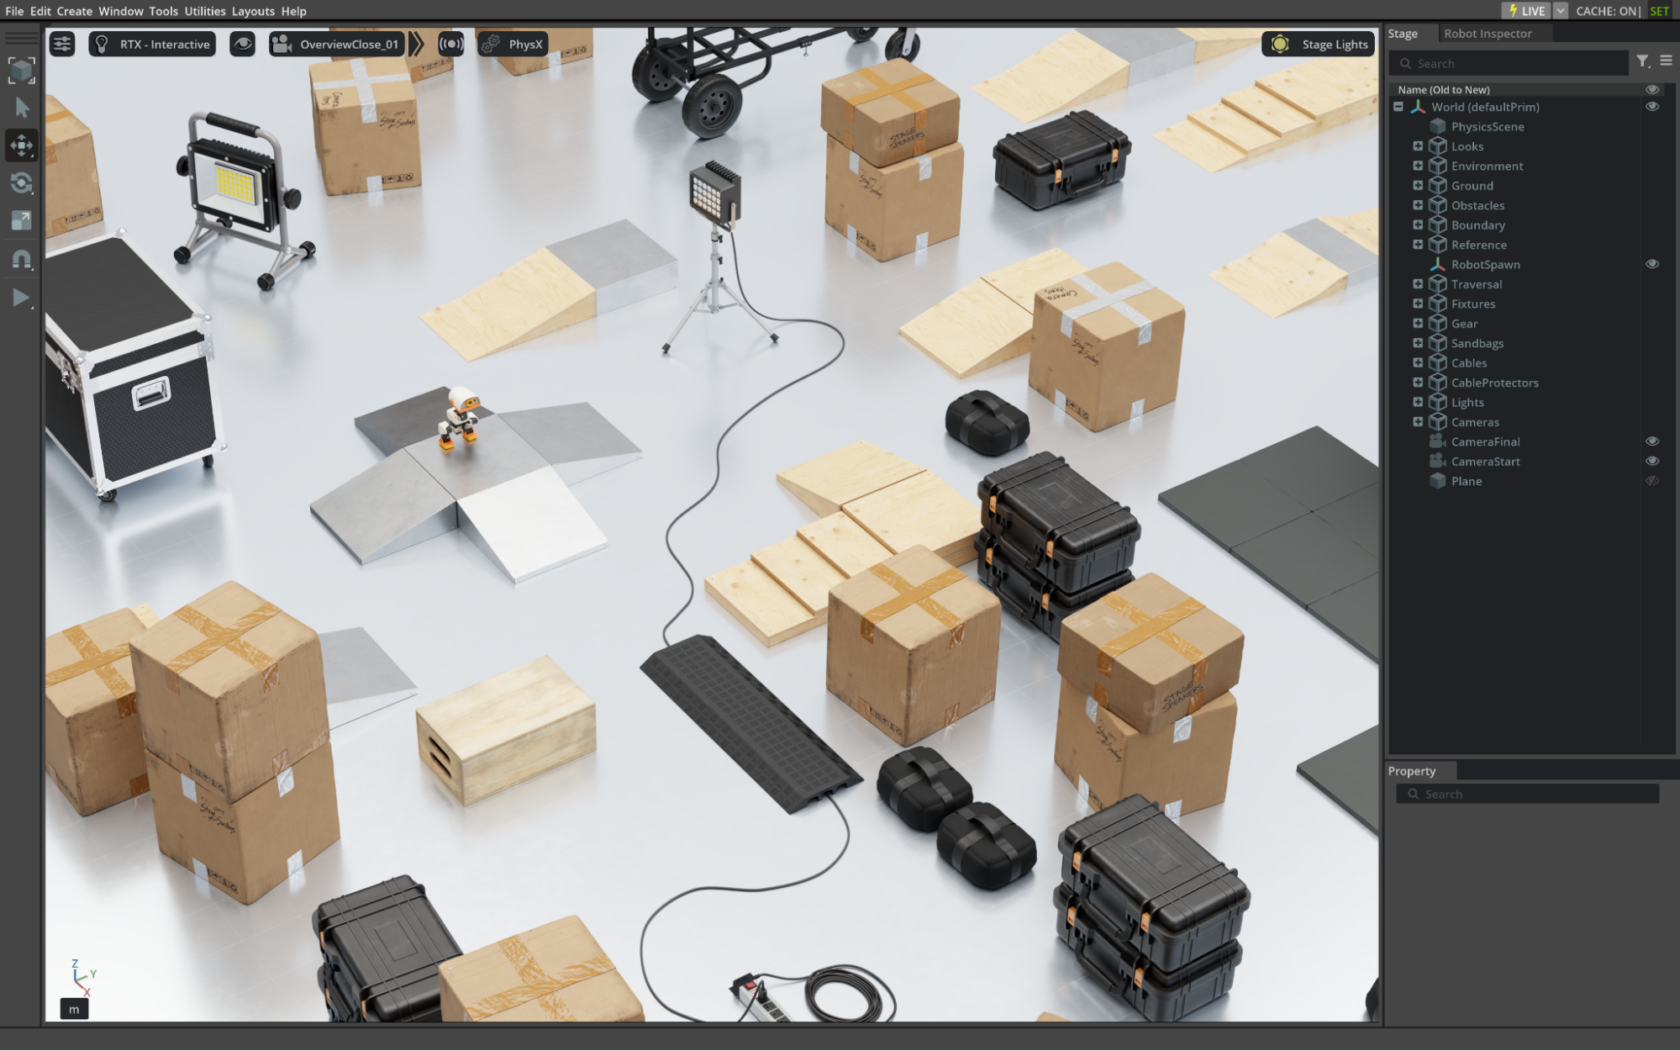
<p><span style="font-weight: 400;">During the GTC keynote, NVIDIA founder and CEO Jensen Huang showed off how AI agents running on RTX Spark can be used to train </span><a target="_blank" href="https://pollen-robotics.com/microduck/"><span style="font-weight: 400;">Hugging Face’s Microduck robot</span></a><span style="font-weight: 400;"> using NVIDIA Isaac Lab, Hermes Agent and Nemotron 3.5 Bolt 74B. </span></p>
<p><img decoding="async" class="aligncenter size-large wp-image-99248" src="https://blogs.nvidia.com/wp-content/uploads/2026/10/keynotedemo-1680x1051.png" alt="" width="1200" height="751" srcset="https://blogs.nvidia.com/wp-content/uploads/2026/10/keynotedemo-1680x1051.png 1680w, https://blogs.nvidia.com/wp-content/uploads/2026/10/keynotedemo-960x600.png 960w, https://blogs.nvidia.com/wp-content/uploads/2026/10/keynotedemo-1280x800.png 1280w, https://blogs.nvidia.com/wp-content/uploads/2026/10/keynotedemo-1536x960.png 1536w, https://blogs.nvidia.com/wp-content/uploads/2026/10/keynotedemo-630x394.png 630w, https://blogs.nvidia.com/wp-content/uploads/2026/10/keynotedemo.png 1999w" sizes="(max-width: 1200px) 100vw, 1200px" /></p>
<p><span style="font-weight: 400;">ASUS, Dell Technologies</span><span style="font-weight: 400;">, </span><span style="font-weight: 400;">HP</span><span style="font-weight: 400;">, Lenovo, </span><span style="font-weight: 400;">Microsoft </span><span style="font-weight: 400;">and </span><span style="font-weight: 400;">MSI </span><span style="font-weight: 400;">laptops are available today, with </span><span style="font-weight: 400;">Acer </span><span style="font-weight: 400;">coming soon.</span></p>
<p><span style="font-weight: 400;">Learn more about </span><a target="_blank" href="https://www.nvidia.com/en-us/products/rtx-spark/"><span style="font-weight: 400;">RTX Spark</span></a><span style="font-weight: 400;">, and get started with the latest </span><a target="_blank" href="https://build.nvidia.com/rtx-spark"><span style="font-weight: 400;">RTX Spark playbooks</span></a><span style="font-weight: 400;">.</span></p>
<h2><b>DGX Spark Gives Developers Room to Build</b></h2>
<p><span style="font-weight: 400;">New </span><a href="https://blogs.nvidia.com/blog/local-ai-dgx-spark-64gb-sync/"><span style="font-weight: 400;">DGX Spark 64GB systems</span></a><span style="font-weight: 400;"> — that can run models including Nemotron 3.5 Bolt 74B 24GB, Qwen3.8 27B and Gemma 4 26B-A4B — start rolling out from partners on Friday, Oct. 23.</span></p>
<p><span style="font-weight: 400;">When workloads require more capacity, developers can connect multiple DGX Spark systems via built-in NVIDIA ConnectX-7 networking and </span><a target="_blank" href="https://docs.nvidia.com/dgx/dgx-spark/nvidia-sync.html"><span style="font-weight: 400;">NVIDIA Sync Cluster Assistant</span></a><span style="font-weight: 400;">. This allows users to run advanced coding models like Qwen 3.8 Flash Next, DeepSeek v4 Flash 0731 and GLM 5.3 Flash.</span></p>
<p><span style="font-weight: 400;">Now, DGX Spark supports clusters of up to eight units in manual configuration, enabling larger models, longer contexts, concurrent agents and distributed development. Ideal for small teams sharing a single cluster as a backend, with each developer running concurrent sessions against the same model, it delivers 1TB of unified memory — enough to run frontier-class models like GLM 5.3.</span></p>
<p><span style="font-weight: 400;">Get started with the </span><a target="_blank" href="https://build.nvidia.com/spark/connect-multiple-sparks"><span style="font-weight: 400;">DGX Spark cluster playbook</span></a><span style="font-weight: 400;">.</span></p>
<p><span style="font-weight: 400;">NVIDIA Sync Model Launcher will also be available later this month. It simplifies access to local AI on a single DGX Spark or a cluster. With a few clicks, Model Launcher downloads a model and container suited to the configuration and connects the model to OpenCode. It automatically loads DGX Spark Skills for troubleshooting, device maintenance, access to official documentation and other workflow guidance.</span></p>
<p><span style="font-weight: 400;">The October DGX Spark software update brings a new Wi-Fi Assistant that lets users switch networks when DGX Spark is running in appliance mode. Plus, DGX Spark Skills provide workflow-focused guidance in troubleshooting and device maintenance directly into NVIDIA Sync via OpenCode.</span></p>
<p><span style="font-weight: 400;">DGX Spark systems are available directly from </span><span style="font-weight: 400;">Acer</span><span style="font-weight: 400;">, </span><span style="font-weight: 400;">ASUS</span><span style="font-weight: 400;">, </span><span style="font-weight: 400;">Dell Technologies</span><span style="font-weight: 400;">, </span><span style="font-weight: 400;">GIGABYTE</span><span style="font-weight: 400;">, </span><span style="font-weight: 400;">HP</span><span style="font-weight: 400;">, Lenovo, </span><span style="font-weight: 400;">MSI </span><span style="font-weight: 400;">and NVIDIA.</span></p>
<h2><b>DGX Station Puts Frontier Intelligence at the Desk</b></h2>
<p><span style="font-weight: 400;">For larger teams, DGX Station offers 748GB of coherent memory and up to 20 petaflops of AI performance, enabling developers to run advanced models like GLM 5.3 and serve 30+ users at speeds comparable to those provided by cloud models. Adding scale, NVIDIA Sync now supports DGX Station, simplifying connections between two Linux-based systems.</span></p>
<p><span style="font-weight: 400;">New integrations with </span><span style="font-weight: 400;">Absolute Security</span><span style="font-weight: 400;">, </span><span style="font-weight: 400;">Splunk by Cisco</span><span style="font-weight: 400;">, </span><a target="_blank" href="https://fleetdm.com/announcements/nvidia-gtc-2026"><span style="font-weight: 400;">Fleet Device Managemen</span><span style="font-weight: 400;">t</span></a><span style="font-weight: 400;">, </span><span style="font-weight: 400;">Microsoft Intune</span><span style="font-weight: 400;">, </span><span style="font-weight: 400;">Perforce Puppet</span><span style="font-weight: 400;">, </span><span style="font-weight: 400;">Progress Software Chef</span><span style="font-weight: 400;"> and </span><a target="_blank" href="https://www.tanium.com/press-releases/tanium-brings-enterprise-grade-manageability-to-nvidia-local-ai-infrastructure"><span style="font-weight: 400;">Tanium</span></a><span style="font-weight: 400;"> let IT teams manage DGX Station systems through enterprise setup, management and conformity processes, helping accelerate approvals and reduce deployment risk while minimizing time to first token.</span></p>
<p><span style="font-weight: 400;">With the upcoming Windows-based systems, developers can build workflows that harness professional applications, run on </span><a target="_blank" href="https://www.nvidia.com/en-us/products/workstations/"><span style="font-weight: 400;">NVIDIA RTX PRO GPUs</span></a><span style="font-weight: 400;"> and operate from agents that run their large language models (LLMs) on NVIDIA GB300 systems — all in one machine.</span></p>
<p><a target="_blank" href="https://www.nvidia.com/en-us/products/workstations/dgx-station-for-windows/"><span style="font-weight: 400;">DGX Station for Windows</span></a><span style="font-weight: 400;">, expected from system manufacturer partners in December, extends local AI into the applications and operating environment enterprises already use. Engineers can run local models and agents in Windows-native software with access to AI models, tools and agents on the same system.</span></p>
<p><span style="font-weight: 400;">DGX Station for Windows will feature support for manufacturing applications from </span><span style="font-weight: 400;">nTop</span><span style="font-weight: 400;">, </span><span style="font-weight: 400;">Dassault Systèmes</span><span style="font-weight: 400;">,</span> <span style="font-weight: 400;">Keysight Technologies</span><span style="font-weight: 400;">, </span><span style="font-weight: 400;">MathWorks</span><span style="font-weight: 400;">, </span><span style="font-weight: 400;">Rockwell Automation</span><span style="font-weight: 400;">, </span><span style="font-weight: 400;">Siemens</span><span style="font-weight: 400;">, </span><span style="font-weight: 400;">Synopsys</span><span style="font-weight: 400;">, </span><span style="font-weight: 400;">Unity</span><span style="font-weight: 400;"> and </span><span style="font-weight: 400;">Altera</span><span style="font-weight: 400;"> for AI-guided design, simulation, validation and engineering automation. Users will be able to run agents using </span><span style="font-weight: 400;">Hermes Agent</span><span style="font-weight: 400;">, </span><span style="font-weight: 400;">Perplexity</span><span style="font-weight: 400;"> or </span><span style="font-weight: 400;">Aible</span><span style="font-weight: 400;"> on premises for agentic control in enterprise environments.</span></p>
<p><span style="font-weight: 400;">The same local, controlled computing model extends to robotics. DGX Station gives robotics teams dedicated compute for post-training, simulation and evaluation, shortening iteration cycles without waiting for shared infrastructure.</span></p>
<p><a target="_blank" href="https://nvidianews.nvidia.com/news/nvidia-advances-isaac-platform-for-general-purpose-robotics-with-new-reference-humanoid-frameworks-simulation-pipelines-and-data"><span style="font-weight: 400;">NVIDIA released three open source reference workflows</span></a><span style="font-weight: 400;"> that bring GPT-6 Astra, NVIDIA Isaac Lab, Isaac Lab-Arena and Cosmos to NVIDIA DGX Station. Developers can use them to refine GR00T 1.7 models with reinforcement learning, train dexterous manipulation skills and post-train Cosmos world models for synthetic data generation.</span></p>
<p><a target="_blank" href="https://developer.nvidia.com/dgx-cloud/nvcf"><span style="font-weight: 400;">NVIDIA Cloud Functions</span></a><span style="font-weight: 400;"> is coming in early access to Linux-based DGX Station. Teams can register local model endpoints in a shared catalog and access them through one OpenAI-compatible entry point. </span></p>
<p><span style="font-weight: 400;">Developers can upgrade the model behind an endpoint without changing application code, while teammates can use shared models without direct machine access. This turns a DGX Station into a locally controlled inference service for a team. </span></p>
<p><span style="font-weight: 400;">DGX Station brings local iteration to AI factory development. On the show floor at GTC Berlin, NVIDIA is previewing </span><a target="_blank" href="https://www.nvidia.com/en-us/data-center/products/dsx-os/"><span style="font-weight: 400;">DSX OS</span></a><span style="font-weight: 400;"> running on DGX Station to simulate AI factory operations before full infrastructure is available. Another demo will showcase DGX Station systems powering a local token factory for more than 30 software developers.</span></p>
<p><span style="font-weight: 400;">DGX Station systems are shipping today from </span><span style="font-weight: 400;">ASUS</span><span style="font-weight: 400;">, </span><a target="_blank" href="https://www.dell.com/en-us/dt/corporate/newsroom/announcements/detailpage.press-releases~usa~2026~10~dell-technologies-and-nvidia-advance-enterprise-agentic-ai-from-the-deskside-to-data-center.htm#/filter-on/Country:en-us"><span style="font-weight: 400;">Dell Technologies</span></a><span style="font-weight: 400;">, </span><span style="font-weight: 400;">GIGABYTE</span><span style="font-weight: 400;">, </span><span style="font-weight: 400;">HP</span><span style="font-weight: 400;">, </span><span style="font-weight: 400;">MSI</span><span style="font-weight: 400;">, </span><span style="font-weight: 400;">Supermicro</span><span style="font-weight: 400;"> and </span><a target="_blank" href="https://www.exxactcorp.com/Exxact-VWS-158270643-E158270643"><span style="font-weight: 400;">Exxact</span></a><span style="font-weight: 400;">. DGX Station for Windows systems are expected to begin shipping later this year from </span><span style="font-weight: 400;">ASUS</span><span style="font-weight: 400;">, </span><span style="font-weight: 400;">Dell Technologies</span><span style="font-weight: 400;">, </span><span style="font-weight: 400;">GIGABYTE</span><span style="font-weight: 400;">, </span><span style="font-weight: 400;">HP</span><span style="font-weight: 400;">, </span><span style="font-weight: 400;">MSI </span><span style="font-weight: 400;">and </span><span style="font-weight: 400;">Supermicro</span><span style="font-weight: 400;">. </span></p>
<h2><b>Introducing Recursive Flint — A New Local Coding Model Optimized for RTX Spark</b><b></b></h2>
<p><span style="font-weight: 400;">Today, frontier AI lab Recursive Superintelligence released Recursive Flint, a local LLM built for fast, accurate coding. A 40-billion-parameter </span><a target="_blank" href="https://www.nvidia.com/en-us/glossary/mixture-of-experts/"><span style="font-weight: 400;">mixture-of-experts</span></a><span style="font-weight: 400;"> model with 2.5 billion active parameters, Recursive Flint delivers fast inference — over 220 tokens per second on a 64GB RTX Spark — along with best-in-class scores in agentic coding benchmarks like SWE-Bench Pro v2, Terminal-Bench 2.1 and SWE-bench verified.</span><b></b></p>
<p><span style="font-weight: 400;">Recursive Flint was built using Recursive’s Eureka Machine, a system for large-scale automated AI research. It automates the full research loop: proposes ideas, implements them, runs experiments to validate ideas and uses the results to decide what to try next — creating specialized kernels that boosted Flint’s generation speed on RTX Spark by 55% without changing the model’s weights.</span><b></b></p>
<p><span style="font-weight: 400;">Developers can </span><a target="_blank" href="https://huggingface.co/RecursiveSI"><span style="font-weight: 400;">download the open weights </span></a><span style="font-weight: 400;">on Hugging Face under the Apache 2.0 license and run the model on RTX Spark and DGX Spark systems, as well as GeForce RTX and RTX PRO GPUs. Developers can also post-train the model with </span><a target="_blank" href="https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/model-coverage/llm/flint/flint.mdx"><span style="font-weight: 400;">NeMo Automodel</span></a><span style="font-weight: 400;"> for supervised fine-tuning and </span><span style="font-weight: 400;">low-rank adaptation, or </span><span style="font-weight: 400;">LoRa, as well as </span><a target="_blank" href="https://github.com/NVIDIA-NeMo/RL/tree/flint-support"><span style="font-weight: 400;">NeMo RL</span></a><span style="font-weight: 400;"> for group relative policy optimization. </span></p>
<h2><b>New Models With Day-Zero Support</b></h2>
<p><span style="font-weight: 400;">NVIDIA is also adding day-zero model support for NVIDIA Nemotron Bolt E4B 4B, GLM, DeepSeek, Qwen, MiniMax, Liquid AI’s LFM2.5-24B-A2B, plus the FLUX.3 Klein diffusion model. </span></p>
<p><span style="font-weight: 400;">Nemotron Bolt E4B 4GB packs natural conversation and multi-turn agentic skills into as little as 4GB of memory, powering fast local voice assistants, interactive game characters and embedded interfaces on NVIDIA GeForce RTX GPUs, NVIDIA Jetson devices, and RTX and DGX Spark. Bolt E4B 4GB releases on Friday, Oct. 23. </span></p>
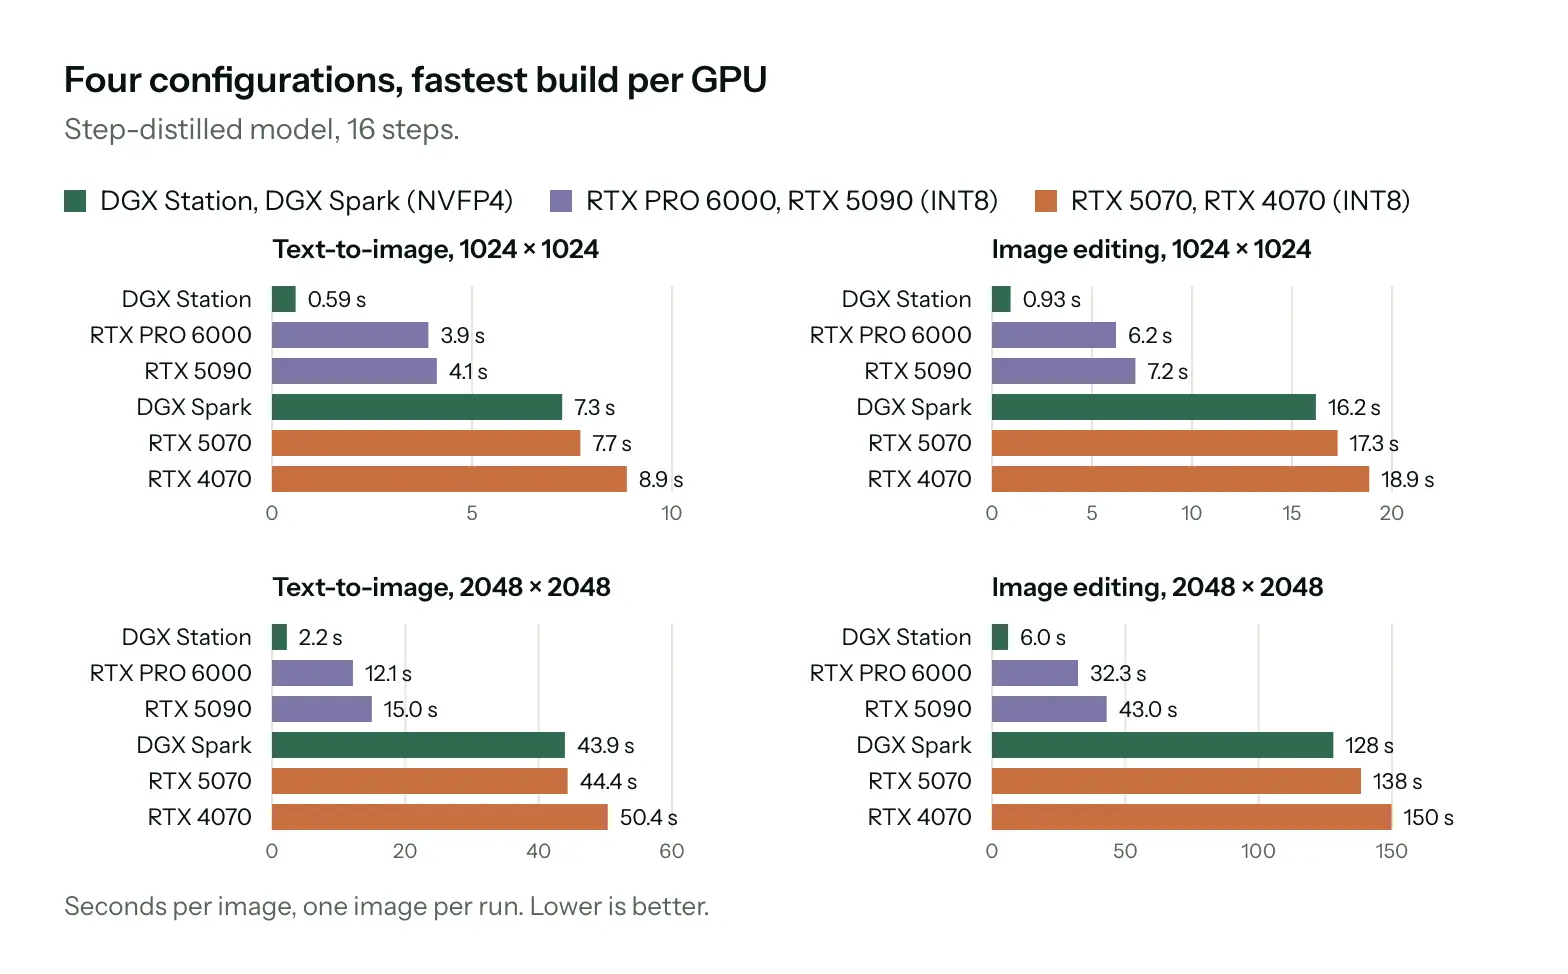
<p><span style="font-weight: 400;">Black Forest Labs’ FLUX 3 Image Klein is a 5.6-billion-parameter open weights image model for generation and editing. NVIDIA-optimized builds let it run on GeForce RTX GPUs with as little as 8GB of VRAM and create a 1-megapixel image in about four seconds on an RTX 5090 GPU.</span></p>
<p><img loading="lazy" decoding="async" class="aligncenter size-full wp-image-99249" src="https://blogs.nvidia.com/wp-content/uploads/2026/10/BFL-configs.png" alt="" width="1568" height="974" srcset="https://blogs.nvidia.com/wp-content/uploads/2026/10/BFL-configs.png 1568w, https://blogs.nvidia.com/wp-content/uploads/2026/10/BFL-configs-960x596.png 960w, https://blogs.nvidia.com/wp-content/uploads/2026/10/BFL-configs-1280x795.png 1280w, https://blogs.nvidia.com/wp-content/uploads/2026/10/BFL-configs-1536x954.png 1536w, https://blogs.nvidia.com/wp-content/uploads/2026/10/BFL-configs-630x391.png 630w" sizes="auto, (max-width: 1568px) 100vw, 1568px" /><span style="font-weight: 400;">MiniMax M3.1 Flash is a new open model built for NVIDIA DGX Station and DGX Spark, bringing long-context AI to the desktop. Liquid AI’s LFM2.5-24B-A2B is an open weights reasoning model that activates just 2 billion of its 24 billion parameters per token, making it fast enough to run private, tool-calling AI agents directly on PCs.</span></p>
<p><span style="font-weight: 400;">Plus, NVIDIA has released a new </span><a target="_blank" href="https://huggingface.co/collections/nvidia/local-ai-optimized-checkpoints"><span style="font-weight: 400;">collection of model checkpoints</span></a><span style="font-weight: 400;"> optimized for RAM efficiency on local AI hardware, enabling frontier-class open models to run with sufficient memory left over for KV cache. Each checkpoint is quantized while staying close to full-precision accuracy, starting with Qwen3.8-Flash-Next-FP4-Local on a single DGX Spark 128GB or RTX PRO 6000 and GLM-5.3-Flash-FP4-Local on two systems.</span></p>
<p><span style="font-weight: 400;">Developers can post-train on day zero with </span><a target="_blank" href="https://github.com/NVIDIA-NeMo/Automodel"><span style="font-weight: 400;">NeMo AutoModel</span></a><span style="font-weight: 400;"> on both DGX Spark and RTX Spark, with example recipes for </span><a target="_blank" href="https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/model-coverage/vlm/nvidia/nvidia-nemotron-3-5-bolt-74b-a9b-bf16.mdx"><span style="font-weight: 400;">Nemotron Bolt E4B</span></a><span style="font-weight: 400;">, </span><a target="_blank" href="https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/model-coverage/diffusion/black-forest-labs/flux3-image-klein.mdx"><span style="font-weight: 400;">Flux 3 Image Klein</span></a><span style="font-weight: 400;"> and more. </span></p>
<h2><b>Accelerated AI Inference</b></h2>
<p><span style="font-weight: 400;">NVIDIA continues to work with the llama.cpp and vLLM open source communities to accelerate agentic workloads on local hardware.</span></p>
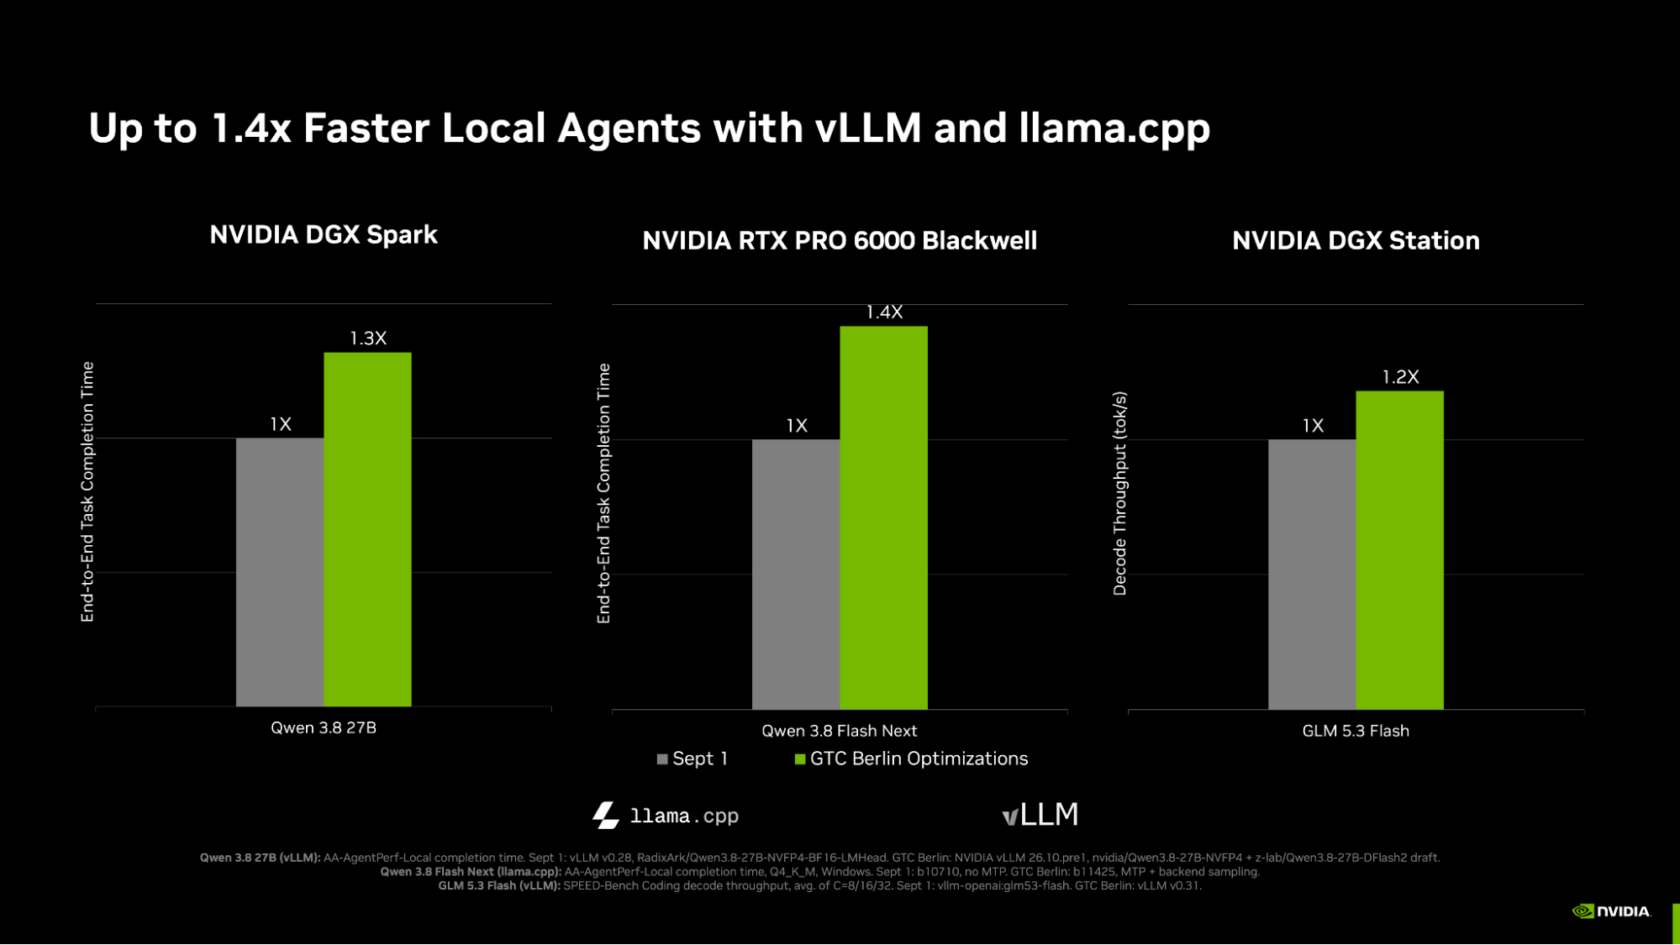
<p><span style="font-weight: 400;">In llama.cpp, new speculative decoding support with MTP for Qwen 3.8 Flash Next makes end-to-end agentic tasks up to 1.4x faster on NVIDIA RTX PRO 6000 Blackwell.</span></p>
<p><span style="font-weight: 400;">In vLLM, faster speculative decoding and new FlashInfer prefill kernels for Qwen’s linear-attention layers make agentic tasks with Qwen3.8 27B up to 1.3x faster on DGX Spark. On DGX Station, GLM 5.3 Flash gets up to 1.2x higher throughput.</span></p>
<p><img loading="lazy" decoding="async" class="aligncenter size-large wp-image-99250" src="https://blogs.nvidia.com/wp-content/uploads/2026/10/llama-1680x945.png" alt="" width="1200" height="675" srcset="https://blogs.nvidia.com/wp-content/uploads/2026/10/llama-1680x945.png 1680w, https://blogs.nvidia.com/wp-content/uploads/2026/10/llama-960x540.png 960w, https://blogs.nvidia.com/wp-content/uploads/2026/10/llama-1280x720.png 1280w, https://blogs.nvidia.com/wp-content/uploads/2026/10/llama-1536x864.png 1536w, https://blogs.nvidia.com/wp-content/uploads/2026/10/llama-1290x725.png 1290w, https://blogs.nvidia.com/wp-content/uploads/2026/10/llama-630x355.png 630w, https://blogs.nvidia.com/wp-content/uploads/2026/10/llama-300x169.png 300w, https://blogs.nvidia.com/wp-content/uploads/2026/10/llama-400x225.png 400w, https://blogs.nvidia.com/wp-content/uploads/2026/10/llama.png 1999w" sizes="auto, (max-width: 1200px) 100vw, 1200px" /></p>
<p><span style="font-weight: 400;">Check out </span><a target="_blank" href="https://localai-inference-recipes-4170b6.gitlab-master-pages.nvidia.com/index.html"><span style="font-weight: 400;">NVIDIA’s local AI inference recipes</span></a><span style="font-weight: 400;"> to try these latest optimizations.</span></p>
<p><i><span style="font-weight: 400;">Follow NVIDIA RTX Spark on </span></i><a target="_blank" href="https://x.com/NVIDIARTXSpark"><i><span style="font-weight: 400;">X</span></i></a><i><span style="font-weight: 400;">, </span></i><a target="_blank" href="https://www.instagram.com/nvidiartxspark/"><i><span style="font-weight: 400;">Instagram</span></i></a><i><span style="font-weight: 400;">, </span></i><a target="_blank" href="https://www.tiktok.com/@nvidiartxspark"><i><span style="font-weight: 400;">TikTok</span></i></a><i><span style="font-weight: 400;"> and </span></i><a target="_blank" href="https://www.facebook.com/NVIDIARTXSpark"><i><span style="font-weight: 400;">Facebook</span></i></a><i><span style="font-weight: 400;"> — and stay informed by subscribing to the </span></i><a target="_blank" href="https://www.nvidia.com/en-us/ai-on-rtx/?modal=subscribe-ai"><i><span style="font-weight: 400;">NVIDIA Local AI newsletter</span></i></a><i><span style="font-weight: 400;">. Follow NVIDIA Workstation on </span></i><a target="_blank" href="https://www.linkedin.com/showcase/3761136/"><i><span style="font-weight: 400;">LinkedIn</span></i></a><i><span style="font-weight: 400;"> and</span></i><a target="_blank" href="https://x.com/NVIDIAworkstatn"><i><span style="font-weight: 400;"> X</span></i></a><i><span style="font-weight: 400;">. </span></i></p>
<p><i><span style="font-weight: 400;">See</span></i><a target="_blank" href="https://www.nvidia.com/en-eu/about-nvidia/terms-of-service/"> <i><span style="font-weight: 400;">notice</span></i></a><i><span style="font-weight: 400;"> regarding software product information.</span></i><span style="font-weight: 400;"> </span></p>
<div style="margin: 0 !important; padding: 0 !important; text-align: center; line-height: 1;"><a style="display: inline-flex; align-items: center; justify-content: center; margin: 0 !important; padding: 10px !important; background-color: #76b900; color: #ffffff !important; font-family: 'NVIDIA Sans', Arial, sans-serif; font-size: 16px; font-weight: bold; line-height: 1 !important; text-align: center; text-decoration: none !important; white-space: nowrap; vertical-align: top;" href="https://blogs.nvidia.com/gtc-berlin-2026-news/">Read All NVIDIA in Europe Announcements</a></div>
<p> </p>
# Bringing the Spark to Europe: Local Intelligence Powers Next Wave of Agents
Source: [https://blogs.nvidia.com/blog/local-ai-gtc-rtx-dgx-spark-station-sync/](https://blogs.nvidia.com/blog/local-ai-gtc-rtx-dgx-spark-station-sync/)
At GTC Berlin, NVIDIA is showcasing its full lineup of local AI hardware\.[RTX Spark](https://www.nvidia.com/en-us/products/rtx-spark/), which[launched last week](https://nvidianews.nvidia.com/news/nvidia-rtx-spark-pcs-available-today-a-new-beginning-for-windows-pcs), powers personal agents on Windows PCs;[DGX Spark](https://www.nvidia.com/en-us/products/workstations/dgx-spark/)supports developers building and scaling applications on Linux; and[DGX Station](https://www.nvidia.com/en-us/products/workstations/dgx-station/)serves enterprise teams running frontier workloads on Linux, with a Windows version arriving in December\.
Announcements include:
- Underdog Desktop Agent now available for RTX Spark
- DGX Spark 64GB available on Friday, Oct\. 23
- NVIDIA Sync to support eight DGX Sparks and add Model Launcher this month
- October DGX Spark software update adds Wi\-Fi Assistant and updates DGX Spark Skills
- DGX Station improves manageability with seven new integrations
- DGX Station for Windows launches in December with support for many manufacturing apps and agent harnesses
- Three new open source reference workflows for robotics on DGX Station
- NVIDIA Cloud Functions is coming in early access to DGX Station
- Recursive Flint, a new local coding model, is now available for NVIDIA local hardware
- Day\-0 support for new Nemotron, GLM, DeepSeek, Qwen, MiniMax and FLUX\.3 AI models
- New accelerations for llama\.cpp and vLLM inference engines and a new collection of checkpoints optimized for local AI hardware\.
Learn more about these local AI announcements below, and check out the demos and[sessions at GTC Berlin](https://www.nvidia.com/en-eu/gtc/session-catalog/)\.
## **RTX Spark Brings Personal Agents to the Windows PC**
RTX Spark is a new beginning for the PC — running personal agents, accelerated content creation and 1440p 100 frames\-per\-second gaming with up to 128GB of unified memory and 1 petaflop of AI compute\.
Here’s what early reviewers are saying about the platform since its October 16 release:
*“A dream machine for serious creators … ”*— CGMag
*“Designed for the future of AI … ”*— The Verge
*“An extremely capable, surprisingly portable and efficient machine … ”*— PCMag
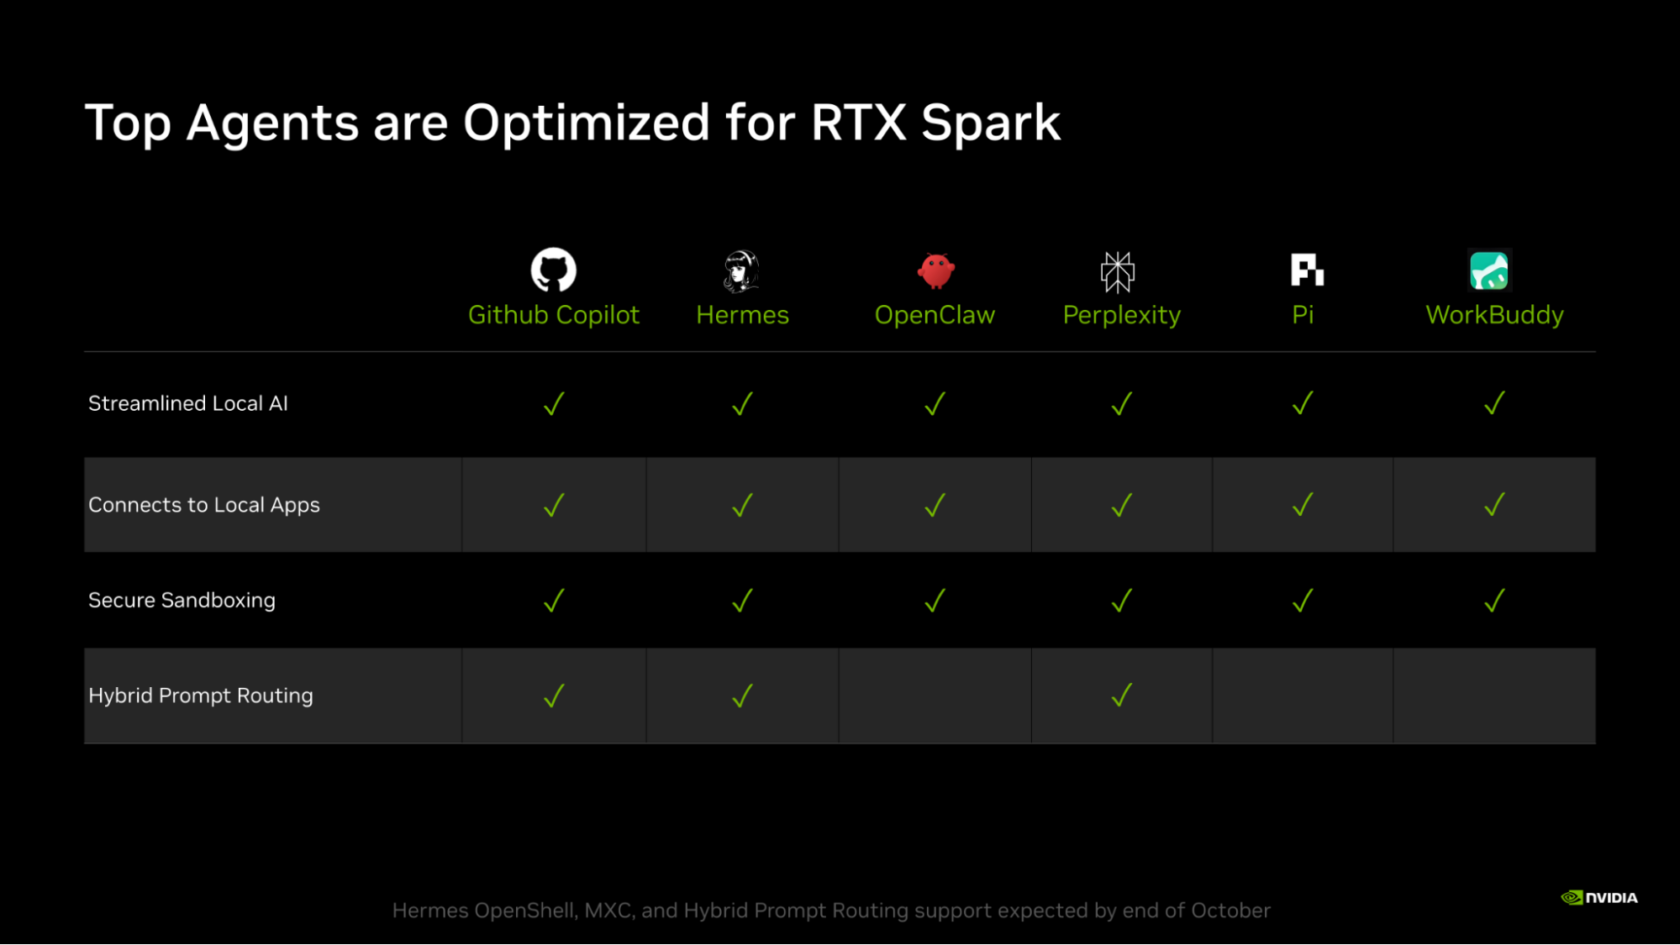
Underdog, a new desktop agent app built for fully local, private AI, is also bringing its experience to RTX Spark\. Powered by its Husky model\-specific inference engine, Underdog runs models entirely on device, so personal agents can get work done without user data ever leaving the PC\. Underdog is available now for[download](https://underdog.ai/download)\.
To better enable developers and enthusiasts to build and customize local agents, many RTX Spark laptops come with an unlocked bootloader\.
During the GTC keynote, NVIDIA founder and CEO Jensen Huang showed off how AI agents running on RTX Spark can be used to train[Hugging Face’s Microduck robot](https://pollen-robotics.com/microduck/)using NVIDIA Isaac Lab, Hermes Agent and Nemotron 3\.5 Bolt 74B\.
ASUS, Dell Technologies,HP, Lenovo,MicrosoftandMSIlaptops are available today, withAcercoming soon\.
Learn more about[RTX Spark](https://www.nvidia.com/en-us/products/rtx-spark/), and get started with the latest[RTX Spark playbooks](https://build.nvidia.com/rtx-spark)\.
## **DGX Spark Gives Developers Room to Build**
New[DGX Spark 64GB systems](https://blogs.nvidia.com/blog/local-ai-dgx-spark-64gb-sync/)— that can run models including Nemotron 3\.5 Bolt 74B 24GB, Qwen3\.8 27B and Gemma 4 26B\-A4B — start rolling out from partners on Friday, Oct\. 23\.
When workloads require more capacity, developers can connect multiple DGX Spark systems via built\-in NVIDIA ConnectX\-7 networking and[NVIDIA Sync Cluster Assistant](https://docs.nvidia.com/dgx/dgx-spark/nvidia-sync.html)\. This allows users to run advanced coding models like Qwen 3\.8 Flash Next, DeepSeek v4 Flash 0731 and GLM 5\.3 Flash\.
Now, DGX Spark supports clusters of up to eight units in manual configuration, enabling larger models, longer contexts, concurrent agents and distributed development\. Ideal for small teams sharing a single cluster as a backend, with each developer running concurrent sessions against the same model, it delivers 1TB of unified memory — enough to run frontier\-class models like GLM 5\.3\.
Get started with the[DGX Spark cluster playbook](https://build.nvidia.com/spark/connect-multiple-sparks)\.
NVIDIA Sync Model Launcher will also be available later this month\. It simplifies access to local AI on a single DGX Spark or a cluster\. With a few clicks, Model Launcher downloads a model and container suited to the configuration and connects the model to OpenCode\. It automatically loads DGX Spark Skills for troubleshooting, device maintenance, access to official documentation and other workflow guidance\.
The October DGX Spark software update brings a new Wi\-Fi Assistant that lets users switch networks when DGX Spark is running in appliance mode\. Plus, DGX Spark Skills provide workflow\-focused guidance in troubleshooting and device maintenance directly into NVIDIA Sync via OpenCode\.
DGX Spark systems are available directly fromAcer,ASUS,Dell Technologies,GIGABYTE,HP, Lenovo,MSIand NVIDIA\.
## **DGX Station Puts Frontier Intelligence at the Desk**
For larger teams, DGX Station offers 748GB of coherent memory and up to 20 petaflops of AI performance, enabling developers to run advanced models like GLM 5\.3 and serve 30\+ users at speeds comparable to those provided by cloud models\. Adding scale, NVIDIA Sync now supports DGX Station, simplifying connections between two Linux\-based systems\.
New integrations withAbsolute Security,Splunk by Cisco,[Fleet Device Management](https://fleetdm.com/announcements/nvidia-gtc-2026),Microsoft Intune,Perforce Puppet,Progress Software Chefand[Tanium](https://www.tanium.com/press-releases/tanium-brings-enterprise-grade-manageability-to-nvidia-local-ai-infrastructure)let IT teams manage DGX Station systems through enterprise setup, management and conformity processes, helping accelerate approvals and reduce deployment risk while minimizing time to first token\.
With the upcoming Windows\-based systems, developers can build workflows that harness professional applications, run on[NVIDIA RTX PRO GPUs](https://www.nvidia.com/en-us/products/workstations/)and operate from agents that run their large language models \(LLMs\) on NVIDIA GB300 systems — all in one machine\.
[DGX Station for Windows](https://www.nvidia.com/en-us/products/workstations/dgx-station-for-windows/), expected from system manufacturer partners in December, extends local AI into the applications and operating environment enterprises already use\. Engineers can run local models and agents in Windows\-native software with access to AI models, tools and agents on the same system\.
DGX Station for Windows will feature support for manufacturing applications fromnTop,Dassault Systèmes,Keysight Technologies,MathWorks,Rockwell Automation,Siemens,Synopsys,UnityandAlterafor AI\-guided design, simulation, validation and engineering automation\. Users will be able to run agents usingHermes Agent,PerplexityorAibleon premises for agentic control in enterprise environments\.
The same local, controlled computing model extends to robotics\. DGX Station gives robotics teams dedicated compute for post\-training, simulation and evaluation, shortening iteration cycles without waiting for shared infrastructure\.
[NVIDIA released three open source reference workflows](https://nvidianews.nvidia.com/news/nvidia-advances-isaac-platform-for-general-purpose-robotics-with-new-reference-humanoid-frameworks-simulation-pipelines-and-data)that bring GPT\-6 Astra, NVIDIA Isaac Lab, Isaac Lab\-Arena and Cosmos to NVIDIA DGX Station\. Developers can use them to refine GR00T 1\.7 models with reinforcement learning, train dexterous manipulation skills and post\-train Cosmos world models for synthetic data generation\.
[NVIDIA Cloud Functions](https://developer.nvidia.com/dgx-cloud/nvcf)is coming in early access to Linux\-based DGX Station\. Teams can register local model endpoints in a shared catalog and access them through one OpenAI\-compatible entry point\.
Developers can upgrade the model behind an endpoint without changing application code, while teammates can use shared models without direct machine access\. This turns a DGX Station into a locally controlled inference service for a team\.
DGX Station brings local iteration to AI factory development\. On the show floor at GTC Berlin, NVIDIA is previewing[DSX OS](https://www.nvidia.com/en-us/data-center/products/dsx-os/)running on DGX Station to simulate AI factory operations before full infrastructure is available\. Another demo will showcase DGX Station systems powering a local token factory for more than 30 software developers\.
DGX Station systems are shipping today fromASUS,[Dell Technologies](https://www.dell.com/en-us/dt/corporate/newsroom/announcements/detailpage.press-releases~usa~2026~10~dell-technologies-and-nvidia-advance-enterprise-agentic-ai-from-the-deskside-to-data-center.htm#/filter-on/Country:en-us),GIGABYTE,HP,MSI,Supermicroand[Exxact](https://www.exxactcorp.com/Exxact-VWS-158270643-E158270643)\. DGX Station for Windows systems are expected to begin shipping later this year fromASUS,Dell Technologies,GIGABYTE,HP,MSIandSupermicro\.
## **Introducing Recursive Flint — A New Local Coding Model Optimized for RTX Spark**
Today, frontier AI lab Recursive Superintelligence released Recursive Flint, a local LLM built for fast, accurate coding\. A 40\-billion\-parameter[mixture\-of\-experts](https://www.nvidia.com/en-us/glossary/mixture-of-experts/)model with 2\.5 billion active parameters, Recursive Flint delivers fast inference — over 220 tokens per second on a 64GB RTX Spark — along with best\-in\-class scores in agentic coding benchmarks like SWE\-Bench Pro v2, Terminal\-Bench 2\.1 and SWE\-bench verified\.
Recursive Flint was built using Recursive’s Eureka Machine, a system for large\-scale automated AI research\. It automates the full research loop: proposes ideas, implements them, runs experiments to validate ideas and uses the results to decide what to try next — creating specialized kernels that boosted Flint’s generation speed on RTX Spark by 55% without changing the model’s weights\.
Developers can[download the open weights](https://huggingface.co/RecursiveSI)on Hugging Face under the Apache 2\.0 license and run the model on RTX Spark and DGX Spark systems, as well as GeForce RTX and RTX PRO GPUs\. Developers can also post\-train the model with[NeMo Automodel](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/model-coverage/llm/flint/flint.mdx)for supervised fine\-tuning andlow\-rank adaptation, orLoRa, as well as[NeMo RL](https://github.com/NVIDIA-NeMo/RL/tree/flint-support)for group relative policy optimization\.
## **New Models With Day\-Zero Support**
NVIDIA is also adding day\-zero model support for NVIDIA Nemotron Bolt E4B 4B, GLM, DeepSeek, Qwen, MiniMax, Liquid AI’s LFM2\.5\-24B\-A2B, plus the FLUX\.3 Klein diffusion model\.
Nemotron Bolt E4B 4GB packs natural conversation and multi\-turn agentic skills into as little as 4GB of memory, powering fast local voice assistants, interactive game characters and embedded interfaces on NVIDIA GeForce RTX GPUs, NVIDIA Jetson devices, and RTX and DGX Spark\. Bolt E4B 4GB releases on Friday, Oct\. 23\.
Black Forest Labs’ FLUX 3 Image Klein is a 5\.6\-billion\-parameter open weights image model for generation and editing\. NVIDIA\-optimized builds let it run on GeForce RTX GPUs with as little as 8GB of VRAM and create a 1\-megapixel image in about four seconds on an RTX 5090 GPU\.
MiniMax M3\.1 Flash is a new open model built for NVIDIA DGX Station and DGX Spark, bringing long\-context AI to the desktop\. Liquid AI’s LFM2\.5\-24B\-A2B is an open weights reasoning model that activates just 2 billion of its 24 billion parameters per token, making it fast enough to run private, tool\-calling AI agents directly on PCs\.
Plus, NVIDIA has released a new[collection of model checkpoints](https://huggingface.co/collections/nvidia/local-ai-optimized-checkpoints)optimized for RAM efficiency on local AI hardware, enabling frontier\-class open models to run with sufficient memory left over for KV cache\. Each checkpoint is quantized while staying close to full\-precision accuracy, starting with Qwen3\.8\-Flash\-Next\-FP4\-Local on a single DGX Spark 128GB or RTX PRO 6000 and GLM\-5\.3\-Flash\-FP4\-Local on two systems\.
Developers can post\-train on day zero with[NeMo AutoModel](https://github.com/NVIDIA-NeMo/Automodel)on both DGX Spark and RTX Spark, with example recipes for[Nemotron Bolt E4B](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/model-coverage/vlm/nvidia/nvidia-nemotron-3-5-bolt-74b-a9b-bf16.mdx),[Flux 3 Image Klein](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/model-coverage/diffusion/black-forest-labs/flux3-image-klein.mdx)and more\.
## **Accelerated AI Inference**
NVIDIA continues to work with the llama\.cpp and vLLM open source communities to accelerate agentic workloads on local hardware\.
In llama\.cpp, new speculative decoding support with MTP for Qwen 3\.8 Flash Next makes end\-to\-end agentic tasks up to 1\.4x faster on NVIDIA RTX PRO 6000 Blackwell\.
In vLLM, faster speculative decoding and new FlashInfer prefill kernels for Qwen’s linear\-attention layers make agentic tasks with Qwen3\.8 27B up to 1\.3x faster on DGX Spark\. On DGX Station, GLM 5\.3 Flash gets up to 1\.2x higher throughput\.
Check out[NVIDIA’s local AI inference recipes](https://localai-inference-recipes-4170b6.gitlab-master-pages.nvidia.com/index.html)to try these latest optimizations\.
*Follow NVIDIA RTX Spark on*[*X*](https://x.com/NVIDIARTXSpark)*,*[*Instagram*](https://www.instagram.com/nvidiartxspark/)*,*[*TikTok*](https://www.tiktok.com/@nvidiartxspark)*and*[*Facebook*](https://www.facebook.com/NVIDIARTXSpark)*— and stay informed by subscribing to the*[*NVIDIA Local AI newsletter*](https://www.nvidia.com/en-us/ai-on-rtx/?modal=subscribe-ai)*\. Follow NVIDIA Workstation on*[*LinkedIn*](https://www.linkedin.com/showcase/3761136/)*and*[*X*](https://x.com/NVIDIAworkstatn)*\.*
*See*[*notice*](https://www.nvidia.com/en-eu/about-nvidia/terms-of-service/)*regarding software product information\.*
NVIDIA announced RTX Spark PCs and a wave of updates to enable local AI agents across RTX and DGX ecosystems, including the OpenShell runtime coming to Windows, NemoClaw expansion, performance improvements, and integrations with Adobe and H Company.
NVIDIA announces accelerated local AI tools, optimized models, and new RTX Spark hardware at IFA 2026 to enable faster and easier local AI inference for developers and enthusiasts.
NVIDIA and Google collaborate to optimize Gemma 4 models for local deployment across RTX GPUs, DGX Spark, and Jetson devices, enabling efficient on-device agentic AI with support for reasoning, coding, multimodal capabilities, and 35+ languages.
At a San Francisco event, NVIDIA and Microsoft announced RTX Spark laptops/compact desktops (up to 128GB unified memory, ~1 petaflop FP4) and the general availability of Microsoft Execution Containers (MXC) to run AI agents securely and locally on Windows PCs.