Cached at:
05/13/26, 04:14 AM
# what 262,715 regex questions on stack overflow haven't answered | ian erik varatalu
Source: [https://iev.ee/blog/what-262715-regex-questions-havent-answered/](https://iev.ee/blog/what-262715-regex-questions-havent-answered/)
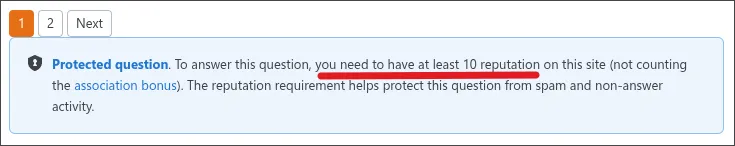
as part of my PhD research on regex engine algorithms and efficiency, i've been building[RE\#](https://github.com/ieviev/resharp), a regex engine with complement, intersection, and lookarounds\. i wanted to update some outdated regex answers on stack overflow, but i need 10 reputation to answer, and with[no one asking questions on there anymore](https://blog.pragmaticengineer.com/stack-overflow-is-almost-dead/)i got a little worried i wouldn't get the chance:
so instead i downloaded the[Stack Overflow data dump](https://stackoverflow.com/help/data-dumps), about 106GB of XML posts, and went through all 262,715 questions tagged`regex`, totalling 859,351,734 views\. i wanted to test RE\# against what people actually use regex for\.
this post is both a survey of common regex pain points and a demonstration of how these can be solved with RE\#\. a lot of the most\-viewed questions are about complement and intersection\. all benchmarks are[on github](https://github.com/ieviev/2026-05-stackoverflow)\.
there's too much to cover in one post, so this one focuses on the topics closest to my research\.
## the top 15
here are the 15 most\-viewed regex questions on stack overflow:
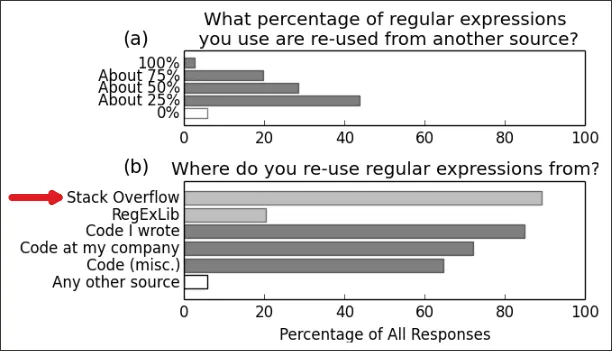
questionviewswhat it is1\.[Regular expression to match a line that doesn't contain a word](https://stackoverflow.com/q/406230)5\.5Mcomplement2\.[How can I validate an email address in JavaScript?](https://stackoverflow.com/q/46155)4\.9Mbasic validation3\.[RegEx match open tags except XHTML self\-contained tags](https://stackoverflow.com/q/1732348)4\.1Mhtml parsing4\.[How can I validate an email address using a regular expression?](https://stackoverflow.com/q/201323)2\.9Mbasic validation5\.[Regular expression for alphanumeric and underscores](https://stackoverflow.com/q/336210)1\.9Mbasic validation6\.[Regex that accepts only numbers \(0\-9\) and NO characters](https://stackoverflow.com/q/19715303)1\.8Mbasic validation7\.[Password regex: 8 chars, 1 uppercase, 1 special character, alphanumerics](https://stackoverflow.com/q/9477906)1\.8Mintersection8\.[How to match "any character" in regular expression?](https://stackoverflow.com/q/2912894)1\.8Mbasics9\.[Filter pandas DataFrame by substring criteria](https://stackoverflow.com/q/11350770)1\.6Mapi usage10\.[Regex: ignore case sensitivity](https://stackoverflow.com/q/9655164)1\.6Mflags11\.[Check whether a string matches a regex in JS](https://stackoverflow.com/q/6603015)1\.6Mapi usage12\.[Password regex: 8 chars, a number, upper\+lowercase, special characters](https://stackoverflow.com/q/19605150)1\.5Mintersection13\.[What is a good regular expression to match a URL?](https://stackoverflow.com/q/3809401)1\.5Mbasic validation14\.[Matching a space in regex](https://stackoverflow.com/q/559363)1\.5Mbasics15\.[Regex Match all characters between two strings](https://stackoverflow.com/q/6109882)1\.5Mbasicsmost of the top 15 are validation, API, or basics questions\. \#1, with 5\.5 million views, asks how to match a line that*doesn't*contain a word\. that's complement\. \#7 and \#12 are intersection \(multiple conditions at once\)\. these answers matter beyond stack overflow: a[2019 study of 193k\+ projects](https://dl.acm.org/doi/10.1145/3338906.3338909)found that developers frequently copy regexes into their own code without adapting them\.
## complement: matching what isn't there
complement means matching everything that*doesn't*match some pattern\. standard regex engines don't have a "not" operator, but the theory has existed since[Brzozowski's 1964 paper](https://dl.acm.org/doi/abs/10.1145/321239.321249)\. in RE\#,`~\(R\)`matches everything that`R`doesn't\. there are 56 questions about it on stack overflow with over 100k views:
top complement questions on stack overflow- **5\.5M:**[Regular expression to match a line that doesn't contain a word](https://stackoverflow.com/q/406230)
- **1\.4M:**[Negative matching using grep \(match lines that do not contain foo\)](https://stackoverflow.com/q/3548453)
- **1\.1M:**[A regular expression to exclude a word/string](https://stackoverflow.com/q/2078915)
- **1\.1M:**[How to negate specific word in regex?](https://stackoverflow.com/q/1240275)
- **1\.1M:**[How can I exclude one word with grep?](https://stackoverflow.com/q/4538253)
- **975k:**[Regex not operator](https://stackoverflow.com/q/7317043)
- **939k:**[Regex: match everything but a specific pattern](https://stackoverflow.com/q/1687620)
- **487k:**[Grep regex NOT containing a string](https://stackoverflow.com/q/10411616)
- **470k:**[How can I 'inverse match' with regex?](https://stackoverflow.com/q/164414)
the top answers are all lookahead workarounds\.
here are four common negative lookaround patterns from the top answers, benchmarked on 100 lines, each ~100 chars long:
questionfancy\-regexpcre2RE\#[not contain word](https://stackoverflow.com/q/406230),`^\(\(?\!W\)\.\)\*$`386\.9 us \(152x\)274\.5 us \(108x\)**2\.55 us \(1x\)**[not contain word](https://stackoverflow.com/q/406230),`^\(?\!\.\*W\)\.\*$`97\.3 us \(36x\)115\.4 us \(42x\)**2\.73 us \(1x\)**[not end with suffix](https://stackoverflow.com/q/16398471),`\.\*\(?<\!S\)$`69\.9 us \(32x\)6\.0 us \(2\.8x\)**2\.18 us \(1x\)**same, one long line \(10 KB\)1\.03 s \(69,281x\)204\.6 us \(14x\)**14\.86 us \(1x\)**[not start with prefix](https://stackoverflow.com/q/2116328),`^\(?\!P\)\.\*`86\.8 us \(34x\)5\.2 us \(2\.1x\)**2\.52 us \(1x\)**the first workaround is so common it has a name: the[tempered greedy token](https://www.rexegg.com/regex-quantifiers.html#tempered_greed)\. it re\-checks the condition at every character position, which is why it's over 150x slower even on short lines\. the lookbehind`\.\*\(?<\!S\)$`looks harmless at 32x on short lines, but scales quadratically: on a 10 KB line, fancy\-regex hits 69,281x\. these patterns show up in log filtering, URL routing, and input validation, anywhere you need to reject strings containing a word\.
with complement, all these follow the same structure:
```
^.*$ & ~(_*word_*)
| |
one line not containing "word"
```
where`\_\*`means "any string" \(or[try it in the web app](https://ieviev.github.io/resharp-webapp/)\)\. the point i want to make here is that the standard approach with lookarounds is slow because it's simulating a missing feature at search time\. when the engine understands complement directly, the negation is built in at compile time and has no cost at search time\.
## intersection: matching multiple conditions at once
similar story with intersection: matching strings that satisfy multiple patterns at once\. standard regex engines don't support it, so the standard answer is to chain`\(?=\.\*X\)`lookaheads \("before matching, look ahead and check that X exists somewhere"\)\. this works, but each lookahead runs a separate pass over the input\. two intersection questions made the top 15 \(\#7 and \#12\), and there are many more:
top intersection questions on stack overflow- **1\.5M:**[Regex for password must contain at least eight characters, at least one number and both lower and uppercase letters and special characters](https://stackoverflow.com/q/19605150)
- **1\.3M:**[Regular Expressions: Is there an AND operator?](https://stackoverflow.com/q/469913)
- **1\.2M:**[How is the AND/OR operator represented as in Regular Expressions?](https://stackoverflow.com/q/8020848)
- **517k:**[Match two strings in one line with grep](https://stackoverflow.com/q/4487328)
- **429k:**[How to find patterns across multiple lines using grep?](https://stackoverflow.com/q/2686147)
- **386k:**[Regex to match string containing two names in any order](https://stackoverflow.com/q/4389644)
- **345k:**[Regular Expression: Allow letters, numbers, and spaces \(with at least one letter or number\)](https://stackoverflow.com/q/576196)
- **314k:**[Regex AND operator](https://stackoverflow.com/q/3041320)
- **304k:**[RegEx to make sure that the string contains at least one lower case char, upper case char, digit and symbol](https://stackoverflow.com/q/1559751)
- **234k:**[Multiple words in any order using regex](https://stackoverflow.com/q/1177081)
here are three examples from the group:
questionfancy\-regexpcre2RE\#[password validator](https://stackoverflow.com/q/19605150)8\.4 us \(12x\)11\.4 us \(17x\)**682\.0 ns \(1x\)**non\-match10\.5 us \(15x\)14\.3 us \(20x\)**703\.0 ns \(1x\)**[two terms in a line/doc](https://stackoverflow.com/q/4487328)66\.3 us \(20x\)86\.6 us \(26x\)**3\.4 us \(1x\)**non\-match138\.0 us \(308x\)181\.4 us \(405x\)**448\.0 ns \(1x\)**[N words in any order](https://stackoverflow.com/q/1177081)190\.1 us \(381x\)267\.1 us \(535x\)**499\.0 ns \(1x\)**non\-match330\.2 us \(23x\)372\.6 us \(26x\)**14\.1 us \(1x\)**with intersection, these are`R & S`, evaluated in a single pass, without lookarounds:
```
_*jack_* & _*james_*
| |
contains "jack" contains "james"
```
## lookaheads are not intersection
the performance cost is one thing, but lookaheads and intersection are not actually the same operation\.
consider`\(?=\.\*A\)\(?=\.\*B\)\.\{3\}`on the input`xyz\_\_\_\_\_\_\_AB`\. hit play to see what happens:
`\(?=\.\*A\)\(?=\.\*B\)\.\{3\}`on`"xyz\_\_\_\_\_\_\_AB"`
the lookaheads scan forward independently of the matched substring\. they confirm that A and B exist*somewhere*ahead, then`\.\{3\}`consumes three characters, none of which contain A or B\. the match is`xyz`\.
with real intersection,`\(\_\*A\_\*\)&\(\_\*B\_\*\)&\.\{3\}`requires A and B to appear**in the matched substring itself**\. there is no 3\-character substring \(in the beginning\) of`xyz\_\_\_\_\_\_\_AB`that contains both A and B, so it doesn't match\.
lookaheads happen to overlap with intersection on one common case: when the entire remaining string is consumed \(e\.g\.`\(?=\.\*A\)\(?=\.\*B\)\.\*`\)\. but the moment the match doesn't consume the exact same characters, lookaheads and the matched substring are out of sync\. chained lookaheads are not "regex AND"\.
## matching until
"match up to X", "match between X and Y", "stop at the first occurrence": the usual answer is a lazy loop:`\.\*?DELIM`\. this can backtrack catastrophically when repeated \(most engines are backtracking\-based\)\. what may surprise you is that you don't actually need lazy loops to express this at all\. but let's look at some examples first\.
top matching until questions on stack overflow- **1\.5M:**[Regex Match all characters between two strings](https://stackoverflow.com/q/6109882)
- **1\.4M:**[How can I match "anything up until this sequence of characters" in a regular expression?](https://stackoverflow.com/q/7124778)
- **1\.2M:**[Regular expression to stop at first match](https://stackoverflow.com/q/2503413)
- **1\.0M:**[Matching up to the first occurrence of a character with a regular expression](https://stackoverflow.com/q/2013124)
- **695k:**[Regex match everything after question mark?](https://stackoverflow.com/q/4419000)
- **688k:**[How can I write a regex which matches non greedy?](https://stackoverflow.com/q/11898998)
- **539k:**[What do 'lazy' and 'greedy' mean in the context of regular expressions?](https://stackoverflow.com/q/2301285)
- **437k:**[Regex to get the words after matching string](https://stackoverflow.com/q/19193251)
- **185k:**[Regex for extracting filename from path](https://stackoverflow.com/q/9363145)
- **159k:**[Regex Until But Not Including](https://stackoverflow.com/q/3850074)
to show how this scales, here are the same patterns benchmarked on matching vs non\-matching inputs\. python's`re`is included here as a representative unoptimized backtracking engine:
questionpython`re`fancy\-regexpcre2RE\#[up to a sequence](https://stackoverflow.com/q/7124778),`\.\*?END`24\.4 us \(16x\)11\.4 us \(7\.5x\)35\.5 us \(23x\)**1\.5 us \(1x\)**non\-match48\.40 ms \(1,125,581x\)75\.0 ns \(1\.7x\)**43\.0 ns \(1x\)**97\.0 ns \(2\.3x\)[between`\[``\]`](https://stackoverflow.com/q/6109882)7\.1 us \(5\.0x\)4\.8 us \(3\.5x\)8\.8 us \(6\.4x\)**1\.4 us \(1x\)**non\-match920\.8 us \(27,903x\)656\.0 ns \(20x\)**33\.0 ns \(1x\)**38\.0 ns \(1\.2x\)5`<div\>`groups466\.0 ns \(13\.6x\)154\.0 ns \(4\.5x\)693\.0 ns \(20\.2x\)**34\.3 ns \(1x\)**non\-match8\.00 ms \(29,630x\)459\.0 ns \(1\.7x\)16\.72 ms \(61,926x\)**270\.0 ns \(1x\)**python blows up on non\-match in all three cases\. fancy\-regex delegates these to rust's`regex`engine since they don't need backtracking features, so it's fine\. pcre2 has optimized some of these away, but not completely: repeat the lazy loop \(row 3\) and it also goes over 60,000x slower on non\-match\. any template engine or scraper that uses repeated lazy loops to extract sections from HTML is vulnerable to this on malformed input\. the common workaround`\[^,\]\*`only works for single\-char delimiters\. for multi\-char delimiters like`</div\>`, there's no escape hatch in standard regex\.
complement gives you another way to express this, without lazy loops:
```
~(_*</div>_*) </div>
| |
not contains </div> then </div>
```
## other performance and security issues
these next ones look innocuous, but specific backtracking engines handle them badly\.
regex performance problems have[their own CWE](https://app.opencve.io/cve/?q=cwe:CWE-1333), and new ones show up daily\.
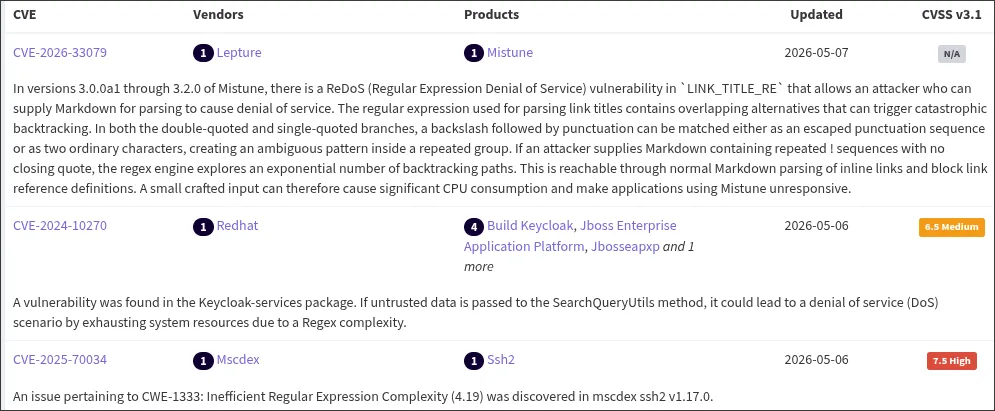
most answers about regex assume a backtracking engine: try possibilities one at a time, backtrack on failure\. each engine has patched different blowups, but not all of them can be patched\. i'll link[Russ Cox's writeup](https://swtch.com/~rsc/regexp/regexp1.html)here\.
i'll avoid the textbook cases like`\(a\+\)\+b`\. instead, here are three real world scenarios where the blowups differ between backtracking engines\.
### python`re`'s quadratic blowup on`\(\.\*\)sol\(\.\*\)`
this one caught my eye\. from["why python regex is so slow?"](https://stackoverflow.com/q/26214328):
> the first test string is 220K long, matches, and the matching is quite fast\. the second test string is 20K long, does not match and it takes 5 seconds to compute\!
this pattern has nothing obviously wrong with it, and almost all backtracking engines handle it fine\. python's`re`does not:
pattern / inputpython`re`python`regex`pcre2fancy\-regex`\(\.\*\)sol\(\.\*\)`245\.6 us \(4\.5x\)**54\.5 us \(1x\)**788\.3 us \(14\.5x\)217\.2 us \(4\.0x\)non\-match22\.40 s \(15,630,846x\)20\.9 us \(14\.6x\)1\.55 ms \(1,079x\)**1\.4 us \(1x\)**`\.\*foo\.\*bar`88\.8 us \(1\.1x\)**77\.6 us \(1x\)**1\.08 ms \(13\.9x\)220\.0 us \(2\.8x\)non\-match4\.62 s \(6,572,546x\)101\.3 us \(144x\)**703\.0 ns \(1x\)**1\.4 us \(2\.0x\)python is fine on a match\. on a non\-match,**22 seconds**for 100 KB\. and it's not the capture groups:`\.\*foo\.\*bar`without captures is just as bad\.
### java's quadratic lookbehinds
`\(?<=From:\.\*\)alice`finds "alice" after a`From:`header using a variable\-length lookbehind\. onlya few engines\*pcre2, fancy\-regex, and python's`re`don't support variable\-length lookbehinds\.even support these\. the input is`From: alice@example\.com`followed by N lines of filler\. one match\. java:
input sizejavapython`regex`regress1\.5 KB4\.6 ms \(39,014x\)1\.2 us \(10x\)**117\.8 ns \(1x\)**5\.8 KB73\.8 ms \(396,774x\)3\.2 us \(17x\)**186\.0 ns \(1x\)**14\.5 KB434\.5 ms \(1,448,170x\)6\.0 us \(20x\)**300\.1 ns \(1x\)**29 KB1\.73 s \(3,580,662x\)11\.4 us \(24x\)**483\.4 ns \(1x\)**58 KB6\.87 s \(7,905,639x\)22\.0 us \(25x\)**869\.1 ns \(1x\)**java tries every possible start position for the lookbehind, making it O\(n²\)\. porting a regex with lookarounds between engines can quietly introduce quadratic behavior\.
### CSV column 10:`^\(\.\*?,\)\{10\}P$`
the usual pattern for "give me CSV column 10", variants in[Q21443370](https://stackoverflow.com/q/21443370),[Q26138582](https://stackoverflow.com/q/26138582),[Q53528067](https://stackoverflow.com/q/53528067)\. same problem as the`<div\>`example above: lazy loop inside repetition\. on a non\-match, the engine tries every way of distributing characters across the 10 groups\. exponential\.
inputpython`re`python`regex`fancy\-regexpcre2match417\.0 ns \(9\.1x\)1\.0 us \(22x\)**46\.0 ns \(1x\)**352\.0 ns \(7\.7x\)`,`x20, non\-match13\.71 ms \(507,711x\)41\.39 ms \(1,533,033x\)38\.0 ns \(1\.4x\)**27\.0 ns \(1x\)**`,`x25, non\-match144\.52 ms \(5,352,445x\)475\.43 ms \(17,608,494x\)44\.0 ns \(1\.6x\)**27\.0 ns \(1x\)**`,`x30, non\-match992\.43 ms \(36,756,581x\)3\.58 s \(132,418,139x\)53\.0 ns \(2\.0x\)**27\.0 ns \(1x\)**python`re`and`regex`both go exponential\. the input`,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,`\(30 commas\) takes python`regex`**3\.58 seconds**\. python keeps showing up because its engine is less optimized than other backtracking engines\. if a service uses a pattern like this to parse CSV, an attacker can send a crafted non\-matching input and hang the server\.
## there are two kinds of regex engine
the main distinction is backtracking or no backtracking\. the specific automata underneath \(Hyperscan's Glushkov automata, RE2's/Rust's Thompson automata, RE\#'s/\.NET's symbolic automata\) matters much less than this one bit\.
part of the reason i went digging through stack overflow is that there's a dogma around regex engines: a set of assumptions that get passed down unchallenged\. the accepted answer on["why python regex is so slow?"](https://stackoverflow.com/q/26214328)is a good example\. it opens by stating non\-backtracking engines swap the meaning of`\.\*`and`\.\*?`\(they don't\), then quotes the readme of a toy implementation: "This regex engine underperforms Python's re module" and concludes:
> Fixing the pathological case at the expense of the typical is probably a good reason not to use the NFA approach as a default engine, not when the pathological case can simply be avoided instead\.
this reasoning shows up everywhere, and at some point it stopped being questioned\.
the benchmarks above already show that non\-backtracking engines can match or beat backtracking ones on real\-world patterns, not just pathological ones\. they're not just a fix for one narrow security issue\. backtracking is exponential in the worst case, and no amount of per\-pattern patches changes that\. but the ecosystem is built on backtracking semantics, switching means breaking compatibility, another incremental patch is always easier than rethinking the engine\.
one fair criticism: the Thompson NFA, which most non\-backtracking engines use, scales poorly on complex patterns\. but that's a limitation of the Thompson NFA, not of non\-backtracking engines\. DFAs and lazy DFAs don't have this problem\.
out of 262,715 regex questions on stack overflow, only 231 even mention the word "backtracking"\. most developers never learn there's a choice, andthe standard reference\*Friedl's[Mastering Regular Expressions](https://www.oreilly.com/library/view/mastering-regular-expressions/0596528124/), widely considered the regex bible, grouped backtracking and non\-backtracking engines together as "NFA engines", making the most important distinction in regex engines invisible to a generation of developers\.did this no favors\.
more performance questions on stack overflow- **399k:**[fastest way to check a string contain another substring in javascript?](https://stackoverflow.com/q/5296268)
- **228k:**[regex\.test vs string\.match](https://stackoverflow.com/q/10940137)
- **193k:**[fastest method to escape html tags as html entities?](https://stackoverflow.com/q/5499078)
- **152k:**[fastest way to check if a string matches a regexp in ruby?](https://stackoverflow.com/q/11887145)
- **112k:**[efficient regex for canadian postal code function](https://stackoverflow.com/q/15774555)
- **110k:**[`\\d`less efficient than`\[0\-9\]`?](https://stackoverflow.com/q/16621738)
- **93k:**[speed up millions of regex replacements in python 3](https://stackoverflow.com/q/42742810)
- **76k:**[sonarqube showing regular expression denial of service \(redos\)](https://stackoverflow.com/q/61478960)
- **40k:**[is regex too slow? real life examples where simple non\-regex alternative is better](https://stackoverflow.com/q/2667015)
- **34k:**[why python regex is so slow?](https://stackoverflow.com/q/26214328)
- **22k:**[why is std::regex notoriously much slower than other regular expression libraries?](https://stackoverflow.com/q/70583395)
## `\\d`is not`\[0\-9\]`
not all regex problems are about performance\. while going through the validation questions, one stood out for a different reason\.
[Q16621738](https://stackoverflow.com/q/16621738)\(110k views\) asks whether`\\d`is less efficient than`\[0\-9\]`\. the performance difference is minor\. they don't match the same thing\.
in e\.g\. \.NET, python, and rust, the default`\\d`matches Unicode digits \(~370 digits in \.NET, ~770 in Rust\), not just ASCII 0\-9\. that includes Eastern Arabic \(`٠١٢٣`\), Devanagari \(`०१२३`\), Fullwidth \(`0123`\), and many others\.
this means`^\\d\{16\}$`as a credit card validator will happily accept`٤٥٣٢١٦٧٨٩٠١٢٣٤٥٦`\. the regex matches\. downstream code that parses those bytes as ASCII digits will misparse or crash\. and if that string lands in a fixed\-size buffer, an ASCII digit is 1 byte but a Unicode digit can be up to 4 in UTF\-8, so 16 "digits" could be 64 bytes\. that's a buffer overflow, past the regex\. this is the kind of thing that ends up on hackerone\.
---
since[the last post](https://iev.ee/blog/symbolic-derivatives-and-the-rust-rewrite-of-resharp), i've run RE\# against 400,000 regexes and inputs, comparing results with the rust regex crate\. all differences \(~1%\) were from longest\-match semantics, which RE\# uses by design\. i think it's close to being industrially useful\. if you find patterns where RE\# is slow, open an issue\.
all examples are[on github](https://github.com/ieviev/2026-05-stackoverflow)\. in part two: the famous "you can't parse HTML with regex" question, and more cases where the problem isn't performance at all\.