@berryxia: 兄弟们,我后背没有发凉。 但,我看到这个模型架构后高兴不已! 大家还在疯狂堆参数、卷通用大模型的时候,Interfaze直接用一个全新混合架构。 把OCR、视觉、STT、结构化输出这些确定性任务的准确率干到了吊打Gemini-3-Flas…
摘要
Interfaze introduces a new hybrid AI model architecture combining DNN/CNN encoders with transformers to achieve superior accuracy and cost-efficiency for deterministic tasks like OCR, vision, and STT compared to generalist models.
查看缓存全文
缓存时间: 2026/05/13 12:19
兄弟们,我后背没有发凉。 但,我看到这个模型架构后高兴不已! 大家还在疯狂堆参数、卷通用大模型的时候,Interfaze直接用一个全新混合架构。 把OCR、视觉、STT、结构化输出这些确定性任务的准确率干到了吊打Gemini-3-Flash、Claude-Sonnet-4.6、GPT-5.4-Mini和Grok-4.3的程度。 他们把任务专用的DNN/CNN编码器和全能transformer融合在一起,实现了真正的“专精+灵活”:CNN负责极致准确和元数据(边界框、置信度)。 transformer负责理解和推理,还能通过
Interfaze: A new model architecture built for high accuracy at scale
Source: https://interfaze.ai/blog/interfaze-a-new-model-architecture-built-for-high-accuracy-at-scale tl;dr: Interfaze is a new model architecture that outperforms models like Gemini-3-Flash, Claude-Sonnet-4.6, GPT-5.4-Mini, and Grok-4.3 across 9 head-to-head benchmarks in OCR, vision, STT, and structured output.
Humans are inefficient at computer-level tasks. We make mistakes, but we’re great at decision-making and understanding nuance.
Imagine telling a human to read a 50-page PDF, map every word to another document with its XY position, and translate the whole thing into Chinese. You’d get tons of mistakes, pay a lot to keep that human on payroll, and wait a long time for the result.
Transformer models are similar. They’re amazing at nuance and human-level tasks, and they make mistakes like a human, but that’s also what keeps them creative.
We’ve been using the wrong models for the wrong tasks.
CNNs/DNNs have existed since the early 90s, from LeNet-5 to ResNet, and more recently CRNN-CTC.
These are deep neural network architectures that are task-specific for things like OCR, translation, or GUI detection. The way they consume and see data is trained to be task specific, which makes them up to 100x more accurate at their specific task. They also produce useful metadata like bounding boxes and confidence scores, letting developers build predictable workflows they can rely on.
So why do so many of us still go for transformers/LLMs for deterministic tasks?
DNNs are not flexible. They’re only as good as their training data, and they aren’t great at human-level nuance.
They might be cheap to serve but expensive to maintain and retrain for new tasks. Take a passport: a CNN can extract the date of birth with bounding boxes and a confidence score, but it can’t calculate the person’s age.
Introducing Interfaze
A new model architecture that merges the specialization of DNN/CNN models with omni-transformers, giving you the best of both worlds.
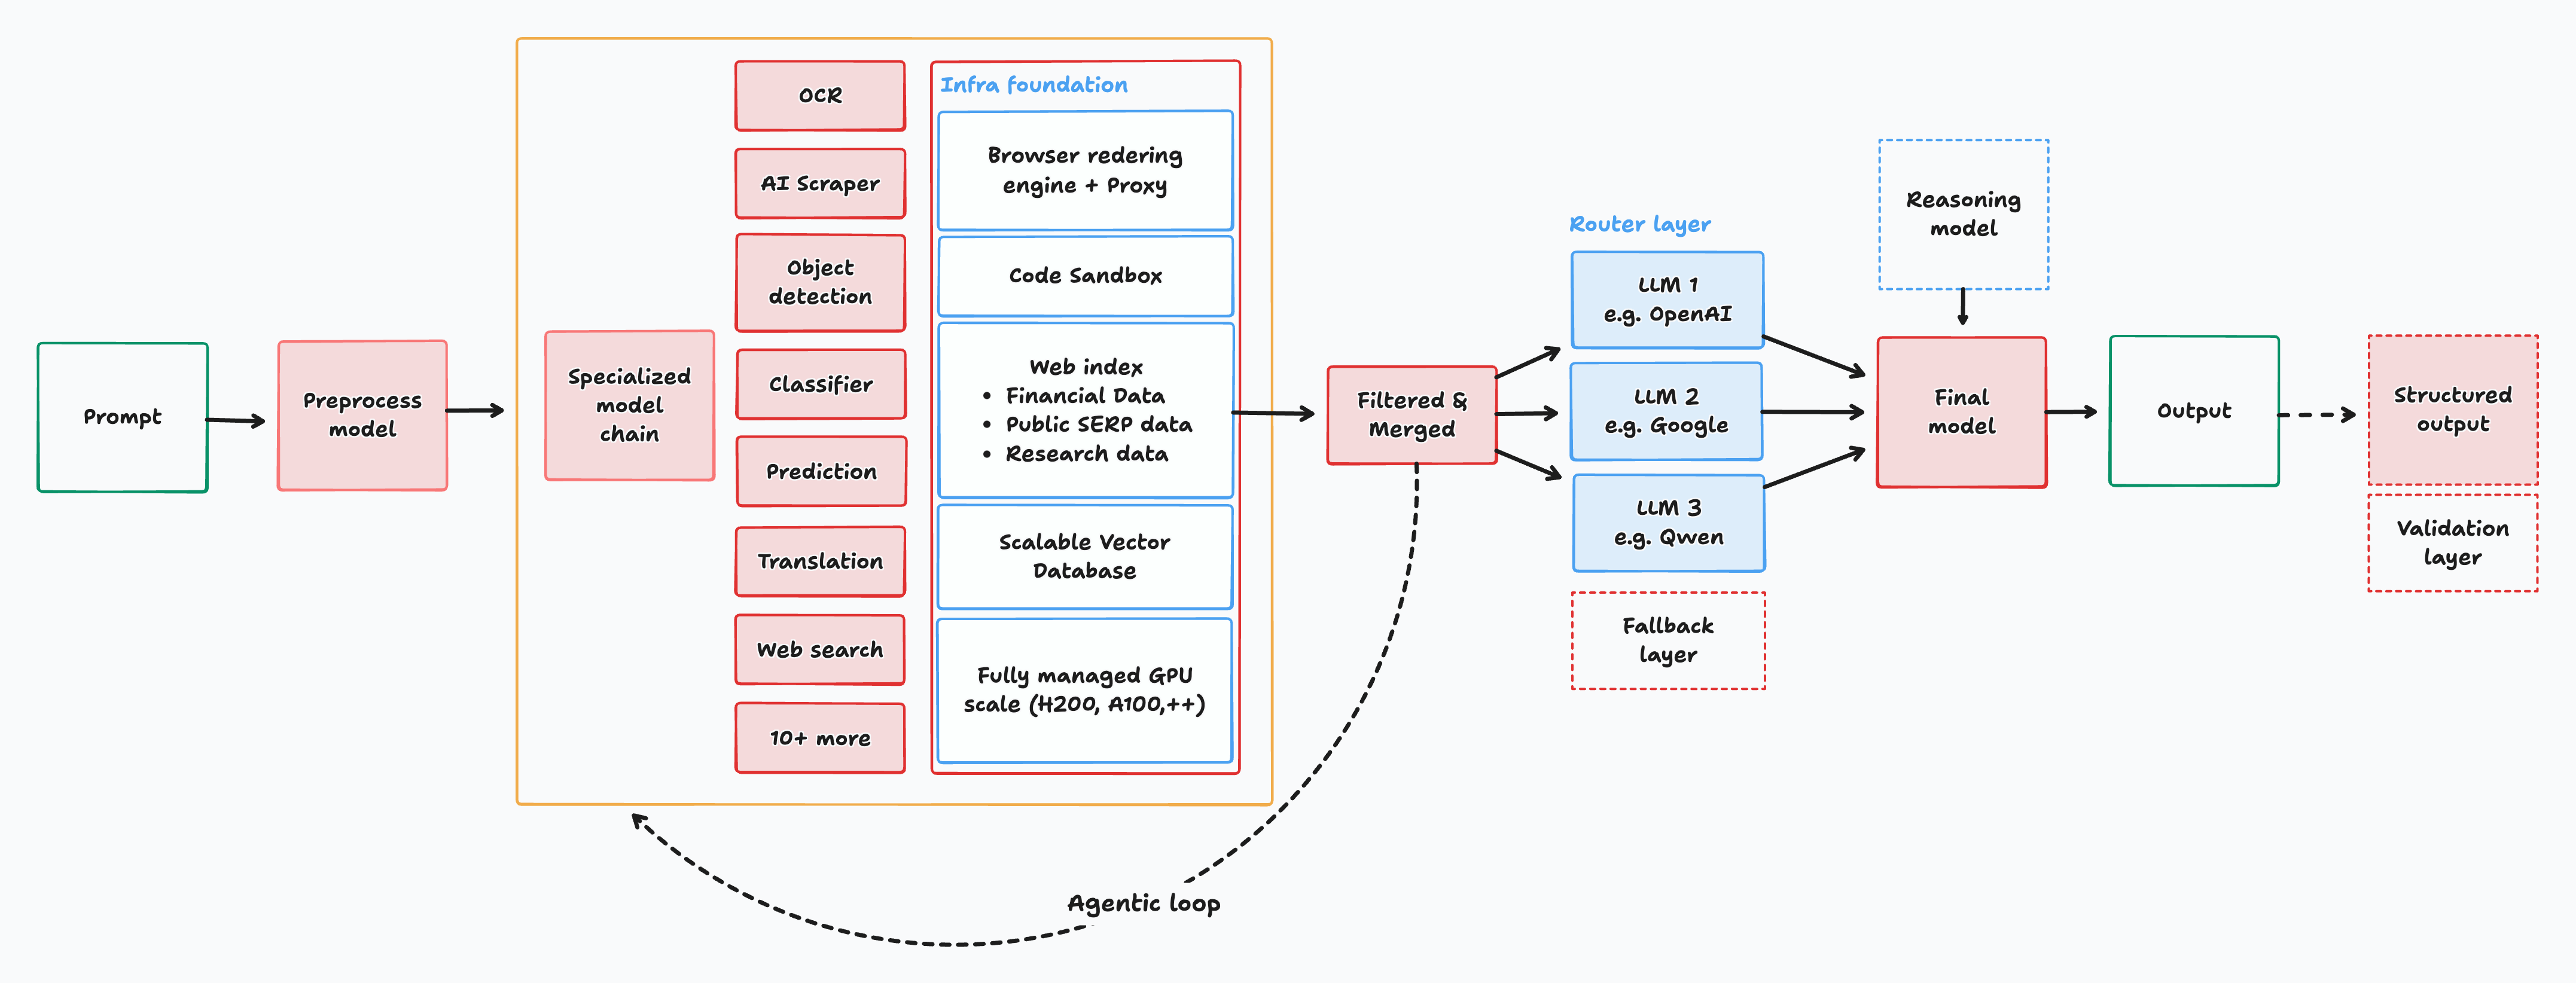 That means high accuracy and low cost on deterministic tasks:
- Vision (image and document, object and GUI detection)
- Web extraction and search
- Audio (STT and speaker diarization)
- Translation
- Video (coming soon)
Model specs
FeatureValueContext window1M tokensMax output tokens32k tokensInput modalitiesText, Images, Audio, FileReasoningAvailable (default: disabled)
Benchmark
While Pro tier models like Claude Opus 4.7 and GPT 5.5 are the best generalist models in the market today for things like coding and complex reasoning tasks, they aren’t commonly used for high volume tasks like OCR or translation due to high cost and slow response times.
Interfaze is benchmarked against models in similar pricing tiers and feature sets that are optimized to squeeze the most performance out of the model at the fastest speed, while keeping cost low at scale.
Today, most people reach for two model categories for deterministic developer tasks:
- Flash/mini modelslike Gemini-3-Flash, GPT-5.4-Mini and Claude Sonnet 4.6. The best balance you can get between performance and price at scale.
- Specialized providerslike Reducto, Mistral OCR or Whisper.
Breakdown
BenchmarkInterfazeGemini-3-FlashClaude-Sonnet-4.6GPT-5.4-MiniGrok-4.3**OCRBench V270.7%**55.8%54.7%52.7%54.7%**olmOCR85.7%**75.3%73.9%80.1%81.9%**RefCOCO82.1%**75.2%75.5%67.0%25.0%VoxPopuli (WER)↓**2.4%**4.0%———**Spider 2.0-Lite52.9%**45.2%49.6%26.7%45.9%**GPQA Diamond89.9%**88.5%**89.9%**82.8%73.6%**MMMLU90.9%**88.7%84.9%75.3%89.7%**MMMU-Pro71.1%**67.6%46.3%40.4%68.7%**SOB Value Acc79.5%**77.3%77.9%75.1%78.4% ↓ = lower is better (word error rate). — = not scored (model has no native audio input). All other rows: higher is better.
Each model is compared head-to-head across nine benchmarks: OCRBench V2, olmOCR, RefCOCO, VoxPopuli-Cleaned-AA, SOB Value, Spider-2.0-Lite, GPQA Diamond, MMMLU, and MMMU-Pro.
Interfaze leads in almost every benchmark, against both specialized models in each category and the generalist flash/mini models.
Our goal isn’t to replace LLMs. It’s to specialize in deterministic tasks. The benchmarks focus on categories like OCR, object detection, and structured output, with a few general benchmarks like GPQA Diamond to show the level of problem-solving and understanding you’d expect from any transformer model.
Interfaze is priced in a similar range as Gemini-3-Flash, at**1\.50 per million input tokens**and**3.50 per million output tokens**.
OCR is our number one use case
Our number one use case from users has been OCR for images and complex, long PDFs.
Interfaze outperforms OCR providers like Chandra OCR and Reducto, and generalist models like Gemini-3-Flash and GPT-5.4-Mini.
It isn’t just the task-specific CNN encoder doing a good job. It’s the ability to lean on object detection for figures and graphics, or lean on the translation layers of the transformer all in a shared vector space.
Structured output is a big part of determinism
Most LLMs today are great at following a JSON schema, but pretty bad at filling it with accurate values. No public benchmark measures the accuracy of those values, so we releasedSOB (the Structured Output Benchmark)last week.
**TL;DR:**SOB gives the model the correct answer in its context, then asks it to generate a JSON output with data it already has. We measure who is the most accurate, with the fewest mistakes and hallucinations, across text, image, and audio modalities (all normalized to text).
Compared against the same flash/mini set used throughout this post. See thefull SOB leaderboardfor all 28 models, including frontier Pro-tier models like Gemini-3.1-Pro, GPT-5.5, and Claude-Opus-4.7.
There’s still huge room for improving structured output without raising cost or compute. Follow us onXorLinkedInto follow our research journey.
Multilingual performance beyond English
Interfaze has great multilingual performance across a wide range of languages.
Speech-to-text on par with specialized ASR providers
On VoxPopuli-Cleaned-AA, Interfaze comes in second on word error rate.
Speech-to-text inference speed
Interfaze transcribes 209 seconds of audio per second of compute, ~1.5× faster than Deepgram Nova-3, ~8× faster than Scribe v2, and over 11× faster than Gemini-3-Flash.
View full VoxPopuli benchmarks →
Here’s how you get started
Set up your SDK
Interfaze speaks the Chat Completions API standard, so any AI SDK that supports OpenAI works out of the box: just point it athttps://api\.interfaze\.ai/v1. Grab your API key from theInterfaze dashboardand drop it in.
OpenAI SDK
Vercel AI SDK
LangChain SDK
import OpenAI from "openai";

const interfaze = new OpenAI({
	baseURL: "https://api.interfaze.ai/v1",
	apiKey: "<your-api-key>",
});
The sameinterfazeclient is reused in every example below.
Complex OCR + object detection
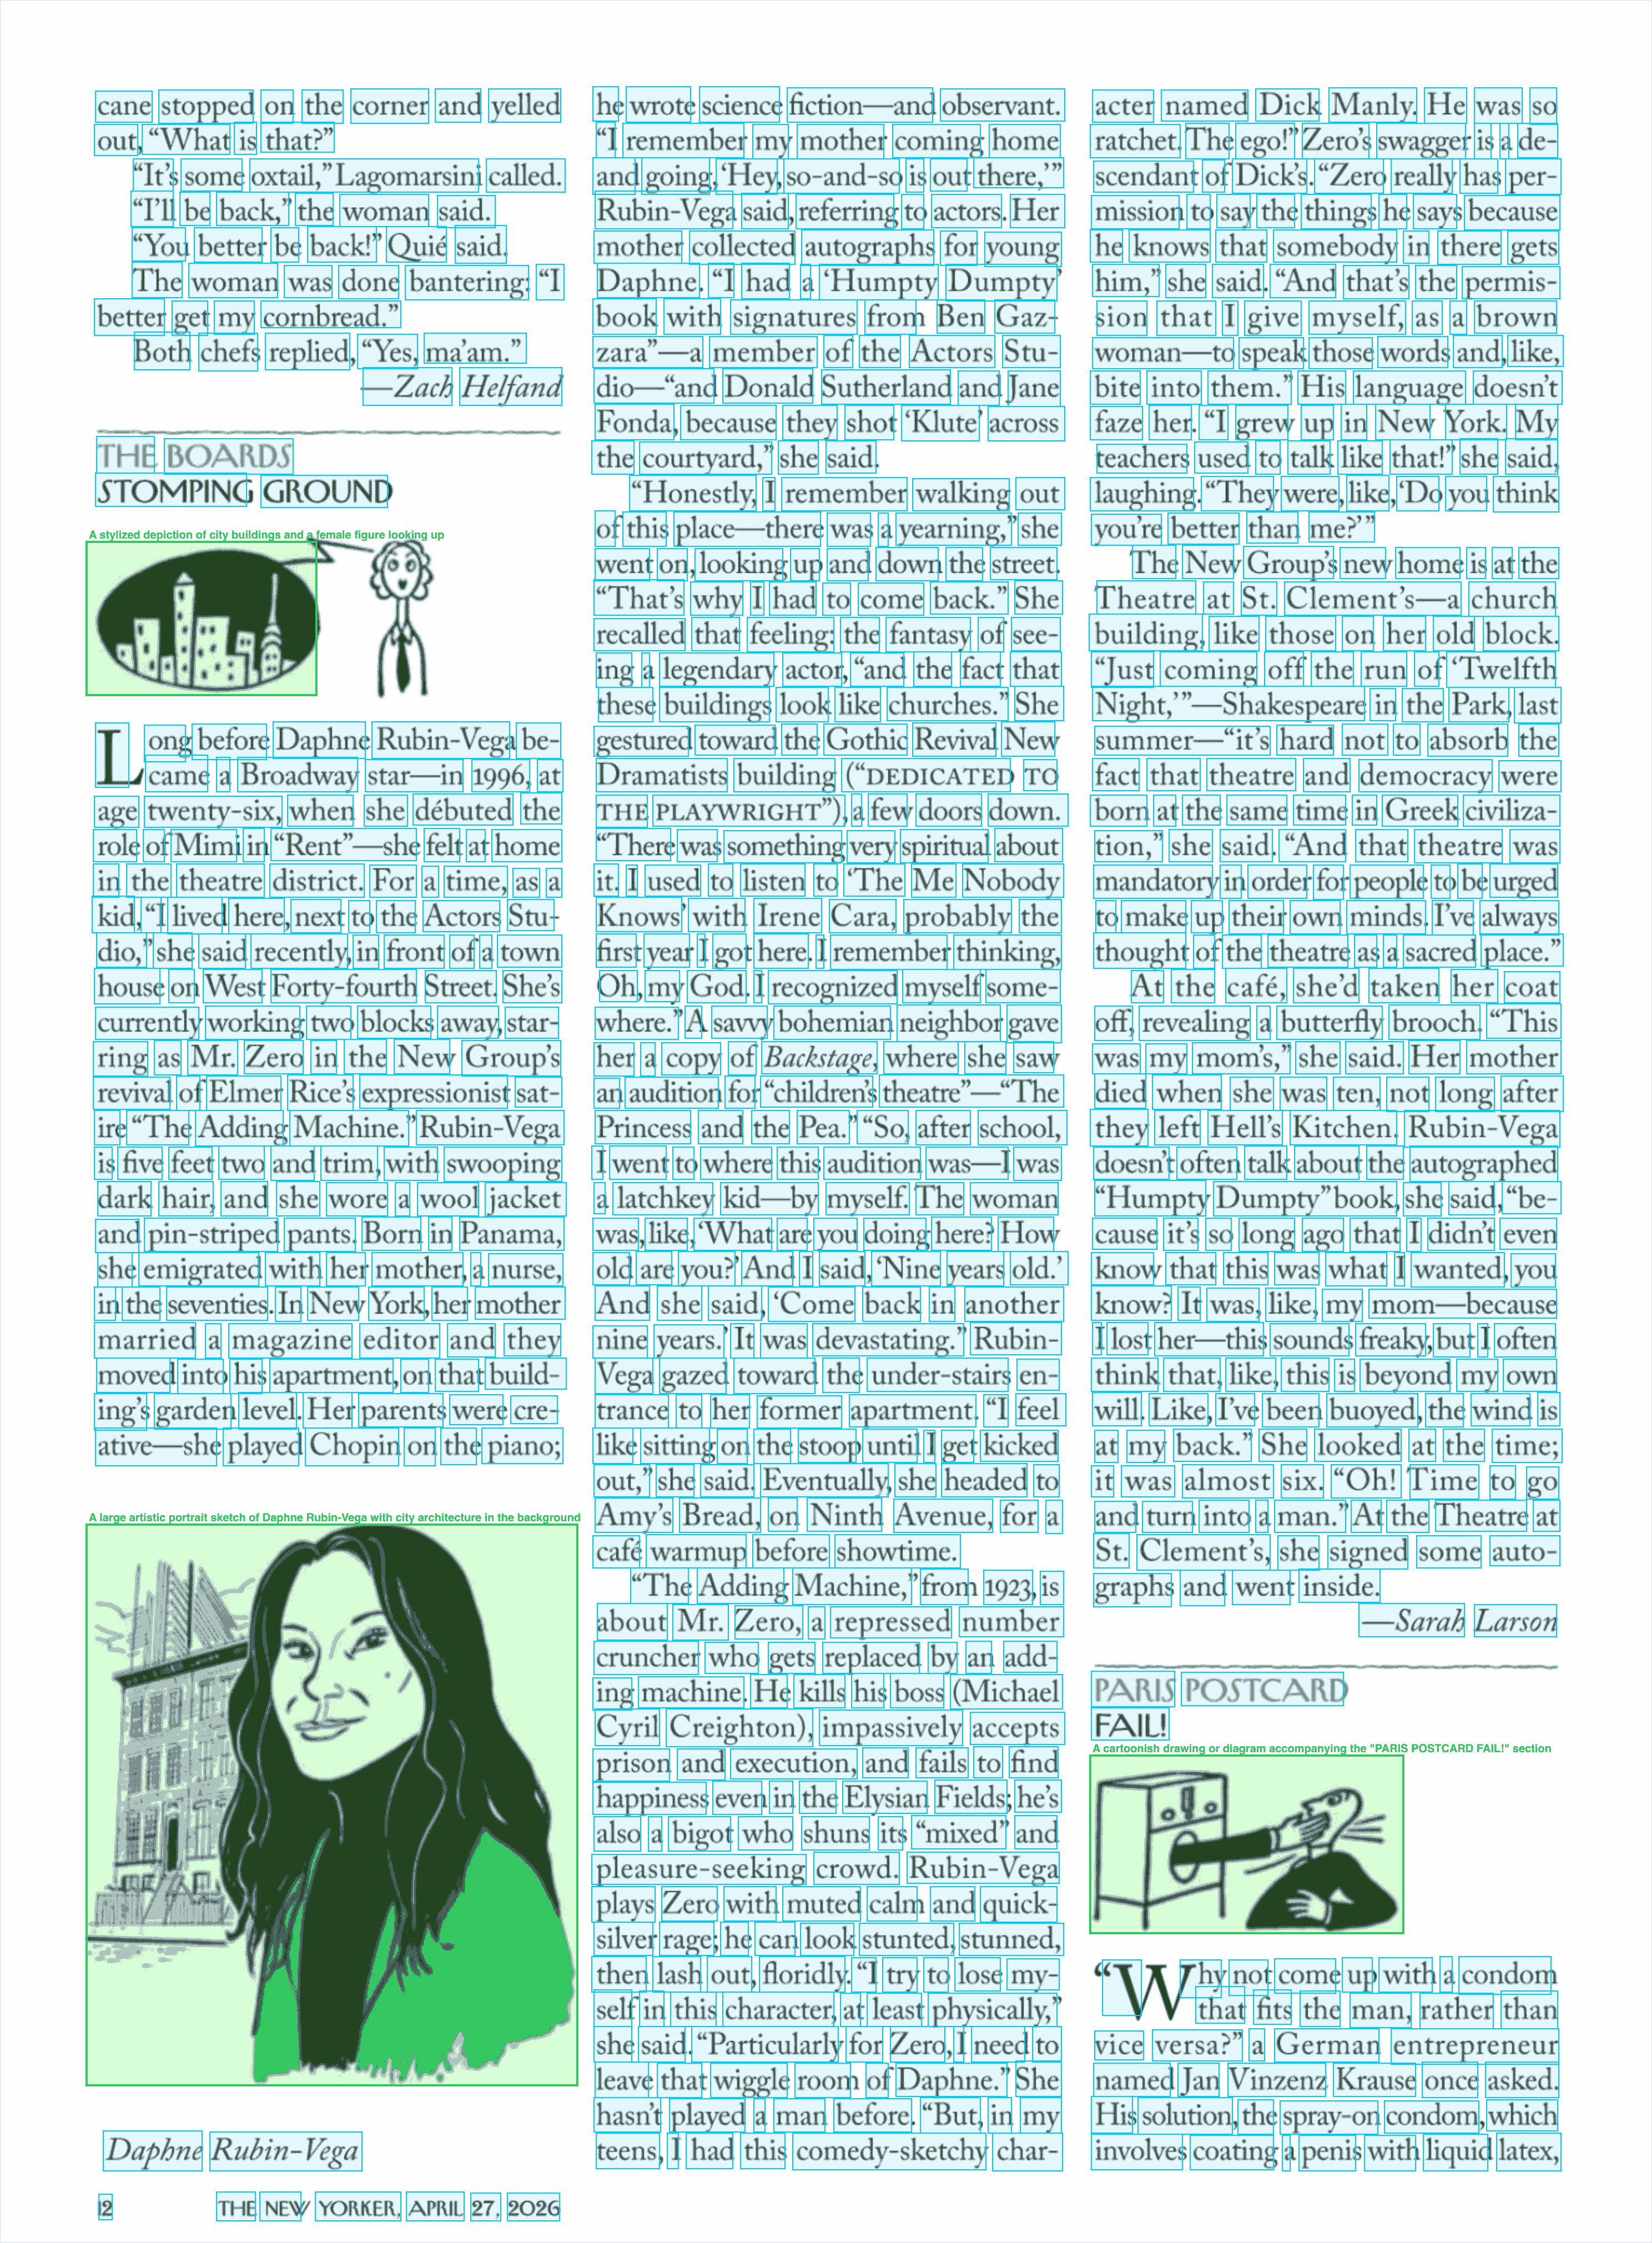
A magazine page with dense multi-column text and three illustrations. Interfaze runs OCR and object detection on the same image in one request, returning the full text plus pixel-coordinates for every figure, all under your schema.
 OpenAI SDK
Vercel AI SDK
LangChain SDK
import { z } from "zod";
import { zodResponseFormat } from "openai/helpers/zod";

const OCRObjectDetectionSchema = z.object({
	text: z.string().describe("all text in the image"),
	graphic_objects: z
		.array(
			z.object({
				description: z.string(),
				top_left_x: z.number(),
				top_left_y: z.number(),
				bottom_right_x: z.number(),
				bottom_right_y: z.number(),
			})
		)
		.describe("graphics objects found in the image"),
});

const response = await interfaze.chat.completions.create({
	model: "interfaze-beta",
	messages: [
		{
			role: "user",
			content: [
				{ type: "text", text: "Extract the text and graphics from the image based on the schema." },
				{
					type: "image_url",
					image_url: {
						url: "https://r2public.jigsawstack.com/interfaze/examples/dense_text_ocr_figures.png",
					},
				},
			],
		},
	],
	response_format: zodResponseFormat(OCRObjectDetectionSchema, "ocr_object_detection_schema"),
});

console.log(response.choices[0].message.content);

//@ts-expect-error precontext is not typed
const precontext = response.precontext;
console.log("OCR bounding boxes + confidence:", precontext[0]?.result);
JSON output
objectcarries the schema response: full page text plus agraphic\_objectsarray with a description and pixel coordinates for each illustration.precontextcarries the raw OCR (per-line and per-word bounding boxes, confidence scores) on the same response.
{
  "object": {
    "text": "cane stopped on the corner and yelled... acter named Dick Manly. He was so observant... STOMPING GROUND ... \"The Adding Machine,\" from 1923, is about Mr. Zero, a repressed number cruncher who gets replaced by an adding machine... 12 THE NEW YORKER, APRIL 27, 2026",
    "graphic_objects": [
      {
        "description": "A drawing located at the top left under the \"STOMPING GROUND\" heading, featuring a cityscape with a moon and a whimsical character.",
        "top_left_x": 84,
        "top_left_y": 484,
        "bottom_right_x": 394,
        "bottom_right_y": 630
      },
      {
        "description": "A detailed line drawing of Daphne Rubin-Vega in front of a building facade, matching the main profile story.",
        "top_left_x": 77,
        "top_left_y": 1367,
        "bottom_right_x": 517,
        "bottom_right_y": 1878
      },
      {
        "description": "A drawing in the bottom right corner depicting a person interacting with a device, situated above the spray-on condom text.",
        "top_left_x": 985,
        "top_left_y": 1581,
        "bottom_right_x": 1264,
        "bottom_right_y": 1737
      }
    ]
  },
  "precontext": [
    {
      "name": "ocr",
      "result": {
        "extracted_text": "cane stopped on the corner and yelled he wrote science fiction-and observant. acter named Dick Manly. He was so\nout, \"What is that?\" \"I remember my mother coming home...",
        "sections": [
          {
            "lines": [
              {
                "text": "cane stopped on the corner and yelled he wrote science fiction-and observant. acter named Dick Manly. He was so",
                "bounds": {
                  "top_left": { "x": 83, "y": 80 },
                  "top_right": { "x": 1406, "y": 78 },
                  "bottom_right": { "x": 1406, "y": 111 },
                  "bottom_left": { "x": 83, "y": 110 },
                  "width": 1323,
                  "height": 30
                },
                "average_confidence": 0.99
              }
              // ... hundreds more lines with per-word boxes and confidences
            ]
          }
        ]
      }
    }
  ]
}
OCR with partial model activation
With our hybrid architecture, you can activate parts of the model to run a specific task without using the full weights.
It’s faster and cheaper, with some tradeoffs, you get a fixed structured output that’s deterministic and consistent on every run, and you can only run one task per request.
 Using the
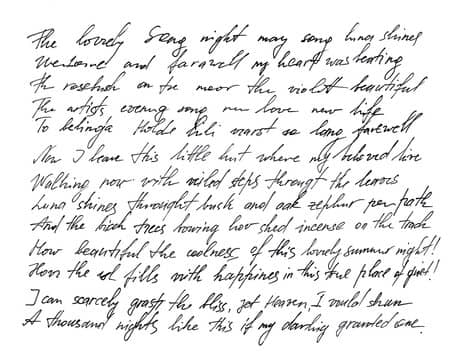
<task\>tag in the system prompt, you control which part of the model activates. Below, we run pure OCR on a handwritten poem.
OpenAI SDK
Vercel AI SDK
LangChain SDK
import { z } from "zod";
import { zodResponseFormat } from "openai/helpers/zod";

const response = await interfaze.chat.completions.create({
	model: "interfaze-beta",
	messages: [
		{ role: "system", content: "<task>ocr</task>" },
		{
			role: "user",
			content: [
				{ type: "text", text: "Extract all text from this image" },
				{
					type: "image_url",
					image_url: {
						url: "https://r2public.jigsawstack.com/interfaze/examples/handwriting.jpeg",
					},
				},
			],
		},
	],
	response_format: zodResponseFormat(z.any(), "empty_schema"),
});

console.log(response.choices[0].message.content);
JSON output
The response is the raw task result withnameandresult, ready to consume directly.
{
  "name": "ocr",
  "result": {
    "extracted_text": "The lovely Song night may song linen shined\nWelcome and faint wei my heart was beating\nthe reseach on the moon the violet beautifull\nThe artist's evening song our love new life\n...",
    "sections": [
      {
        "lines": [
          {
            "text": "The lovely Song night may song linen shined",
            "bounds": {
              "top_left": { "x": 27, "y": 22 },
              "top_right": { "x": 422, "y": 21 },
              "bottom_right": { "x": 423, "y": 47 },
              "bottom_left": { "x": 27, "y": 51 },
              "width": 395.5,
              "height": 27.5
            },
            "average_confidence": 0.78
          }
          // ... more lines with per-word boxes and confidences
        ]
      }
    ]
  }
}
Learn more about running tasks →
Accessing the internet
Interfaze comes built in with its own web index from scraping multiple SERP indexes and our own crawler.
OpenAI SDK
Vercel AI SDK
LangChain SDK
import { z } from "zod";
import { zodResponseFormat } from "openai/helpers/zod";

const GarryTanSchema = z.object({
	linkedin_url: z.string(),
	x_url: z.string(),
	first_name: z.string(),
	last_name: z.string(),
	location: z.string(),
	latest_education: z.string(),
	current_job: z.string(),
	followers: z.number(),
	experience: z.array(
		z.object({
			company: z.string(),
			title: z.string(),
			start_date: z.string(),
			end_date: z.string(),
		})
	),
});

const response = await interfaze.chat.completions.create({
	model: "interfaze-beta",
	messages: [{ role: "user", content: "Enrichment information of Garry Tan, Y Combinator" }],
	response_format: zodResponseFormat(GarryTanSchema, "garry_tan_enrichment_schema"),
});

console.log(response.choices[0].message.content);

//@ts-expect-error precontext is not typed
const precontext = response.precontext;
console.log("Web search results:", precontext[0]?.result);
JSON output
objectreturns the enriched profile typed exactly to the schema, whileprecontextincludes the raw web search results Interfaze pulled in to ground the answer.
{
  "object": {
    "linkedin_url": "https://linkedin.com/in/garrytan",
    "x_url": "https://x.com/garrytan",
    "first_name": "Garry",
    "last_name": "Tan",
    "location": "San Francisco, California, United States",
    "latest_education": "Stanford University (1999-2003), BS in Computer Systems Engineering",
    "current_job": "President & CEO at Y Combinator, Founder at Garry's List, Board Partner & Advisor at Initialized Capital",
    "followers": 319863,
    "experience": [
      {
        "company": "Garry's List",
        "title": "Founder",
        "start_date": "Jan 2026",
        "end_date": "Present"
      },
      {
        "company": "Y Combinator",
        "title": "President & CEO",
        "start_date": "Jan 2023",
        "end_date": "Present"
      },
      {
        "company": "Initialized Capital",
        "title": "Founder & Managing Partner",
        "start_date": "Jan 2012",
        "end_date": "Dec 2022"
      },
      {
        "company": "Posterous.com",
        "title": "Cofounder",
        "start_date": "Jan 2008",
        "end_date": "Jan 2011"
      },
      {
        "company": "Palantir Technologies",
        "title": "Lead Engineer, Designer",
        "start_date": "Sep 2005",
        "end_date": "Oct 2007"
      }
      // ... more roles
    ]
  },
  "precontext": [
    {
      "name": "search",
      "result": [
        {
          "title": "Garry Tan - President & CEO, Y Combinator - LinkedIn",
          "description": "President & CEO of Y Combinator. Y Combinator funds hundreds of companies per year...",
          "url": "https://www.linkedin.com/in/garrytan"
        }
        // ... more search results
      ]
    }
  ]
}
Long audio transcription
The clip below is1 hour 35 minutesof a podcast episode. Interfaze transcribes it in**~50 seconds**with per-chunk timestamps.
OpenAI SDK
Vercel AI SDK
LangChain SDK
import { z } from "zod";
import { zodResponseFormat } from "openai/helpers/zod";

const response = await interfaze.chat.completions.create({
	model: "interfaze-beta",
	messages: [
		{ role: "system", content: "<task>speech_to_text</task>" },
		{
			role: "user",
			content: [
				{ type: "text", text: "Transcribe the audio file https://r2public.jigsawstack.com/interfaze/examples/stt_long_audio_sample_3.mp3" },
			],
		},
	],
	response_format: zodResponseFormat(z.any(), "empty_schema"),
});

console.log(response.choices[0].message.content);
JSON output
The response is the raw task result as shown below.
{
  "name": "speech_to_text",
  "result": {
    "text": "We don't teach leaders how to have uncomfortable conversations. We don't teach students how to have uncomfortable conversations. You tell me which is going to be more valuable for the rest of your life. How to have a difficult conversation or trigonometry?...",
    "chunks": [
      { "timestamp": [0, 3.39], "text": "We don't teach leaders how to have uncomfortable conversations. We don't teach students how" },
      { "timestamp": [3.39, 6.79], "text": "to have uncomfortable conversations. You tell me which is going to be more valuable" },
      { "timestamp": [6.79, 10.18], "text": "for the rest of your life. How to have a difficult conversation or trigonometry?" }
      // ... thousands more timestamped chunks across the full 1h 35m
    ]
  }
}
Conclusion
We’re excited to keep experimenting, growing and discovering new research that makes deterministic AI more efficient and accessible to all developers!
Get started for free and try it on your own documents, images and prompts. We’re excited to see what you build!
Get started
- Get an API key— sign in to the Interfaze dashboard.
- Read the docs— start with the quickstart and SDK setup.
- View pricing— usage-based, same range as the flash/mini models.
Dive deeper
- Full leaderboard— every benchmark, every model.
- Benchmark code- see how we ran the benchmarks.
- Structured Output Benchmark- the SOB leaderboard.
Stay in touch
- Follow us onXandLinkedInfor research updates.
- Join the conversation onDiscord.
- Questions or feedback? Email[email protected].
相似文章
Interfaze:专为规模化场景下高准确率而构建的新型模型架构
Interfaze 推出了一种混合 AI 模型架构,结合 CNN/DNN 的专项优势与 Transformer 能力,在 OCR 和翻译等确定性任务上实现卓越精度,同时在规模化应用中保持成本效率。
@aaron_epstein: 新发布的模型在OCR、视觉和STT任务上击败了sonnet 4.6、gemini 3 flash和gpt 5.4 mini @interfaze_ai
来自interfaze_ai的新AI模型声称在OCR、视觉和语音转文字任务上超越领先模型(sonnet 4.6、gemini 3 flash、gpt 5.4 mini)。
@MaxForAI: http://Z.ai和清华这篇ZCube,做Infra的家人们值得看下。 很多人聊AI infra,第一反应还是GPU、显存、量化、推理框架。 但到长上下文和Prefill-Decode分离之后,网络已经不再是机房里的「配角」了。 每一…
ZCube是一种新的网络架构,通过打平拓扑并混合单/多轨接入,优化了长上下文和PD分离场景下的KV Cache传输,在GLM-5.1生产集群中实现了交换机/光模块成本降低33%、GPU推理吞吐提升15%、TTFT P99下降40.6%。
@berryxia: Apple 一直其实在赌端侧模型的应用! 统一架构内存就是端侧模型的天然温床! 统一内存也就是,内存即显存。 也看到越来越多的优秀端侧模型出现。 OpenBMB 把 MiniCPM-V 4.6 这个 1.3B 的多模态模型放出来了,我看完…
OpenBMB 发布了 MiniCPM-V 4.6,一个 1.3B 参数的多模态模型,通过高分辨率视觉处理和高效压缩技术,在消费级硬件和手机上实现快速推理,性能超过同类大模型,且全面开源支持多种推理和量化框架。
@berryxia: 卧槽,这一波直接把DeepSeek的“墙角挖到了啊”! 昨晚看到HuggingFace刷到这个有意思的OCR开源模型和原来背后有趣的故事。 这个OCR模型直接与传统的OCR模型完全不同! 光着速度和精准度真的就无敌了~~ 先说说背景,熟悉…
百度开源了Unlimited OCR模型,采用R-SWA注意力机制,可一次性处理数百页文档,无需分页,KV Cache恒定。该模型创新性地借鉴了人类抄书时的注意力模式,并与DeepSeek OCR有技术渊源,引发了对人才流动的关注。