openbmb/MiniCPM-V-4.7-35B-A3B
Summary
OpenBMB发布了MiniCPM-V 4.7的35B-A3B版本,这是MiniCPM-V系列的首个MoE模型,借助Lookahead Expert Scheduling等技术成为首个能在设备端流畅运行且不损失性能的开源MoE多模态模型,同时在性能与效率上达到新的帕累托前沿。
View Cached Full Text
Cached at: 10/12/26, 07:03 PM
openbmb/MiniCPM-V-4.7-35B-A3B · Hugging Face
Source: https://huggingface.co/openbmb/MiniCPM-V-4.7-35B-A3B On-device results·Evaluation·Examples·Usage·Model weights
MiniCPM-V 4.7is the latest model in the MiniCPM-V series, available in a35B-A3Bvariant, with35B-A3B being the first MoE model in the MiniCPM-V series. It builds on the family’s single-image, multi-image, and video understanding capabilities, combining stronger foundation capabilities with efficient visual encoding and on-device inference. Notable features of MiniCPM-V 4.7 include:
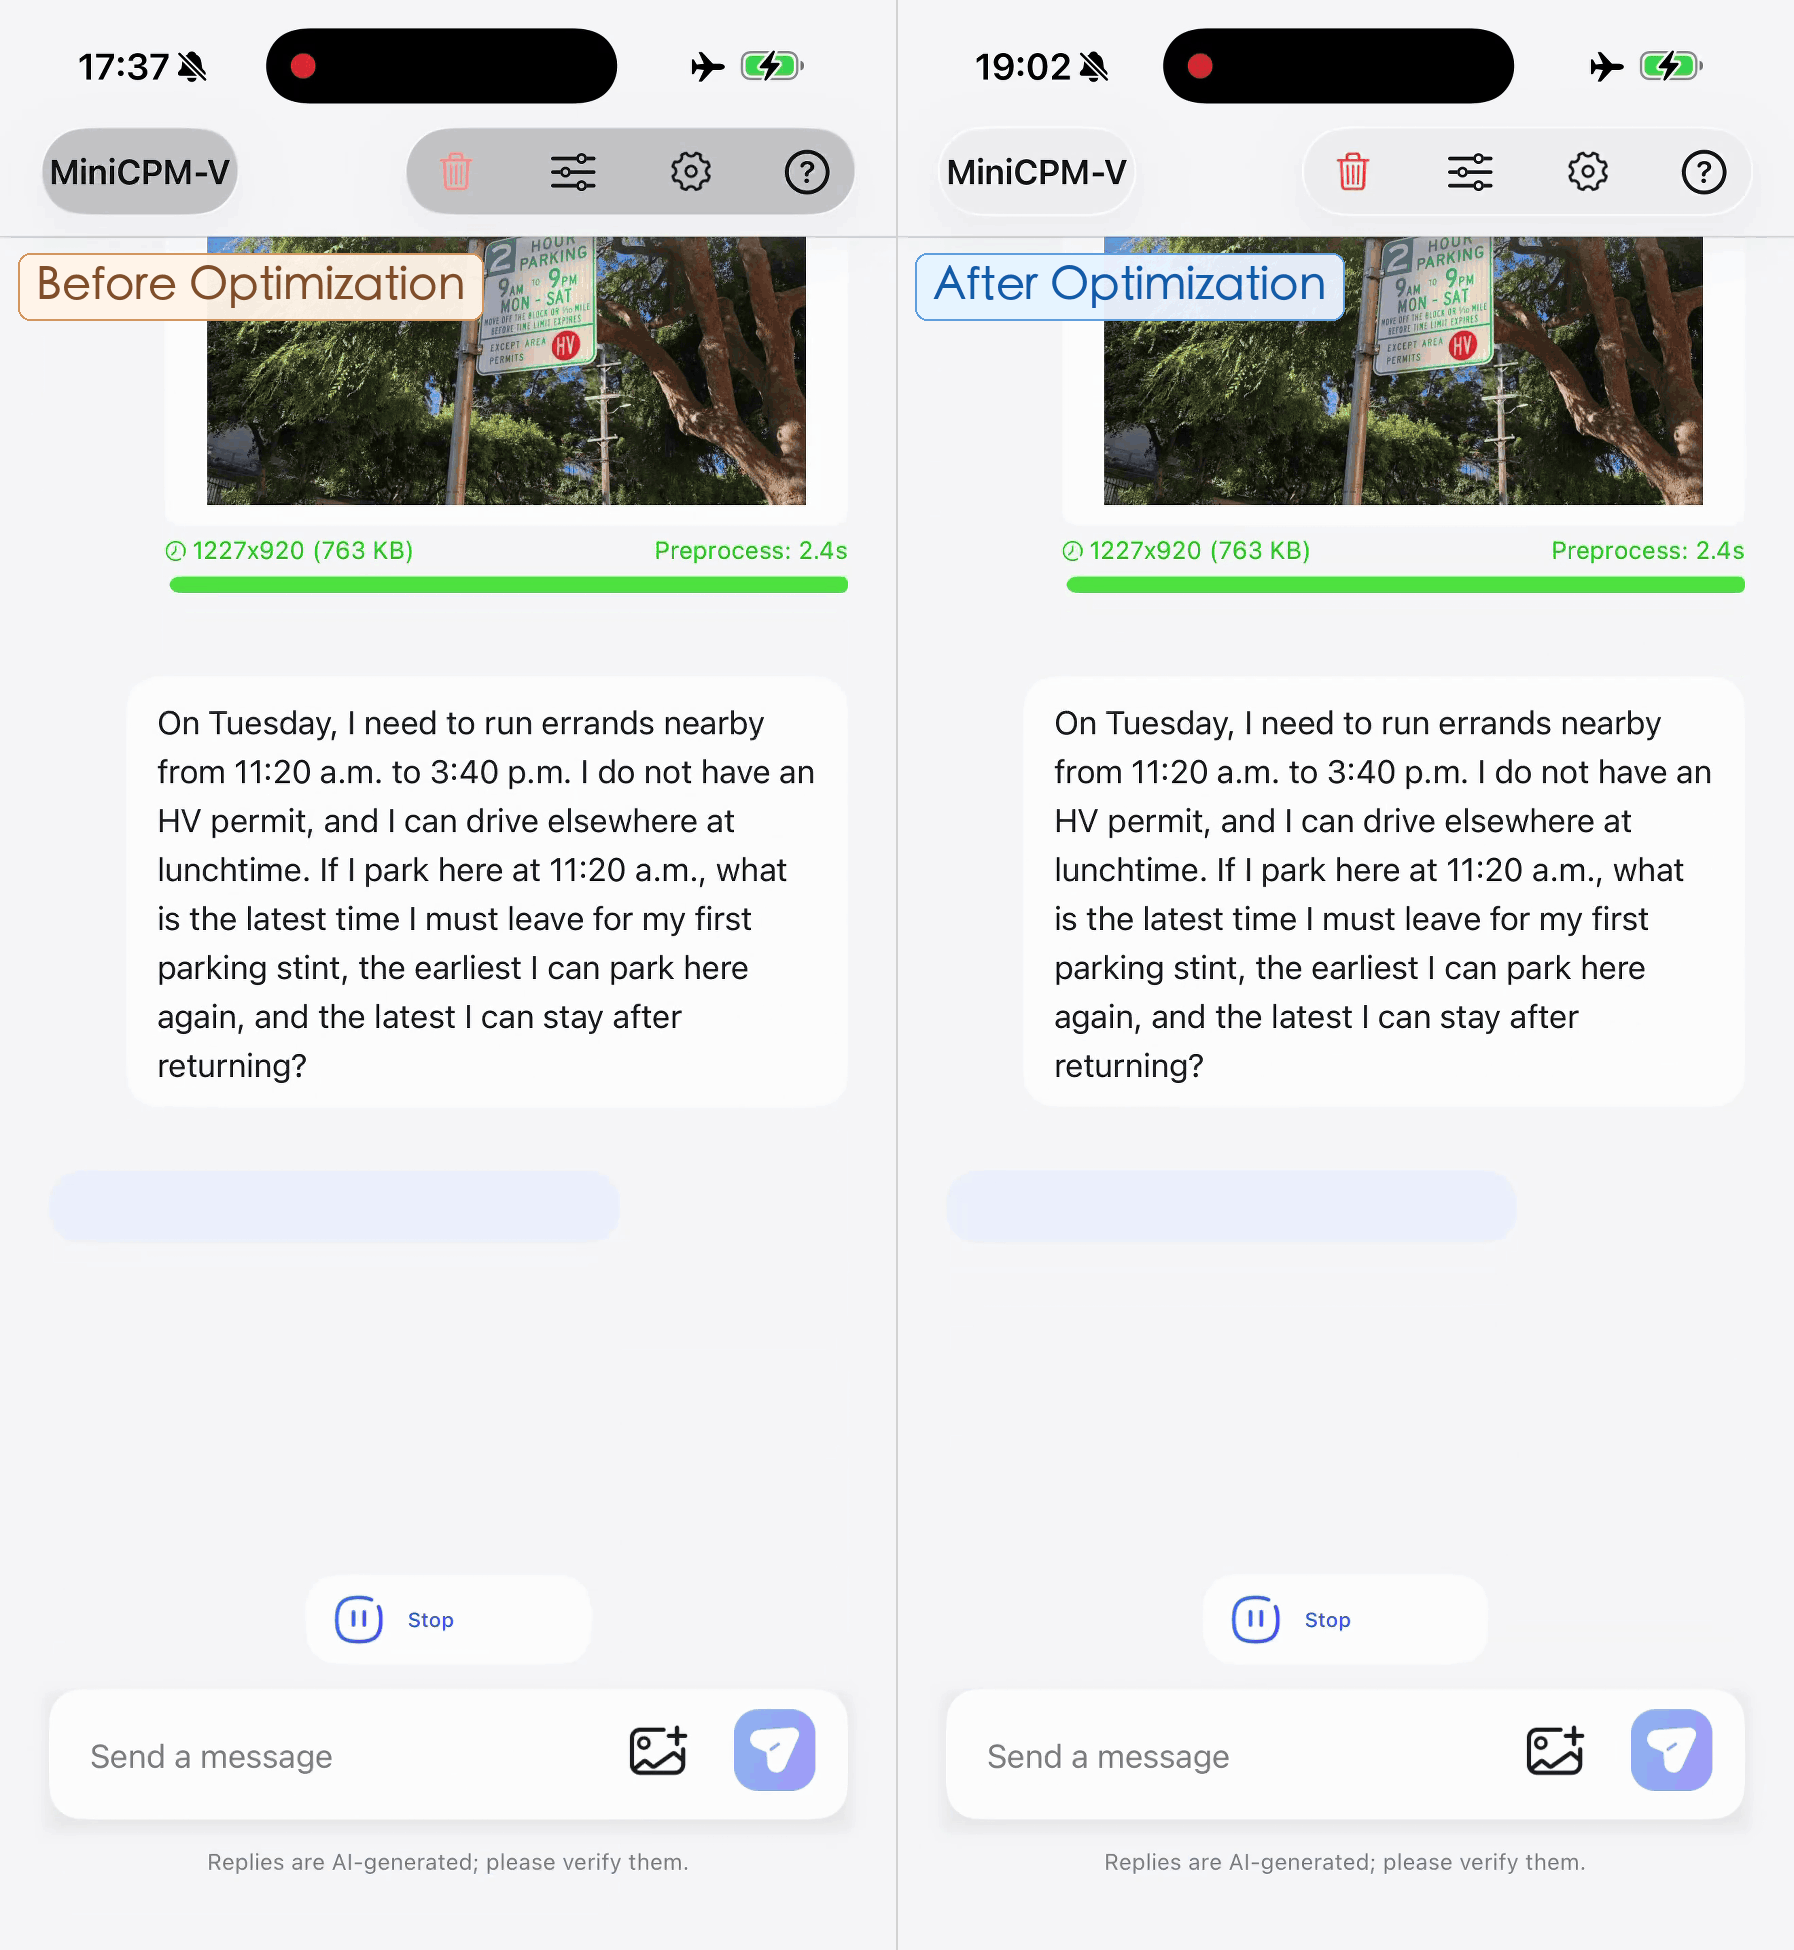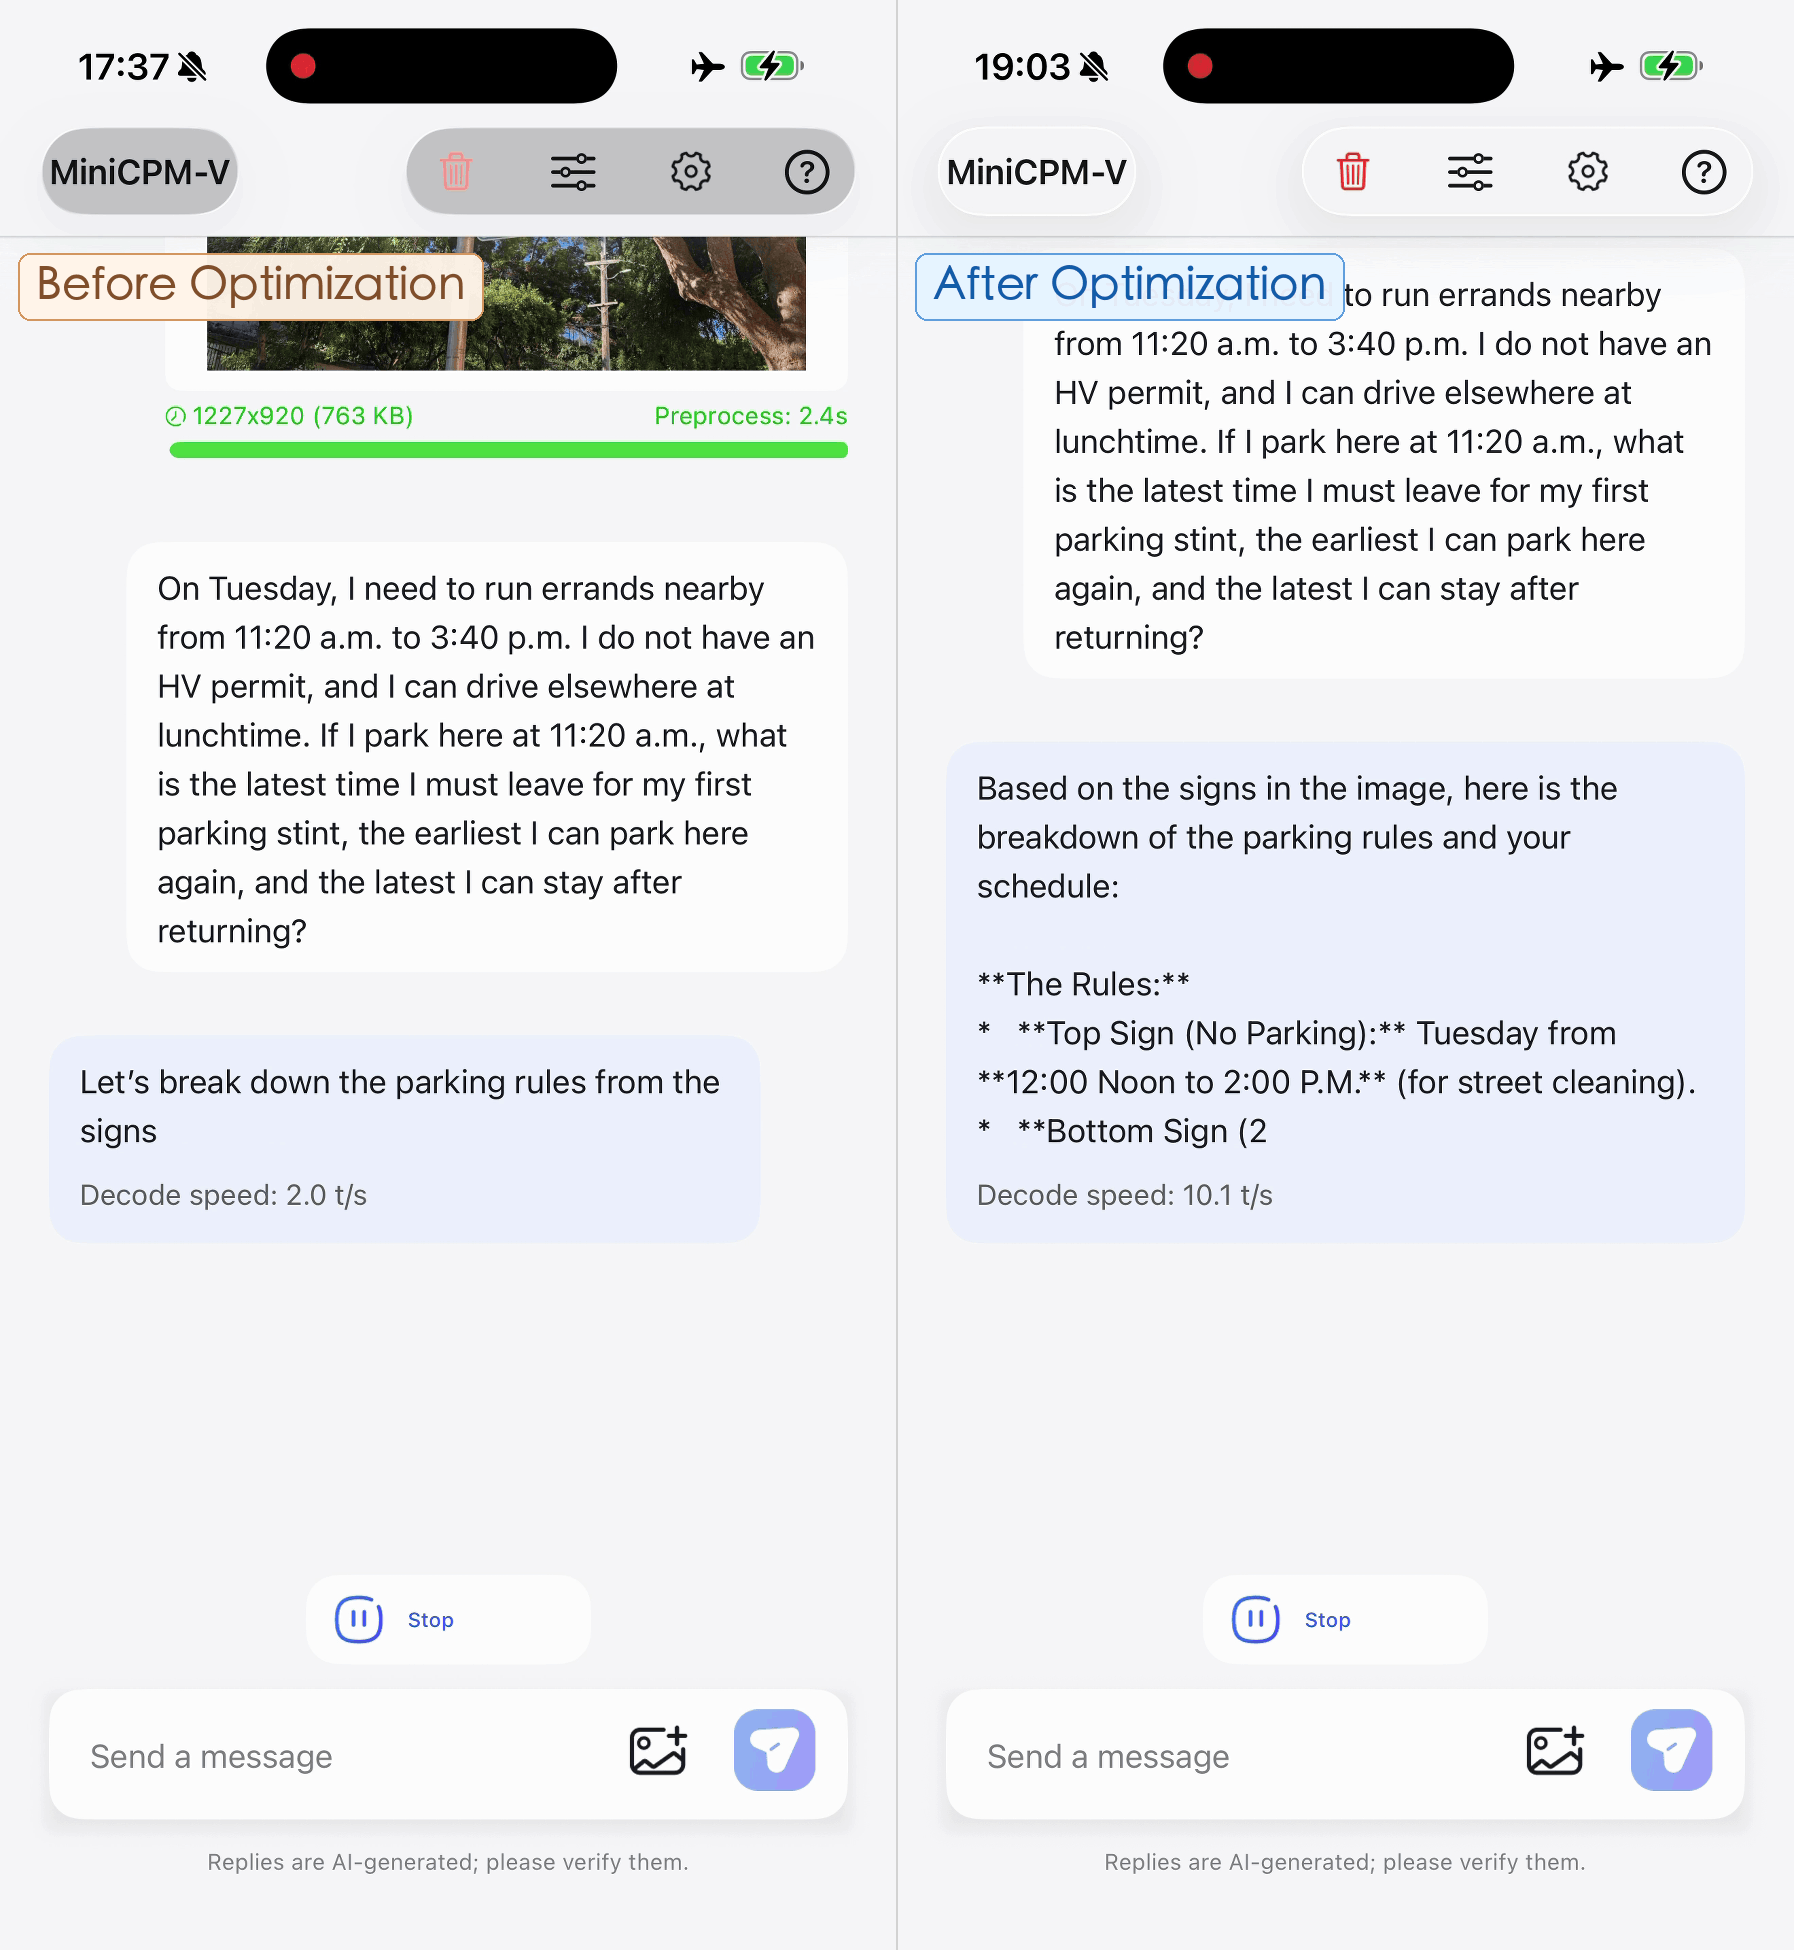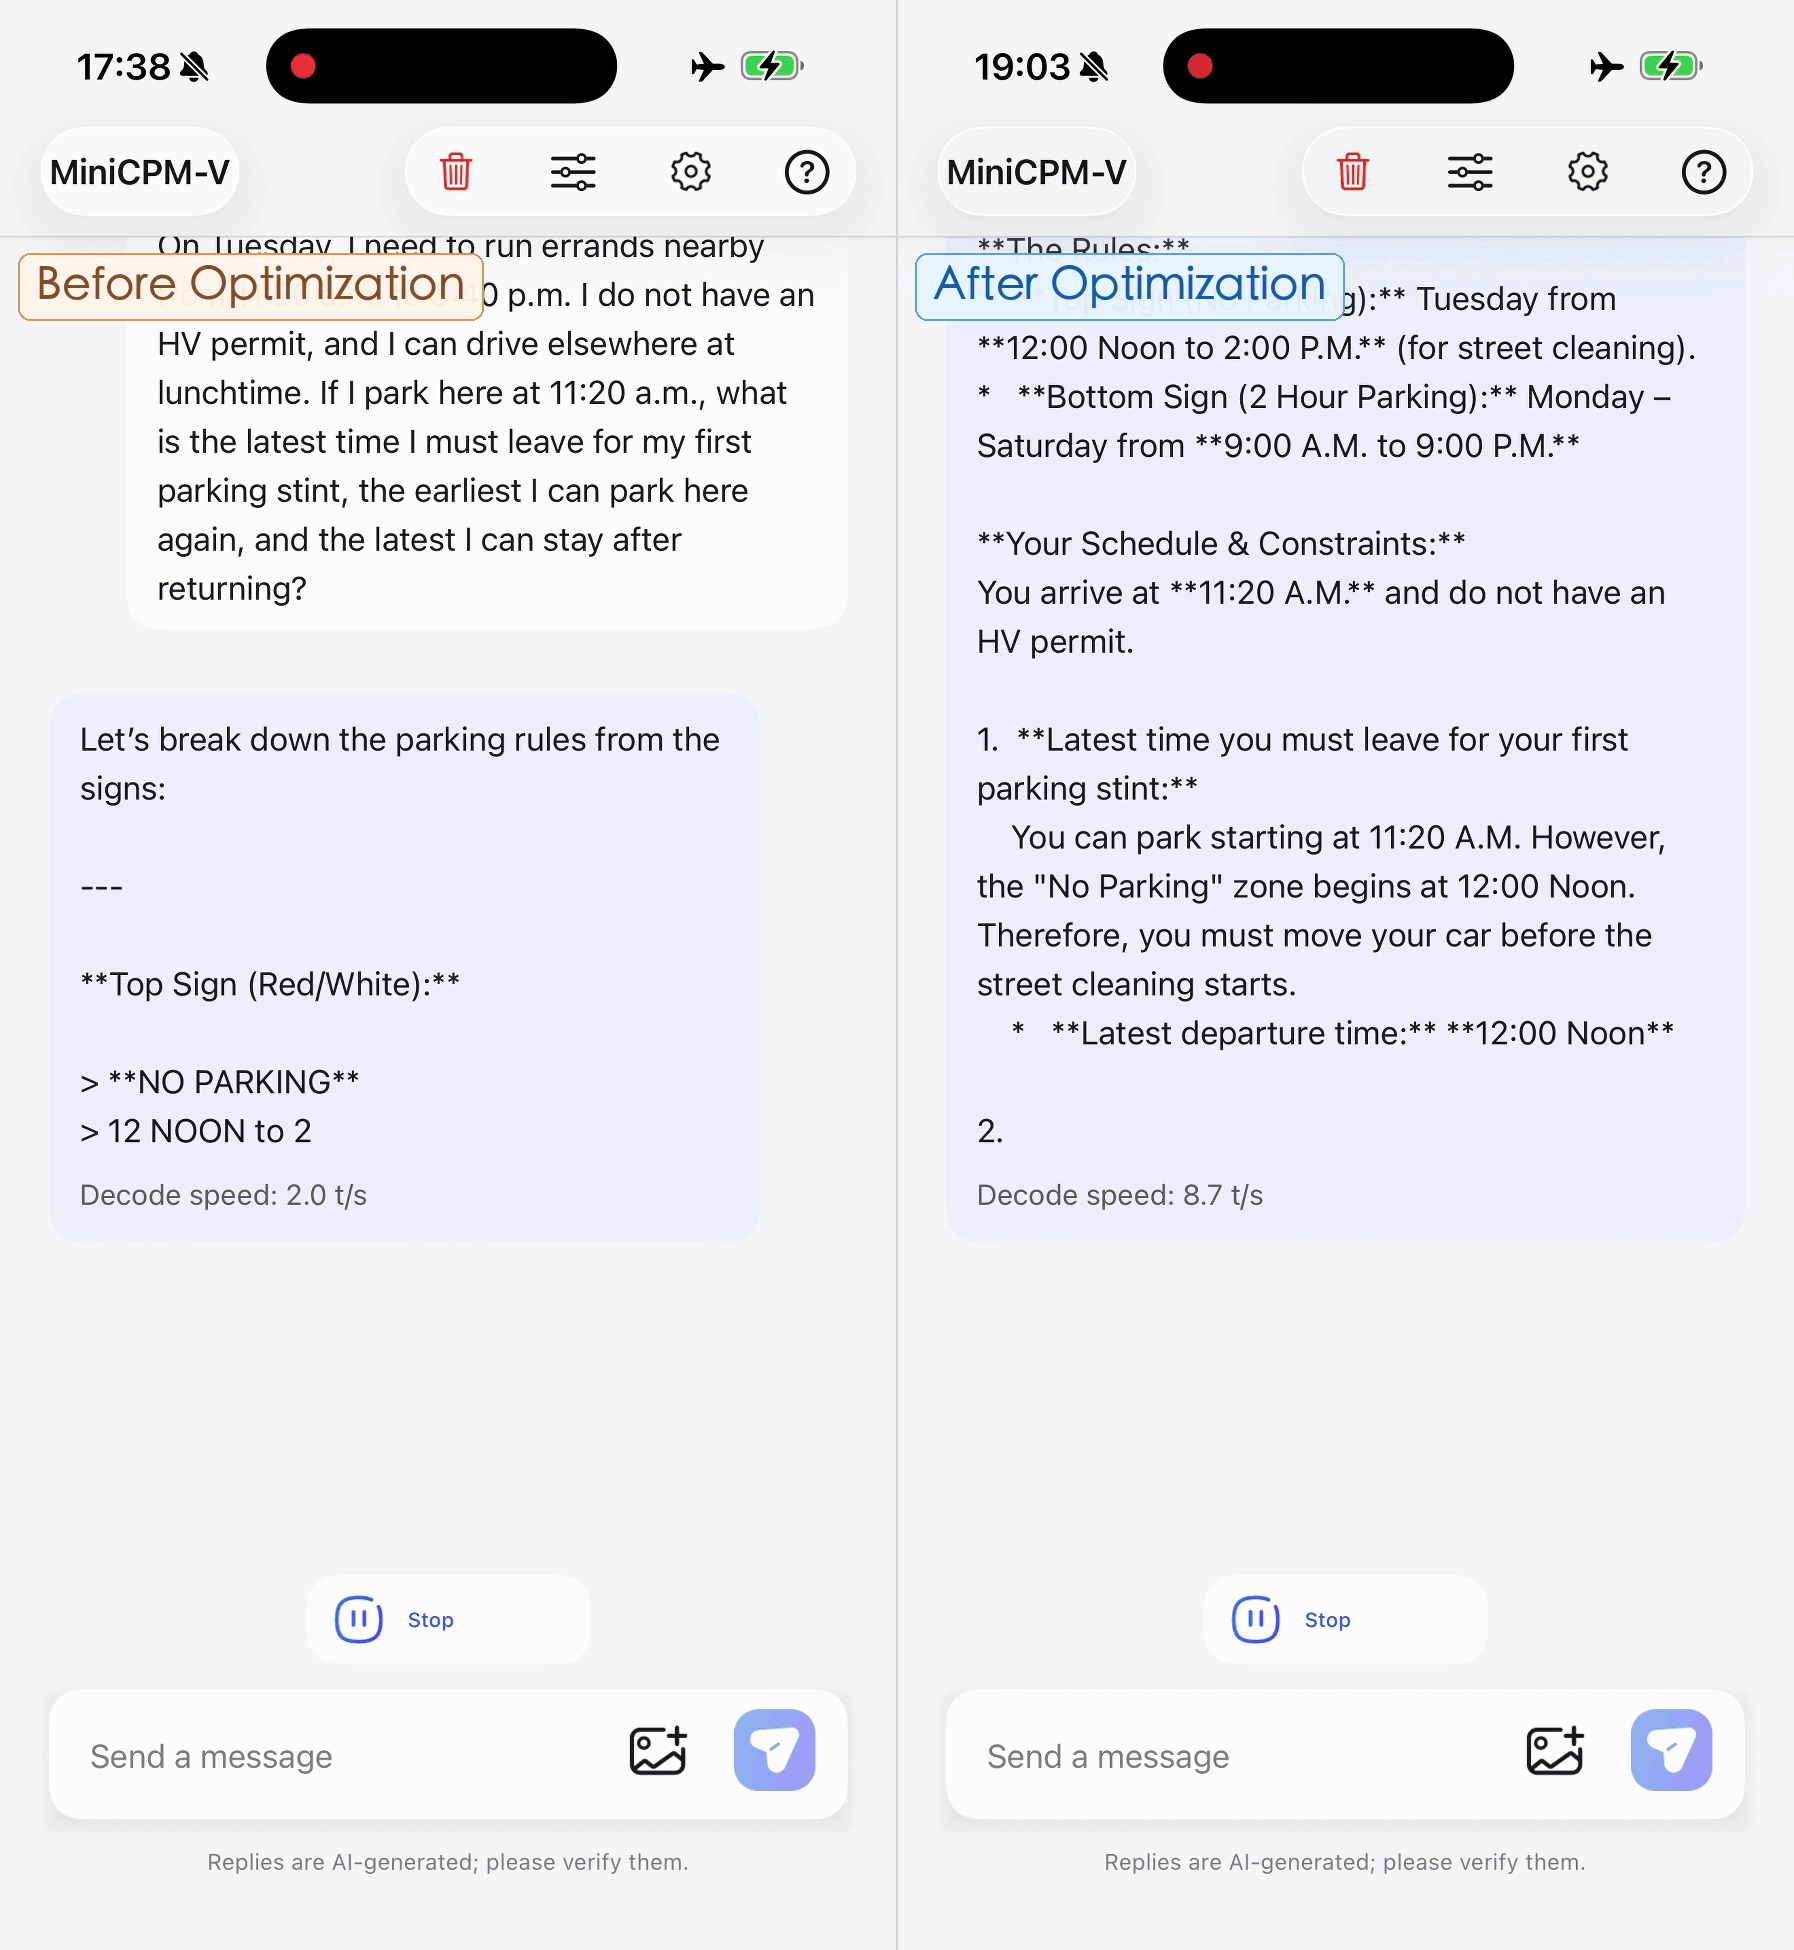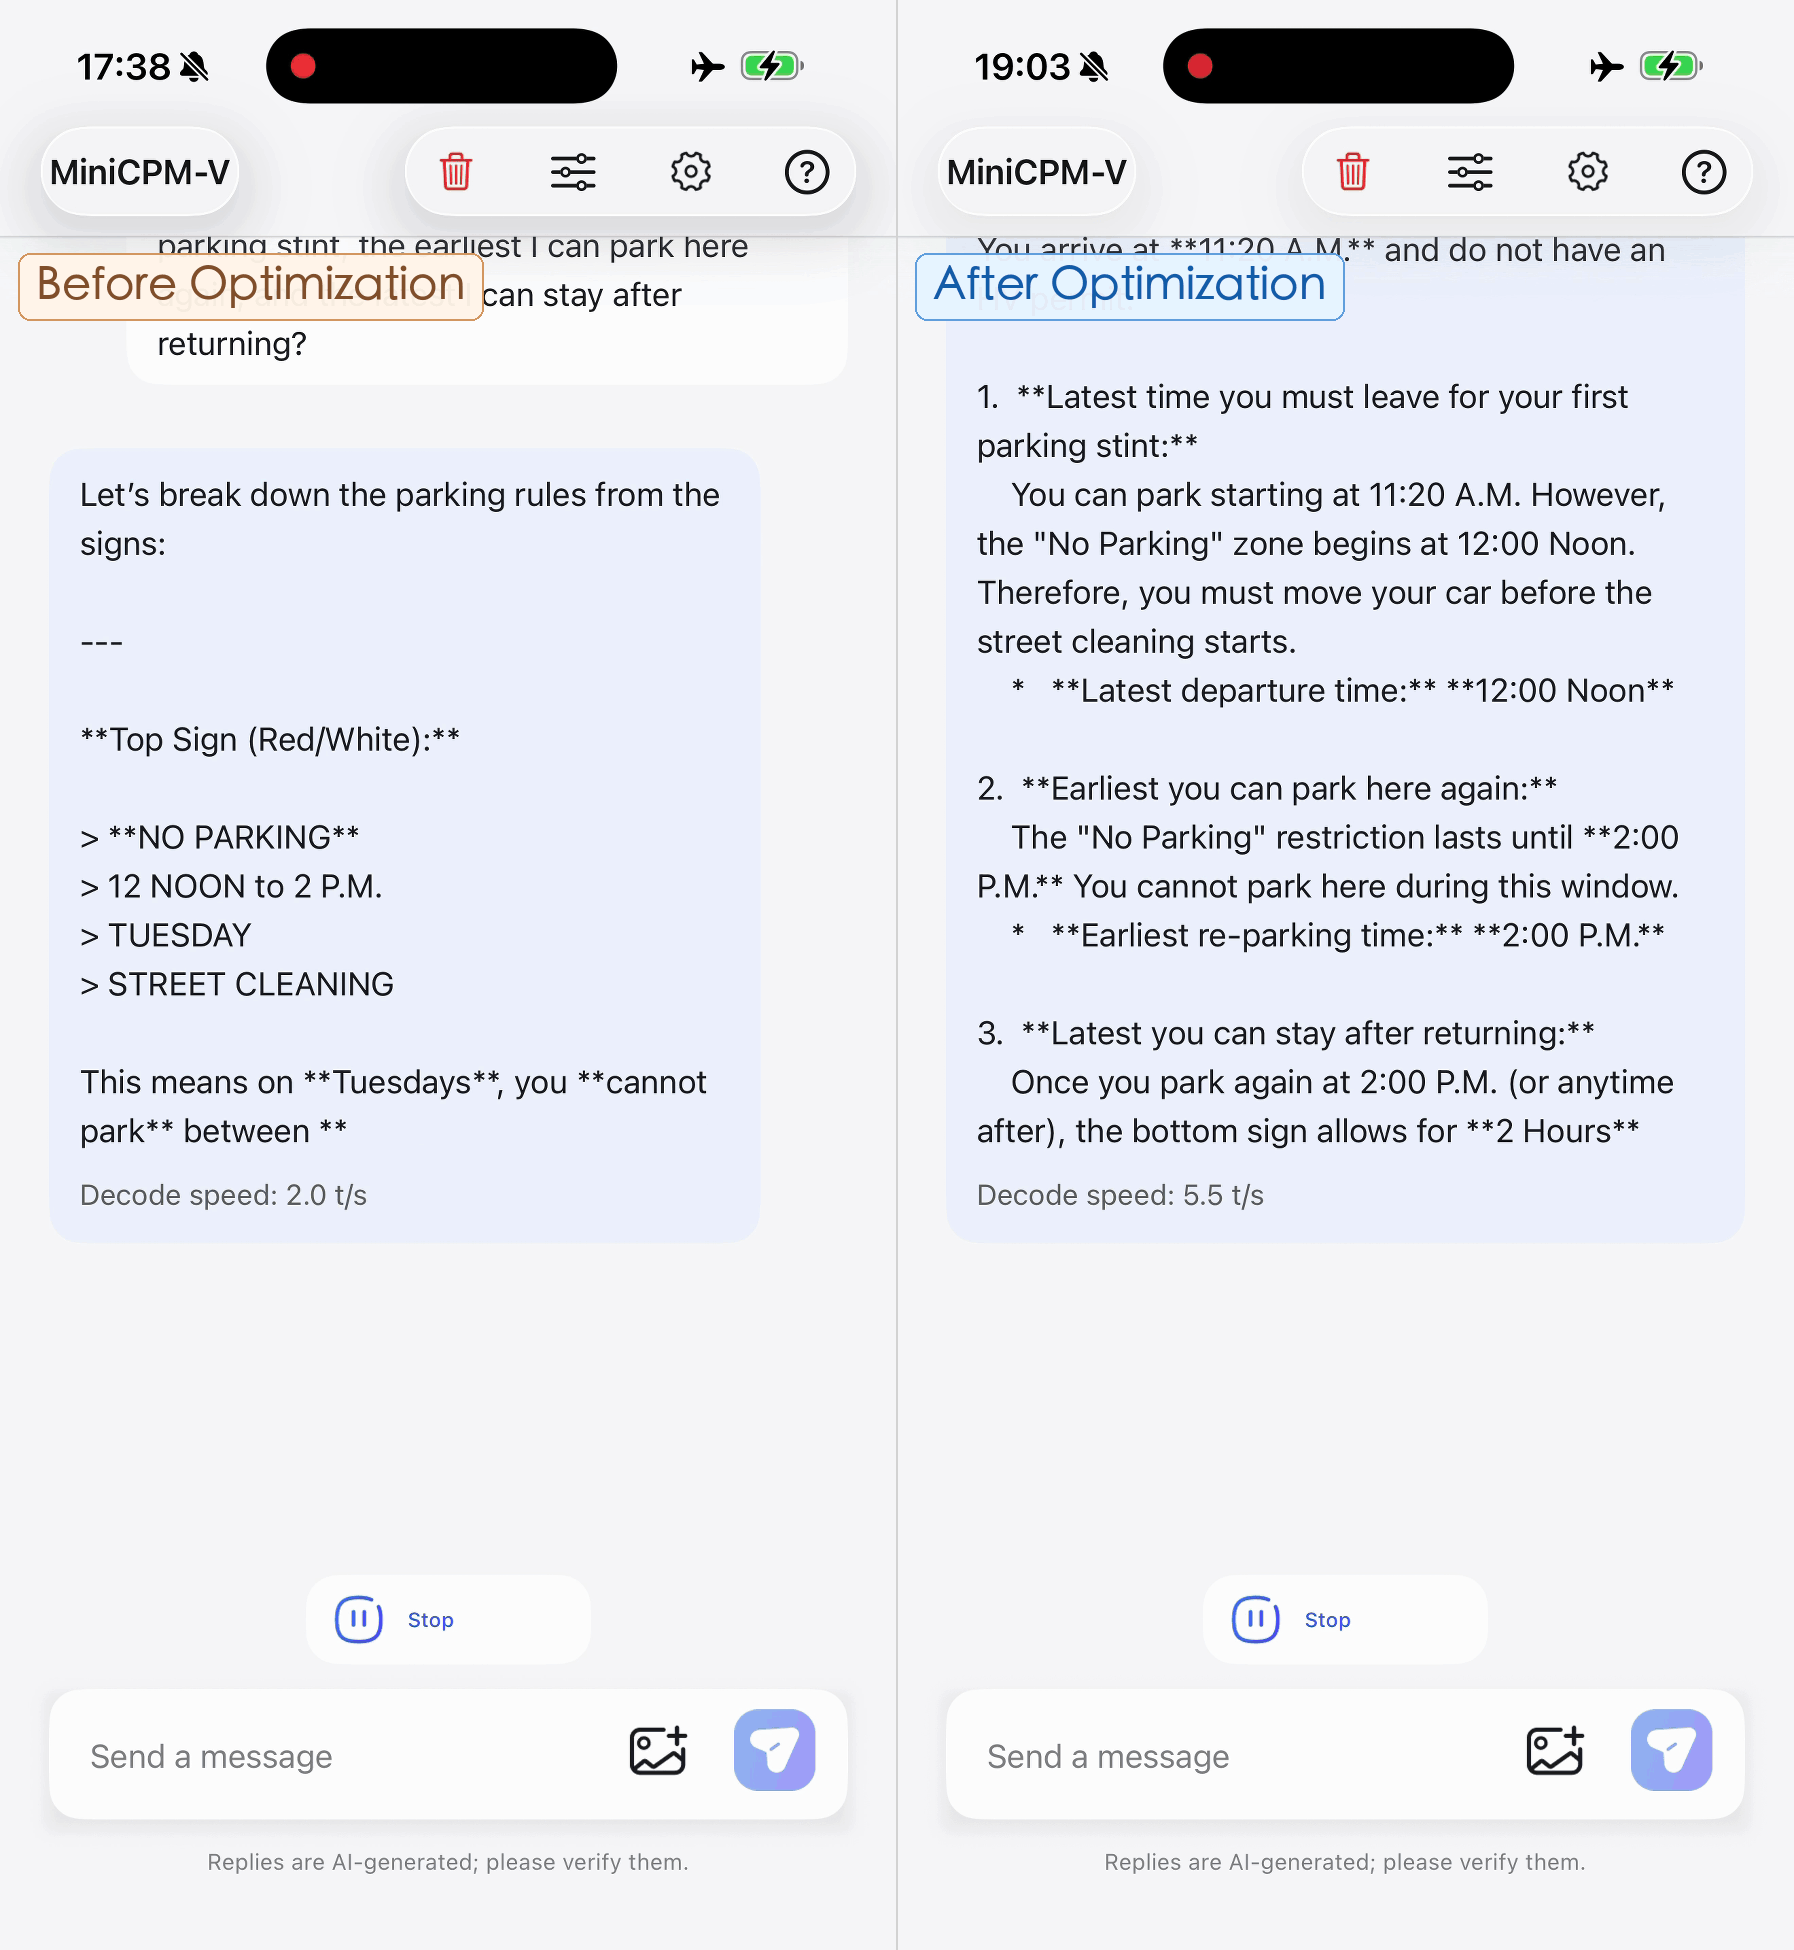
- 📱The First Open-Source MoE Model with Lossless, Smooth On-Device Inference.With ourLookahead Expert Scheduling (LES)technique introduced alongside MiniCPM-V 4.7, combined with fine-grained layer-wise quantization and DSpark speculative sampling integration, MiniCPM-V 4.7 35B-A3B becomes thefirst open-source MoE model to run smoothly on-device without compromising performance, achieving a decoding speed of13+ tokens/s on iPhone 17 Pro Max.
- 🔥A New Pareto Frontier in Performance and Efficiency.As model capabilities continue to advance, inference efficiency has become an important measure of a model’s value. On resource-constrained devices, delivering the strongest possible capabilities within a limited resource budget calls for higher capability density. The35B-A3Bvariant of MiniCPM-V 4.7 advances the performance–efficiency Pareto frontier for MLLMs. In Instruct mode, 35B-A3Bachieves a higher overall score in less inference time than Qwen3.6 35B-A3B.
- 🚀Efficient Architecture.Based on the intra-ViT early compression technique fromLLaVA-UHD v4, MiniCPM-V 4.7 compresses visual tokens early within the vision encoder, reducing computation in subsequent encoder layers. It also supportsmixed 4x/16x visual token compression, allowing developers to balance visual detail and inference cost across tasks.
- 💻Broad Platform and Chip Support.MiniCPM-V 4.7 supportsiOS, Android, and HarmonyOS, together with open-source on-device deployment support. It also providesday-0 support for chip platforms from Rockchip, Houmo, Intel, AMD, and Arm, extending deployment options across mobile and local computing devices.
- 🛠️Developer Friendly.MiniCPM-V 4.7 supportsinference frameworksincluding SGLang, vLLM, llama.cpp, and Ollama, along withfine-tuning frameworksincluding SWIFT and LLaMA-Factory. It provides GGUF, BNB, AWQ, and GPTQ quantized variants and addsFP8 quantization support. We also releaseSelf-Replay Fine-Tuning, a fine-tuning approach that helps developers extend model capabilities at low cost while reducing forgetting of existing capabilities, making further customization easier.
https://huggingface.co/openbmb/MiniCPM-V-4.7-35B-A3B#get-startedGet started
Model weights·Inference·Fine-tuning·Live demo·Local deployment·API·Cookbook
https://huggingface.co/openbmb/MiniCPM-V-4.7-35B-A3B#on-device-capability-and-efficiencyOn-Device Capability and Efficiency
https://huggingface.co/openbmb/MiniCPM-V-4.7-35B-A3B#smooth-on-device-moe-inference-without-compromising-performanceSmooth On-Device MoE Inference without compromising performance
An MoE model can have far more total parameters than it activates for a single token, but its on-device storage requirements are not limited to those active parameters. Different tokens can select different experts at different layers, while device memory often cannot hold all expert weights. Without a latency constraint, weights can remain on SSD or other storage, be loaded as needed, and be released after computation. This makes large-model inference possible, but repeated loading stalls can make decoding too slow for real-time interaction.
Another approach is to restrict the pool of available experts. For example, fixing an expert subset for an entire prompt can reduce loading frequency, but limits subsequent token-level routing to that subset, potentially excluding experts the model would otherwise select and reducing its capabilities. The central goal is thereforesmooth inference without compromising performance: preserving model capability while delivering sufficient throughput under limited memory and bandwidth.
MiniCPM-V 4.7 35B-A3B addresses this challenge through three complementary techniques:
- Lookahead Expert Scheduling (LES)uses cross-layer routing prediction to preload experts likely to be needed by the next layer. Among the experts selected by the actual router, it prioritizes those successfully prefetched and overlaps their computation with loading the remaining required experts. Predictions guide only prefetching and scheduling; computation still follows the model’s original token-level routing, and required experts missed by the prediction are loaded and evaluated as usual.
- Fine-grained layer-wise quantizationreduces the storage footprint and memory traffic of expert weights while preserving model capability, making expert loading better suited to on-device memory and bandwidth constraints.
- DSpark speculative sampling integrationincorporates speculative sampling into the on-device inference process, working with expert scheduling and quantization to improve decoding efficiency.
Together, these techniques make MiniCPM-V 4.7 35B-A3B the first open-source MoE model to run smoothly on-device without compromising performance, achieving13+ tokens/s on iPhone 17 Pro Max.
On-Device MoE Inference: Before and After Optimization
https://huggingface.co/openbmb/MiniCPM-V-4.7-35B-A3B#evaluationEvaluation
Significantly Advancing the Performance–Efficiency Pareto Frontier
The 35B-A3B variant of MiniCPM-V 4.7 advances the performance–efficiency Pareto frontier. In Instruct mode, 35B-A3B reaches a higher overall score in less inference time than Qwen3.6 35B-A3B.
Overall Performance (35B-A3B, Instruct)
Vision-Language
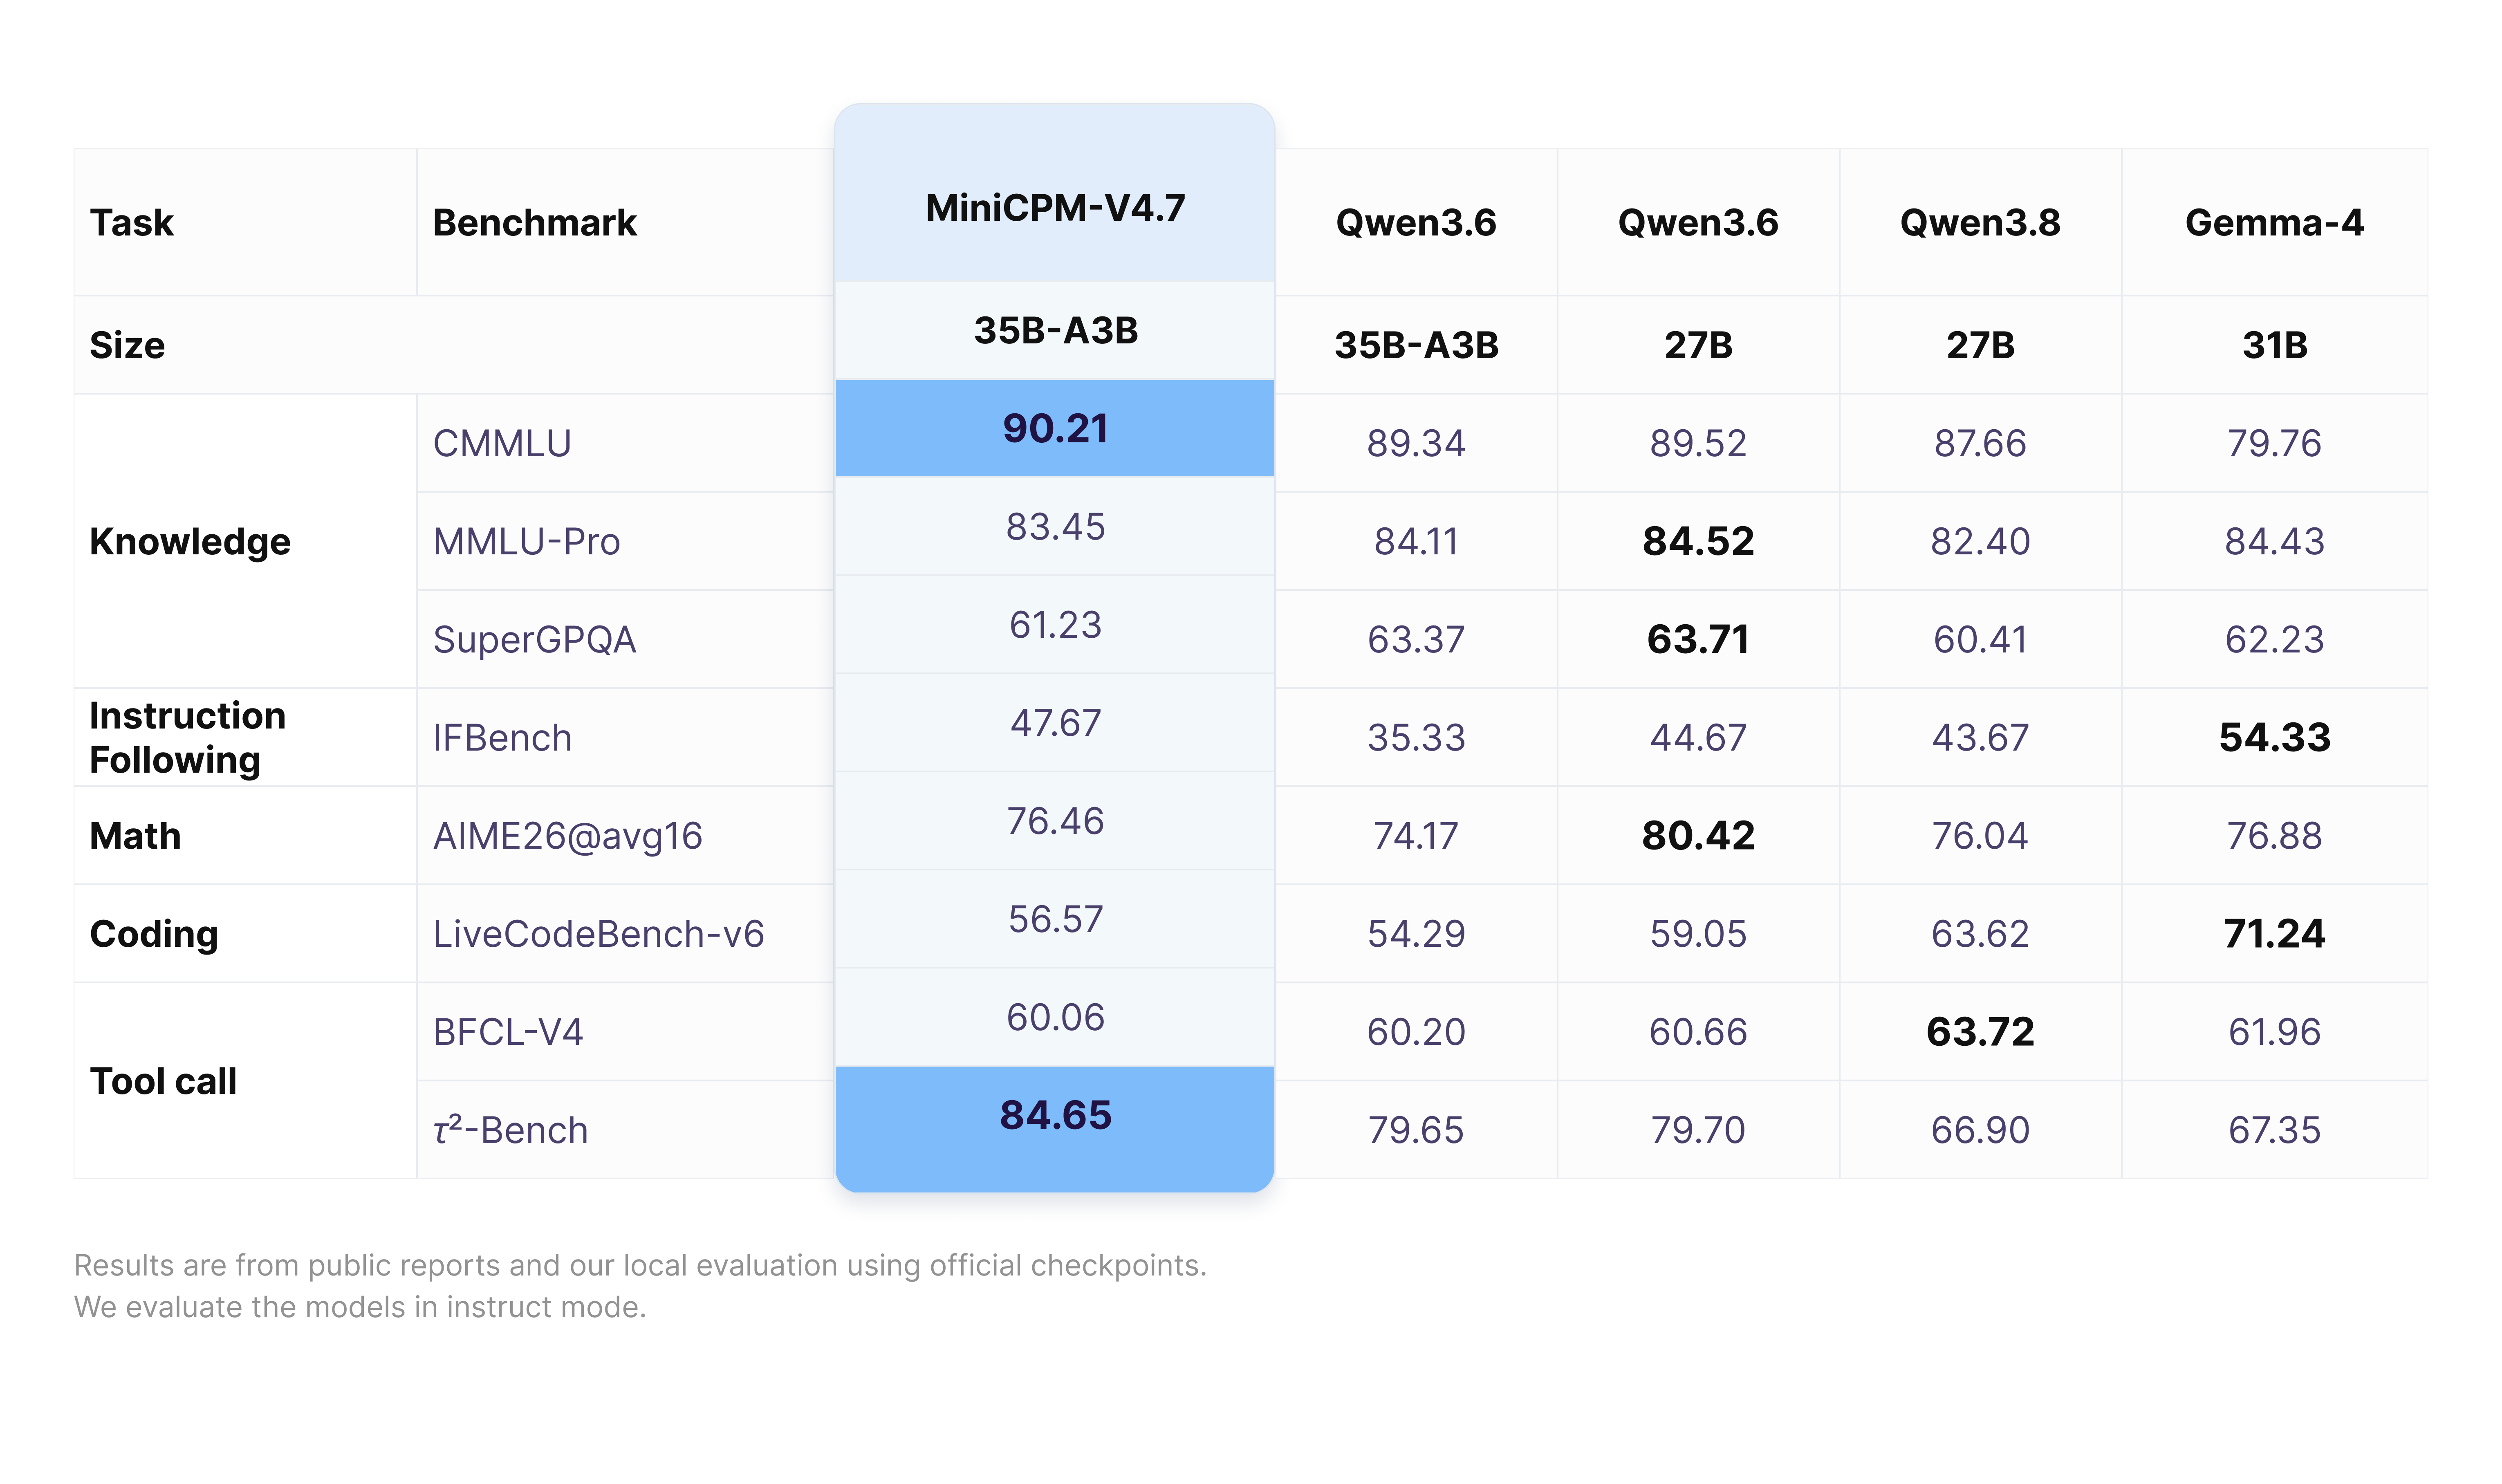
Language
https://huggingface.co/openbmb/MiniCPM-V-4.7-35B-A3B#examplesExamples
MiniCPM-V 4.7 can run on phones and tablets. The clips below are unedited screen recordings captured directly on the devices.
https://huggingface.co/openbmb/MiniCPM-V-4.7-35B-A3B#usagesUsages
https://huggingface.co/openbmb/MiniCPM-V-4.7-35B-A3B#inference-with-transformers-Inference with Transformers
Click to expand the Transformers inference examples.##### https://huggingface.co/openbmb/MiniCPM-V-4.7-35B-A3B#installation-Installation
pip install "transformers[torch]>=5.18.0" torchvision torchcodec
Note on CUDA compatibility:
torchcodec(used for video decoding) may have compatibility issues with certain CUDA versions. For example,torch\>=2\.11bundles CUDA 13.1 by default, while environments with CUDA 12.x may encounter errors such asRuntimeError: Could not load libtorchcodec. Two workarounds: 1. ReplacetorchcodecwithPyAV— supports both image and video inference without CUDA version constraints:pip install "transformers[torch]>=5.18.0" torchvision av2. Pin the CUDA versionwhen installing torch to match your environment (e.g. CUDA 12.8):pip install "transformers>=5.18.0" torchvision torchcodec --index-url https://download.pytorch.org/whl/cu128
https://huggingface.co/openbmb/MiniCPM-V-4.7-35B-A3B#load-the-model-Load the Model
import torch
from transformers import AutoModelForImageTextToText, AutoProcessor

model_id = "openbmb/MiniCPM-V-4.7-35B-A3B"

processor = AutoProcessor.from_pretrained(model_id)
model = AutoModelForImageTextToText.from_pretrained(
    model_id, torch_dtype="auto", device_map="auto"
)

# Flash Attention 2 is recommended for faster inference and lower GPU memory usage,
# especially in multi-image and video scenarios.
# model = AutoModelForImageTextToText.from_pretrained(
#     model_id,
#     torch_dtype=torch.bfloat16,
#     attn_implementation="flash_attention_2",
#     device_map="auto",
# )
https://huggingface.co/openbmb/MiniCPM-V-4.7-35B-A3B#image-inference-Image Inference
messages = [
    {
        "role": "user",
        "content": [
            {"type": "image", "url": "https://huggingface.co/datasets/openbmb/DemoCase/resolve/main/refract.png"},
            {"type": "text", "text": "What causes this phenomenon?"},
        ],
    }
]

downsample_mode = "16x"  # Using `downsample_mode="4x"` for Finer Detail

inputs = processor.apply_chat_template(
    messages, tokenize=True, add_generation_prompt=True,
    return_dict=True, return_tensors="pt",
    downsample_mode=downsample_mode,
    max_slice_nums=36,
    enable_thinking=False,
).to(model.device)

generated_ids = model.generate(**inputs, downsample_mode=downsample_mode, max_new_tokens=512)
generated_ids_trimmed = [
    out_ids[len(in_ids):] for in_ids, out_ids in zip(inputs.input_ids, generated_ids)
]
output_text = processor.batch_decode(
    generated_ids_trimmed, skip_special_tokens=True, clean_up_tokenization_spaces=False
)
print(output_text[0])
https://huggingface.co/openbmb/MiniCPM-V-4.7-35B-A3B#video-inference-Video Inference
messages = [
    {
        "role": "user",
        "content": [
            {"type": "video", "url": "https://huggingface.co/datasets/openbmb/DemoCase/resolve/main/football.mp4"},
            {"type": "text", "text": "Describe this video in detail. Follow the timeline and focus on on-screen text, interface changes, main actions, and scene changes."},
        ],
    }
]

downsample_mode = "16x"  # Using `downsample_mode="4x"` for Finer Detail

inputs = processor.apply_chat_template(
    messages, tokenize=True, add_generation_prompt=True,
    return_dict=True, return_tensors="pt",
    downsample_mode=downsample_mode,
    max_num_frames=128,
    stack_frames=1,
    max_slice_nums=1,
    use_image_id=False,
    enable_thinking=False,
).to(model.device)

generated_ids = model.generate(**inputs, downsample_mode=downsample_mode, max_new_tokens=2048)
generated_ids_trimmed = [
    out_ids[len(in_ids):] for in_ids, out_ids in zip(inputs.input_ids, generated_ids)
]
output_text = processor.batch_decode(
    generated_ids_trimmed, skip_special_tokens=True, clean_up_tokenization_spaces=False
)
print(output_text[0])
https://huggingface.co/openbmb/MiniCPM-V-4.7-35B-A3B#advanced-parameters-Advanced Parameters
You can customize image/video processing by passing additional parameters toapply\_chat\_template:
ParameterDefaultApplies toDescriptiondownsample\_mode``"16x"Image & VideoVisual token downsampling."16x"merges tokens for efficiency;"4x"keeps four times as many tokens for finer detail.Must also be passed togenerate\(\).max\_slice\_nums``9Image & VideoMaximum number of slices when splitting a high-resolution image. Higher values preserve more detail for large images. Recommended:36for image,1for video.max\_num\_frames``128Video onlyMaximum number of main frames sampled from the video.stack\_frames``1Video onlyTotal sample points per second.1= main frame only (no stacking).N(N>1) = 1 main frame + N−1 sub-frames per second; the sub-frames are composited into a grid image and interleaved with main frames. Recommended:3or5.use\_image\_id``TrueImage & VideoWhether to prepend<image\_id\>N</image\_id\>tags before each image/frame placeholder. Recommended:Truefor image,Falsefor video.
Note:
downsample\_modemust be passed tobothapply\_chat\_template(for correct placeholder count) andgenerate(for the vision encoder). All other parameters only need to be passed toapply\_chat\_template.
https://huggingface.co/openbmb/MiniCPM-V-4.7-35B-A3B#serving-with-transformers-serve-Serving withtransformers serve
Hugging Face Transformers includes a lightweight OpenAI-compatible server for quick testing and moderate-load deployment.
pip install "transformers[serving]>=5.18.0"
Start the server:
transformers serve openbmb/MiniCPM-V-4.7-35B-A3B --port 8000 --host 0.0.0.0
Send a request:
curl -s http://localhost:8000/v1/chat/completions \
  -H 'Content-Type: application/json' \
  -d '{
    "model": "openbmb/MiniCPM-V-4.7-35B-A3B",
    "messages": [{
      "role": "user",
      "content": [
        {"type": "image_url", "image_url": {"url": "https://huggingface.co/datasets/openbmb/DemoCase/resolve/main/refract.png"}},
        {"type": "text", "text": "What causes this phenomenon?"}
      ]
    }]
  }'
Tool calling example:
curl -s http://localhost:8000/v1/chat/completions -H 'Content-Type: application/json' -d '{
  "model": "openbmb/MiniCPM-V-4.7-35B-A3B",
  "messages": [{"role": "user", "content": [
    {"type": "text", "text": "the weather of Beijing"}
  ]}],
  "tools": [{
    "type": "function",
    "function": {
      "name": "get_weather",
      "description": "Get the current weather for a given location",
      "parameters": {
        "type": "object",
        "properties": {
          "location": {"type": "string", "description": "City name"}
        },
        "required": ["location"]
      }
    }
  }]
}'
https://huggingface.co/openbmb/MiniCPM-V-4.7-35B-A3B#speculative-decoding-dspark-Speculative decoding (DSpark)
Click to show speculative decoding.Speculative decoding (DSpark): we also releaseMiniCPM-V-4.7-35B-A3B-DSpark, a DSpark draft model trained forMiniCPM-V-4.7-35B-A3B.
https://huggingface.co/openbmb/MiniCPM-V-4.7-35B-A3B#inference-with-openvino%E2%84%A2Inference with OpenVINO™
OpenVINO™is an open-source toolkit for optimizing and deploying AI inference on Intel CPU/GPU/NPU platforms. OpenVINO provides day-0 support for MiniCPM-V-4.7 on Intel platforms with high-performance inference. See theOpenVINO™ Toolkitto get started. You can install and run the example with this notebook (link TBD).
https://huggingface.co/openbmb/MiniCPM-V-4.7-35B-A3B#on-device-deploymentOn-Device Deployment
MiniCPM-V 4.7 supports deployment on iOS, Android, and HarmonyOS, with day-0 support for Rockchip, Houmo, Intel, AMD, and Arm chip platforms. See theedge deployment repositoryfor the apps and source code.
https://huggingface.co/openbmb/MiniCPM-V-4.7-35B-A3B#inference-and-fine-tuningInference and Fine-Tuning
For supported inference and training frameworks, seeSupported Inference and Training Frameworks and API. TheMiniCPM-V 4.7 Cookbookcovers deployment, fine-tuning, and quantization workflows.
Task guides
Quantization
https://huggingface.co/openbmb/MiniCPM-V-4.7-35B-A3B#acknowledgementsAcknowledgements
Click to view acknowledgements.We would like to thank the following projects:
- Qwen3.6for providing the language backbone
- SigLIP2for providing the vision understanding module
- Transformers
https://huggingface.co/openbmb/MiniCPM-V-4.7-35B-A3B#model-weightsModel Weights
MiniCPM-V 4.7 is available in the following variants:
Also available onOllama.
Similar Articles
openbmb/MiniCPM-V-4.7-1B
MiniCPM-V 4.7 1B 是 MiniCPM-V 系列最新模型,主打性能与效率的新帕累托前沿,采用早期视觉 token 压缩架构,支持 iOS/Android/HarmonyOS 及多家芯片平台的端侧部署,并提供 FP8 量化与 Self-Replay 微调方法。
openbmb/MiniCPM-V-4.7-35B-A3B-gguf
MiniCPM-V 4.7 35B-A3B is the first MoE model in the MiniCPM-V series, released in GGUF-quantized form for llama.cpp, enabling lossless on-device multimodal inference at 13+ tokens/s with only 3GB of memory on iPhone 17 Pro Max while surpassing Qwen3.6 35B-A3B in performance-efficiency.
@FeitengLi: OpenBMB open-sources MiniCPM-V 4.6, 1.3B parameters (SigLIP2-400M + Qwen3.5-0.8B), 262k context, visual encoding FLOPs 50%+ less than previous generation. Token cost for the same task is lower than Qwen3.5-0…
OpenBMB releases MiniCPM-V 4.6, a 1.3B-parameter multimodal LLM with 262k context and significantly reduced visual encoding FLOPs, achieving strong benchmark performance and broad inference framework support.
openbmb/MiniCPM5-2B-GGUF
Release of MiniCPM5-2B-GGUF, a 2B parameter AI model optimized for on-device deployment, achieving state-of-the-art performance in its class with open-source training datasets.
A 35B vision model running on an iPhone? OpenBMB just released MiniCPM-V 4.7
OpenBMB 开源发布了 MiniCPM-V 4.7 35B-A3B 视觉语言模型,可在 iPhone/iPad 上以 13-17 tok/s 运行,并引入 LES(前瞻专家调度)技术加速 MoE 推理,同时更新 34 项多模态基准表现。