@anyscalecompute: LLM post-training is the new baseline. Picking the wrong method or GPU config is how you waste a 36-hour run. Introduci…
Summary
Anyscale introduces a new Agent Skill for LLM post-training that automatically selects the optimal fine-tuning method (SFT, DPO, GRPO, etc.) and generates ready-to-launch configs, helping avoid wasted GPU runs.
View Cached Full Text
Cached at: 05/15/26, 09:08 PM
LLM post-training is the new baseline. Picking the wrong method or GPU config is how you waste a 36-hour run. Introducing Anyscale Post Training skill, an Anyscale Agent Skill that picks your method (SFT, DPO, GRPO, PPO), plans GPU memory, and generates ready-to-launch configs before your run starts. https://na2.hubs.ly/H05t71j0
Introducing the Anyscale LLM Post-Training Skill
Source: https://www.anyscale.com/blog/anyscale-llm-post-training-skill
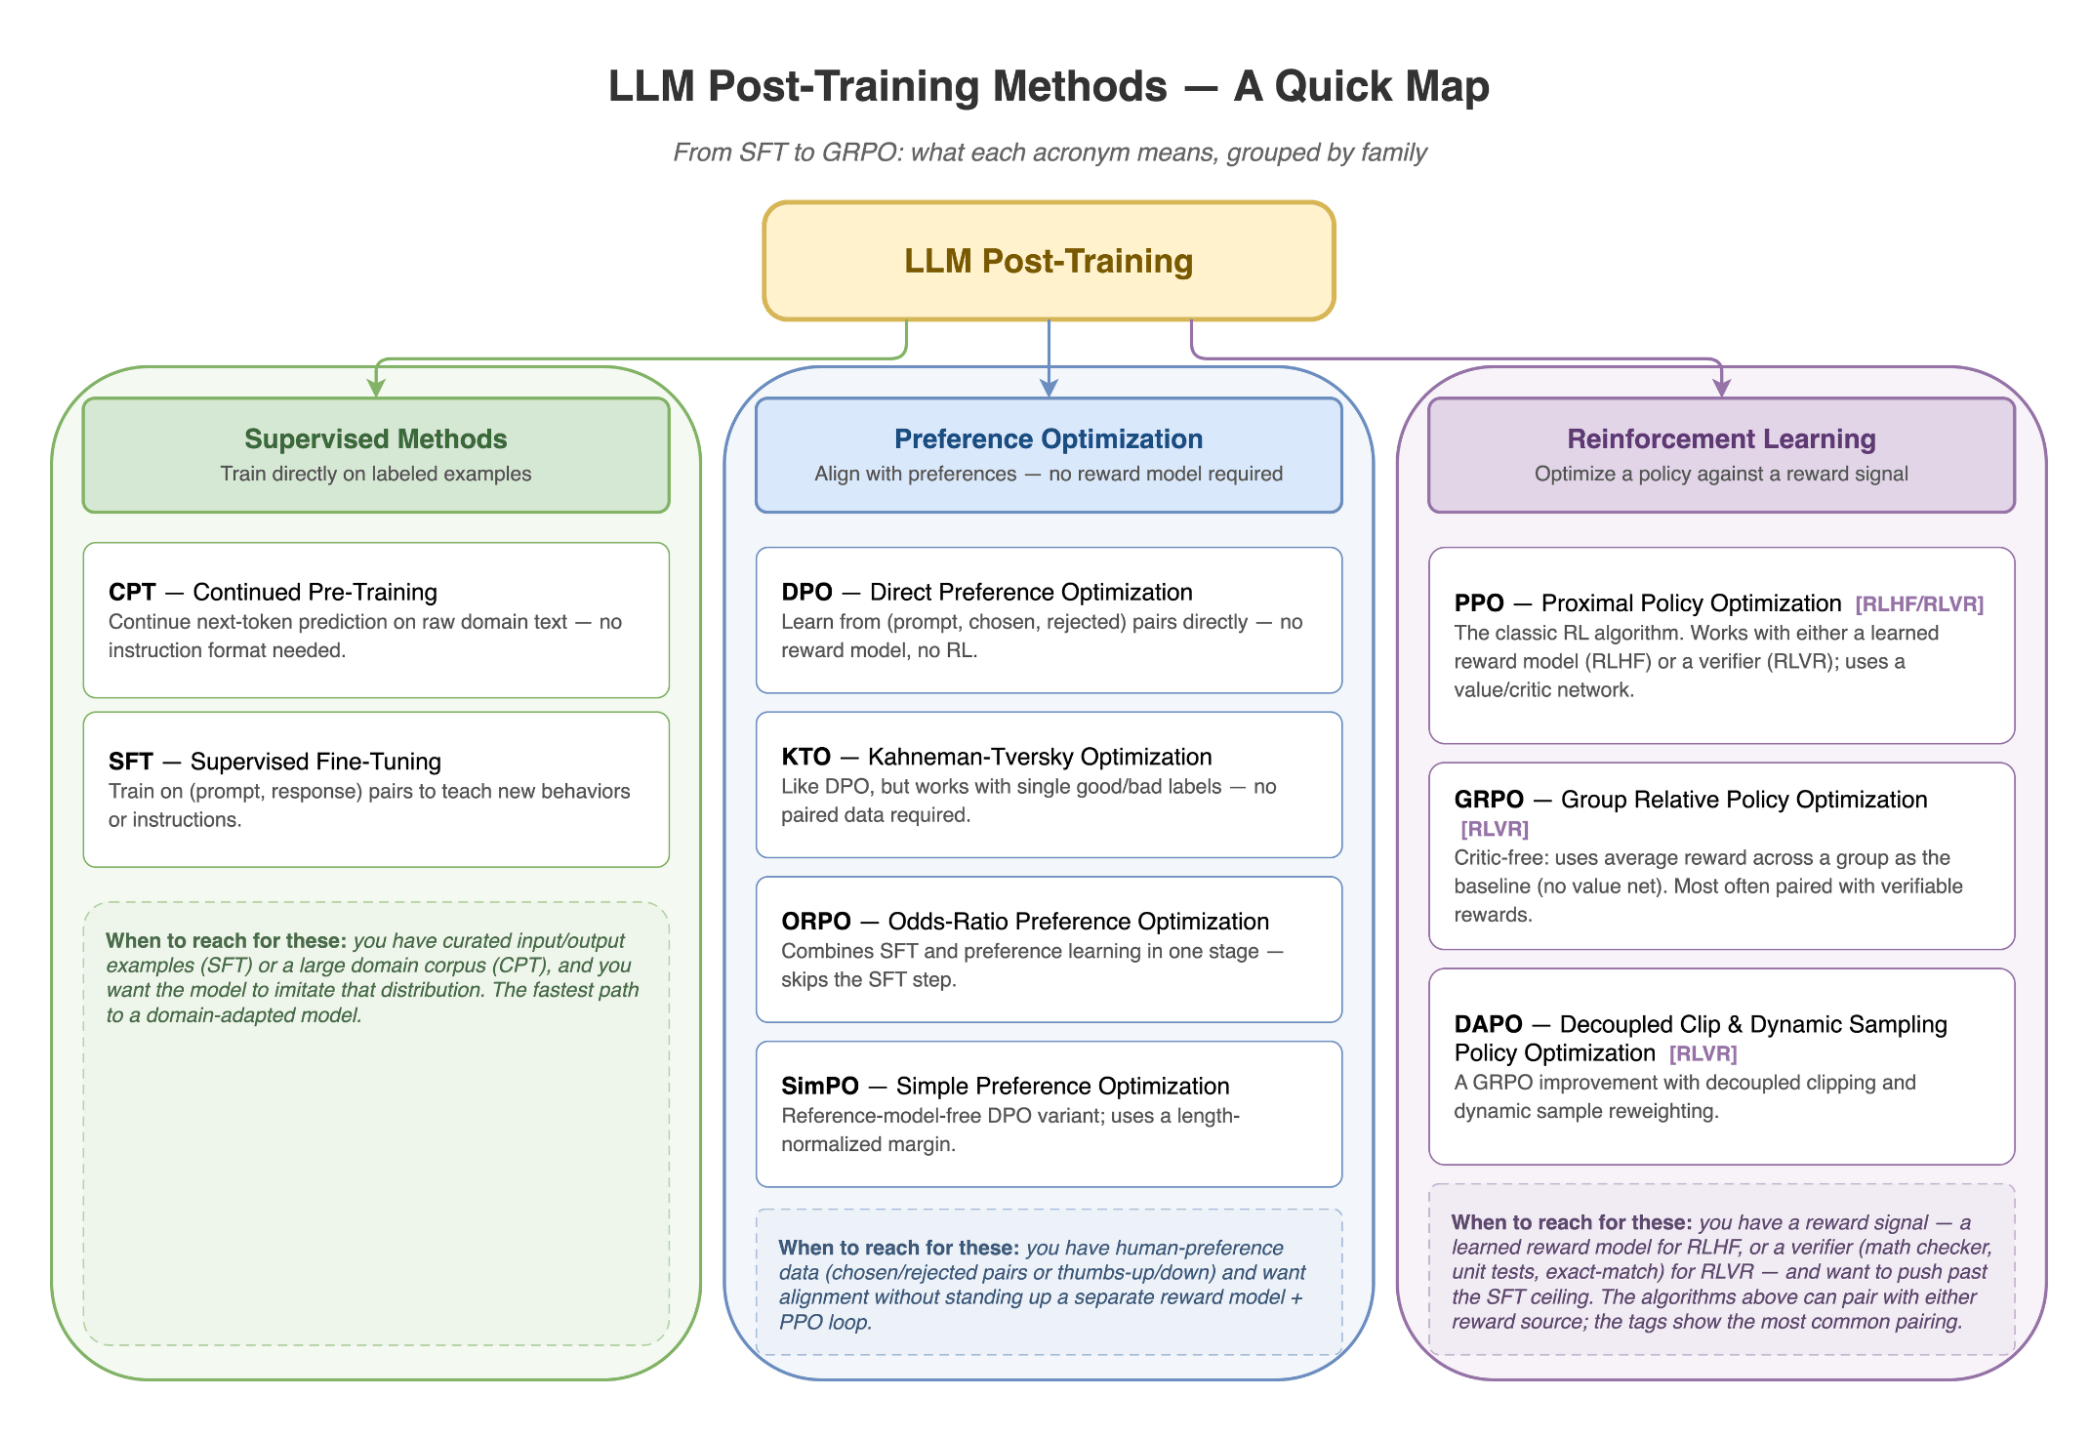
Today we’re introducing/anyscale\-workload\-llm\-post\-training, a new addition toAnyscale Agent Skillsfor scoping and generatingLLM post-trainingruns on Anyscale. Given a model, dataset, objective, and target hardware, the skill helps choose between SFT, continued pre-training (CPT), preference optimization methods such as DPO, KTO, ORPO, and SimPO, classic RLHF with PPO, and RLVR methods such as GRPO and DAPO. It then generates standard framework configs for LLaMA-Factory, SkyRL, or Ray Train and prepares them forAnyscale Jobs.
LinkLLM post-training is the new frontier — but harder than everhttps://www.anyscale.com/blog/anyscale-llm-post-training-skill#llm-post-training-is-the-new-frontier-%E2%80%94-but-harder-than-ever
LLM post-training has moved through a few distinct waves. The first modern wave was instruction tuning / supervised finetuning (SFT) and Reinforcement Learning from Human Feedback (RLHF) at scale: OpenAI’sInstructGPTshowed that supervised demonstrations plus human preference rankings could make a smaller GPT-3 model feel more useful and aligned than a much larger base model, and ChatGPT made that recipe familiar to everyone building product LLMs. Strictly speaking, RLHF was not invented by InstructGPT; earlier work used human-feedback reward models for language tasks. But InstructGPT made RLHF the reference architecture for instruction-following LLMs: collect demonstrations, train a reward model from ranked outputs, then optimize the policy, most commonly with Proximal Policy Optimization (PPO).
The second wave made alignment cheaper and easier to operate. Preference optimization methods such asDPO, KTO, ORPO, andSimPOkept the human preference data but removed the separate online RL loop, giving teams a more direct way to move a model toward preferred answers.
DeepSeek-R1marked the most recent major shift for reasoning models. Its success helped popularize Reinforcement Learning from Verifiable Rewards (RLVR), such asGRPOandDAPO, where the reward comes from a programmatic verifier instead of a learned reward model: math correctness, unit tests, exact match, SQL execution, or another check the system can grade automatically.
That history explains the method menu teams face today: SFT to teach new behaviors, DPO-style methods to align with preference data, RLHF when human preference modeling is central, and GRPO/DAPO-style RLVR when the task can be checked automatically.
anyscale-llm-post-training-skill-image3 Selecting the RL stack has become its own engineering problem. The landscape ofopen-source RL libraries for LLMsillustrates just how rapidly the post-training ecosystem has fragmented: TRL, verl, OpenRLHF, RAGEN, NeMo-RL, ROLL, AReaL, Verifiers, SkyRL, and slime all target overlapping but different combinations of RLHF, reasoning, and agentic RL. The right choice depends on more than whether you want PPO or GRPO; it also depends on generator and environment abstractions, training backend, inference engine, async rollout support, weight synchronization, and orchestration model.
Once teams move beyond a tutorial and into a real post-training run, the complexity becomes concrete:
- **Methodology choice.**CPT, SFT, DPO, KTO, ORPO, PPO, or GRPO? Each has a different data shape, reward-model requirement, and GPU profile.
- **Framework choice.**A library optimized for text-only RLHF may not expose the environment layer needed for tool-use agents; a high-performance stack may colocate training and generation in ways that reduce GPU usage but constrain rollout flexibility. Picking the wrong starting point can mean rewriting the pipeline halfway through.
- **GPU planning that’s actually right.**RLVR setups can require multiple resident model instances — for example, a trainable policy, a frozen reference model for KL regularization, and a vLLM rollout engine. For a dense 7B model in bf16, each copy is roughly 14 GB, so three copies create a ~42 GB weight-memory floor before optimizer state, activations, KV cache, and framework overhead. For MoE models, total parameters drive weight memory even when only a subset of experts is active per token.
- **Dependency hell.**Mismatched CUDA toolkits, unpinned
torchwheels, DeepSpeed compatibility constraints, and FSDP+QLoRA dtype requirements can surface only at runtime. The skill pins dependencies against the selected Anyscale runtime and flags framework-specific settings such asbnb\_4bit\_quant\_storage=torch\.bfloat16where required.
LinkWhat we built: a skill that makes the hard decisions with youhttps://www.anyscale.com/blog/anyscale-llm-post-training-skill#what-we-built:-a-skill-that-makes-the-hard-decisions-with-you
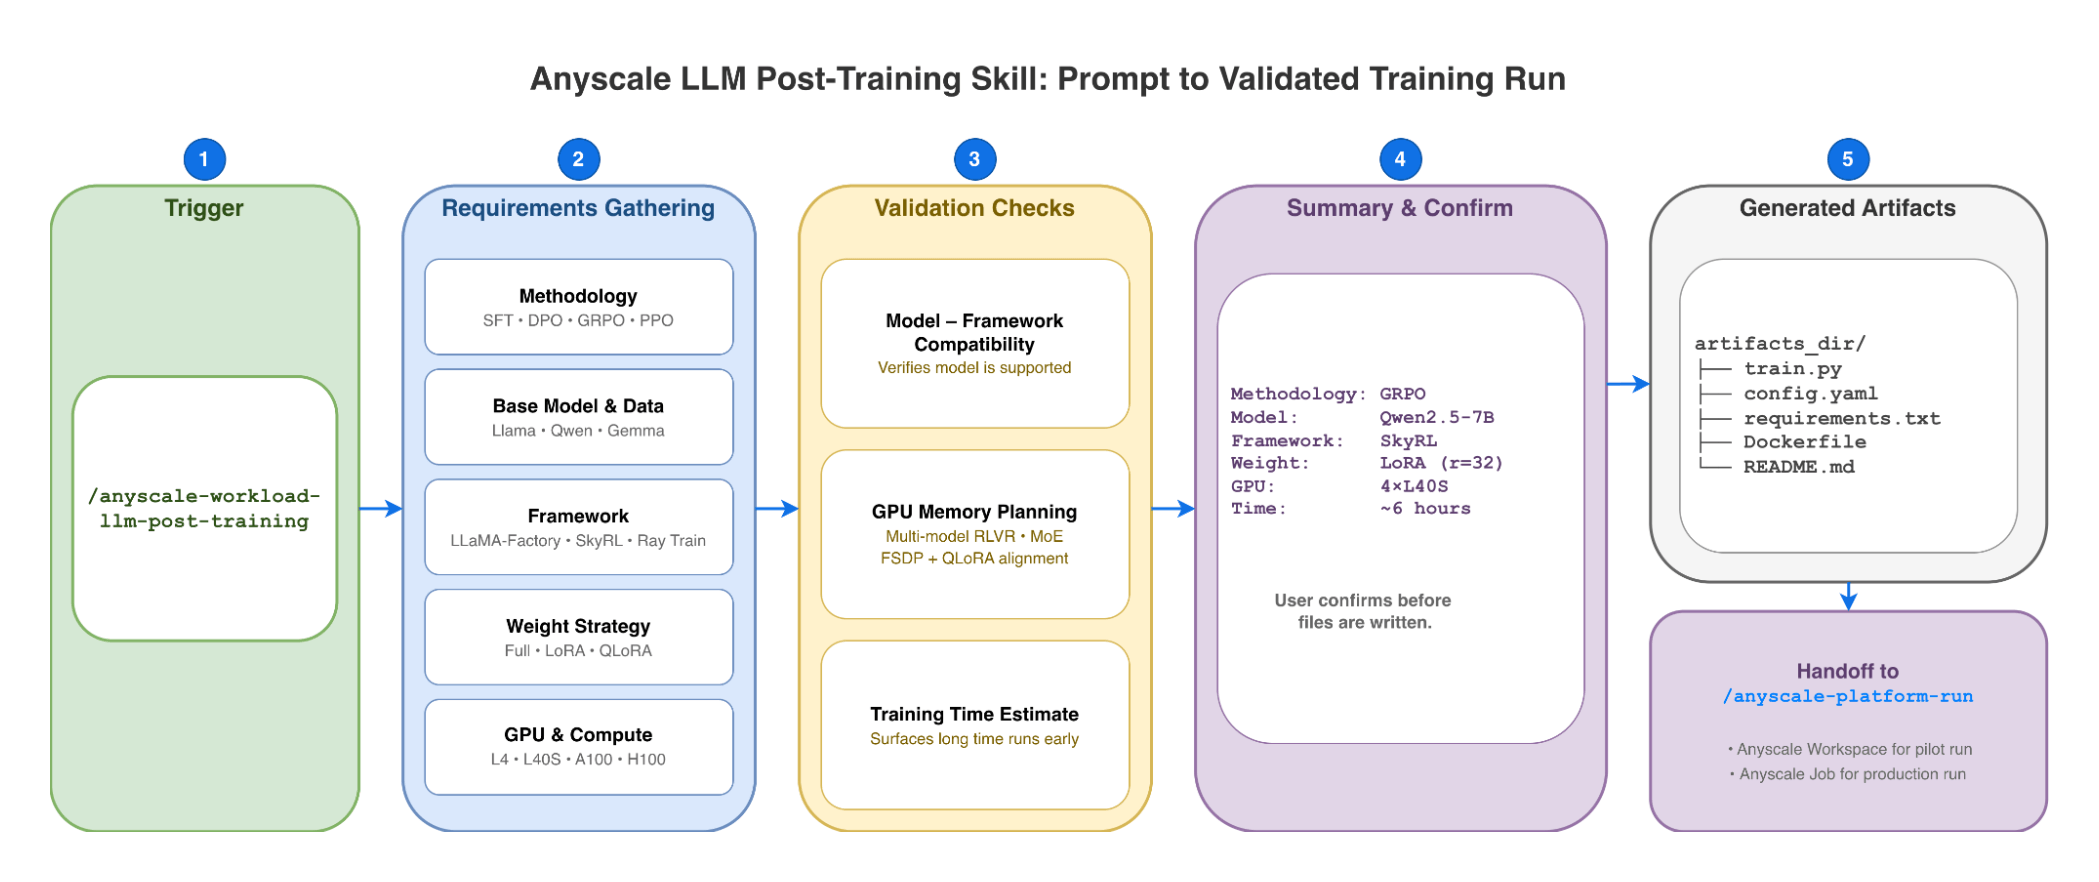
/anyscale\-workload\-llm\-post\-trainingwalks an AI coding agent through an interactive, multiple-choice requirements flow that mirrors how an Anyscale Forward Deployed Engineer would scope an LLM fine-tuning project — and then generates code, configs, and dependencies for the selected Anyscale runtime.
Before writing any code, the skill:
- Picks the methodology—SFTfor instruction-following,DPO/SimPO/ORPOfor reward-model-free preference optimization,GRPO/DAPOfor verifiable-reward tasks,PPOwhen you need policy optimization with a reward signal, oragentic tuningfor tool use.
- Recommends a framework—LLaMA-Factoryfor SFT, CPT, and preference optimization,SkyRLfor RLVR and agentic rollouts, orRay Trainfor custom training loops and reward models, following the same trade-offs described inChoose a framework for LLM post-training.
- Verifies model–framework compatibilityby checking the framework’s supported-models page against your base model (Llama, Qwen, Gemma, DeepSeek, Mistral, etc.).
- Plans GPU memory and node shape— including multi-model RLVR placement, MoE weight accounting, FSDP+QLoRA dtype alignment, and the trade-off between
accelerator\_type(flexible scheduling) andanyscale/accelerator\_shape(single-node placement for frameworks that benefit from fixed local topology). - **Estimates training time before launch.**A 36-hour run on 4×L4 is surfacedbeforeyou start, alongside a comparison table of faster GPU alternatives.
- Surfaces evaluation and checkpointing choices— validation dataset paths, checkpoint cadence, artifact storage, and framework-native eval commands are captured in the generated README instead of being left as afterthoughts. This matches the documentation’s guidance to evaluate task performance, safety, robustness, and regressions throughout post-training.
- Avoids known version traps— pins CUDA-compatible torch wheels in a Dockerfile when needed, accounts for LLaMA-Factory and DeepSpeed compatibility constraints, and flags framework-specific dtype and scheduler settings before the job starts.
anyscale-llm-post-training-skill-image1
The output is a timestampedartifacts\_dir/containing a native framework script, a YAML config,requirements\.txt, aDockerfilewhen needed, and a README for launching as anAnyscale Jobor running interactively in a workspace. Because the skill generates standard open-source code rather than proprietary abstractions, you retain full control over the training loop.
Note: the skill does not replace ML judgment — teams still owndataset quality and labeling, reward design, eval selection, and final approval before launching jobs that incur cloud costs. Its job is to make the setup, compatibility checks, and operational scaffolding explicit before GPUs start running.
LinkWithout the skill vs with the skillhttps://www.anyscale.com/blog/anyscale-llm-post-training-skill#without-the-skill-vs-with-the-skill
Failure mode
Without the skill
With the skill
Wrong methodology for the data
Discovered after first run flatlines
Recommended based on the user’s preference-data shape
torchwheel built for a newer CUDA runtime than the node driver supports
Runtime CUDA mismatch
Torch wheel pinned against the selected Anyscale runtime
RLVR OOM on 4×L40S — reference model or rollout engine not budgeted
Hours of triage on the first rollout
Multi-model footprint estimated before launch
36\-hour run discovered at hour 30
Schedule blown
Estimate surfaced at config time, with upgrade options
FSDP or DeepSpeed compatibility issue
Training never starts
Compatibility setting surfaced in generated runtime config
LinkExample: Launch GRPO on GSM8K with the Agent Skillhttps://www.anyscale.com/blog/anyscale-llm-post-training-skill#example:-launch-grpo-on-gsm8k-with-the-agent-skill
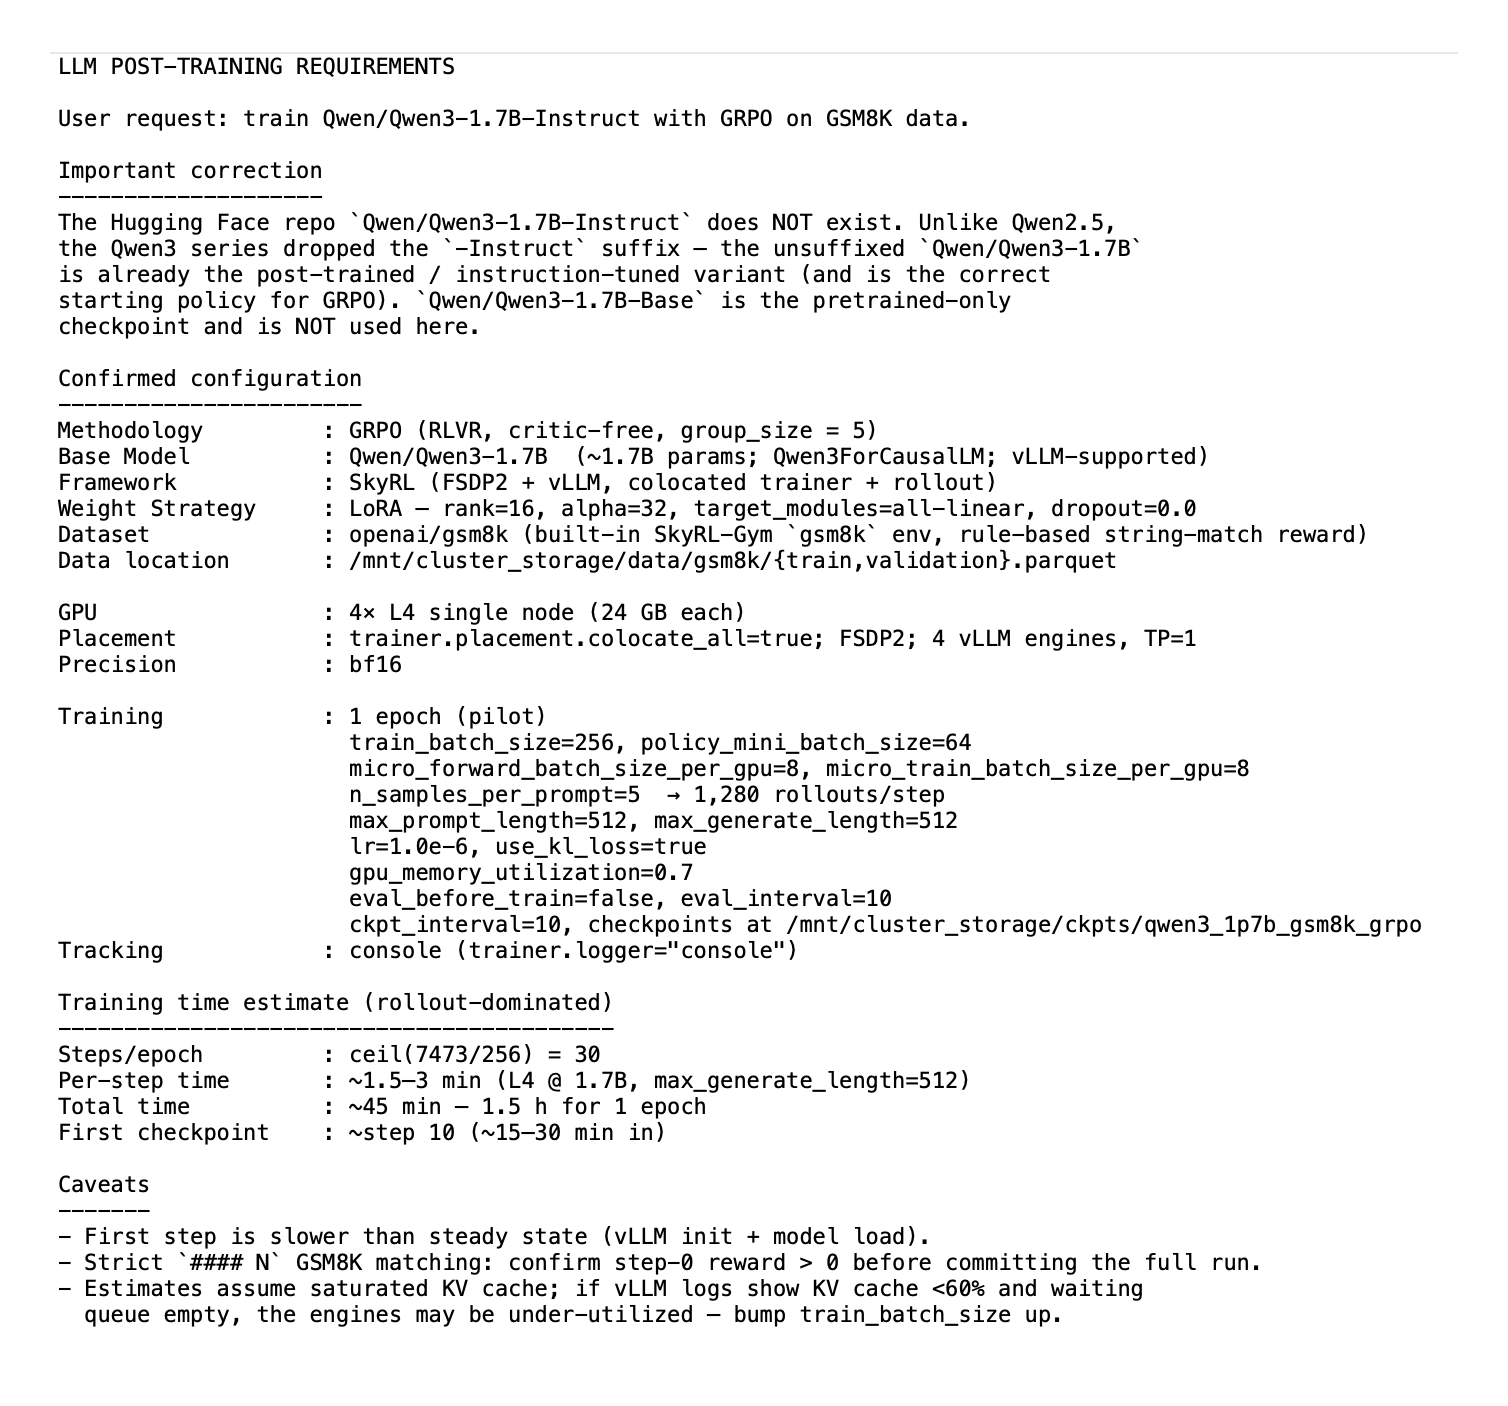
/anyscale-workload-llm-post-training train Qwen/Qwen3-1.7B-Instruct with GRPO on GSM8K data
Your browser does not support the video tag.
The agent gathers requirements, then surfaces a confirmation summarybeforegenerating any files:
anyscale-llm-post-training-skill-image2
Once confirmed, the skill writes a timestamped artifact directory and hands off to/anyscale\-platform\-run, which launches it on Anyscale (workspace for interactive iteration, job for unattended runs). The flow follows the sameGRPO with SkyRLpattern documented for Anyscale Jobs.
qwen25_7b_instruct_grpo_gsm8k_llm_posttraining_<timestamp>/
├── README.md                  # setup, monitoring, eval, LoRA/merged deployment
├── user_request_summary.txt   # frozen config + memory budget + time estimate
├── workspace.yaml             # 4× L40S single node on the SkyRL FSDP image
├── requirements.txt           # extras for data prep (image has the rest)
├── prepare_data.py            # wraps SkyRL's gsm8k_dataset.py + 64-row pilot slice
├── run_train.sh               # script to start the training process
LinkExecuting runs and resolving errors with the Anyscale Platform Skillshttps://www.anyscale.com/blog/anyscale-llm-post-training-skill#executing-runs-and-resolving-errors-with-the-anyscale-platform-skills
Once the skill generates your training assets, the agent will recommend using/anyscale\-platform\-runto initiate a pilot execution. This short-cycle validation checks model loading, FSDP2 sharding, vLLM initialization, weight synchronization, and reward logic within minutes, surfacing OOM errors or configuration trapsbeforeyou commit to a full-scale run. Upon a successful pilot, the agent prompts you to launch the production training job across your entire dataset.
When a run encounters a mid-flight failure—whether it’s an NCCL timeout, disk exhaustion during checkpointing, or a diverging loss curve—the platform removes the need to manually SSH into nodes or parse raw Ray logs. Instead, /anyscale-platform-fix can analyze the active job telemetry, actor logs, and cluster metrics to diagnose the root cause. The skill can also monitor the training process in real-time, detecting issues like the reward signal remains to 0 and proposing actionable resolutions—such as adjusting the reward verifier logic or the vLLM config parameters. It can then relaunch the environment or job upon your approval, and once training is complete, the skill can automate merging the LoRA adapters back into the base LLM weights.
LinkComposes with other Agent Skillshttps://www.anyscale.com/blog/anyscale-llm-post-training-skill#composes-with-other-agent-skills
Once your post-training run completes, you can transition to production by leveraging the/anyscale\-workload\-llm\-servingskill to launch the model as anAnyscale Service.
/anyscale-workload-llm-serving deploy [path_to_checkpoints] as a multi-LoRA endpoint
Alternatively, you may merge the LoRA adapters into the base weights and utilize the/anyscale\-workload\-ray\-dataskill to orchestrate a large-scale batch inference workload:
/anyscale-workload-llm-post-training merge lora adapter [path_to_checkpoints] to the base LLM and then use /anyscale-workload-ray-data to summarize PDFs in [path_to_pdf_files]
LinkGet startedhttps://www.anyscale.com/blog/anyscale-llm-post-training-skill#get-started
The post-training skill ships with the existing Agent Skills release and installs through theAnyscale Agent Skills installation flow.
If you don’t see/anyscale\-workload\-llm\-post\-traininginanyscale skills list, update the Anyscale CLI and confirm that the skill is available for your organization.
LinkResources:https://www.anyscale.com/blog/anyscale-llm-post-training-skill#resources:
- Anyscale Agent Skills documentation
- Anyscale template: Anyscale GRPO with SkyRL
- Anyscale template: Anyscale Fine-tuning LLMs with LLaMA-Factory
- Anyscale template: Anyscale Fine-tune an LLM with Ray Train and DeepSpeed
- Post-training for LLMs on Anyscale
- Why post-train your LLM
- Dataset preparation for LLM post-training
- Choose a framework for LLM post-training
- Deploy multi-LoRA adapters on LLMs
Similar Articles
@_avichawla: SFT vs. DPO vs. RLVR, clearly explained: All three methods customize an LLM, but they learn from different forms of sup…
An explainer comparing SFT, DPO, and RLVR for customizing LLMs, with a hands-on experiment training Qwen3 0.6B on GSM8K using GRPO on Amazon SageMaker AI, achieving a ~2.9 percentage-point accuracy gain, plus guidance on choosing the right supervision method and an AWS serverless model-customization workshop.
@Suryanshti777: NVIDIA just revealed the hidden tricks they’re using to make LLM fine-tuning dramatically faster. Not new GPUs. Not big…
NVIDIA and Unsloth have published a technical guide detailing three low-level optimizations that can accelerate LLM fine-tuning by up to 25%, including packed-sequence caching, double-buffered checkpointing, and optimized MoE routing. The guide provides deep systems-level explanations and benchmarks aimed at ML engineers and developers.
@AnnmariaKAntony: LLMs are good at CUDA because the internet is full of it. But a model that gives you highly optimized CUDA may still st…
A multi-agent synthetic data pipeline with SFT and GRPO RL post-training improves HIP compilation and correctness on AMD MI350X GPUs for a 14B open-source model.
Show HN: Fine-tune an 8B model on a 4 GB laptop GPU
Soup is an open-source CLI that simplifies LLM fine-tuning and post-training with a single command, enabling QLoRA-based training on consumer GPUs with as little as 4 GB VRAM via layer streaming. The latest version adds preference losses like DPO, ORPO, SimPO, and KTO without doubling memory requirements.
@AlphaSignalAI: You can now boost any LLM's accuracy 2-10x without training it. Most teams improve model accuracy by fine-tuning or swa…
OptiLLM is an open-source proxy that boosts any LLM's accuracy 2-10x by adding extra compute at inference time, using techniques like multi-agent cross-verification and Monte Carlo tree search.