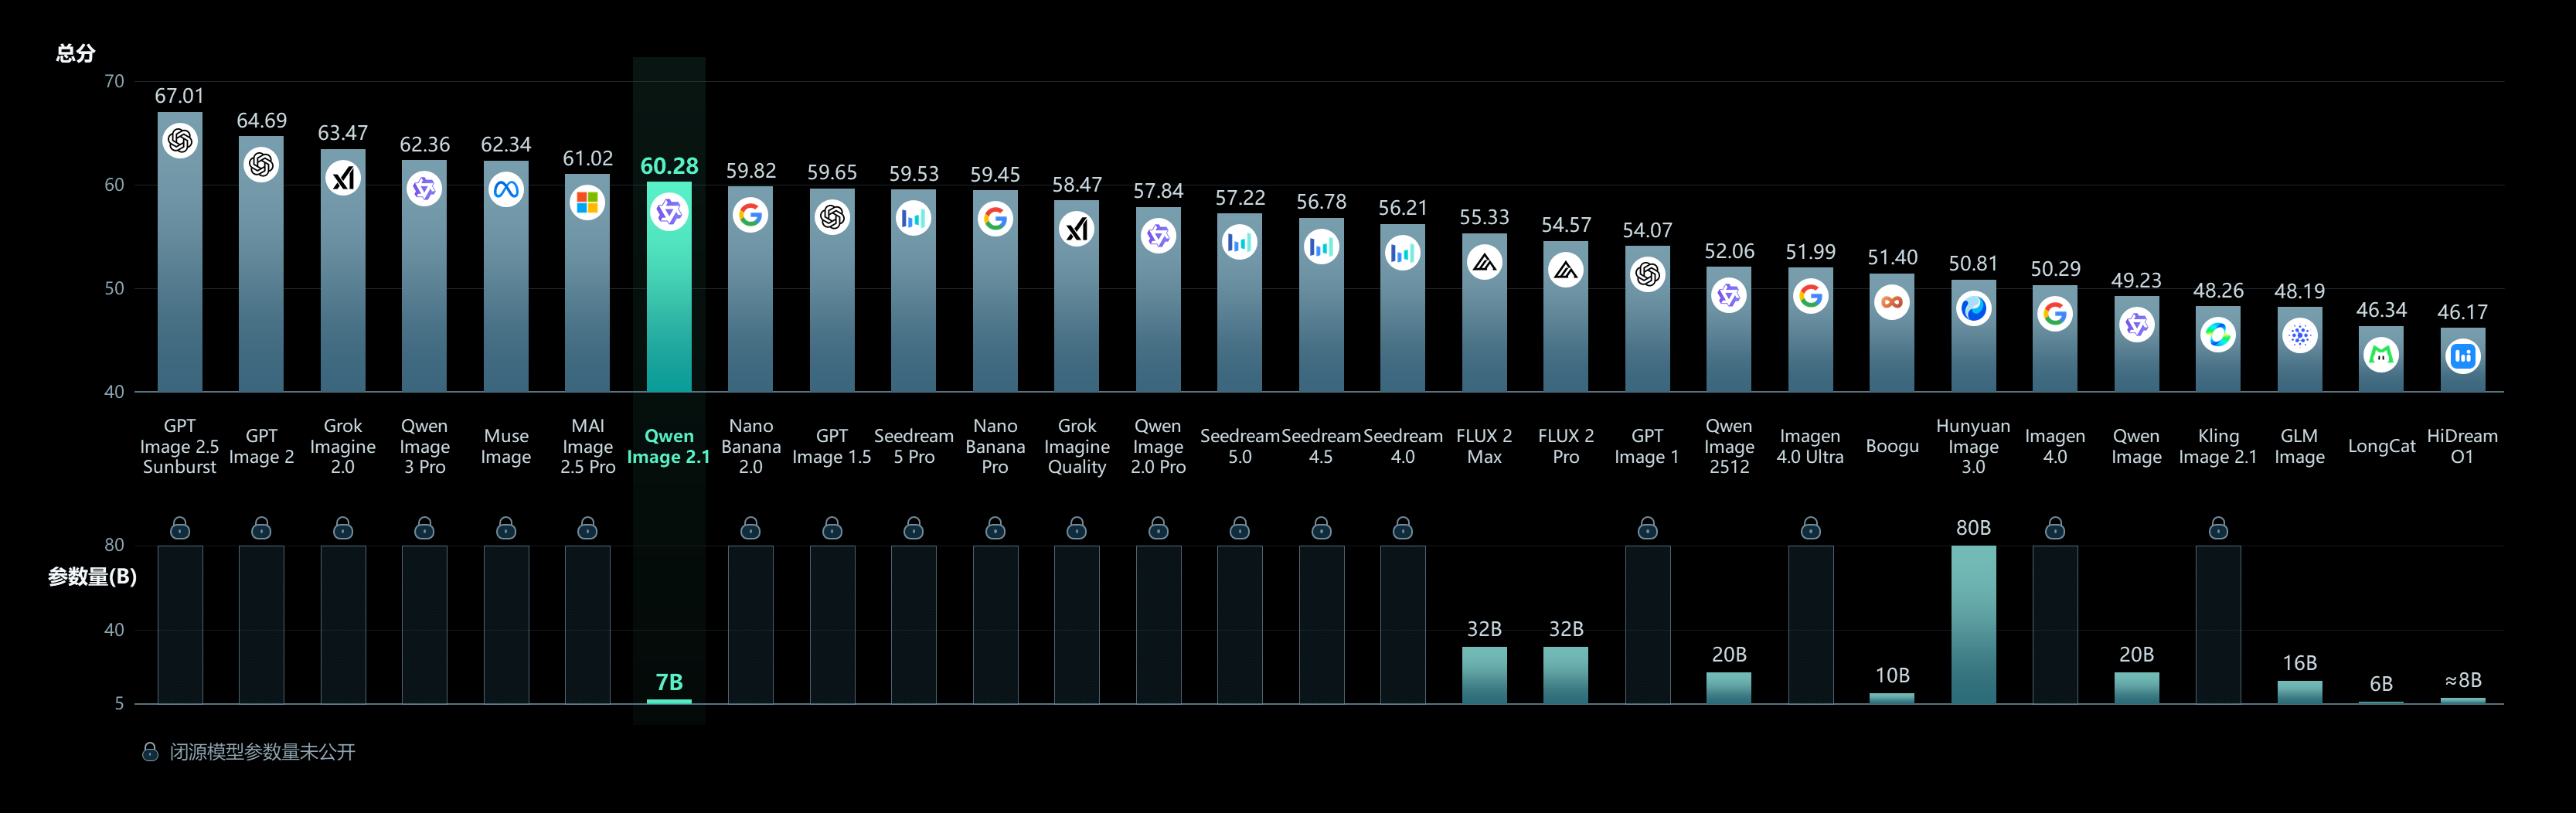
@UnslothAI: Qwen-Image-2.1 can now run locally on 12GB VRAM with Unsloth GGUFs! The 7B model performs on par with Nano Banana 2.0. …
Summary
Unsloth has released GGUF quantized versions of Qwen-Image-2.1, enabling it to run locally on 12GB VRAM with performance comparable to Nano Banana 2.0.
View Cached Full Text
Cached at: 09/23/26, 12:10 PM
Qwen-Image-2.1 can now run locally on 12GB VRAM with Unsloth GGUFs! The 7B model performs on par with Nano Banana 2.0. For higher quality, you can also run Dynamic FP8 on just 6GB of VRAM via offloading. GGUF: https://huggingface.co/unsloth/Qwen-Image-2.1-GGUF… Guide: https://unsloth.ai/docs/models/qwen-image-2.1…
unsloth/Qwen-Image-2.1-GGUF · Hugging Face
Source: https://huggingface.co/unsloth/Qwen-Image-2.1-GGUF
https://huggingface.co/unsloth/Qwen-Image-2.1-GGUF#read-our-how-to-run-qwen-image-21-guide-%F0%9F%92%9CRead our How toRun Qwen-Image-2.1 Guide!💜
This is a GGUF quantized version ofQwen-Image-2.1. unsloth/Qwen-Image-2.1-GGUF usesUnsloth Dynamic 2.0methodology for SOTA performance.
sd-cli --diffusion-model qwen-image-2.1-Q4_K_M.gguf \
  --vae qwen_image_2.1_vae_bf16.safetensors \
  --llm Qwen3-VL-8B-Instruct-UD-Q4_K_XL.gguf \
  -p "a cartoon sloth mascot waving, flat vector illustration, bright colours" \
  --steps 20 --cfg-scale 6.0 --sampling-method euler -W 1024 -H 1024 --diffusion-fa \
  -o out.png
https://huggingface.co/unsloth/Qwen-Image-2.1-GGUF#samplesSamples
Rendered with the Q4_K_M denoiser and the Q4_K_M text encoder, 1024x1024, 20 steps, cfg 6.0, euler.
🤖ModelScope| 🤗HuggingFace| 📑Blog| 🖥️Demo| 🫨Discord| 💬WeChat

https://huggingface.co/unsloth/Qwen-Image-2.1-GGUF#introductionIntroduction
We are excited to open-sourceQwen-Image-2.1, a unified text-to-image generation and image editing model in the Qwen family. With just7B parameters in its visual generation component(32 Single-Stream DiT layers), Qwen-Image-2.1 balances generation quality, inference efficiency, and versatility.
Four key improvements define this release:
- Compact and Efficient: a lightweight architecture with mixed-granularity attention and prefix KV cache reuse delivers strong image quality at low computational cost.
- Native Transparency, Unified Creation and Editing: generate regular or transparent (RGBA) images from text, edit transparent layers, and extract subjects from photographs, all in one model.
- Versatile Editing: support up to10 reference images, specify local edits via circles, painted annotations, or separate masks, and preserve identity for people and products.
- Realistic Textures and Refined Aesthetics: improved typography, portrait lighting, and fine details for more visually compelling results.
For more details, see theGitHub repoandBlog.
https://huggingface.co/unsloth/Qwen-Image-2.1-GGUF#quick-startQuick Start
https://huggingface.co/unsloth/Qwen-Image-2.1-GGUF#installationInstallation
pip install torch>=2.4.0
pip install transformers>=5.17
pip install git+https://github.com/huggingface/diffusers
pip install accelerate pillow
https://huggingface.co/unsloth/Qwen-Image-2.1-GGUF#text-to-imageText-to-Image
import torch
from diffusers import QwenImage21Pipeline

pipe = QwenImage21Pipeline.from_pretrained(
    "Qwen/Qwen-Image-2.1", torch_dtype=torch.bfloat16
).to("cuda")

image = pipe(
    prompt="A neon shop sign that reads \"QWEN IMAGE 2.1\", rainy night, reflections on wet pavement",
    width=2048, height=2048,
    num_inference_steps=40,
    generator=torch.Generator("cuda").manual_seed(42),
).images[0]

image.save("t2i_example.png")
https://huggingface.co/unsloth/Qwen-Image-2.1-GGUF#image-editingImage Editing
import torch
from PIL import Image
from diffusers import QwenImage21Pipeline

pipe = QwenImage21Pipeline.from_pretrained(
    "Qwen/Qwen-Image-2.1", torch_dtype=torch.bfloat16
).to("cuda")

input_image = Image.open("input.png")

image = pipe(
    prompt="Change the background to a sunset beach",
    image=input_image,
    num_inference_steps=40,
    generator=torch.Generator("cuda").manual_seed(42),
).images[0]

image.save("edit_example.png")
https://huggingface.co/unsloth/Qwen-Image-2.1-GGUF#transparent-image-generation-rgbaTransparent Image Generation (RGBA)
Use the recommended prompt format for transparent images:
image = pipe(
    prompt="This is an RGBA image with transparency. A cute cartoon dragon sticker. The image has alpha channel and the background is transparent.",
    width=2048, height=2048,
    num_inference_steps=40,
    generator=torch.Generator("cuda").manual_seed(42),
).images[0]

image.save("transparent_example.png")
https://huggingface.co/unsloth/Qwen-Image-2.1-GGUF#supported-aspect-ratiosSupported Aspect Ratios
aspect_ratios = {
    "1:1":  (2048, 2048),
    "4:3":  (2400, 1792),
    "3:4":  (1792, 2400),
    "3:2":  (2528, 1696),
    "2:3":  (1696, 2528),
    "16:9": (2752, 1536),
    "9:16": (1536, 2752),
}
https://huggingface.co/unsloth/Qwen-Image-2.1-GGUF#memory-optimizationMemory Optimization
pipe = QwenImage21Pipeline.from_pretrained(
    "Qwen/Qwen-Image-2.1", torch_dtype=torch.bfloat16
)
pipe.enable_model_cpu_offload()
https://huggingface.co/unsloth/Qwen-Image-2.1-GGUF#showcaseShowcase
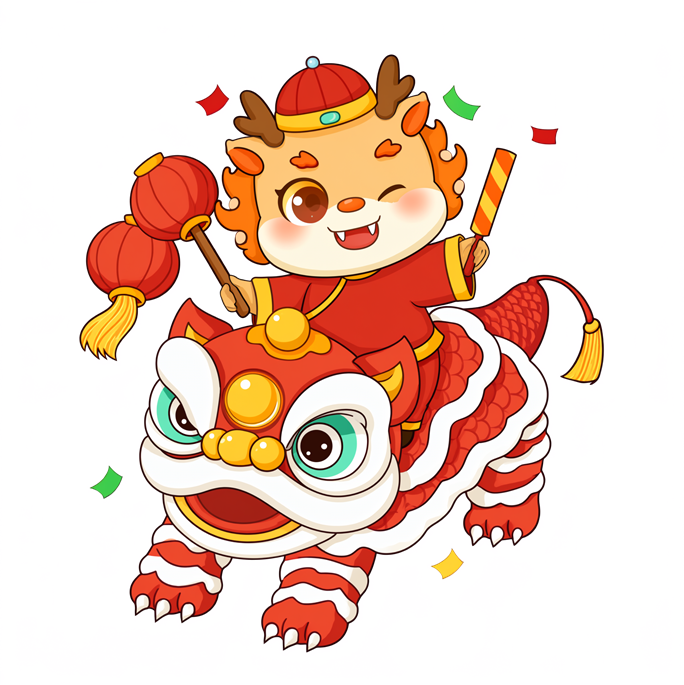
Native transparent image generation
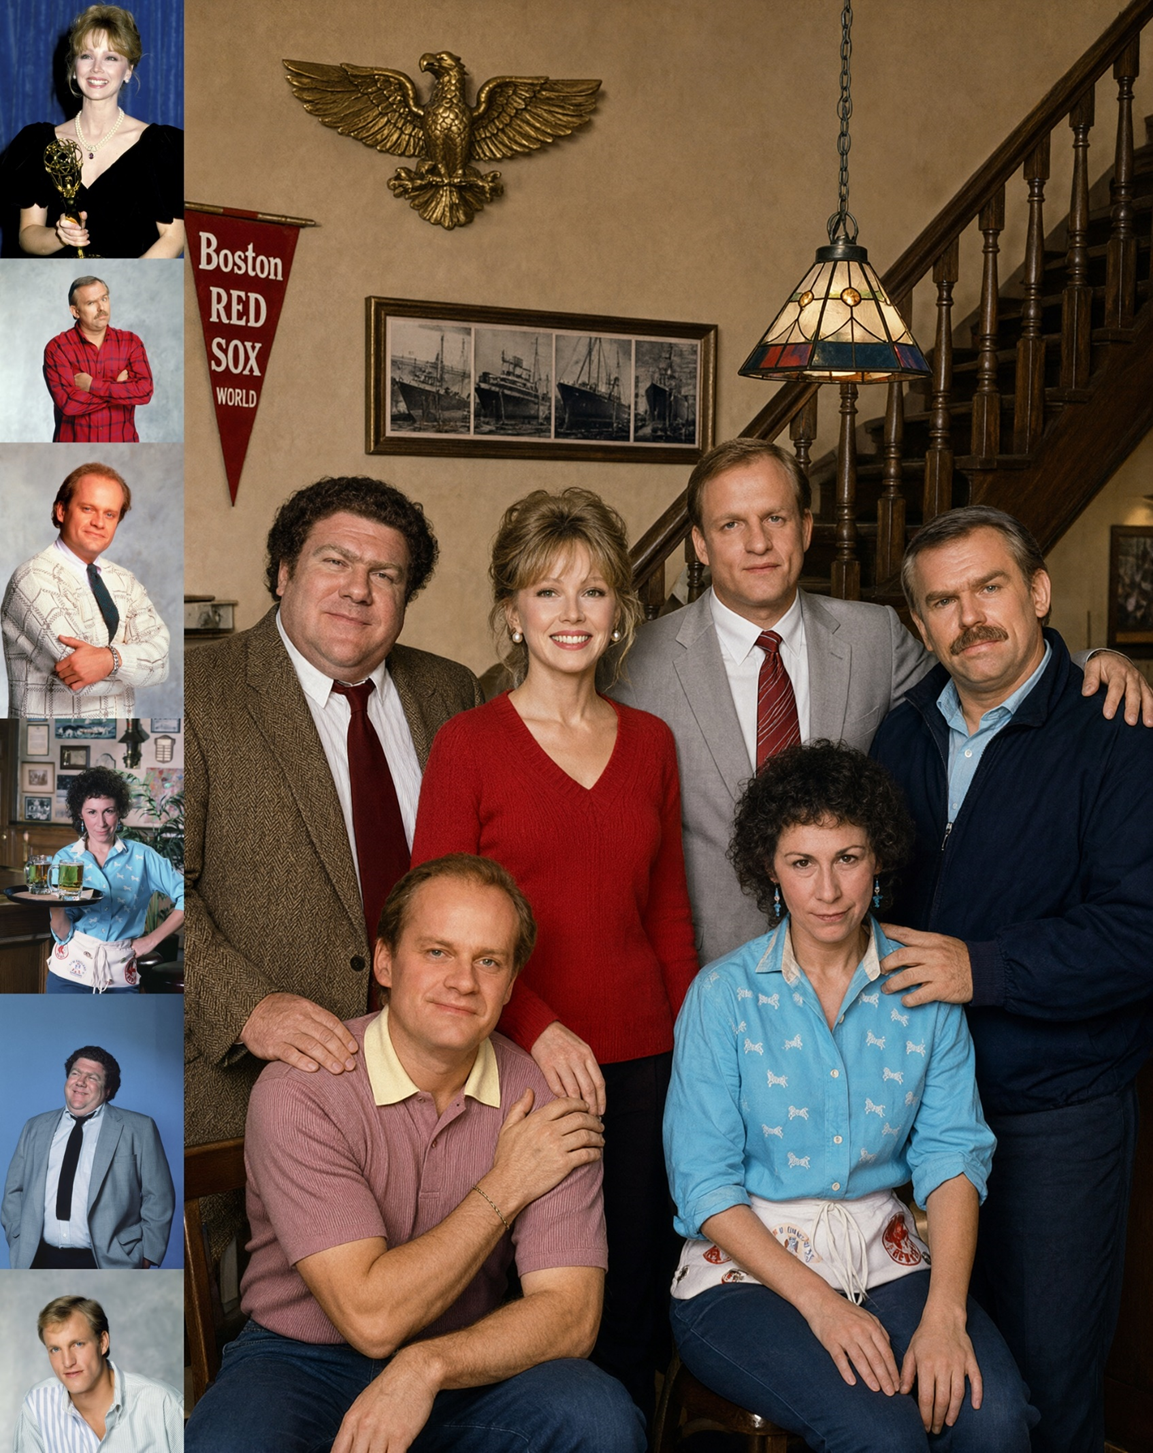
Group photograph generated from six portrait references
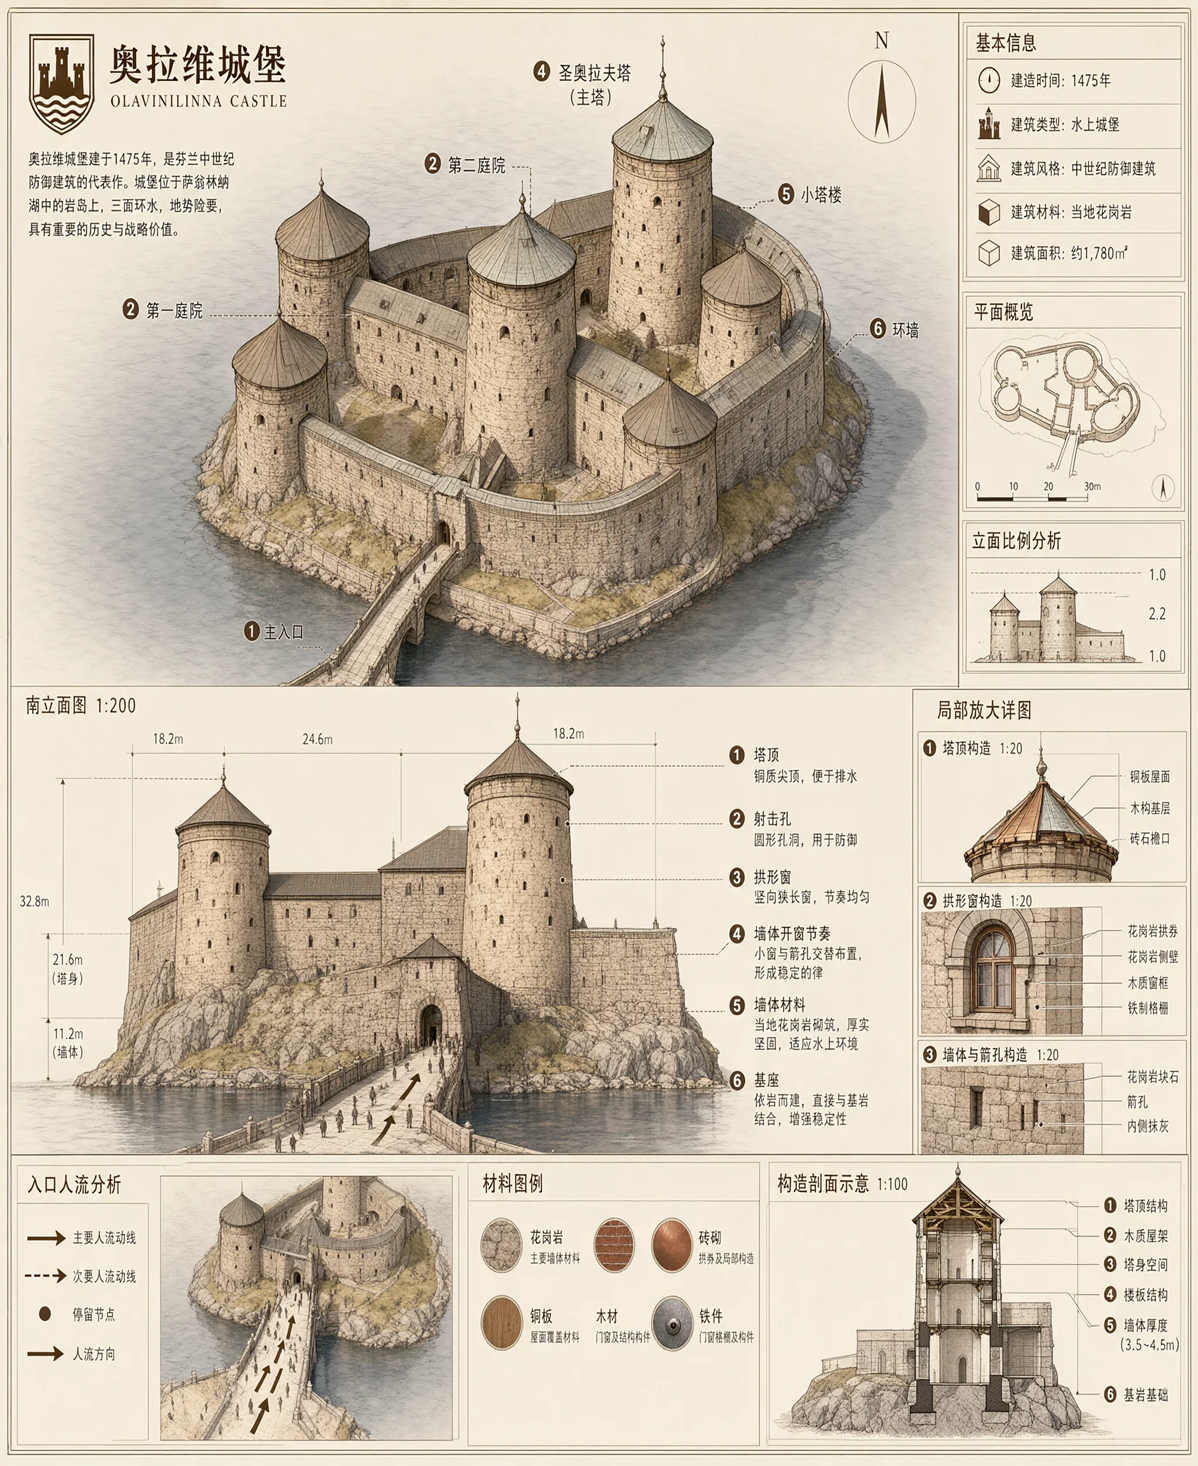
Text rendering
https://huggingface.co/unsloth/Qwen-Image-2.1-GGUF#licenseLicense
This model is licensed under theQwen Research License Agreement.
Qwen (@Alibaba_Qwen): Meet Qwen-Image-2.1, the most balanced and cost-effective image generation model in the Qwen-Image series! Now open weights! 🎨
A unified model for both generation and editing, delivering top-tier quality in a lightweight package.
Highlights: 👀
- Compact & exceptionally fast:
Similar Articles
@UnslothAI: Qwen3.8 can now be run locally! We shrank Qwen3.8-2.4T-A95B from 4.9TB to 397GB (-91% size) via Dynamic 1-bit by select…
Unsloth announces that Qwen3.8 can now run locally, shrinking the 2.4T-parameter model from 4.9TB to 397GB via Dynamic 1-bit quantization, with a guide and GGUF release.
@UnslothAI: Qwen3.8-27B is coming! Will run locally on 17GB RAM/VRAM setups.
Alibaba announces Qwen3.8-27B open-weights release, capable of running locally on 17GB RAM/VRAM, alongside the larger Qwen3.8-Max.
@Lonely__MH: All rise! The GGUF quantized version of Qwen-Image-2.1 is here! Thanks to the @UnslothAI team for stepping in! Based on…
The GGUF quantized version of the Qwen-Image-2.1 AI model is released, featuring Dynamic 2.0 technology for efficient 4-bit quantization, supporting text-to-image and transparent image generation in a 4.2GB size suitable for Mac users.
unsloth/Qwen-Image-2.1-GGUF
Qwen-Image-2.1 is a unified text-to-image generation and image editing model with 7B parameters, featuring improvements in efficiency, transparency, versatility, and realism. This GGUF quantized version from unsloth enables efficient local inference.
@cyrilXBT: UNREAL. Qwen 3.8 27B is now happily running on an RTX 4060 locally with only 8GB of VRAM. You’re looking at a 64k conte…
A user shares that the Qwen 3.8 27B model runs locally on an RTX 4060 with only 8GB VRAM using Unsloth's IQ4_XS quantization, achieving a 64k context window and impressive performance metrics.