@vanstriendaniel: The real tokenmaxxing move: use frontier agents to build small classifiers for large-scale data curation. Small classif…
Summary
Using frontier agents to build small classifiers for data curation can reduce costs significantly compared to LLM labeling, as demonstrated in a case study on the FinePDFs-Edu dataset.
View Cached Full Text
Cached at: 09/12/26, 04:59 PM
The real tokenmaxxing move: use frontier agents to build small classifiers for large-scale data curation.
Small classifiers already help curate the data used to train LLMs. I wanted to see how far an agent could take me in building one.
I used Astra, SetFit and @huggingface Jobs to turn 200 agent-labelled examples into a reusable document-purpose classifier, reviewing the categories and tricky cases along the way.
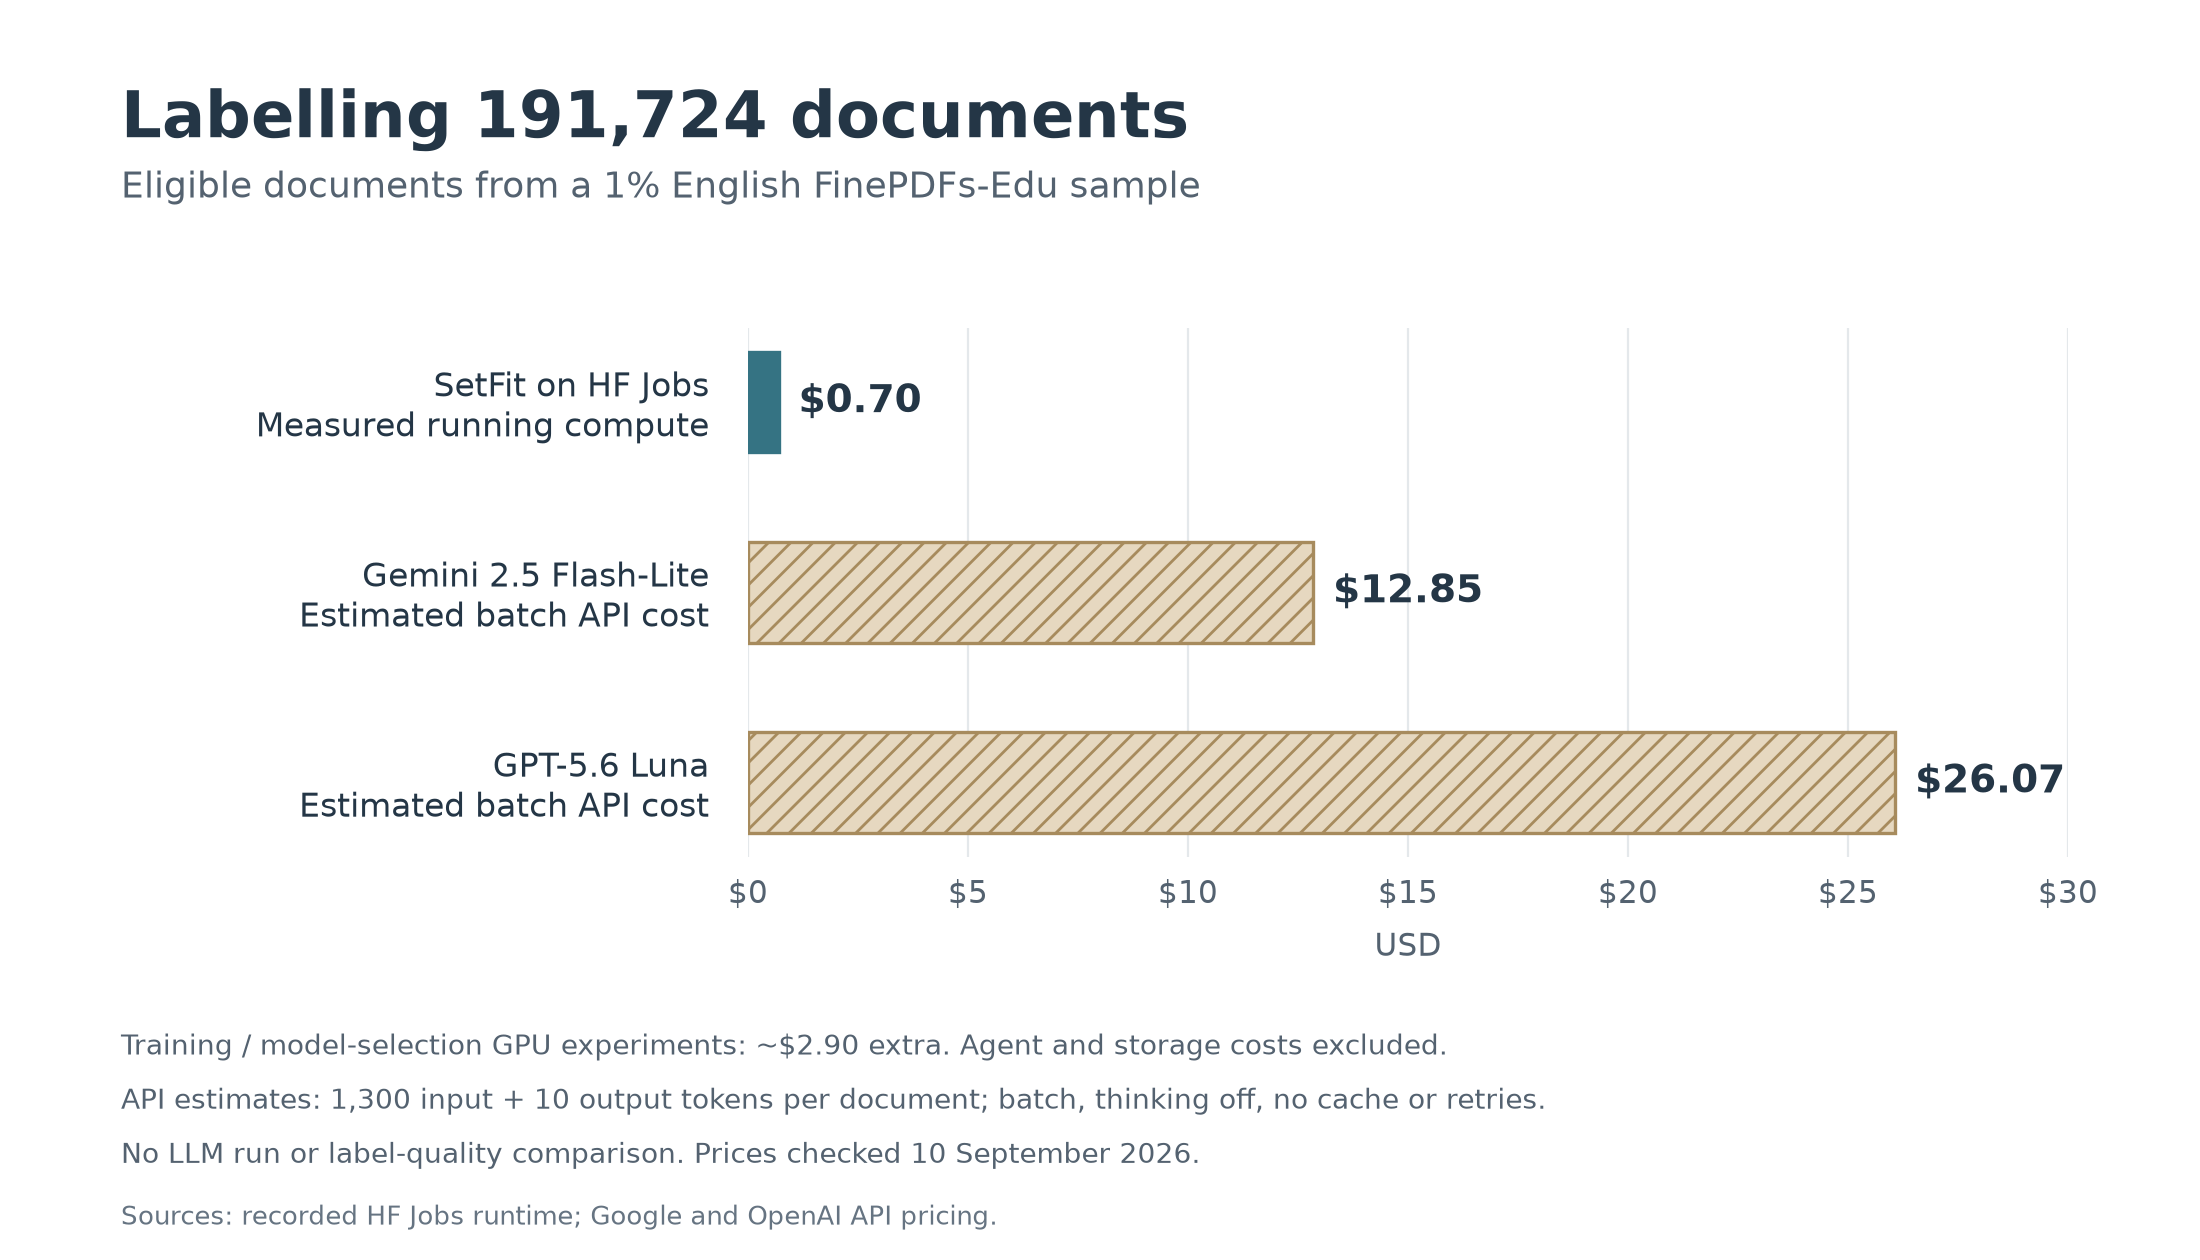
It classified 191,724 FinePDFs-Edu documents for ~$0.70 in inference compute, versus an estimated $13–26 to label the same document excerpts with low-cost batch LLMs.
Training experiments added ~$2.90 in compute.
Workflow, mistakes, reusable model and a prompt to try on your own data: https://danielvanstrien.xyz/posts/2026/agents-data-curation/index.html…
Building data curation classifiers with agents, SetFit and Jobs – Daniel van Strien
Source: https://danielvanstrien.xyz/posts/2026/agents-data-curation/index.html
Card index,Encyclopædia Britannica(1929).Source. FinePDFs-Educontains text extracted from PDFs and filtered for educational value. It’s a subset ofFinePDFs, a dataset built from PDFs collected byCommon Crawl. It includes a wide variety of material, from worksheets and reference guides to research papers.
Depending on what we want to train, we might want different mixtures of these documents: material for pretraining, sources for generating supervised fine-tuning examples, or documents for training a retriever. How could we add metadata that makes those choices easier?
Document purpose seemed like one useful dimension. An LLM is a useful starting point for labelling a few examples, especially while the categories are still changing. For a small batch, that may be all we need. At around 23 million English documents, though, repeatedly processing each document and rubric with an LLM adds up.
Training a small classifier gives us a reusable model: we can save and version it, share it, and apply the same classification scheme to new batches. The initial labelling and training work can be spread over many runs. FinePDFs-Edu itself used classifiers trained on LLM-generated annotations for its educational filtering; we could add another dimension using a similar approach.
I wanted to see how far I could get by asking a coding agent to help build one: explore the data, propose categories, create training examples, and train and test a model usingHugging Face Jobs.
The workflow involved several rounds of reviewing documents, refining the labels and checking models before running the classifier on a larger sample:
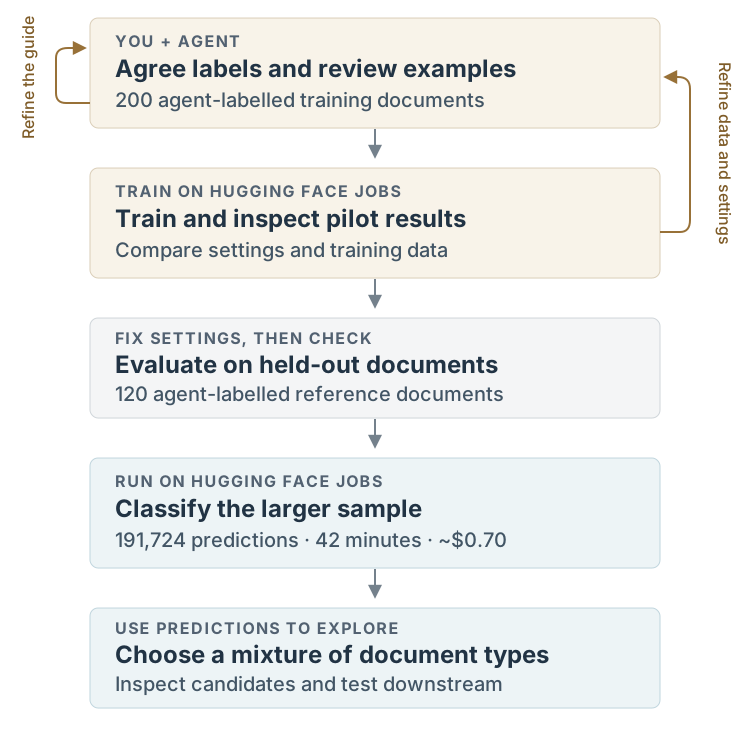
Figure 1: Human review and pilot experiments feed back into the labels and training before the final evaluation and larger run.
What should the labels describe?
After exploring samples with the agent and looking through documents myself, we settled on six categories describing document purpose: instruction/reference, exercise/assessment, administration/policy, research/analysis, news/promotion, and other. A school worksheet and a school policy can be about the same subject while serving different purposes.
The agent sampled documents, proposed a labelling guide and labelled examples. I reviewed the categories and tricky cases before we expanded the training set to200 agent-labelled documents. Deciding what belonged in each category took several rounds of discussion.
Building and checking the classifier
We usedSetFit, a library for training text classifiers from small labelled datasets, with a149-million-parameter ModernBERT encoder. The agent wrote the scripts and ran training and comparisons on Jobs. Long documents were represented by excerpts from their beginning, middle and end. Thetrained classifier and prediction helperare available on the Hub.
We compared classifier settings and training-data choices, including whether fine-tuning helped over using the original embeddings. We also repeated training with three random seeds to check how much the results varied.
On 120 held-out, agent-labelled documents, the model we used for the larger run reached65.8% accuracy and 0.556 macro F1. Those labels followed the reviewed guide; they aren’t independent human ground truth.
The breakdown is useful for deciding how to sample. Precision measures how often a prediction matches the reference label; recall measures how many reference examples of a category the model finds.
PurposeReference examplesPrecisionRecallAdministration/policy2469%75%Exercise/assessment1974%74%Instruction/reference4173%54%News/promotion2055%85%Research/analysis1357%62%Other3—0% The model correctly identified a phonics worksheet as exercise/assessment, but classified a handout explaining French grammatical gender as administration/policy. It made no “other” predictions in this evaluation.
Instruction/reference predictions could help find candidates, but the 54% recall means filtering exclusively on that label would miss many examples. I’d retain random samples for coverage and review documents before relying on a category.
We could do another development round: ask an agent or LLM to review fresh predictions alongside random documents, flag disagreements for me to check, and use corrected examples to refine the guide and retrain. A revised model would need a fresh held-out evaluation. This would be a possible next step, not a result of the current experiment.
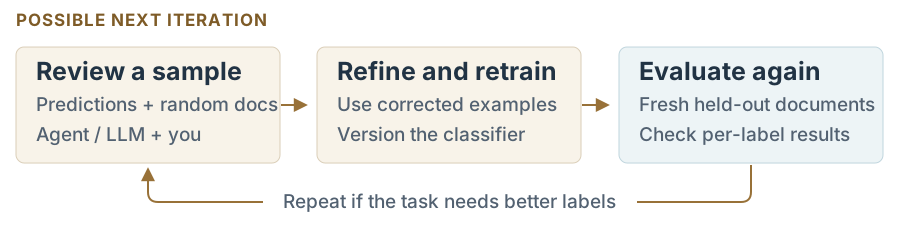
Figure 2: A possible next round: review fresh examples, refine the classifier, then evaluate again.
Running it on a larger sample
The agent then wrote an inference script to read source Parquet with DuckDB, prepare excerpts, classify batches and save predictions as Parquet. Jobs ran the script and installed its declared Python dependencies. The core of the Python submission looked like this:
job = api.run_uv_job(
    script="classify.py",
    flavor="a10g-small",
    timeout="2h",
    python="3.12",
    secrets={"HF_TOKEN": token},
    env=run_environment,
)
Here,run\_environmentincludes the pinned input revision and runtime settings. Thecomplete inference scriptalso handles saving progress and checking inputs.
We sampled230,234 source rows: 1% of the English subset. After language and text checks,191,724 received predictions; excluded rows were retained with reasons. This sampled row groups across all 100 English files, so it is a clustered sample.
The Job took42 minutes, costing approximately**0\.70**in running compute\. Training and model\-selection GPU experiments added about**2.90**; agent costs and storage aren’t included.
For comparison, labelling the same excerpts with low-cost batch LLM APIs would cost an estimated**13–26**\. Scaling to the**full English FinePDFs\-Edu subset**projects to roughly**70 for classifier inference versus $1,300–2,600 for those APIs**.1We haven’t compared their label quality. Extending to other languages would require additional model and evaluation work.
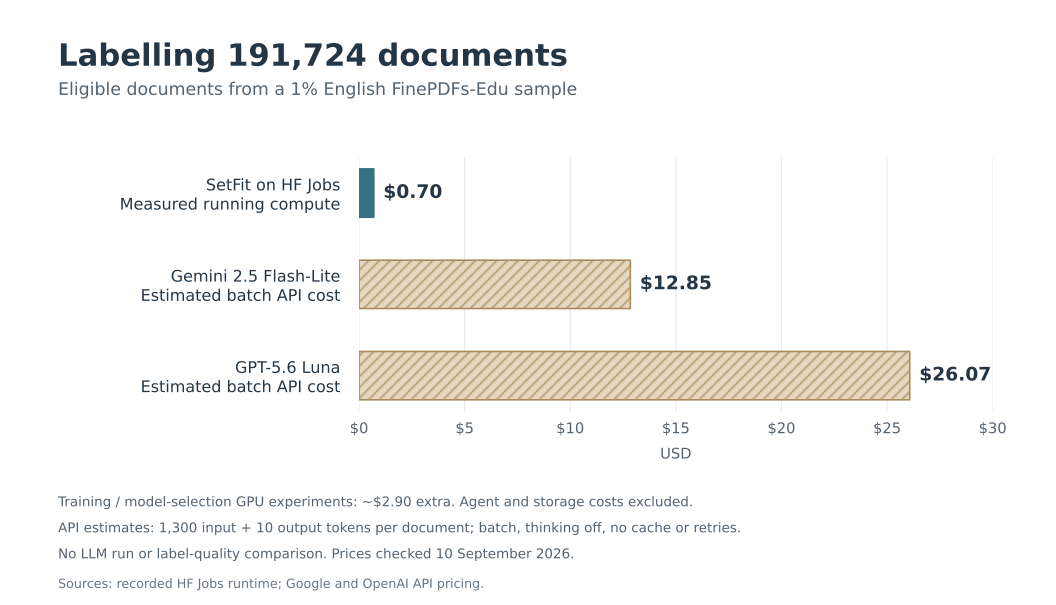
Figure 3: The Jobs bar is based on measured runtime; the two API bars are budget estimates for the same document excerpts. Download the chart as PNG·SVG
What would I use this for?
Theresulting datasetjoins the predictions back to source text. I could use it to build retrieval-training candidates with different proportions of exercises, reference material and research.
Purpose could also be combined with separately developed topic or reading-level labels to find, for example, introductory science explanations. Each additional classifier would have its own compute and validation costs, but the resulting columns would give us more ways to select data for experiments.
Document purpose doesn’t establish quality or relevance, and I haven’t tested downstream gains. This is a proof of concept for having an agent help turn a curation idea into a cheap, reusable classifier.
For a starting point with your own labelled data, theSetFit Jobs recipeincludes a reusableUV training script. You can give the recipe to your agent along with this prompt. Use the copy button to copy the whole prompt:
Help me build a small classifier for curating this dataset: [dataset URL].

First ask what I want to use the data for, then explore a sample and propose useful categories. Show me examples and ambiguous cases so we can refine the guide together.

Use hf jobs --help to explore the compute options. Consider the SetFit UV recipe as a starting point:
https://huggingface.co/datasets/uv-scripts/classification/blob/main/train-setfit.py

Propose a compute budget, train and evaluate a baseline, and show me its per-category results and mistakes before we decide whether to refine it or scale it. Save the trained model and preprocessing details so we can reuse them.
Footnotes
- Estimates dated 10 September 2026: Gemini 2.5 Flash-Lite and GPT-5.6 Luna batch prices fromGoogleandOpenAI. Assumes 1,300 input tokens per eligible document, including the rubric, and 10 output tokens; thinking disabled, no caching or retries. These are budget estimates, not measured API runs. Full-English projections assume the same eligibility rate, document lengths and throughput; training is a separate cost.↩︎
Similar Articles
Frontier LLM-based agents can overcome the ontology curation bottleneck for natural phenotypes
This paper demonstrates that frontier LLM-based agents, when provided with source publications, annotation guides, and ontologies, can perform phenotype annotation at a level comparable to trained human curators, substantially outperforming previous NLP tools and overcoming a key bottleneck in comparative morphological data integration.
@dzhulgakov: Jev is all the hype: people didn’t realize that many classification tasks don’t need frontier LLM What you may also not…
The blog post describes a practical method for fine-tuning large language models as calibrated classifiers using token probabilities, enabling cost-effective classification tasks with minimal compute resources.
@MaximeRivest: this was essentially me looking for ways to have a jev at home before they made it.
The author shares their past efforts to achieve efficient single-expert loading for high-quality token-level classification at scale, echoing Maxime Rivest's thoughts on the utility of domain-specific expert models.
@dlwh: Frontier AI models are built from thousands of small decisions: data sourcing, filtering, mixtures, curricula, scaling …
Frontier AI models are built from thousands of small decisions, emphasizing the importance of process knowledge in their development.
Token maxxing
Discusses strategies and techniques for maximizing token usage in large language models to improve efficiency and output quality.