Model-Based Online Decision Making via Generative Trajectory Planning
Summary
论文提出 Generative Trajectory Planning (GTP),一种基于学习到的扩散先验对动作序列进行采样与束搜索精炼的模型在线决策框架,在 MuJoCo 运动与长时程操作任务上超越基线,并开源代码与模型。
View Cached Full Text
Cached at: 10/15/26, 02:57 AM
Paper page - Model-Based Online Decision Making via Generative Trajectory Planning
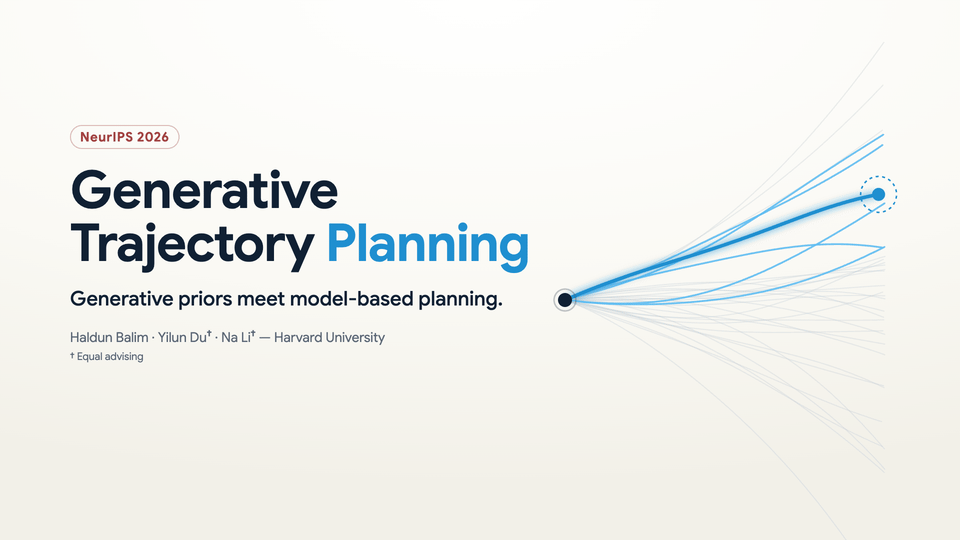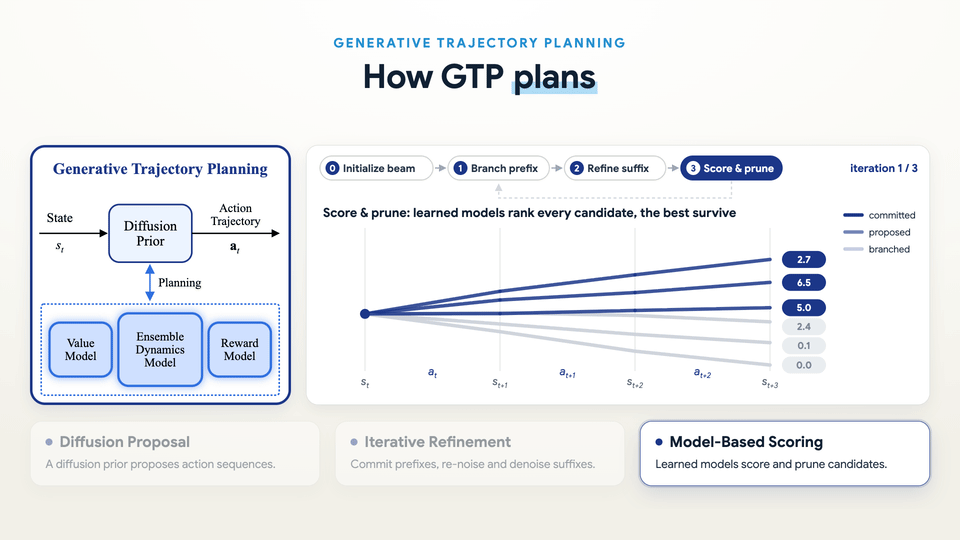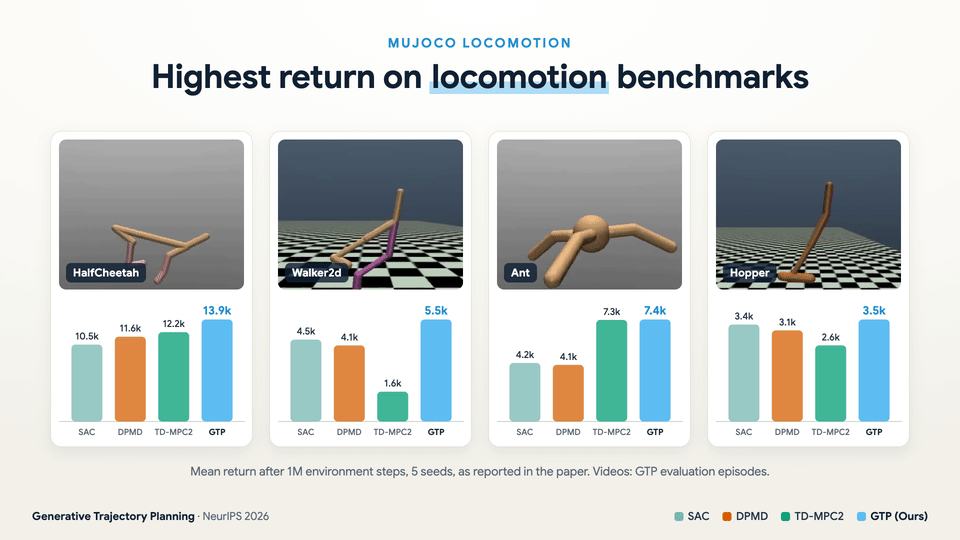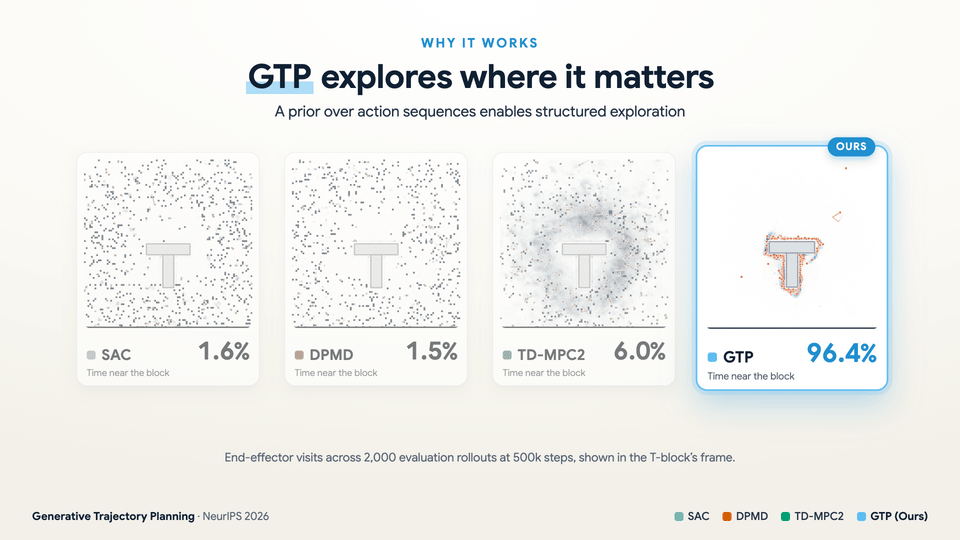
Source: https://huggingface.co/papers/2610.18677 🧭 IntroducingGenerative Trajectory Planning (GTP), a model-based framework for online decision making that plans with alearned diffusion prior over action sequences.
Instead of optimizing action sequences from scratch at every step, GTP samples candidate sequences from the diffusion prior, refines them with beam search, and scores them with learned dynamics, reward and value models, alllearned online from scratchin a self-improving loop.
- 🏃**Locomotion:**highest return on all five MuJoCo tasks against model-free, diffusion-policy and model-based baselines
- 🦾**Long-horizon manipulation:**GTP solves PushT from pixels, where every baseline fails, and matches or beats every baseline on the Fetch tasks.
- 🔍**Structured exploration:**the prior over action sequences steers exploration toward the states that matter for the task, instead of scattering the agent’s visits across the state space.
- 🔭**Long-horizon training:**by reasoning over whole action sequences, GTP keeps training stably on long-horizon tasks where policy-centric methods, limited by short-horizon bootstrapping, break down.
Code and trained models for every environment are available!
🌐Project page· 💻Code· 🤗Models
We welcome your questions and feedback!
Similar Articles
Looking Ahead and Back: Anticipatory Generative Modeling for Road-Network Trajectories
论文提出一种面向路网轨迹生成的图约束生成范式 Anticipatory Generative Modeling,并提出模型 Foresight,通过"anticipate–select–update–re-anticipate"循环解决路口转移选择问题,超越扩散模型等基线方法。
TrajGenAgent: A Hierarchical LLM Agent for Human Mobility Trajectory Generation
TrajGenAgent proposes a hierarchical LLM agent framework that decouples macro-level activity planning from micro-level spatiotemporal instantiation for realistic human mobility trajectory generation without fine-tuning. It also introduces an anomaly-detection-based evaluation for behavioral fidelity.
Anticipatory Commonsense with Moving Objects: An ASP-Based Framework for Predictive Reasoning with Interacting Trajectories
该论文提出一个基于回答集编程(ASP)的混合声明式框架,用于对交互式运动轨迹进行可解释的前瞻性推理,并在Argoverse 2基准上进行评估,每个预测轨迹都附带可检查的事件级假设。
Plan online, learn offline: Efficient learning and exploration via model-based control
OpenAI proposes POLO (Plan Online, Learn Offline), a framework combining model-based control with value function learning and coordinated exploration to enable efficient learning on complex control tasks like humanoid locomotion and dexterous manipulation with minimal real-world experience.
Active Timepoint Selection for Learning Measure-Valued Trajectories
This paper introduces a framework for active timepoint selection to infer probability paths from sparse snapshots, using linearized optimal transport to map distributions into a tangent space for Gaussian Process modeling, thereby enabling uncertainty-aware acquisition policies.