You can just merge Qwen3.6 & 3.8 27B to get decent performance with much fewer token generation
Summary
JetBrains has created an unofficial derivative by merging Qwen3.6 and Qwen3.8 27B models to achieve decent performance with fewer token generations, optimized for coding tasks.
View Cached Full Text
Cached at: 09/28/26, 01:57 PM
JetBrains/Qwen3.8-3.6-27B-blend · Hugging Face
Source: https://huggingface.co/JetBrains/Qwen3.8-3.6-27B-blend **Unofficial JetBrains derivative.**This model was prepared by JetBrains using Qwen models developed by Alibaba Cloud. This release is not affiliated with, sponsored by, or endorsed by Alibaba Cloud or Alibaba Group.
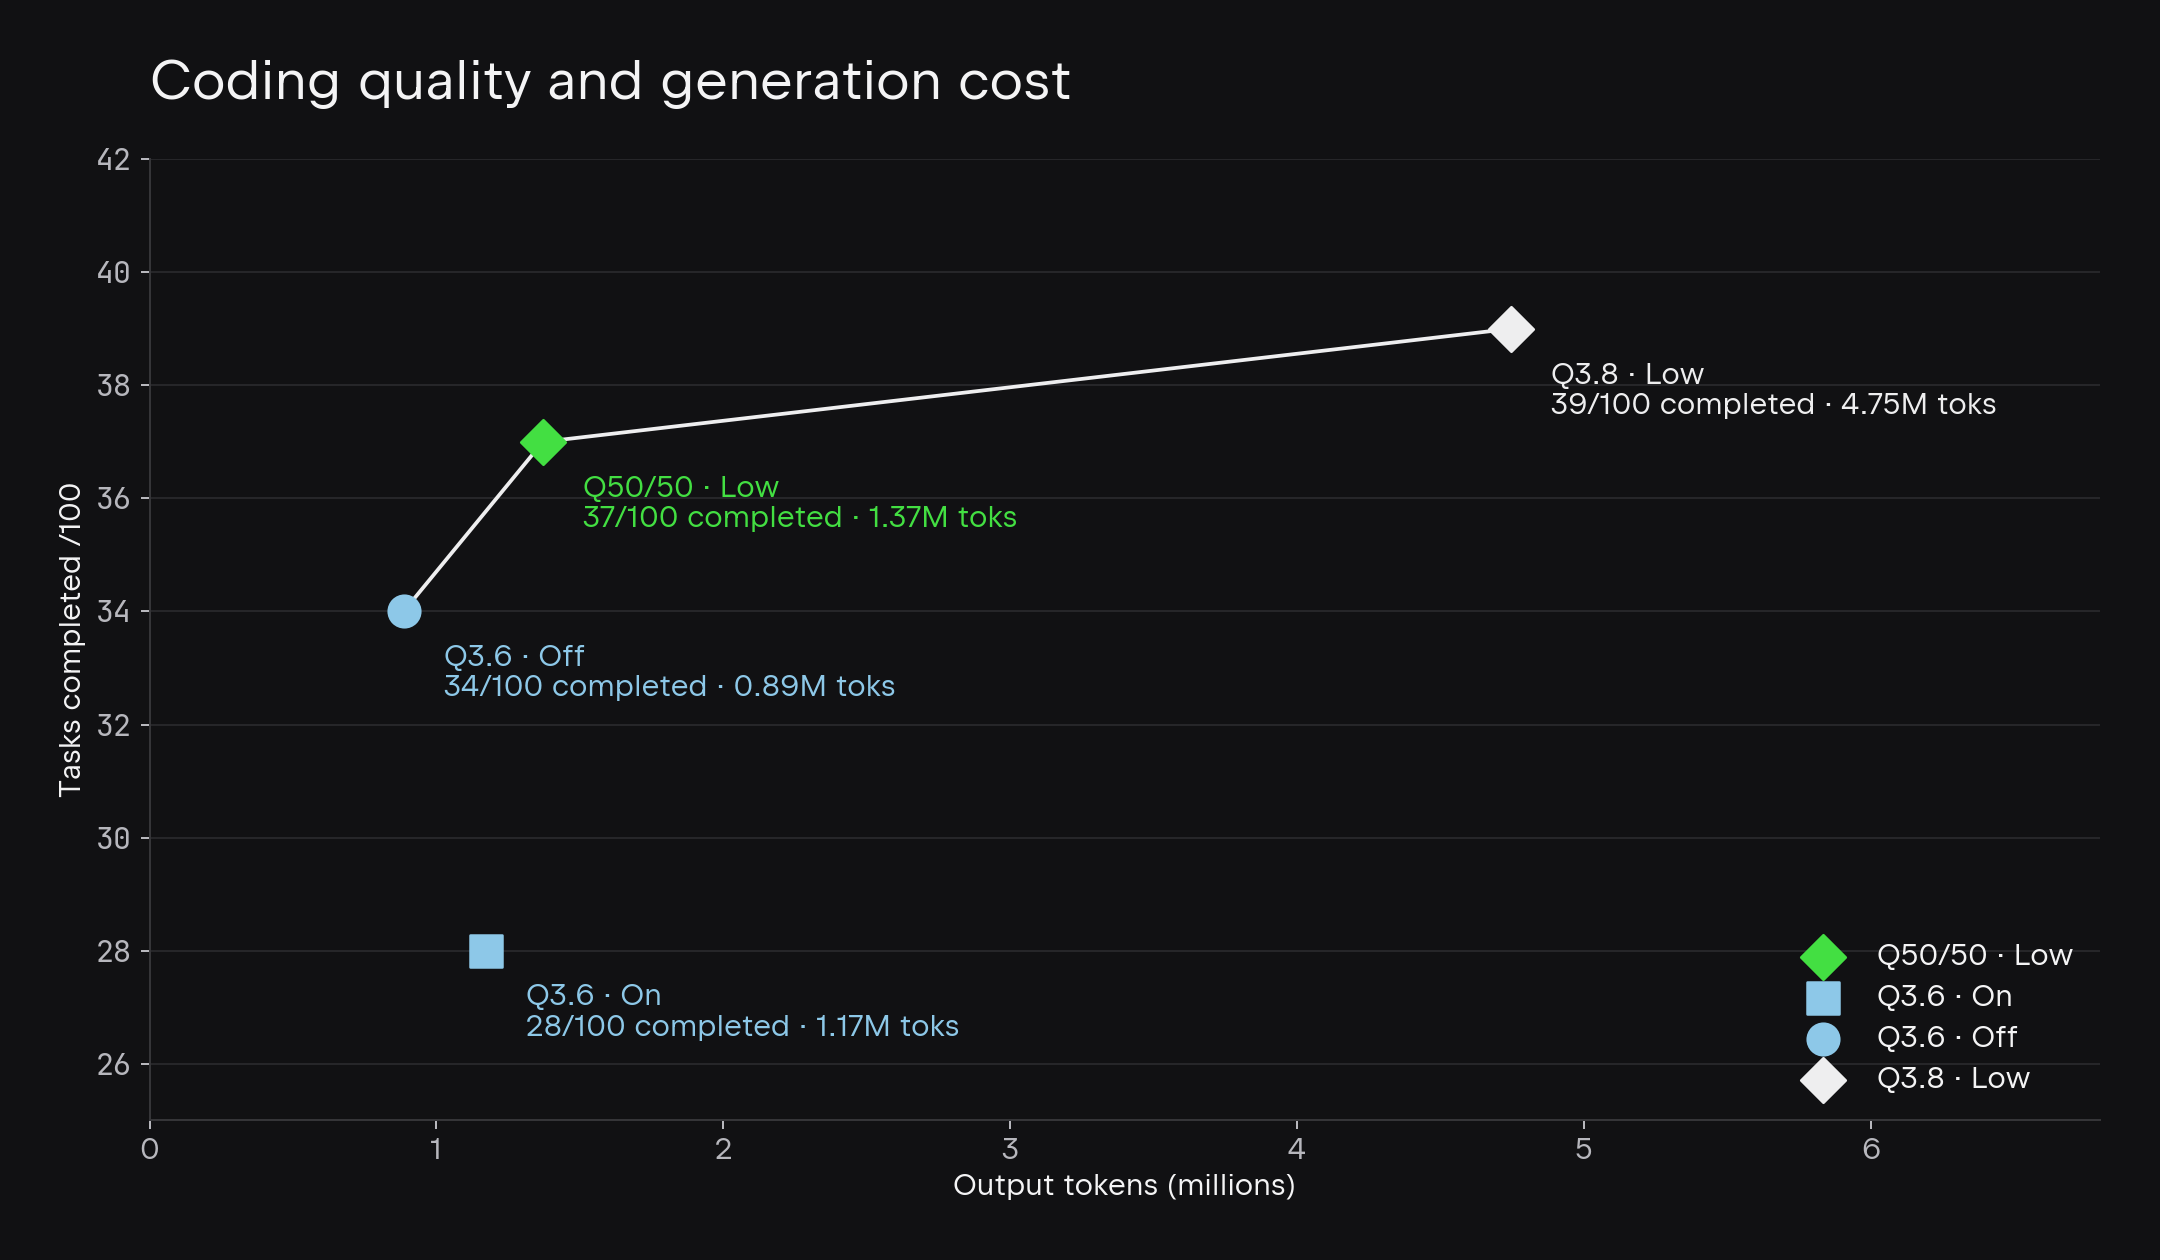
Tasks completed versus output tokens on JetBrains’ 100-task internal coding benchmark. Reasoning settings differ between configurations; see the article for methodology and context.
ReadMaking Local AI Smarter and Fasterfor the Junie Local release story, coding evaluations, token-efficiency results, and MTP runtime experiments.
Available formats:BF16·GGUF·MLX 4-bit·MTP MLX 4-bit.
This model is a 50/50 combination of Qwen3.6-27B and Qwen3.8-27B, created by linearly interpolating their checkpoint parameters. The configuration, tokenizer, processor, and chat template are retained from Qwen3.8-27B. Exact source revisions and merge settings are recorded inmerge-manifest.json.
The interpolation uses float32 accumulation.
0.5 * Qwen/Qwen3.6-27B + 0.5 * Qwen/Qwen3.8-27B
Qwen/Qwen3\.6\-27Brevision6a9e13bd6fc8f0983b9b99948120bc37f49c13e9Qwen/Qwen3\.8\-27Brevision1d4bf0f2ff6012fd82039f2fa52739d0dd7c60c0
https://huggingface.co/JetBrains/Qwen3.8-3.6-27B-blend#license-and-attributionLicense and attribution
Distributed under the Apache License, Version 2.0. The original QwenLICENSE, includingCopyright 2026 Alibaba Cloud, is retained unchanged.
Copyright © 2026 JetBrains s.r.o. This notice applies only to original material contributed by JetBrains. Upstream Qwen material remains subject to its original copyright and attribution notices.
SeeNOTICEfor attribution andCHANGES.mdfor a description of the modifications and the affected files.
https://huggingface.co/JetBrains/Qwen3.8-3.6-27B-blend#note-on-acceptable-useNote on acceptable use
This model is distributed under the Apache License, Version 2.0. This notice does not modify the License. Users are reminded that using this model, or its outputs, to infringe the copyright or other intellectual property rights of third parties may violate applicable law, independent of the terms of this License.
https://huggingface.co/JetBrains/Qwen3.8-3.6-27B-blend#training-and-upstream-informationTraining and upstream information
No additional training or fine-tuning was performed, and no additional training data was used to create this derivative; its preparation consisted of the checkpoint merge and, where applicable, the extraction, format conversion, and quantization described above and inCHANGES.md.
For upstream information, see the officialQwen3.6-27B model cardandQwen3.8-27B model card. Qwen also publishes aTraining Data Summary, which describes training data for models powering qwen.ai generally; it does not identify the exact training datasets for these two checkpoints.
Similar Articles
Qwen 3.8 27B is faster than expected
A user reports that the Qwen 3.8 27B model achieves 50-60 tokens per second on dual 5060 TI cards, showing unexpected speed improvements over previous versions like Qwen 3.6.
Qwen 3.8 27b is strong even at Q3_xxs
The user finds Qwen 3.8 27b in Q3 quantization highly effective for coding tasks with fast inference speeds, outperforming previous models, despite minor issues in general conversations.
Qwen3.8-27B: slower tokens, faster and better results
Qwen3.8-27B is a new AI model that emphasizes wall-clock time over token speed, offering superior intelligence for local deployment on consumer hardware with 32 GB VRAM.
I tested Qwen3.8 27B IQ3_XXS (10.18GiB) vs Bonsai Ternary PQ2 (6.42GiB)
The author compared the performance of Qwen3.8 27B IQ3_XXS and Bonsai Ternary PQ2 on limited VRAM, finding that Qwen is faster and uses fewer tokens, while Bonsai has a smaller file size but longer generation times.
For those with 12GB GPUs, you can now run QWEN 3.6 27B wth little loss via the new Ternary version.
A new ternary quantized version of Qwen3.6 27B, called Bonsai 27B, allows running the model on 12GB GPUs with 10x less memory and 95% of original performance, making it accessible for local deployment.