@PyTorch: Over the last two years, @Meta has consolidated PyTorch's media stack across three libraries: TorchCodec, TorchVision, …
Summary
Meta has consolidated PyTorch's media processing stack over two years, making TorchCodec the single home for CPU and CUDA decoding/encoding of images, video, and audio, while TorchVision and TorchAudio now focus strictly on high-performance media transforms.
View Cached Full Text
Cached at: 10/06/26, 01:34 AM
Over the last two years, @Meta has consolidated PyTorch’s media stack across three libraries: TorchCodec, TorchVision, and TorchAudio.
TorchCodec serves as the single home for CPU and CUDA media decoding and encoding across images, video, and audio. TorchVision and TorchAudio now focus strictly on high performance media transforms.
Read the full technical debrief to learn more about what has changed and why: https://bit.ly/3VMBwzN
Evolution of the PyTorch Media Processing Landscape – PyTorch
Source: https://pytorch.org/blog/evolution-of-the-pytorch-media-processing-landscape/
Featured projects
TL;DR
If you need todecode or encodemedia, whether it’s images, video, or audio, useTorchCodec. If you need totransformmedia, useTorchVisionfor images and video, andTorchAudiofor audio. Everything else that used to live in these libraries (models, datasets, etc.) is better served today by the wider ecosystem, for example the HuggingFace libraries.
Images, video and audio are now central to a lot of model development, from vision-language models to diffusion models that generate images and video. Training these models means decoding media into tensors and transforming them, and generative models then need to encode their outputs back into media files. Over the last two years we have consolidated PyTorch’s media stack across three libraries:TorchCodec,TorchVision, andTorchAudio. This post describes where things landed, and why.
Before and now
TorchCodec: the one place for decoding and encoding
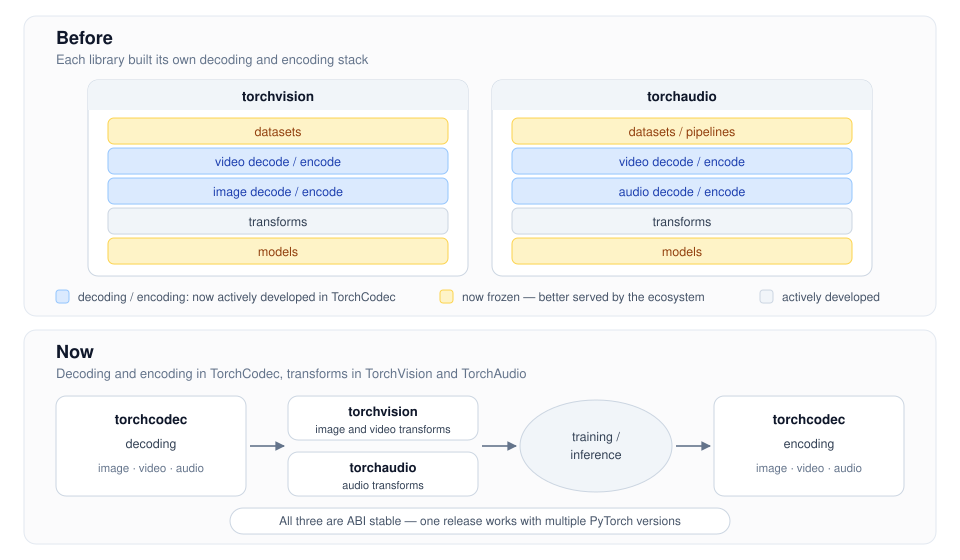
A few years ago, media decoding and encoding capabilities were scattered and partially duplicated across TorchVision and TorchAudio, with each one building its own stack. TorchVision had multiple entry points (io\.read\_video\(\)andio\.VideoReader\(\)), spread across three backends: PyAV in Python, a C++ FFmpeg backend, and a CUDA/NVCUVID backend. Only the PyAV backend was available out-of-the-box, as the two other backends required building from source, and were tied to a specific FFmpeg version. TorchAudio hadStreamReaderandStreamWriterfor video and audio, and additional audio decoding utils with various backends (FFmpeg,libsoundfile,libsox). Image decoding lived in TorchVision.
In response to this, we have consolidated all decoding and encoding capabilities for media to live in TorchCodec: images, video, and audio, on CPU and CUDA. The APIs that used to live in TorchVision or TorchAudio are deprecated, or removed. We did this for three reasons:
**One centralized location for users.**With all media I/O in TorchCodec, users no longer have to work out which library happens to offer the decoder they need, and they get a library designed as a whole rather than a set of independent APIs.
**Performance optimizations.**A single centralized place also means that our development effort goes into one library, instead of being spread across many. When decoding and encoding lived in several implementations, it was never obvious which one deserved the optimization work. Now it is, and anything we make faster in TorchCodec makes everyone faster. TorchCodec is generally more performant than the previous implementations we had in TorchVision and TorchAudio, particularly for CUDA video decoding.
**Maintenance and dependencies.**Media I/O involves a lot of dependencies: six major FFmpeg versions (4 through 9 at the time of writing), NVIDIA’s codec SDK for GPU decoding, and one library per image format (libjpeg,libpng, etc.), each with its own licensing rules about what we can ship. On top of that, none of them are pure Python dependencies: they’re all C/C++ libraries, which makes the build, the CI, and the releases much harder. All of this complexity is now contained to TorchCodec, which greatly simplifies the maintenance burden for both TorchVision and TorchAudio.
TorchVision and TorchAudio: now focused on transforming media
TorchVision and TorchAudio supported a broad product surface, ranging across models, datasets, pipelines, transforms, and the I/O above. Today, both libraries are focused around what they do best: their transforms. The rest is not under active development.
The driving factor here was the observation that the transforms in TorchVision and TorchAudio are the most active usage areas in the community. In contrast, models, datasets, and pipelines have lagged in usage, as great alternatives have risen, such as the HuggingFace libraries. Narrowing the scope of TorchAudio and TorchVision allows us to double-down on their strengths, and on the pieces that are not covered by other parts of the ecosystem.
This transition was particularly disruptive for TorchAudio: a lot of APIs were deprecated and eventually removed. We appreciate the community’s patience and feedback, which allowed us to reconsider our initial plan. Several popular APIs we had originally slated for removalwere kept. This migration was difficult, but we believe it was worth it. A smaller TorchAudio is one that can actually be maintained, so it’s one users can continue to rely on.
How they fit together
In practice the split is simple: TorchCodec turns media files or encoded bytes into tensors (decoding), and tensors back into media files (encoding). TorchVision and TorchAudio transform the tensors in between.
For video, with TorchCodec’sVideoDecoderand TorchVision’sv2 transforms:
import torch
from torchcodec.decoders import VideoDecoder
from torchvision.transforms import v2

clip = VideoDecoder("video.mp4")[10:20]   # FrameBatch, uint8, (10, C, H, W)

transform = v2.Compose([
    v2.RandomResizedCrop(224),
    v2.ToDtype(torch.float32, scale=True),
])
batch = transform(clip.data)
For audio, with TorchCodec’sAudioDecoderand TorchAudio’stransforms:
from torchcodec.decoders import AudioDecoder
from torchaudio.transforms import MelSpectrogram

samples = AudioDecoder("audio.mp3").get_all_samples()   # AudioSamples

mel = MelSpectrogram(sample_rate=samples.sample_rate)(samples.data)
Images work the same way:decode\_imageand friends return plain tensors that go straight intotorchvision\.transforms\.v2. Encoding goes in the other direction, withVideoEncoder,AudioEncoder,JpegEncoderandPngEncoder.
In terms of releases, all three libraries are nowABI stable. This means that a given version of TorchCodec, TorchVision or TorchAudio isn’t tied to one single version of PyTorch anymore: it keeps working with the PyTorch versions that come after it. They no longer need to be rebuilt for every PyTorch release, so their release cadence no longer matches PyTorch’s. That’s expected!
If you’re still using the decoding or encoding APIs in TorchVision or TorchAudio, now is a good time to move to TorchCodec: start with ourmigration guide, and let us know onGitHubif something you need is missing.
There is a lot more to say about the media processing libraries, and we’ll do it in a follow-up post: what’s new in each library, and how to get the most performance out of a full decoding and transform pipeline. Stay tuned!
Similar Articles
TorchCodec 0.14: HDR Video Decoding for CPU and CUDA, and Fast Wav Decoder
TorchCodec 0.14 adds HDR video decoding for CPU and CUDA, along with a fast WAV decoder, enabling efficient conversion of video and audio data into PyTorch tensors for ML workflows.
@PyTorch: PyTorch releases are no longer just about shipping PyTorch binaries. Release engineering now coordinates PyTorch, Trito…
The article announces PyTorch Conference North America 2026, where Andrey Talman from Meta will discuss modernizing the PyTorch release process, including coordination with Triton and vllm, and the use of AI agentic workflows.
@PyTorch: The PyTorch Foundation continues to grow as a multi-project home dedicated to supporting collaboration across every sta…
The PyTorch Foundation announces a new quarterly blog series where its hosted projects (PyTorch, vLLM, DeepSpeed, Ray, Helion, Safetensors) share updates. Highlights include PyTorch 2.13 release with performance improvements and Apple Silicon optimization, along with progress on ExecuTorch and hardware enablement.
@PyTorch: FBTriton is the Triton repo where Meta develops its experimental GPU optimization solutions (including TLX/torchTLX and…
Meta's FBTriton is a downstream fork of OpenAI's Triton compiler that enables rapid development of GPU optimizations like TLX and autoWS while staying synced upstream. This blog details its continuous upstream ingestion strategy, hierarchical L1/L2/L3 validation framework, and the practical challenges of balancing innovation with production stability.
@PyTorch: PyTorch member Meta just open-sourced a GPU kernel that makes attention 2.3x faster on NVIDIA Blackwell. TLX Block Atte…
Meta open-sources TLX Block Attention, a warp-specialized Triton kernel that achieves 2.3x speedup for block-diagonal self-attention on NVIDIA Blackwell GPUs, with up to 3.5x speedup when fused with rotary embeddings.