@Zefan_Cai: Spot the wrong target before you hit Confirm. Try the Open-Jev-27B-v1.1 demo: click between two examples and see how th…
Summary
Open-Jev-27B-v1.1 is an open-source AI model with a LoRA adapter, achieving 85.28% accuracy on JevBench and featuring interactive demos for various tasks.
View Cached Full Text
Cached at: 09/23/26, 06:11 PM
Spot the wrong target before you hit Confirm. Try the Open-Jev-27B-v1.1 demo: click between two examples and see how the model chooses an action. No code. No setup. An interactive replay of real model outputs. Try it ↓ https://zefan-cai.github.io/open-jev/v1-1/
Open-Jev-27B-v1.1 · Same preview. Different target.
Source: https://zefan-cai.github.io/open-jev/v1-1/ Open-Jev-27B-v1.1 / New model + new demo
The preview points torecord_A. A candidate action now targetsrecord_B. Inspect how two saved 27B v1.1 predictions select among the supplied options.
Rank-8 LoRA adapter + FP32 decision head over a pinned Qwen3.8-27B base. Base weights are required separately.
Illustrative UI from synthetic text-state records. No browser actions executed. Playback is edited and does not measure inference latency.
Public JevBench / 231 tasks
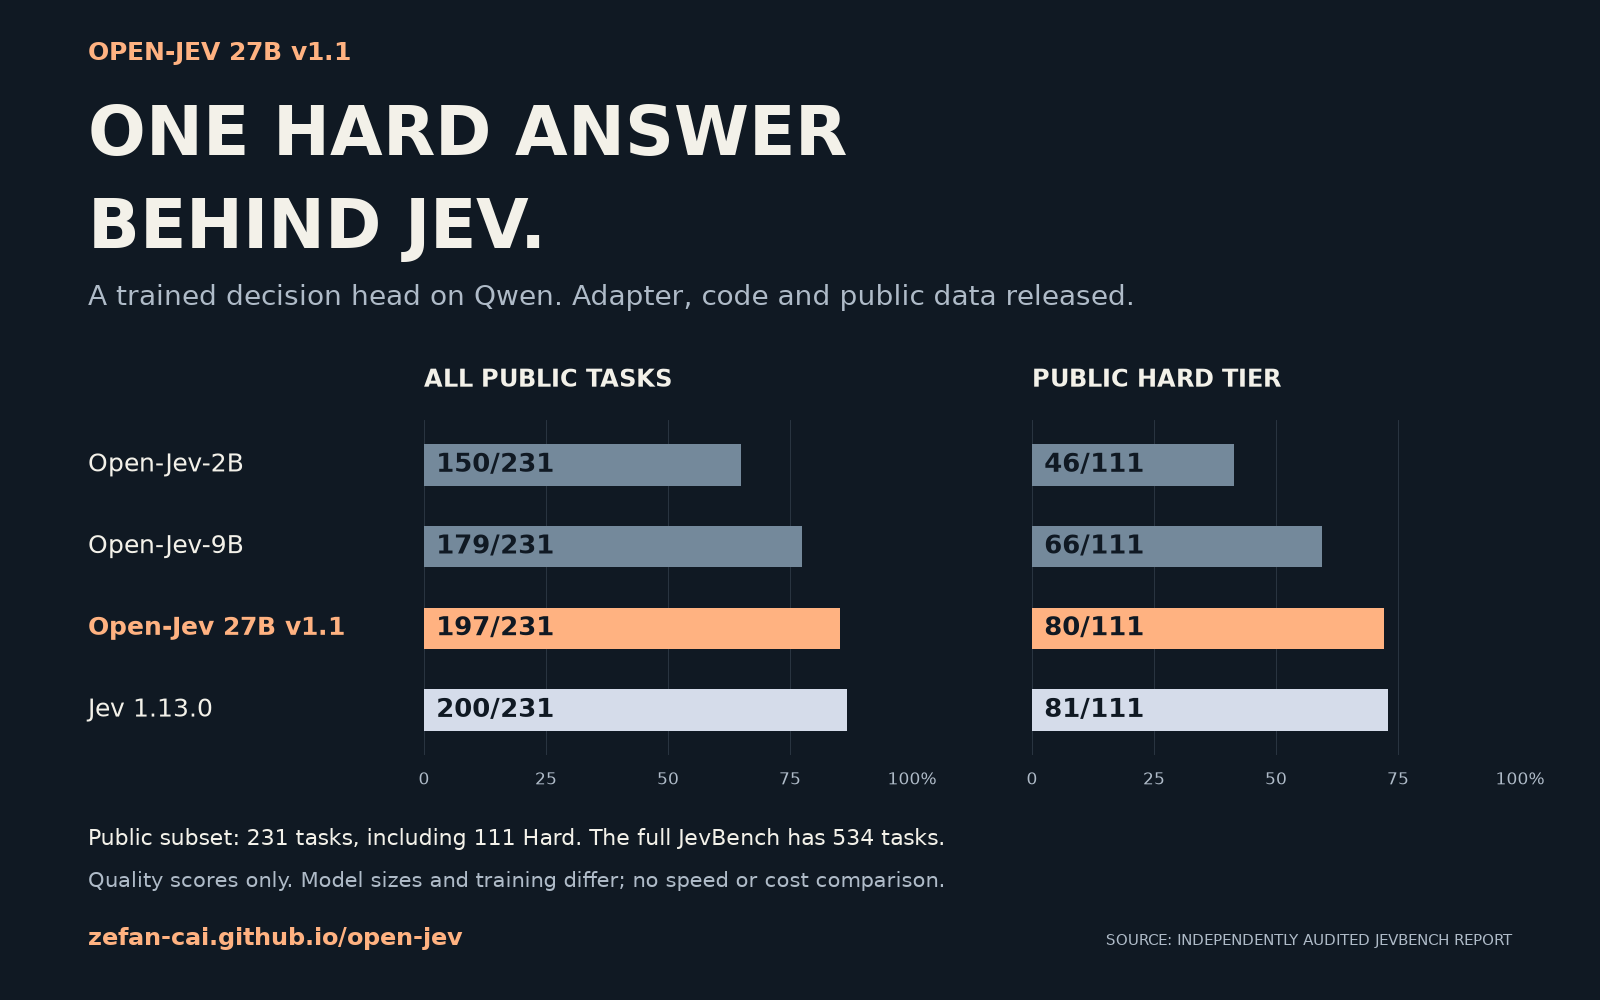
80 out of 111 on Hard. One answer behind Jev.
Open-Jev-27B-v1.1 scores197/231 overall (85.28%)and80/111 Hard (72.07%). Jev scores 200/231 overall and 81/111 Hard.
This is the public 231-task subset of the 534-task benchmark. Model scale, data and prior training differ across Open-Jev versions. Shared multi-GPU evaluation times do not establish single-GPU or HTTP/API latency.
 127,787Complete internal Test/OOD rows audited
**96.65%**Expanded Test · 41,357 / 42,789 hard labels
**96.44%**Expanded OOD · 80,934 / 83,924 hard labels
All 43,301 Test and 84,486 OOD rows were evaluated; accuracy uses hard labels. The public dataset is a 326,619-row redistributable projection, excluding 2,053 Wiki records. It is not the complete internal corpus.See all four old/expanded Test/OOD columns·Audit and protocol.
New / Four interactive game demos
Your move. Then the model’s.
Try Snake, tic-tac-toe, Box Runner and Tile Platformer. Choose an action, then inspect the realOpen-Jev-27B-v1.1probabilities across 16 independent recorded game states, including three model/reference disagreements.
Interactive snapshots of saved decisions; no live model inference or new gameplay rollout.
Enter the game arcade ↗ Try text classification in your browser
Bring your own categories.
The interactive workbench runsOpen-Jev-2B on CPU. Paste messages or import a CSV, define labels, then download the results.
Open the Open-Jev-2B workbench ↗
Inspect the decision. Build your own.
Open-Jev-27B-v1.1 is a LoRA adapter and decision head. These selected examples do not establish a general task success rate or a safety guarantee.
Similar Articles
I turned Qwen3.8-27B Q2_64 + llama.cpp into a fully TypeSafe AI-compatible Jev-like system. OpenAI API still intact! World’s first Vision-enabled Jev-like model! <10 GB VRAM, 170 ms on an RTX 3090 and ~140 tok/s in chat. 76% vs. 88% Jev-1.13 Acc. on a diverse 22,000-request typed-decision benchmark
Bonsai-Llama-Jev is an open-source, vision-enabled typed-decision inference system that runs locally with low VRAM and high accuracy, outperforming other systems in a diverse benchmark.
OpenJev
OpenJev is a browser-based tool that allows users to run AI models locally and compare different inference methods, such as reading logits directly versus generating tokens in JSON format.
@0xMovez: https://x.com/0xMovez/status/2101007482919227841
The article provides a 10-step guide to building the fastest AI Agent Brain using Jev, a System One model by TypeSafe AI, which offers faster and cheaper decision-making compared to LLMs.
@Saccc_c: I strongly recommend that everyone try Jev themselves—it can boost your Codex operation speed by 10 times and save a to…
TypeSafe AI launches Jev, a System One Model optimized for automation, delivering 193.6x faster and 444.6x cheaper decision-making than traditional LLMs, with typed outputs and confidence estimates.
@noisyb0y1: https://x.com/noisyb0y1/status/2102309802072272956
Jev is a new AI model by TypeSafe AI optimized for rapid, low-cost decision-making, offering significant speed and cost improvements over traditional AI models.