Cached at:
10/01/26, 02:55 PM
# Runway Research | Introducing Praxis-1
Source: [https://runway.com/research/introducing-praxis-1](https://runway.com/research/introducing-praxis-1)
“Pick up the tennis ball and put it in the box\.”
Today we're announcingPraxis\-1, our first open\-weight world action model\. It's built on the same large\-scale video pretraining behind our general world models\. We're actively testingPraxis\-1with early partners across a variety of embodiments, and will release it publicly in the coming months\.
Every robotics project with ambitions of large\-scale deployments runs into the same problem: real\-world data is scarce and expensive to collect in the volume a generalist policy needs\. For deployments with frequent edge cases, like autonomous driving or household robotics, there’s no practical path to collect the data required for training, let alone at meaningful volume\.
Video, however, is effectively limitless, and is becoming infinite as generative models reach parity with real video on both quality and speed\. People film and upload more of everyday life each day than any robot lab could capture through teleoperated demonstrations\. More recently,[we've found](https://runway.com/research/accelerating-robot-policy-evaluation)that simulating robot policies inside our world model predicts real\-world results with 0\.95 correlation, comparing favorably to more expensive 3D reconstruction–based techniques\.Praxis\-1extends our bet that the best policy models will learn from video, and use that scale to bring embodied intelligence to every industry on earth\.
## Video Pretraining As a Foundation for Policy
We’ve recently extended our work on pretraining large video models into interactive, real\-time video models like[Solaris](https://runway.com/news/research/introducing-solaris)and[GWM Worlds 2](https://runway.com/research/introducing-gwm-worlds-2)\. By teaching our models how to generate accurate physics — how objects behave, how hands move, what a task looks like partway through — we’ve created dynamic, complex environments for agent training in the digital and physical world\.Praxis\-1brings the same approach to robotics, providing a generalist policy model for robotics developers and researchers that works across any embodiment or environment, no matter how complex\.
A policy that already understands physical plausibility and object behavior from video pretraining has an enormous head start on one built from action data alone\. The premise is similar to language models learning on available text; teaching those models the structure of the world from large\-scale data allows them to now operate effectively in settings that differ from their training sets\.
Figure 1 — Multi\-step tasks in complex environments
The base approaches the shelf, navigates towards the object, takes the book and puts it away\. 1x speed
01Approaches the shelf02Assesses the approach03Picks up the object04Removes it from the environment
We find that the same pattern holds in robotics: policy performance improves as we scale third\-person video\. The bottleneck on a capable policy becomes how much general video a model can train on\.
Figure 2 — Web video matches teleop robot video
Final placement error after finetuning, against hours of pretraining video\. Lower is better\.
Error bars and band: ±1 SEM over 93 evaluation pairs\. Differences smaller than a bar are not significant\.
Figure 3 — Where policies usually break
Four cases that defeat policies trained on demonstrations alone\. 1x speed
Rigid, repeatedMany near\-identical objects, one targetClutteredOcclusion, overlapping tablewareTransparentIce and clear plastic, weak depth cuesDeformableCloth with no fixed grasp point
## Testing With Early Partners
We're rollingPraxis\-1out to key partners ahead of a public launch, including[Noble Machines](https://www.noblemachines.ai/),[Standard Bots](https://standardbots.com/)and[Ultra](https://www.ultra.tech/), each running the model on their own hardware\. We’ll be providing early access to additional partners pre\-launch\. This testing is designed to ensure both efficacy and safety – we’ll evaluate on a variety of embodiments and environments, identifying and closing potential gaps before moving to general availability\.
- [Noble Machines](https://www.noblemachines.ai/) Bimanual manipulation\. 2x speed noblemachines\.ai
- [Standard Bots](https://standardbots.com/) 6\-DoF arm · RO1\. 2x speed standardbots\.com
- [Ultra](https://www.ultra.tech/) Mobile base 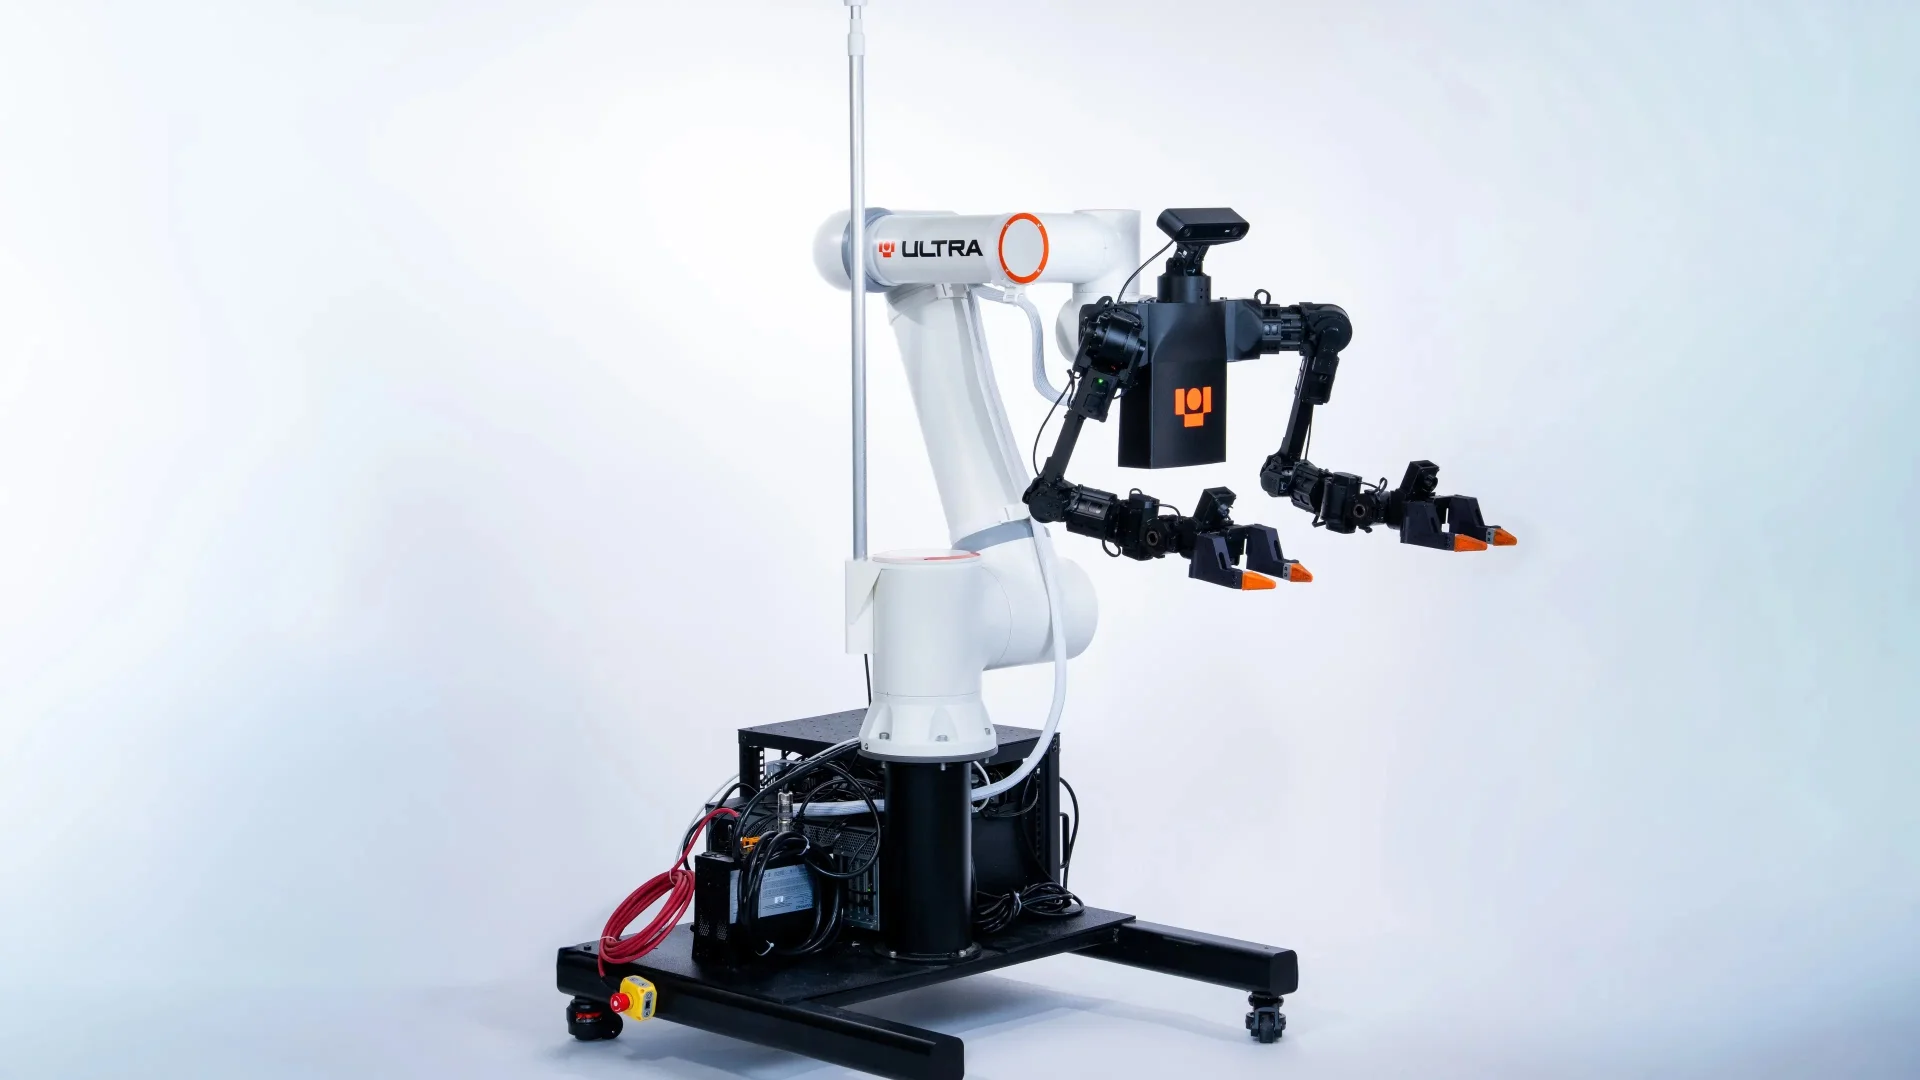 ultra\.tech
Figure 4 — Studio, home
The same policy moved between environments without retraining\. 1x speed
StudioControlled light, fixed rigKitchenDomestic counter, mixed light
## Why Open Weight
WhenPraxis\-1releases publicly, we'll ship it with open weights rather than as a closed model\. We believe that U\.S\. leadership in physical AI is critical\. Regaining our global lead in manufacturing, accelerating productivity across our economy and securing ourselves and our allies will rely on this\. Achieving this will require a significant increase in investment across both hardware and software, but it will also require a level of interoperability and openness from American models that does not currently exist for physical use cases\. We view open world models as a compounding advantage that gives hardware developers flexibility and control they don’t currently have\.