lightseekorg/tokenspeed
Summary
TokenSpeed 是一个开源 LLM 推理引擎,专为 agentic 工作负载设计,采用首创的控制面(C++ 有限状态机)与执行面(Python)分离架构,主打 TensorRT-LLM 级性能与 vLLM 级易用性,已加入 PyTorch 生态并获 NVIDIA、AMD 支持。
View Cached Full Text
Cached at: 10/15/26, 12:44 PM
lightseekorg/tokenspeed
Source: https://github.com/lightseekorg/tokenspeed
TokenSpeed is a speed-of-light LLM inference engine designed for agentic workloads, with TensorRT-LLM-level performance and vLLM-level usability. The goal is to be the most performant inference engine for production agentic workloads.
Core components:
- Scheduler: C++ control plane and Python execution plane. Request lifecycle, KV cache ownership, and overlap timing are encoded as a finite-state machine, with safe KV resource reuse enforced by the type system at compile time.
- Kernels: pluggable, layered kernel system with a portable public API and a centralized registry including one of the fastest MLA (Multi-head Latent Attention) implementations on Blackwell for agentic workloads.
- Entrypoint: SMG-integrated AsyncLLM for low-overhead CPU-side request handling.
Differentiation
TokenSpeed takes a fundamentally different architectural approach from existing LLM inference engines. The PyTorch Foundation highlighted these architectural differentiators when welcoming TokenSpeed to the PyTorch Ecosystem Landscape:
TokenSpeed is an open source LLM inference engine and the first to separate the control plane from the execution plane. The control plane is implemented in C++ as a finite-state machine, using the type system to enforce safe resource management, including request lifecycles and KV cache state, at compile time rather than runtime. The execution plane is implemented in Python, enabling fast iteration and lowering the cognitive load for researchers and engineers. This architecture combines strong correctness guarantees in the core scheduling system with the development velocity of a high-level execution layer.
TokenSpeed also treats kernels as a first-class, modular subsystem, separating them from the core engine through a portable public API, centralized registry and selection model, and an extensible plugin mechanism for heterogeneous accelerators.
More importantly, TokenSpeed is the Switzerland of open-source LLM inference engines: neutral because it’s backed by the non-profit LightSeek Foundation rather than a commercial company, with serious hardware and engineering support from vendors like NVIDIA and AMD.
News
- [2026/10] 🔥 685 tokens/s per user: serving Qwen3.8-Flash-Next on NVIDIA GB300 with TokenSpeed. [blog]
- [2026/10] 🔥 Advancing Kimi K3 inference on AMD Instinct MI355X GPUs with TokenSpeed. [AMD blog]
- [2026/09] Kimi K3 Optimization on GB300 — Part I. [blog]
- [2026/08] Qwen3.8 Flash Next at Day 0 and GLM 5.3 Flash at Day 0.
- [2026/08] Qwen3.8 at Day 0: 2.4T-Scale Inference with TokenSpeed. [blog]
- [2026/08] TokenSpeed joins the PyTorch Ecosystem.
- [2026/07] Kimi K3 at Day 0: Frontier Model Enablement on Leading Platforms with TokenSpeed. [blog]
- [2026/07] TML Inkling at Day 0: FP4 Inference on NVIDIA and AMD with TokenSpeed. [blog]
- [2026/06] Deep dive into the design and optimization of TokenSpeed-Kernel. [PyTorch blog]
- [2026/05] 🚀 TokenSpeed hits 580 TPS on Qwen3.5-397B-A17B for agentic workloads. [PyTorch blog]
- [2026/05] TokenSpeed announced — a speed-of-light LLM inference engine for agentic workloads. [blog]
Blogs and talks
For technical blogs, conference talks, and engineering articles from LightSeek Foundation, visit the LightSeek Blog.
Sponsors and partners
LightSeek’s work is advanced by the support of sponsors and partners across the AI ecosystem.
Performance comparison
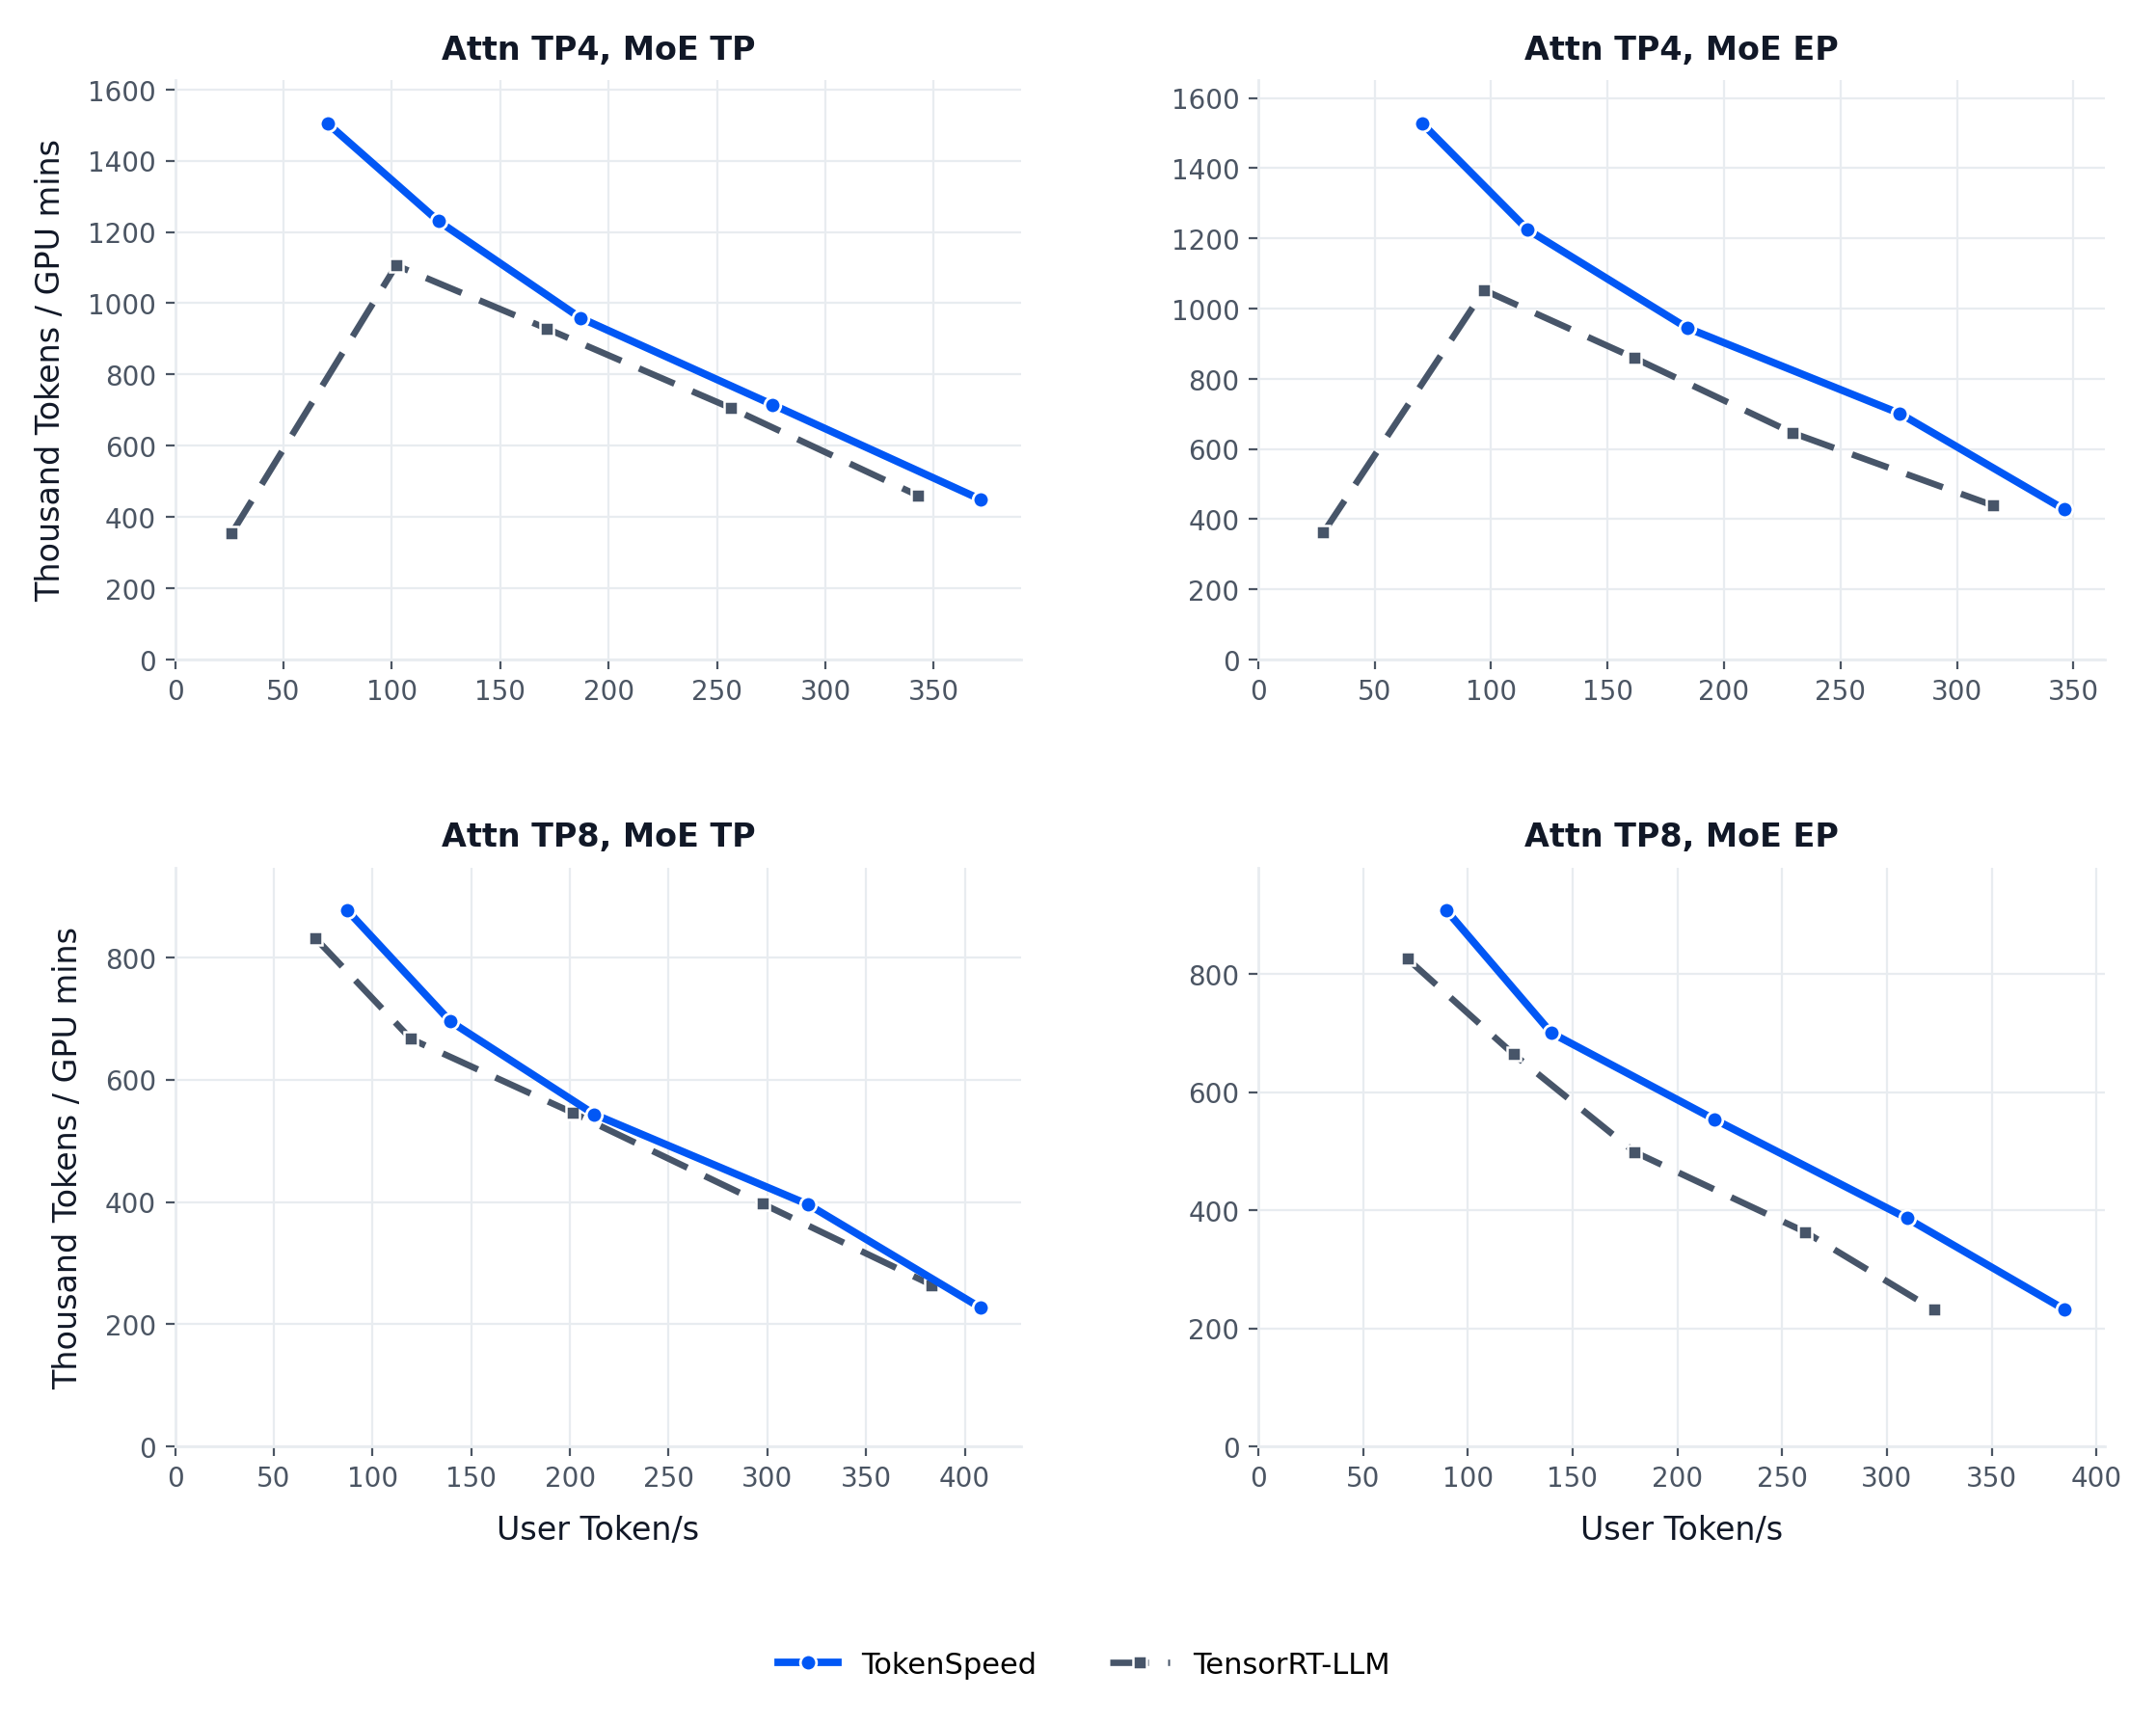
TokenSpeed vs. TensorRT-LLM Pareto curves on agentic workloads (Kimi K2.5, B200)
Documentation
Start here:
- Docs Index
- Getting Started
- Launching a Server
- Model Recipes
- Server Parameters
- Compatible Parameters
- Parallelism
Citation
@misc{tokenspeed2026,
  author       = {{TokenSpeed Team}},
  title        = {{TokenSpeed}: A Speed-of-Light {LLM} Inference Engine},
  year         = {2026},
  howpublished = {\url{https://github.com/lightseekorg/tokenspeed}}
}
Similar Articles
TokenSpeed: A Speed-of-Light LLM Inference Engine for Agentic Workloads (5 minute read)
Lightseek releases TokenSpeed, a high-performance LLM inference engine optimized for agentic workloads, featuring compiler-backed parallelism and advanced kernel optimizations that have been adopted by vLLM.
@PyTorch: LightSeek (@lightseekorg) TokenSpeed brings Day-0 optimized FP4 inference support for Thinking Machines Lab’s Inkling a…
LightSeek's TokenSpeed provides Day-0 optimized FP4 inference support for Thinking Machines Lab's Inkling model on NVIDIA and AMD accelerators, built on PyTorch and collaborating with vLLM.
@PyTorch: One runtime, multiple GPU architectures, and zero vendor-specific model code. In this blog post, the TokenSpeed team @l…
TokenSpeed-Kernel is a portable, high-performance kernel system for LLM inference that enables zero vendor-specific model code and supports multiple GPU architectures, achieving up to 3.6x higher throughput on AMD MI355X.
@QingQ77: Pure Rust LLM inference engine with custom CUDA kernels for each hardware × model × quantization combination, achieving higher inference speed than vLLM and TensorRT-LLM. https://github.com/Avarok-Cybersecurity/a…
Atlas is a pure Rust LLM inference engine that delivers faster inference than vLLM and TensorRT-LLM by customizing CUDA kernels for each hardware × model × quantization combination.
AccelOpt: A Self-Improving LLM Agentic System for AI Accelerator Kernel Optimization
AccelOpt is a self-improving LLM agentic system that autonomously optimizes AI accelerator kernels through iterative generation and optimization memory, achieving 49-61% peak throughput improvements on AWS Trainium while being 26x cheaper than Claude Sonnet 4.