Momentic (YC W24) launched on Launch HN, showcasing Mo, an AI QA engineer that tests apps end-to-end and has caught over 117k bugs across 70M+ test runs. The platform integrates with coding agents via MCP and CI pipelines using plain-English YAML tests with self-healing capabilities.
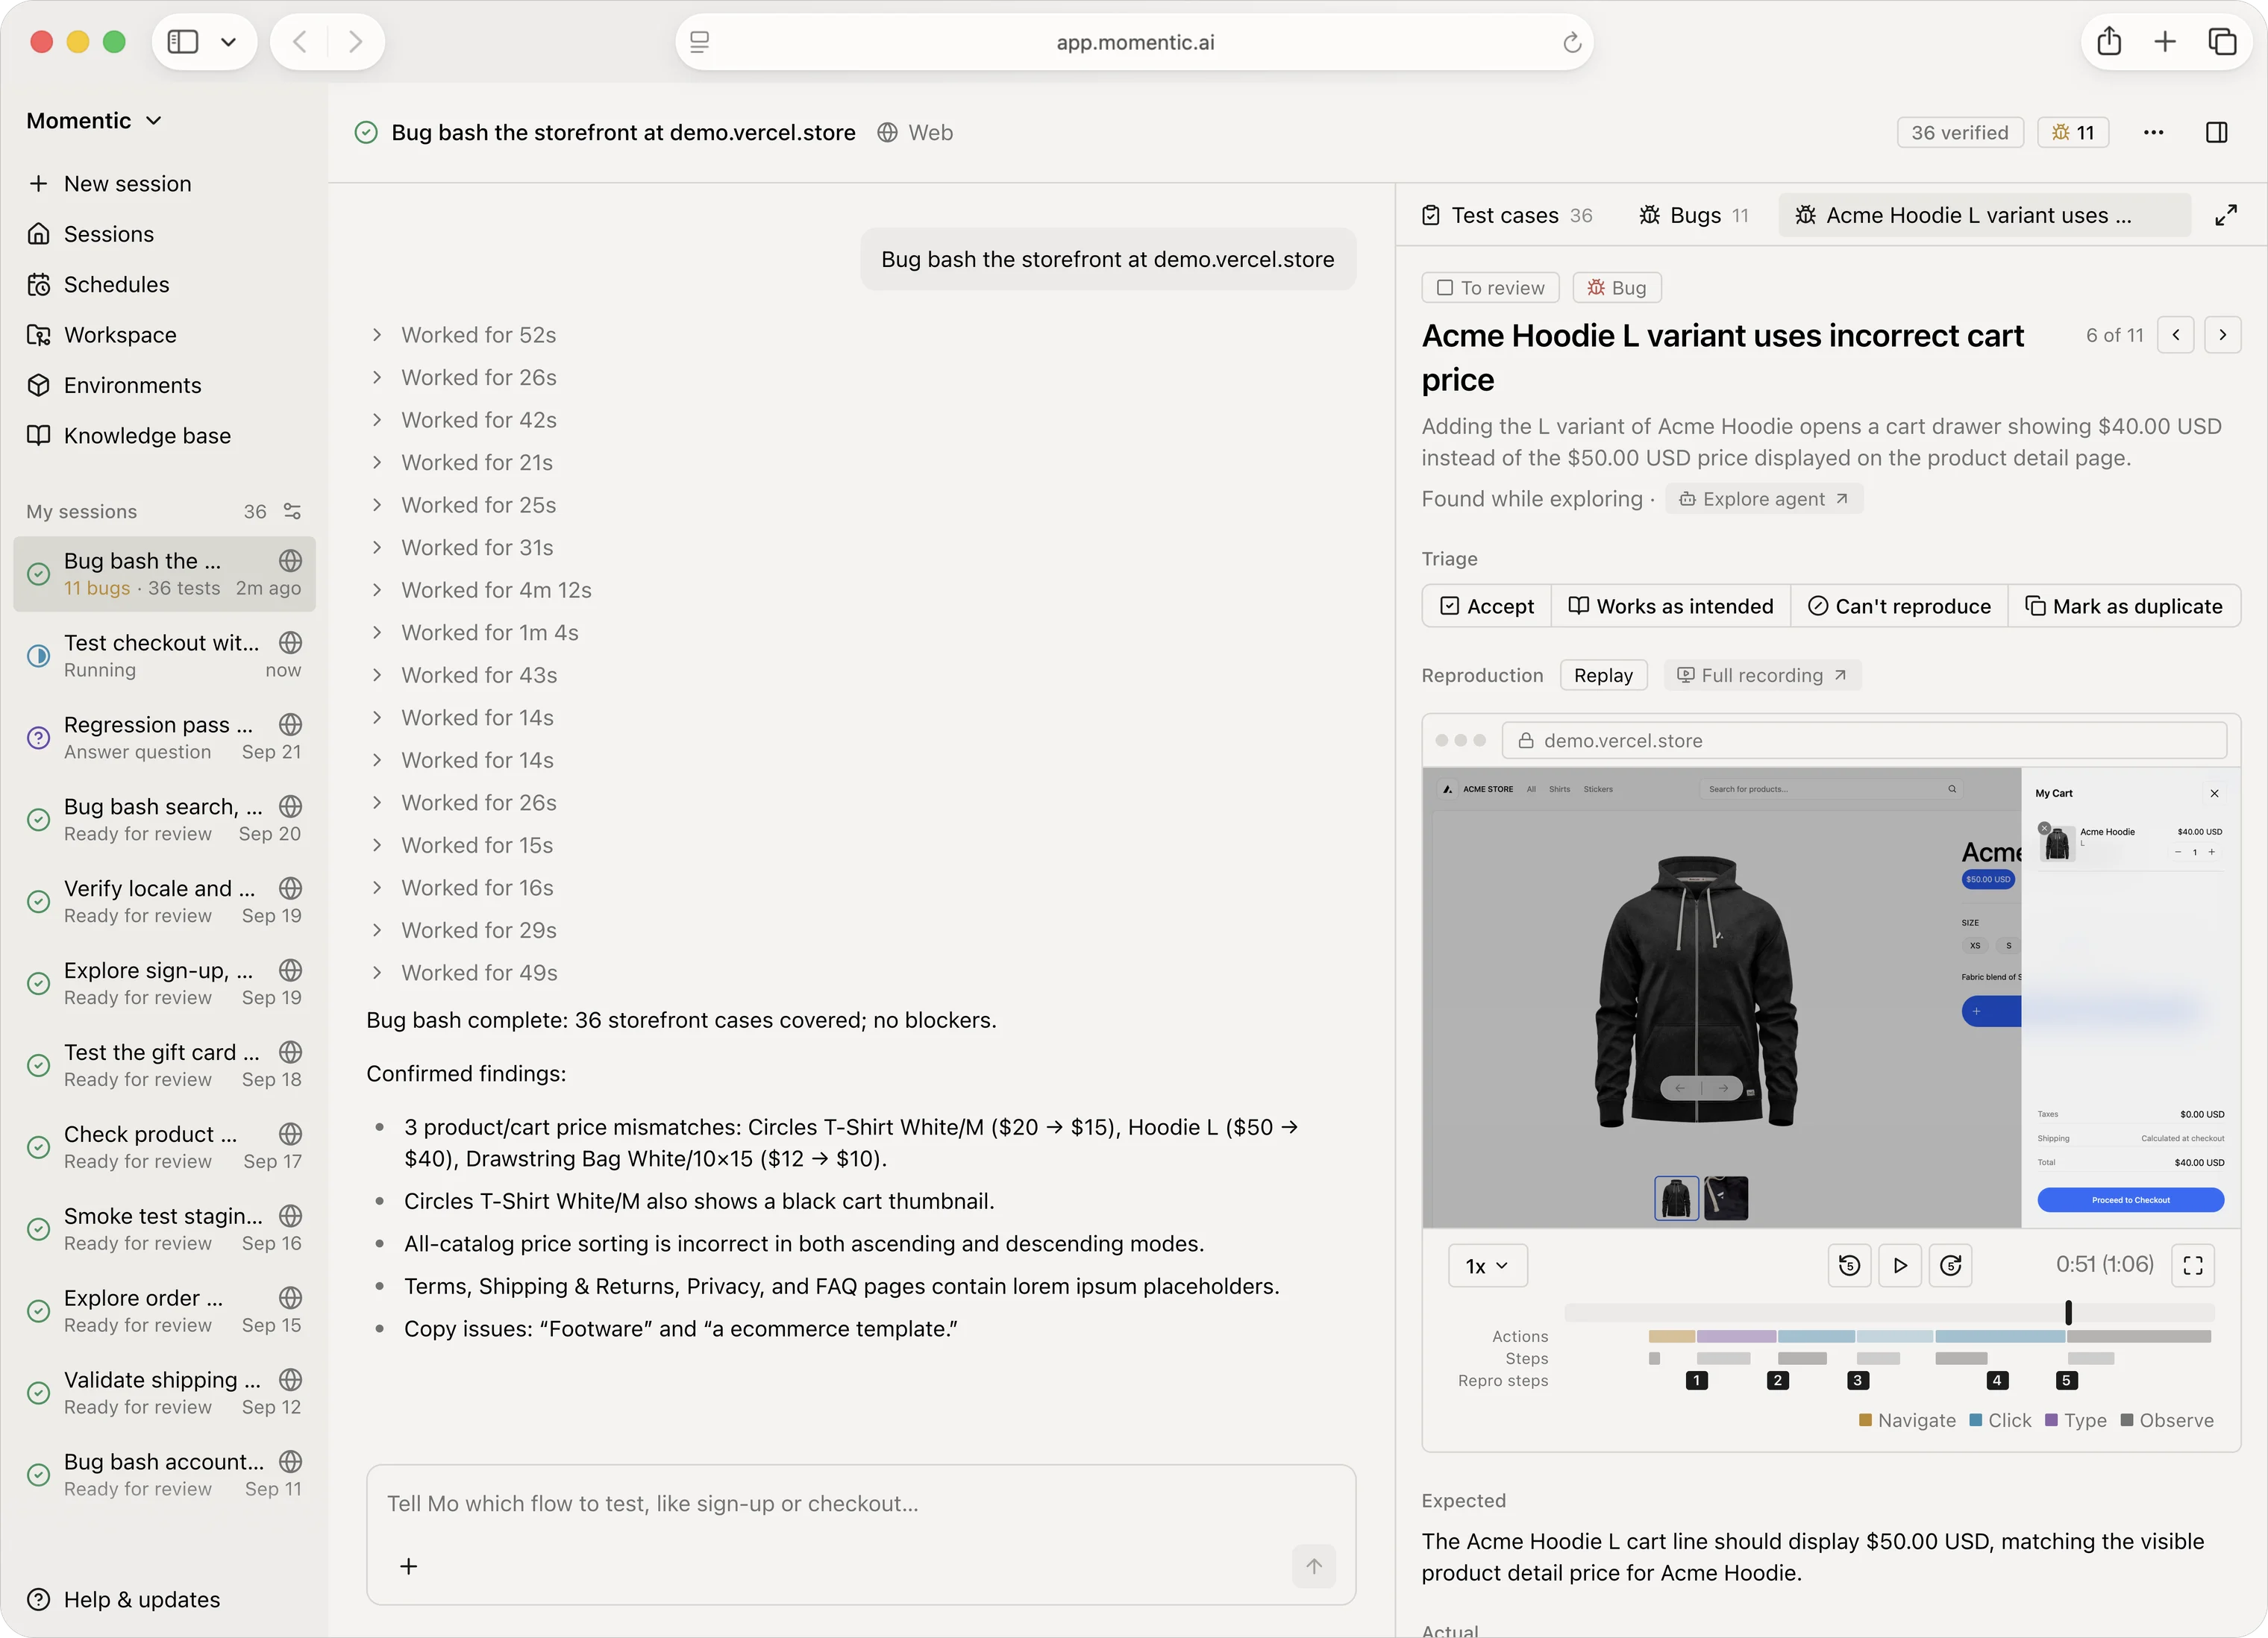
Hey HN, we’re Wei-Wei and Jeff. We’re building Momentic, QA agents that autonomously plan, explore, and bug-bash controls and user flows in your web, iOS, Android, and (soon) desktop apps to catch bugs.<p>Here’s a demo: <a href="https://youtu.be/BFsM-Se1Fh8" rel="nofollow">https://youtu.be/BFsM-Se1Fh8</a><p>We’re both software engineers that spent our careers on dev tooling and infra across companies like Robinhood, Retool, WeWork, and Qualtrics. Testing was always a pain in the ass (esp Playwright and Selenium), so we built agents to do it for us.<p>Modern day software has a ton of bugs and the change failure rate is only growing faster as coding agent adoption scales. LLMs are really good at generating code, but reinforce their own assumptions, write a ton of useless tests, and are bad at visual understanding. On DeepSWE v1.1, Sonnet 5.5 hit 66.2% pass rate when banned from writing tests, versus 65.3% when allowed.<p>OSS end-to-end testing frameworks like Playwright, Selenium, or Maestro force you to hardcode implementation details like XPath, text, or aria-* attributes in your tests. Even with agents, these take a nontrivial amount of time and tokens to build and maintain.<p>In 2023, we saw Nat Friedman drive a browser with GPT-3 via natbot. We were inspired to use this technology to automate the most painful and tedious parts of software engineering: testing. We started with using LLMs to generate and maintain Playwright, but quickly realized that those primitives were fundamentally misaligned with the agentic SDLC. We think the future of QA is agents testing themselves, not writing scripts.<p>Mo is a custom agent harness for catching bugs that builds on the past 3 years of Momentic and millions of test traces from complex, real-world applications. Mo is built for recall: it finds the most real bugs, though Codex is a bit more precise at 86% vs 84%. The tradeoff is cost: Mo costs $2.67 per bug vs $0.80 for Codex, less than Claude Code and Devin.<p>- Self-organizing agent graph. Mo builds a directed acyclic graph (DAG) as it explores. Large product areas automatically fork into parallel sub-agents, each with their own browser or device for concurrent execution.<p>- Specialized agents for domain specific tasks. Planner agents reason over screenshots and video while dedicated locator agents inspect page structure to resolve plain-English interaction targets. Others include image analysis, video understanding, audio generation, and more.<p>- Parallel agents coordinate through cooperative resource leases. Agents can announce that they’re “using” or “modifying” overlapping resources or fixtures. Multiple “using” claims can coexist, but only a single “modifying” claim can be active on any particular one.<p>- Scaled infrastructure. Mo ships with a tunnel that lets users expose private sites and local apps to our hosted agents and infra. A single bug bash can spin up 100s of concurrent browsers and devices.<p>We benchmarked Mo against coding agents on 4 popular open-source apps: Gitea (58.8k stars), Metabase, Twenty (YC), and Saleor, with 1,396 human-labeled bugs. Each agent got the same brief, a fresh E2B sandbox, and no access to source code. Codex and Claude Code used hosted Browserbase browsers, while Devin used its built-in browser. For evaluators, we implemented LLM as a judge (GPT-6.1 Sol) with a human reviewer.<p>Results from a time-boxed 60-minute run:<p>- Mo: 269 bugs, 19.3% recall, 84% precision, $2.67 per bug<p>- Codex (GPT-6.1 Sol + Playwright MCP): 86 bugs, 6.2% recall, 86% precision, $0.80 per bug<p>- Claude Code (Opus 5.5 + Playwright MCP): 59 bugs, 4.2% recall, 80% precision, $4.09 per bug<p>- Devin: 27 bugs, 1.9% recall, 84% precision, $3.89 per bug<p>Mo finds more bugs the more time it has. From 30 to 60 minutes, it went from 177 to 269 bugs (+52%), while Codex gained only 16%.<p>Results: <a href="https://momentic.ai/qa-bench">https://momentic.ai/qa-bench</a><p>Write-up: <a href="https://momentic.ai/blog/qa-bench">https://momentic.ai/blog/qa-bench</a><p>Dataset: <a href="https://huggingface.co/datasets/momentic/qa-bench" rel="nofollow">https://huggingface.co/datasets/momentic/qa-bench</a><p>Harness: <a href="https://github.com/momentic-ai/qa-bench" rel="nofollow">https://github.com/momentic-ai/qa-bench</a><p>We just shipped PR testing for Vercel and Cloudflare deploy previews and we’re giving every new signup $250 in Mo spend. Paid plans have higher infra capacity and included usage along with options to top up.<p>We’d love for you to try it out and give us feedback. Feel free to comment here, we’ll be around all day!
# AI Testing Platform: 117k Bugs Caught | Momentic
Source: [https://momentic.ai/](https://momentic.ai/)
## Catchbugsbefore they ship\.
Mo is an AI QA engineer that tests your app end to end\. Verify critical flows and find bugs from a prompt\.
Tests created77,813
Test runs executed70,607,819
Changes verified339,166
PRs verified80,290
Auto\-heals8,932,104
Bugs caught117,010
Tests created77,813
Test runs executed70,607,819
Changes verified339,166
PRs verified80,290
Auto\-heals8,932,104
Bugs caught117,010
Tests created77,813
Test runs executed70,607,819
Changes verified339,166
PRs verified80,290
Auto\-heals8,932,104
Bugs caught117,010
Trusted in production by teams shipping every day\.
"Our team's experience with Momentic has been great\. Setting up tests is simple and the developer experience has been fantastic\."
Erdem
Head of Developer Experience, Notion
"Having E2E QA be part of the development process, run this fast \(6\.3x parallel\), and at this scale \(for every single pull request\) is a true dream\. Seriously, a green CI now has a measurable impact on my sleep quality\."
Glavin
Founding AI Engineer, Coframe
"Momentic makes it 3x faster for our team to write and maintain end\-to\-end tests\. Startups win by shipping faster and better, and Momentic enabled us to do exactly that\."
"I just ran our first automated eval across 110 prompts\. This would have taken well over an hour manually — I kicked it off in 5 seconds and it was done in 14 minutes\. HUGE for us\."
Mike
Engineering Manager, Runway
"I love working with Momentic\. Especially after having years of previous experience in QA, it feels like riding a bike, except the bike is a supercharged electric one\!"
Anna
Senior Productivity Engineer, Webflow
Code moves faster\. Verification has to keep up\.
Codingagentshavemadeitdramaticallyfastertobuildsoftware\.Thebottleneckisnowknowingitworks\.Verificationbelongsintheagentloop\.Agentsneedevidencefromtheappitselftoverifythattheirchangesdelivertheintendedbehavior\.
[Explore](https://momentic.ai/#platform)
## Theagenticquality platform\.
Write the user flows you need to verify\. Momentic runs the tests against your app\. Reuse successful AI actions and review proposed repairs as the app changes\.
1of 5
01
Knows how your product works
Add terminology, expected behavior, and test guidance to the Knowledge base\. AI\-assisted steps look up relevant entries as they run\.
PRODUCT CONTEXT AT EACH AI STEP
02
Keep tests working as the UI changes
Momentic finds controls again when the UI changes during a run\. Permanent healing proposes a test\-file repair for you to review\.
RUNTIME RECOVERY AND REVIEWED REPAIRS
03
Verify changes with your coding agent
Give your coding agent the changed flow\. It can use MCP to author a test, check it in a live session, and save the YAML alongside your code\.
TESTS REVIEWED WITH THE CODE
04
See why a test failed
Inspect the failing step, screenshots, and traces\. Classify failures as application bugs, test flakiness, or environment issues\.
STEP\-LEVEL FAILURE EVIDENCE
05
Verify before you merge or deploy
Run the CLI in your CI job\. Use its exit code as a required check before merging or deploying\.
CLI EXIT CODES FOR CI CHECKS
Verification from your editor to CI\.
## Define what matters\. LetMomenticverify it\.
Write steps and assertions in plain\-English YAML\. Review and version the tests in your repository\.
01/ author
### Write tests inplain English
Describe a user flow and its expected result in plain English\. Keep the steps and assertions in YAML files your team and coding agent can review\.
02/ run
### Run locally and inCI
Use the CLI to check the app you're changing\. Run the same tests in CI before the next merge or deploy\.
03/ triage
### Find theroot cause
See which step failed and inspect its screenshots and traces\. AI triage investigates the cause and proposes a test repair for you to review\.
04/ heal
### Auto\-healas your product evolves
Momentic finds controls again when the UI changes\. Permanent healing proposes test\-file edits for review\. Apply the diff and rerun to check the result\.
## Learnshow your product works\.
Describe your product’s terminology, business rules, and expected behavior in the Knowledge base\. Agents use that context to choose actions and check outcomes\.
### Knowledge base
Give agents the product rules they need to check a flow\.
### App graph
Maps screens and user flows seen during test runs\.
### Review new guidance
Review session suggestions before adding them to the Knowledge base\.
Loved by engineering teams\.

“Momentic gave us afast and reliableway to validate Poe\.com's AI responses, even when they weren't deterministic\.”
Momoko F\.Head of Product Operations, Quora
30 min
daily test execution, down from 7 hours
500\+
manual test cases replaced
100%
critical tests created in one month
[Read the full story](https://momentic.ai/customers/quora)
Examples of application failures found by Momentic, with the affected flow and its impact\.
117,010before production
DetectedON A FEATURE BRANCH
### New\-device 2FA prompt skipped
At a consumer fintech app, a login routing change bypassed the new\-device verification step\.
Impact
A security checkpoint was silently skipped\.
DetectedBEFORE RELEASE
### Page creation flow broken on mobile
On mobile, keyboard auto\-dismissed when creating a new page, breaking content flow\.
Impact
Silent friction in the core creation flow\.
DetectedIN STAGING
### Driver ETA stuck on 'calculating'
A dependency update on a large rideshare app caused the live ETA subscription to silently fail after a ride was booked\.
Impact
Riders never saw an arrival estimate\.
DetectedBEFORE DEPLOY
### Scheduling availability displayed incorrectly
Incorrect display and logic in the calendar scheduling view\.
Impact
Wrong availability shown to users\.
DetectedIN CI
### Timer reset when the screen locked
At a leading wellness app, an iOS lifecycle change reset the active sleep timer the moment the phone locked\.
Impact
Audio sessions ended mid\-playback overnight\.
Detected8 MIN BEFORE DEPLOY
### Saved cards dropped at checkout
At a top food\-delivery marketplace, a payment\-form refactor stopped pre\-filling saved cards, forcing manual re\-entry to pay\.
Impact
Returning users abandoned checkout on mobile\.
DetectedIN A NIGHTLY RUN
### Filters cleared when paginating results
At a popular online retail marketplace, moving to page two reset every active category and price filter\.
Impact
Shoppers lost their refined search results\.
DetectedBEFORE MERGE
### Valid promo codes rejected at the final step
At a large online travel marketplace, a validation change rejected multi\-segment promo codes on the last checkout step\.
Impact
Discounts failed and carts were abandoned\.
DetectedPRE\-RELEASE
### Wrong subtitle language on first play
At a major streaming platform, a locale\-detection bug auto\-selected the wrong subtitle track on initial playback\.
Impact
Wrong\-language captions at session start\.
DetectedBEFORE RELEASE
### Legacy API issues exposed
12 bugs caught in one day\. Exposed legacy API issues that would have shipped undetected\.
Impact
Risked shipping regressions into major release\.
## Verify what youship\.
## Changelog
TesterArmy is a YC-backed agentic testing platform that lets developers specify end-to-end tests in natural language, automatically runs them before deployment and in production, and has already caught critical bugs for over 30 teams.
Intuned is a YC-backed tool that uses an AI agent to build, deploy, and maintain Playwright-based browser automations, handling scraping, RPA, and crawlers with built-in anti-detection and authentication.
Agentic CleanSlop launches on Product Hunt, letting developers authenticate, scan and fix vibe-coded TypeScript/Node.js apps directly from coding agents like Claude Code, Codex, and Cursor, surfacing real-world risks instead of hundreds of findings.
Agnost AI is a platform that analyzes agent conversations to surface user feedback, detect failures, and generate automated fixes, helping teams improve their AI agents.
Manufact is a cloud platform for building and deploying MCP agents, servers, and apps, offering an SDK, automated deployment, monitoring, and marketplace submission tools.