@LangChain: LangChain Community Spotlight: Enterprise RAG on LangChain Kacper Klusek of Soba Labs shows how to build enterprise RAG…
Summary
LangChain Community Spotlight featuring Kacper Klusek of Soba Labs on building enterprise RAG by fixing retrieval first: contextual chunking, BM25 hybrid search, and a reranker cut failed retrievals by 67% in Anthropic's evaluation, with LangSmith evals catching document drift.
View Cached Full Text
Cached at: 11/01/26, 01:41 AM
LangChain Community Spotlight: Enterprise RAG on LangChain 🔎📚
Kacper Klusek of Soba Labs shows how to build enterprise RAG on LangChain by fixing retrieval before you touch the model. In Anthropic’s published evaluation, the retrieval chain he recommends (contextual embeddings, BM25 and a reranker) cut failed retrievals by 67%. LangSmith online evals then catch the decay that starts when your documents change.
📖 Read the full guide: https://sobalabs.ai/blog/enterprise-rag-on-langchain/…
Enterprise RAG on LangChain: fix retrieval first | Soba Labs
Source: https://sobalabs.ai/blog/enterprise-rag-on-langchain/
 Your enterpriseRAGsystem will not fail where you are looking. The model takes the blame for a wrong answer, but the highest-leverage fixes sit a step earlier, in the chunks retrieval never returned.Fix retrieval first: contextual chunking, hybrid search and a reranker cut failed retrievals by 67% in Anthropic’s published evaluation, more than any model swap will buy you.LangChainships every block of that stack, and LangSmith closes the loop with evaluators that catch the decay a demo never shows. This post walks the stack in the order the data says to build it: architecture, chunking, hybrid retrieval, reranking, then the eval loop that keeps it honest.
Retrieval fails long before the model does
The case for RAG has not changed: models have what theLangChain retrieval docscall finite context and static knowledge, so the system fetches relevant external knowledge at query time. What has changed is where production teams lose. When a RAG answer is wrong, read the retrieved set before blaming the model: in our reviews the passage that held the answer was split badly, embedded without its surroundings, outranked by a near-duplicate, or never indexed at all, and the model summarized the wrong context faithfully. Each of those is a retrieval defect, and each has a named fix that costs less than a frontier model upgrade.
That ordering is the practical point. Teams tune prompts and swap models because those changes take an afternoon, while the retrieval stack looks like plumbing. The plumbing is the product.In production RAG, the generating model is rarely the bottleneck; the chunks you hand it are.
Pick the architecture by who controls the loop
The current LangChain docs organize RAG into three architectures, and the choice comes down to control. In 2-Step RAG, retrieval always runs before generation, so latency is predictable and the number of LLM calls is capped. Inagentic RAG, an agent decides when and how to retrieve during reasoning; the docs note that the only thing an agent needs for RAG behavior is access to tools that fetch external knowledge. Hybrid designs sit between, wrapping retrieval in validation steps: query enhancement, retrieval validation that can re-query when documents come back thin, and answer validation against the sources.
ArchitectureWho controls retrievalLatencyFits2-Step RAGThe pipeline: retrieval always precedes generationPredictable, LLM calls cappedFAQs, documentation botsAgentic RAGThe model: an agent decides when and how to retrieveVaries with the loopMulti-source and multi-step questionsHybridThe pipeline plus validation steps that can re-queryBetween the twoEnterprise QA that must not guessStart with 2-Step unless you can say which question class it fails. We made the same argument about agent control flow inLangGraph agents in production: give the model the smallest loop that answers the question, because every degree of freedom you grant is a failure mode you now have to evaluate.
Chunking is a retrieval decision, not preprocessing
Chunkinglooks like preprocessing and behaves like ranking: whatever boundaries you cut are the only retrieval units that exist. Thesplitters documentationis unusually direct about the default:*“For most use cases, start with theRecursiveCharacterTextSplitter. It provides a solid balance between keeping context intact and managing chunk size.”*It keeps paragraphs intact where it can and descends to sentences and words only when a unit exceeds the chunk size, and for HTML, Markdown or JSON the structure-based splitters follow the document’s own boundaries instead. LangChain’sknowledge base tutorialpins the working defaults:
from langchain_text_splitters import (
    RecursiveCharacterTextSplitter,
)

splitter = RecursiveCharacterTextSplitter(
    chunk_size=1000,
    chunk_overlap=200,
    add_start_index=True,
)
chunks = splitter.split_documents(pages)
# the tutorial's 107-page PDF becomes 516 chunks
add\_start\_index=Truekeeps each chunk’s character offset, which you will want the first time a user asks where an answer came from. The deeper problem is that a chunk cut from its document loses its referents, and that is whatcontextual retrievalrepairs: Anthropic’spublished methodprepends a short generated context to each chunk before embedding, and contextualembeddingsalone reduced the top-20 retrieval failure rate by 35%, from 5.7% to 3.7%, at a one-time cost of $1.02 per million document tokens. The same post names the escape hatch worth checking before you build anything:“If your knowledge base is smaller than 200,000 tokens (about 500 pages of material), you can just include the entire knowledge base in the prompt that you give the model, with no need for RAG or similar methods.”
Hybrid search wins the queries embeddings miss
Densesemantic searchover avector databasematches meaning and shrugs at exact strings, which is a problem the first time a user searches for an error code, a part number or a clause reference. The fix is old technology kept on purpose: pair the dense index with BM25, thesparse retrievalalgorithm that still wins on exact identifiers, and fuse the result sets. Weaviate’shybrid search docsstate the pattern plainly:*“Hybrid search combines the results of a vector search and a keyword (BM25F) search by fusing the two result sets. The fusion method and the relative weights are configurable.”*Theiralphaweight runs from 0, pure keyword, to 1, pure vector, and Relative Score Fusion has been the default fusion method since v1.24, sohybrid searchhas become a configuration decision.
Anthropic’s evaluation above measured the same combination: adding contextual BM25 to contextual embeddings took the failure rate from 3.7% to 2.9%, a 49% total reduction from the 5.7% baseline. Scope it honestly, though: BM25 earns its keep on corpora full of identifiers and jargon, andmetadata filteringon fields like date, product or tenant often cuts the candidate set more cheaply than either index.
Reranking is the cheapest accuracy left on the table
First-stage retrieval, dense or hybrid, is built for recall over a large corpus. A reranker is a second model that reorders a small candidate set by actual relevance to the query, and because it reads query and document together, it catches what bi-encoder embeddings structurally cannot. Cohere’sRerank docsdescribe the endpoint simply: given a query and a list of documents, it indexes them from most to least semantically relevant, and the model lineup now runs to Rerank 5. The gains are published and specific: Cohere’sRerank 3.5 announcementmeasured it +23.4% better than hybrid search and +30.8% better than BM25 on a financial services dataset, and Anthropic’s pipeline retrieved the top 150 candidates and passed the top 20 afterreranking, closing the failure-rate ladder at 1.9%, the 67% reduction the intro promised.
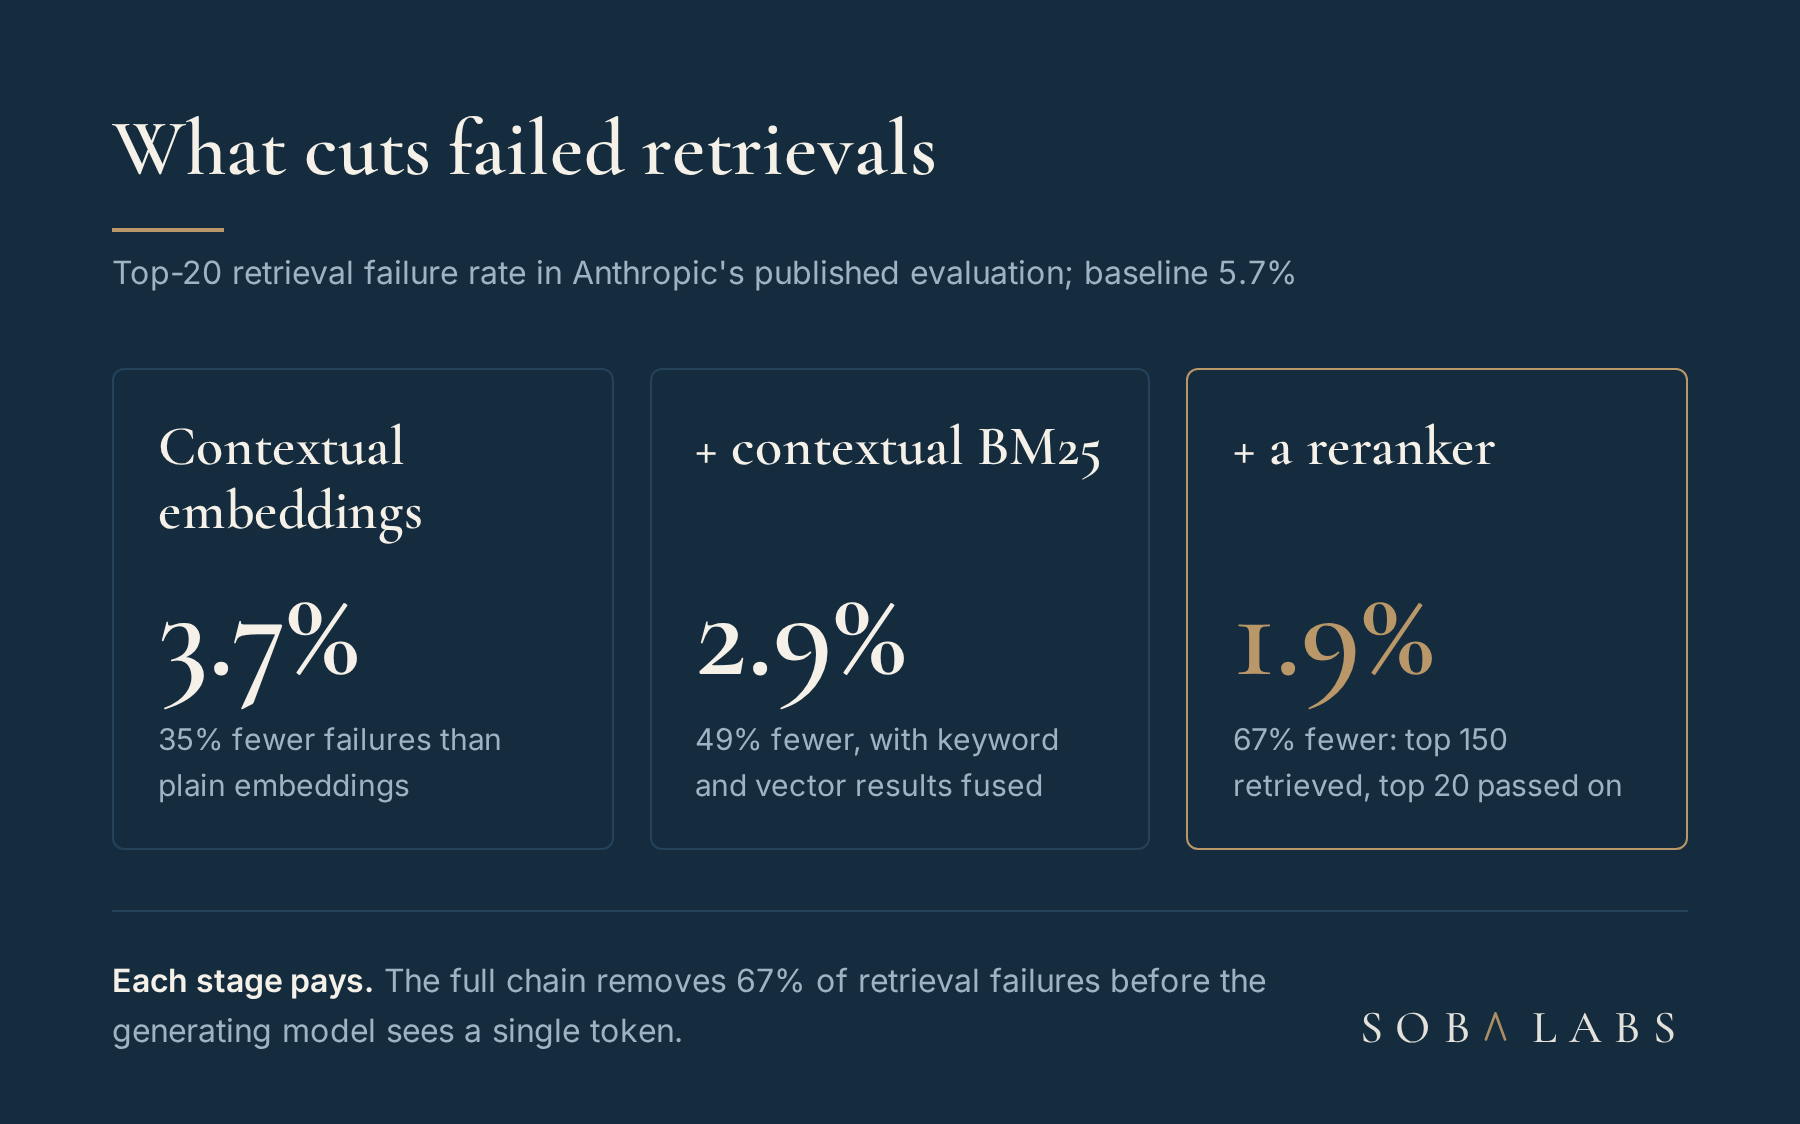 Anthropic’s published failure-rate ladder: each stage pays, and the reranker closes it at 1.9%.The cost is one extra model call per query over a few dozen candidates, plus latency you should measure before you commit. If your error budget has room for exactly one retrieval upgrade this quarter, this is the one with published numbers behind it.
The eval loop is what catches silent decay
A RAG system passes its launch review and then the corpus moves: documents get rewritten, products get renamed, yesterday’s precedents contradict today’s policy.A RAG system decays through its data, not its code, so no deploy-time test will catch it decaying.TheLangSmith RAG evaluation tutorialdecomposes quality into four comparisons instead of one score: correctness (response vs reference answer), relevance (response vs input), groundedness (response vs retrieved docs), and retrieval relevance (retrieved docs vs input). The split is what makes the loop diagnostic. A grounded but irrelevant answer is a retrieval problem; a relevant but ungrounded one is the model freelancing, the failure we took apart inyour agent’s summary is not a source.
Offline datasets cover what you thought to test. Production needsonline evaluation: LangSmith’sonline evaluationsrunLLM-as-a-judgeevaluators against live traces,“to identify issues, measure improvements, and ensure consistent quality over time”, with a sampling rate for cost control, 0.1 to judge a tenth of traces. LangChain’sJanuary 2026 newsletterstates the operating principle we would underline twice:“Production traces become living test cases that shape what you evaluate next”. Wire groundedness and retrieval relevance as online judges and the silent decay stops being silent. Judge calibration is its own discipline, which we covered inLangSmith LLM-as-judge.
What we check before an agentic RAG build ships
The checklist we run before any agenticRAG evaluationgate comes from a production architecture review we did of a knowledge-capture system, one that retrieves rules and past human judgments and writes every correction back as a future precedent. Three checks from it transfer to almost every enterprise RAG build, and they are part of theLangChain implementation workwe get hired for.
**The trap:**a correction captured into the store is not a correction the system will ever retrieve. Whether it resurfaces depends on the relevance threshold and top-N, so a good fix can be saved and never seen again, with no failing test.
First, the write-read round trip: after a human correction is written back, run a near-identical input and assert the new precedent actually appears in the retrieved set. Second, re-run the golden-set regression when the data changes, not only when the code deploys; retrieval breaks silently on a corpus update, which is exactly when nobody is watching CI. Third, record the embedding model version on every record from day one, because models get deprecated, similarity across embedding versions is meaningless, and re-embedding thousands of records is a migration you want planned rather than discovered. None of these require new tooling; all three are assertions your existing test harness can hold.
The takeaway
Enterprise RAG on LangChain is won in the retrieval stack. Choose the smallest architecture that answers your question class, take the documented chunking defaults and add context to the chunks, fuse BM25 with your vector index, and spend your one upgrade on a reranker: that chain, measured end to end in Anthropic’s published evaluation, removes two thirds of retrieval failures before the generating model sees a token. Then treat evaluation as the production half of the system, with online judges for groundedness and retrieval relevance, a round-trip test on every write path, and regressions that fire on data changes. The model will keep improving without you. The retrieval stack is the part of your system that only gets better because you built it that way, the same bet we unpacked inMCP is now built into LangChain.
Sources
- Retrieval, LangChain docs
- Text splitters, LangChain docs
- Build a knowledge base, LangChain docs
- Introducing Contextual Retrieval, Anthropic
- Hybrid search, Weaviate docs
- Rerank overview, Cohere docs
- Introducing Rerank 3.5, Cohere
- Evaluate a RAG application, LangSmith docs
- Online evaluations, LangSmith docs
- January 2026 LangChain newsletter, LangChain blog
Similar Articles
@DanKornas: RAG Playlist What you will learn: - Retrieval Augmented Generation - Document Loaders in LangChain - Text Splitters in …
Tweet announces a RAG Playlist covering topics from basic RAG to advanced techniques like CRAG and Self-RAG using LangChain and LangGraph, with a link in the comments.
AgenticRAG: Agentic Retrieval for Enterprise Knowledge Bases
This paper introduces AgenticRAG, a framework from Microsoft that enhances enterprise knowledge base retrieval by equipping LLMs with tools for iterative search, document navigation, and analysis. It demonstrates significant improvements in recall and factuality over standard RAG pipelines on multiple benchmarks.
@LangChain: LangSmith for Startups Spotlight: @corridor @Corridor uses LangSmith to develop + run novel agentic security evaluation…
LangChain spotlights Corridor, which uses LangSmith to build agentic security evaluations, trace inference pipelines, and manage memory graphs while securing AI coding agents as they write code. Trusted by security teams at companies like Etsy, ElevenLabs, Lovable, and Mercor.
@LangChain: Spend less time on triaging Ship fixes faster Catch regressions earlier Introducing LangSmith Engine: an agent that wor…
LangChain launches LangSmith Engine in public beta, an autonomous agent that monitors production traces, clusters failures, diagnoses root causes, and proposes fixes and eval coverage to streamline agent development.
@tom_doerr: Builds production-grade RAG systems and Agentic workflows https://github.com/jamwithai/production-agentic-rag-course…
A learner-focused project that teaches building production-grade RAG systems and agentic workflows, covering keyword search, hybrid retrieval, and LangGraph agent integration.