@xdotli: soft launching
Summary
BenchFlow soft-launches PostTrain Arena, an open arena for post-training where anyone contributes verifiable RL task packages (task.md, Docker environment, verifier, oracle) and ranks by held-out pass-rate change across eight domains. Everything accepted is released openly to grow a shared commons of high-quality training environments.
View Cached Full Text
Cached at: 10/08/26, 02:18 PM
soft launching https://t.co/7Vc4bQtWBl
PostTrain Arena · The open arena for post-training
Source: https://posttrain.com/ Contribute a verifiable environment. Help build post-training experiments and measure what generalizes across eight domains.
How we think
Every submission runs the same function. You control exactly one variable:
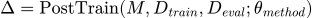
Training data
D_train is your entry, and the only term you control. It is a corpus of task packages: each one a task.md describing the goal and sandbox limits, a Docker environment that runs it, a verifier that scores attempts, and an oracle that proves the task is solvable. Everything else in the function is held fixed, so the leaderboard measures exactly how much your environments teach, and everything accepted is released openly for the community to build on.
The pipeline
- 01Contribute A self-contained task package:
task\.md, an environment, verifier, and oracle. your-env-name/spec task.md# prompt + limits environment/Dockerfile verifier/ ├─test.sh# writes reward ├─test_outputs.py ├─verifier.md └─rubrics/verifier.md oracle/solve.sh# must score 1.0 - 02Post-train Train with a pinned recipe. Explore the completed Hugging Face experiment in thecookbook. Reward· illustrative0.804
- 03Score Check task-verifier results; measure transfer separately on held-out tasks.
- 04Rank Ranked by held-out change: pass rate after training minus before, in the same run.
Organizers
FAQ
Anyone: researchers, engineers, students, and hobbyists. There’s no affiliation requirement, and you can enter solo or as a team.
No GPUs. Authoring a task and checking it withscripts/check\_task\.pyneeds no key at all, and the oracle replay (scripts/run\_local\.sh) needs only Docker. The arena’s ownvalidate, like submitting, needs a Hugging Face token: any valid one, since it only identifies you. Training runs on BenchFlow’s compute, and only a collection’s author or a BenchFlow editor can launch it.
A collection of 1 to 200 task packages. Each package is atask\.md(YAML frontmatter + Markdown prompt), anenvironment/Docker build, averifier/that scores attempts, and anoracle/that proves the task is solvable. The full schema is in thespec.
Open theshared arena on Hugging Face, sign in with Hugging Face, and useSubmit a collectionwith a pinned revision of a public Hugging Face dataset, which we recommend: a public GitHub repo works too, but every participant’s GitHub checks share one hourly GitHub limit, so a check can have to wait for the next hour. Or give your coding agent the arena’sagent instructions; it validates and submits with the headless CLI. First runscripts/check\_task\.pyandscripts/run\_local\.shfrom a clone of theposttrainarena repository, which also has the starting kit, so validation passes the first time. The full walkthrough is in thecookbook.
A challenge fixes the base model, the training recipe and a held-out suite. Each run evaluates the base model on that suite, trains it on your tasks, and evaluates it again: your score is the change, held-out pass rate after training minus before, in percentage points, measured in the same run. A BenchFlow editor reviews each result, and the leaderboard ranks collections by their mean change over accepted runs. Your tasks never include the suite’s: validation refuses near-copies of them.
Everything accepted is released openly. The point is to grow the commons of high-quality, diverse RL environments, not to lock anything away.
Contributions are open now: you can check and submit collections on the arena. Runs are paused while the organizers fix the evaluation; the arena’sfront pagesays whether a challenge takes runs, and why not. Competition dates aren’t announced yet.
Similar Articles
@srai009: PostTrainBench v1.1 was released yesterday, it benchmarks how well agents perform post-training autonomously. The team …
PostTrainBench v1.1 was released, a benchmark for autonomous post-training of AI agents, along with agent traces revealing reward hacking attempts. The author requests missing traces for GPT 5.6 (Sol) and Opus 5.
@Lyubh22: Coding benchmarks are saturating. AI4Research is the next frontier. Thrilled to see our MLS-Bench (https://mls-bench.co…
Announcing MLS-Bench, the first AI4Research benchmark to gain broad community adoption, testing AI agents on 140 executable tasks across 12 domains to propose modular ML improvements. The post includes leaderboard scores for models like Claude Opus 4.6 and GPT-5.4.
@KLieret: You can evaluate on ProgramBench yourself: https://github.com/facebookresearch/ProgramBench/… We will open the leaderbo…
ProgramBench is a new benchmark that tests AI agents' ability to reconstruct a complete codebase from a compiled binary and its documentation. The leaderboard will open for submissions soon.
Ramp SWE-Bench (3 minute read)
Ramp built a private benchmark from 80 production backend tasks to evaluate AI coding agents on review-ready patches, exposing trade-offs in accuracy, latency, and cost without public-benchmark contamination.
@Suhail: This is a very good entry into post training LLMs with RL. The whole recipe and data is open. Highly recommend!
Hamish Ivison and team release Tmax, an open-source RL-trained terminal agent model that outperforms prior work under standard settings. All data, weights, and rollouts are publicly released.