@kyutai_labs: Introducing REKI, a 2.4B vision-language-action model pretrained on public data only. With a simple design, it rivals l…
Summary
Kyutai Labs introduces REKI, a 2.4B vision-language-action model pretrained exclusively on public data that sets a new Pareto frontier between performance and model size, using a simple design with register-token memory in the action expert. Full code, data curation pipelines, and all pretrained/finetuned weights are released.
View Cached Full Text
Cached at: 10/16/26, 04:45 PM
Introducing REKI, a 2.4B vision-language-action model pretrained on public data only. With a simple design, it rivals larger models trained on in-house data with complex multi-stage pipelines, setting a new Pareto frontier between performance and size. https://t.co/fKi8HyT7Vh https://t.co/AN2cUU1Tc7
REKI: Registering Knowledge in VLAs
Source: https://kyutai.org/reki/ Registering Knowledge in VLAs
Juliette Marrie1, Paul Pacaud2, Adrien Ramanana Rahary1,3, Shizhe Chen2, and Moritz Böhle1
We introduce REKI, a 2.4B vision-language-action model (VLA) pretrained exclusively on public data that sets a new Pareto frontier between performance and model size: on LIBERO-Plus, RoboTwin Clean2Rand and RoboCasa365, it is outperformed only by models about twice its size. REKI consists of a vision-language model (VLM) followed by a flow-matching action expert, and is pretrained on a curated mixture of public robot, egocentric human and vision-language data. Additionally, we endow it with a memory that gives the policy access to its recent past at negligible cost: a few register tokens in the action expert summarize the output of the VLM at each frame and persist in the expert’s cache. This memory improves success in simulation and on real robots, and makes oscillations between poses about four times rarer. REKI uses a simple model design and training paradigm, and is optimized to be efficient at training and inference. We release the full code across data curation, training, inference and evaluation, deployment, and all pretrained and finetuned model weights.
808590234567parameters (B)success rate (%)REKI
Success rate against model size.REKI sets a new Pareto frontier between performance and model size: it scores highest on LIBERO-Plus, and is only outperformed by models about twice its size on RoboTwin Clean2Rand and RoboCasa365. Hover over a point or a legend entry to identify the models.
Autonomous rollouts of REKI on a UR5 arm, at 3× speed. REKI is finetuned for 3k steps (1h of training) on 50 demonstrations per task.
Memory in the action expert
Intuitively, past context should help a robot act, but it is not clear how best to use it in a VLA. Current methods put past frames into the vision-language backbone, unroll the model during training, or add a separate memory module, and each of these adds training or inference cost. REKI puts the memory in the action expert: a small set of register tokens summarizes each encoded frame and is cached across chunks, so each frame is encoded only once, with no separate module and no sequential unroll.
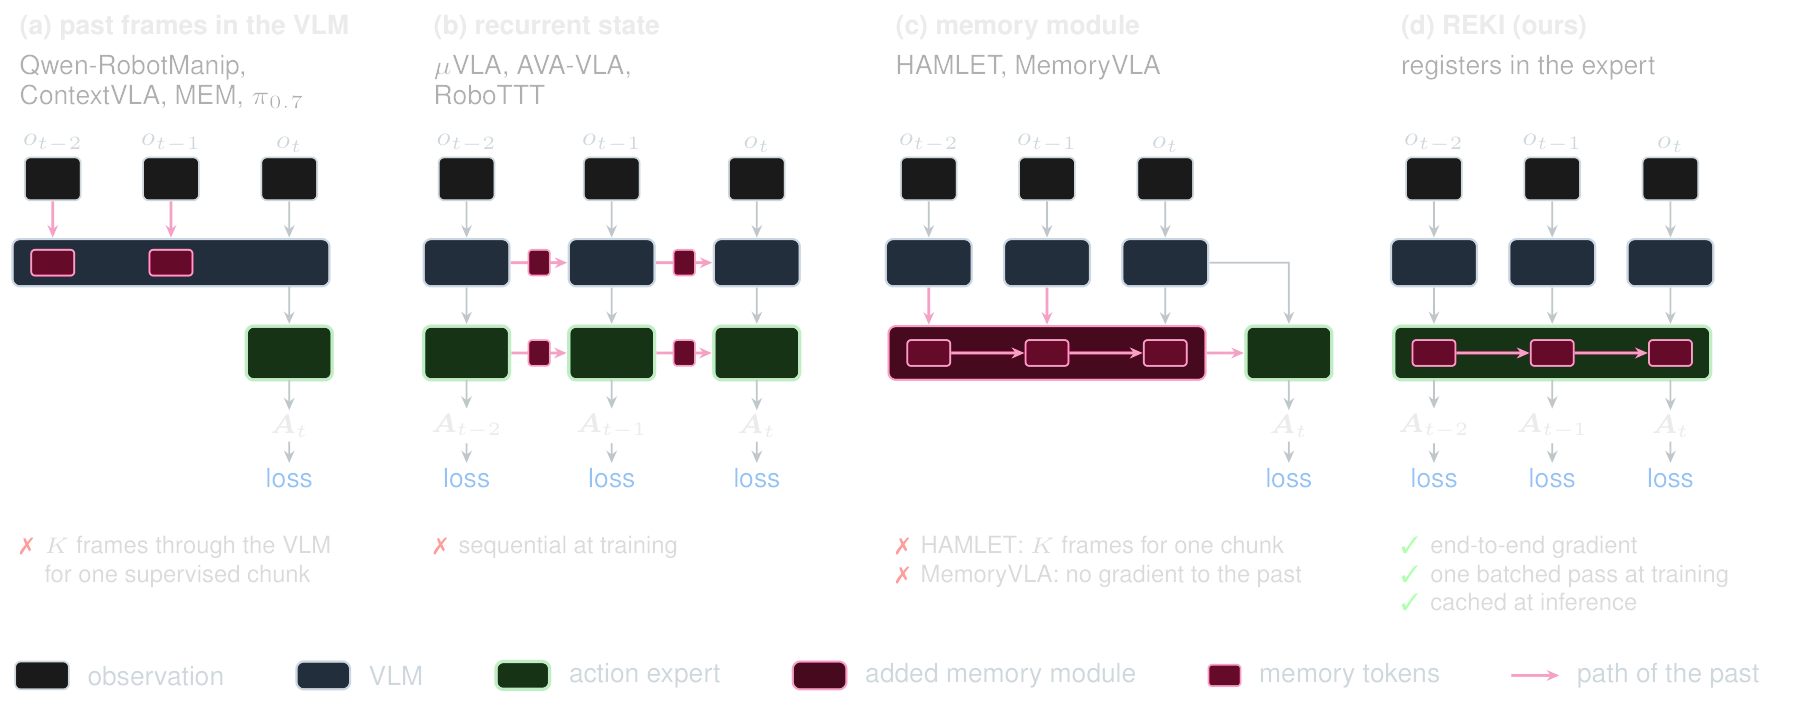
How VLAs carry the past, over one training window of three frames: (a) past frames in the VLM, (b) a recurrent state, (c) an added memory module. (d) In REKI, the memory tokens are registers in the action expert, read by the self-attention already present. The window is one batched pass, and every frame receives a loss.
Model
A Qwen3.5-2B vision-language backbone encodes the camera views and the instruction as a context, which every block of a 200M-parameter flow-matching action expert reads by cross-attention. Robot state and flow time modulate the actions through adaptive normalization. In the expert, the action tokens of each frame are preceded by 32 learned register tokens. The registers cross-attend the encoded prompt and views of that frame, and self-attend the registers of the earlier frames. Since they do not attend the action tokens, they depend only on the observations and can be shared across frames and denoising steps.
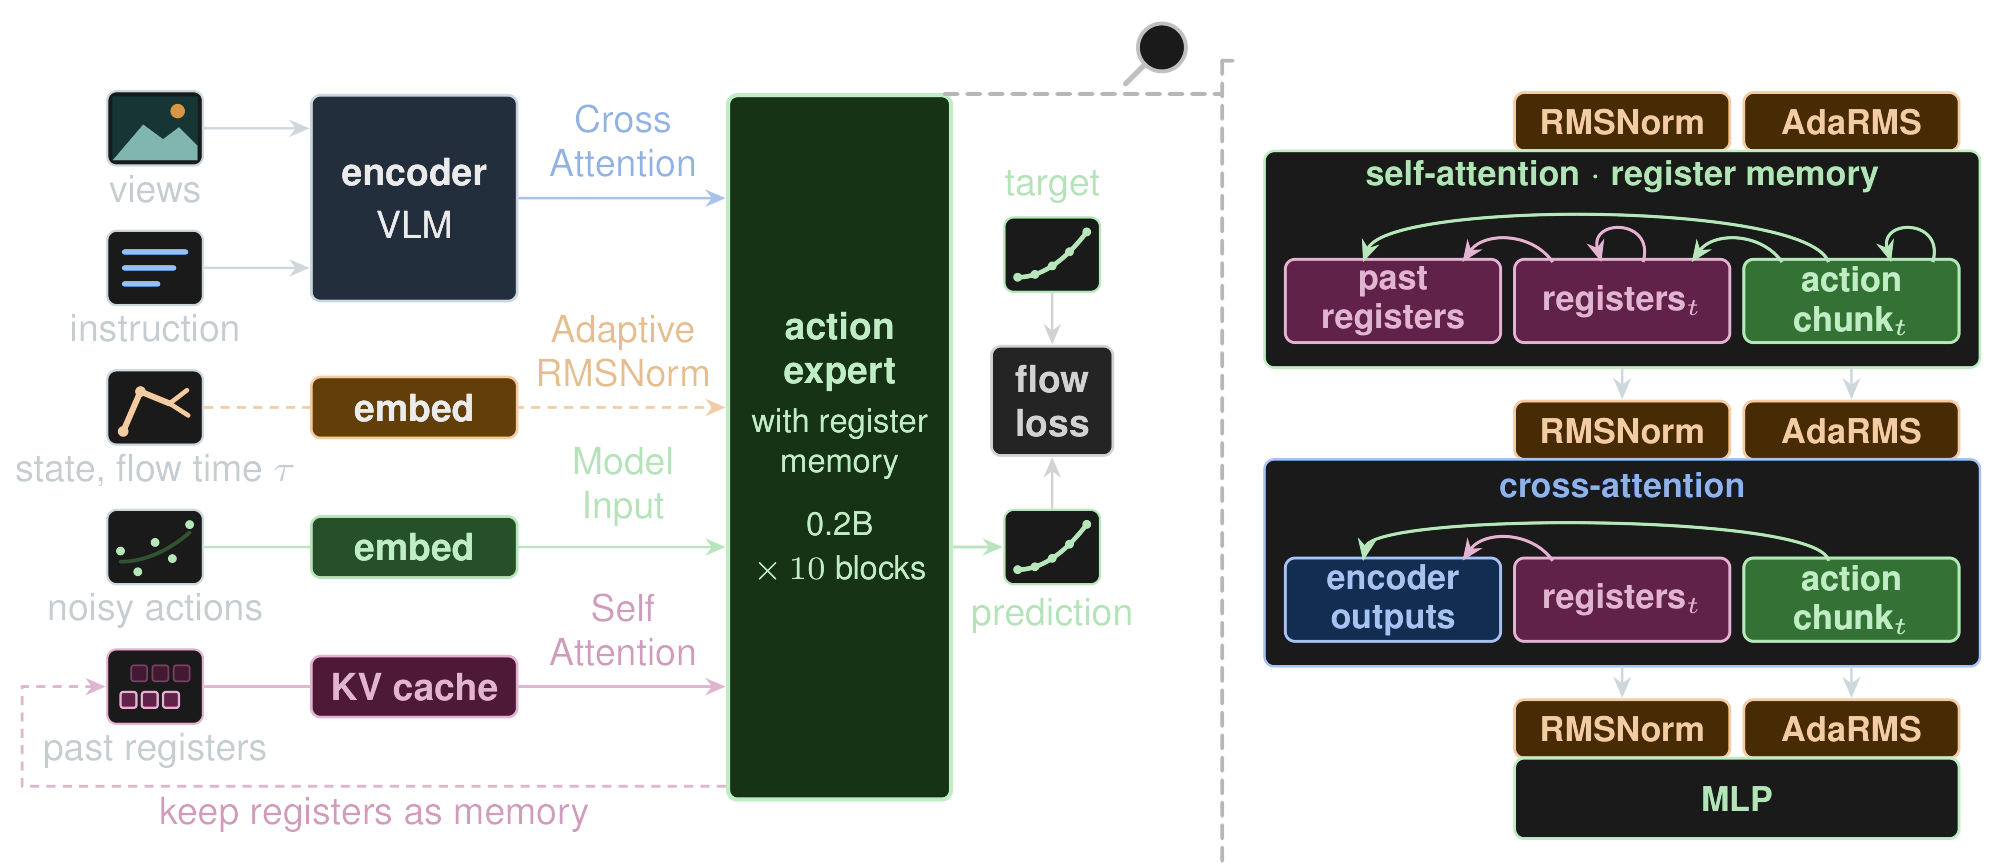
Left:REKI. The register keys and values of past frames are kept in a cache and read by self-attention.Right:one expert block. Action tokens read the current and past registers and themselves, and registers never read them.
We train on windows ofK= 3 frames from one episode, taken one second apart. At inference, the keys and values of the registers are cached in a rolling window over theK− 1 preceding frames: when a new frame enters, the registers of the oldest one are dropped.
One step, then memory over time.The registers summarize the current frame and stay fixed during denoising. Their keys and values are cached, and the actions of later frames read them.
Memory at almost no cost
The memory is cheap at training and at inference.
- Training.A window ofKframes is packed into one batch and encoded in a single pass, so it costs no more VLM compute thanKmemoryless frames. In the expert, registers and action tokens are attended by one variable-length FlashAttention call, and the loss of each frame is averaged over eight independent noise draws that share one VLM pass.
- Inference.The registers depend on neither the flow time nor the robot state, so they are computed only once per frame, in the first denoising step. Their keys and values are cached and reused in the other denoising steps and in the nextK− 1 frames. WithK= 3, predicting an action chunk from two 256×256 images takes 21.8 ms on one H100, and reading the cached registers adds 0.1 ms. The cache adds about 2 MiB of GPU memory per past frame.
VLM prefillEuler loop (10 steps)other
051015202530ms per chunk−0.6noneref.1+0.02+0.13+0.34+0.58+1.116+1.932+3.564memory window K in frames (none: no registers; trained with K = 3)
Time of one action chunk on one H100 against the memory windowK(two 256×256 cameras, ten Euler steps, VLM and action expert as CUDA graphs; median of 400 chunks, whiskers 10th to 90th percentile). Labels give the change againstK= 1. Hover over a bar for its split.
Fast inference
We time one call, from the raw observation to the actions of one chunk, on one H100 with LIBERO inputs, for each model with its released checkpoint and code. Most of these models are released without a compiled path, or with one that can be further optimized, so we also compile them ourselves without changing their computation. With compilation, REKI predicts a chunk in 21.8 ms, the fastest of the compared models: X-VLA takes 25.5 ms, π0.5(openpi) 33.8 ms, ABot-M0 46.1 ms and InternVLA-A1.5 51.3 ms. InternVLA-A1.5 uses the same VLM as REKI, but its larger action expert increases the denoising time.
Inference latency
0306090120ms per chunkREKI (ours)(2.4B)21.8 msX-VLA(0.9B)25.5 msπ0.5,openpi(3.3B)33.8 msπ0.5,LeRobot(3.3B)49.1 msABot-M0(4.6B)46.1 msInternVLA-A1.5,released compiled(2.7B)94.2 msInternVLA-A1.5,compiled by us(2.7B)51.3 msABot-M0.5(5B)1.4 s
GPU timehost timecompiled by us
Inference latencyof one action chunk on one H100, from the raw observation to the actions, with LIBERO inputs. Dark: GPU time; light: host time. Dashed: compiled by us.
Benchmark results
REKI is pretrained once, then finetuned on each benchmark separately:
- LIBERO-Plusperturbs the 40 LIBERO tasks along seven axes: camera viewpoint, initial robot state, language, lighting, background, sensor noise and object layout.
- RoboTwin 2.0 Clean2Randevaluates models finetuned on clean scenes only under randomized background, lighting, clutter and table height, separately and combined.
- RoboCasa365evaluates models trained on its 300 kitchen tasks on 50 target tasks in three groups: atomic, composite seen and composite unseen.
Among the models pretrained on public data, REKI has the highest out-of-distribution success on LIBERO-Plus and RoboTwin Clean2Rand, although it is the smallest. On RoboCasa365, it reaches 38.4, ahead of the larger RLDX-1 (36.0) and Qwen-RobotManip (35.9), both pretrained on in-house data.
RoboTwin Clean2Rand
020406080success rate (%)With pretrainingNo pretrainingQwen-RobotManip(4.7B)68.5REKI (ours)(2.4B)65.8π0.5(3.3B)63.8ABot-M0(4.6B)55.7GR00T-N1.7(3.1B)35.5Qwen-RobotManip(4.7B)52.3REKI (ours)(2.4B)52.0StarVLA(4.5B)36.6
LIBERO-Plus
406080100success rate (%)With pretrainingNo pretrainingREKI (ours)(2.4B)90.4Qwen-RobotManip(4.7B)89.0RLDX-1(6.9B)86.7ACoT-VLA(3.8B)86.6π0.5(3.3B)85.7InternVLA-A1.5(2.7B)84.8Being-H0.7(3B)84.0ABot-M0.5(5B)83.7ABot-M0(4.6B)80.5π0(3.2B)69.4REKI (ours)(2.4B)86.1Qwen-RobotManip(4.7B)78.3StarVLA(4.5B)75.0
RoboCasa365
0306090success rate (%)Xiaomi-Robotics-1(5.1B)57.4ABot-M0.5(5B)40.4REKI (ours)(2.4B)38.4RLDX-1(6.9B)36.0Qwen-RobotManip(4.7B)35.9GR00T-N1.5(2.4B)23.9GR00T-N1.6(3.0B)21.9π0.5(3.3B)16.9
public datapretrained on in-house dataworld-action model
Success rateon RoboTwin Clean2Rand, LIBERO-Plus and RoboCasa365. Bars give the mean, ticks the conditions (RoboCasa365: the three task groups). Pick a condition to rank the models on it.
Pretraining on public data helps most out of distribution, and most where REKI without pretraining fails: it adds 13.8 points on Clean2Rand, including 30.3 under clutter and 22.4 under the Hard condition, and 4.3 on LIBERO-Plus.
Memory and repetitive motion
Memory improves success on all three benchmarks, and most of the gain already comes with one past frame. Removing the past frames at evaluation brings the model back to the level of a memoryless one, so the gain comes from reading the past at inference.
LIBERO-Plus
7075808590953→33→23→11→190.490.188.988.9
RoboTwin Clean
5560657075803→33→23→11→173.473.667.267.9
RoboCasa365
atomiccomp-seencomp-unseen
0204060803→33→23→11→138.439.334.933.0
Kat finetuning →Kat evaluation
Memory window, written as frames at finetuning → frames at evaluation: success rate. RoboCasa365: the bar gives the three task groups, the line the average. Hover over a bar for its values.
Without memory, the policy often gets stuck moving an arm back and forth between two poses, switching direction at each new chunk.
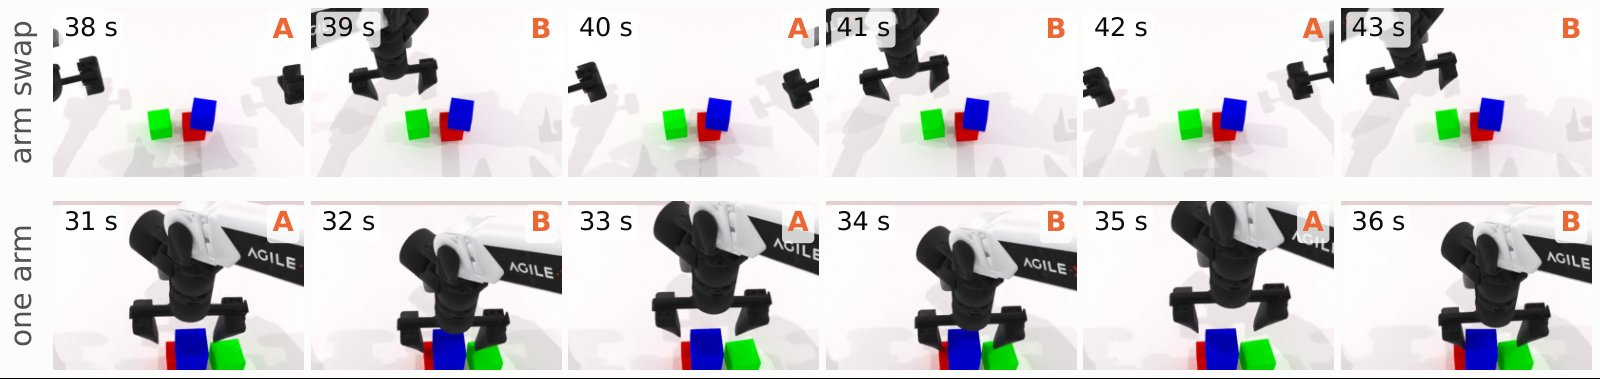
Oscillation without memory.Two RoboTwin rollouts of REKI trained without memory. Frames are one chunk (one second) apart, and A and B mark the two poses the arm alternates between.
With memory, such oscillations are about four times rarer on RoboTwin (4.1% of the episodes against 18.6%), and the difference is largest in two-arm tasks.
by memory window
05101520253→33→23→11→14.14.614.818.6
by task class
0510152025one-armtwo-arm15.85.224.53.1
1→13→3
Oscillation.Left: share of oscillating episodes on RoboTwin Clean, by memory window. Right: oscillating episodes by task class, without (1 → 1) and with (3 → 3) memory.
We attribute this to perceptual aliasing: if two poses each look like demonstrations that continue towards the other, a memoryless policy alternates between them. A short history resolves the ambiguity.
Public data only
REKI is pretrained for 200k steps on 32 H100 GPUs, on a mixture of public data only:
- Robot manipulation.Public teleoperation datasets (RoboSet, Galaxea, AgiBot World, RoboCOIN, RoboMIND, RDT-1B, DROID, BridgeData V2, RT-1, BC-Z), complemented by motion-planned simulation from InternData-A1 and GR00T-X-Embodiment-Sim and bimanual YAM demonstrations from ABC.
- Egocentric human manipulation.EgoDex, EgoVerse and Xperience, about 350k episodes and 170M frames.
- Vision-language data.The FineVision and LLaVA-OneVision-1.5 subsets most relevant for spatial reasoning, plus RoboPoint, RefSpatial and PixMo, at 10% of the sampled frames.
We keep each dataset’s native control convention rather than remapping to a shared action space, and we curate every source before training. As REKI is trained only on public data, it is fully reproducible by the scientific community.
Released models
Thecodecovers training, evaluation on all benchmarks, the data processing pipeline and a real-robot policy server.
from reki import RekiPolicy

policy = RekiPolicy.from_pretrained("kyutai/reki-2b-libero", device="cuda")
policy.reset()  # at every episode start: clears the register cache
actions = policy.predict(
    images={"camera_top": img0, "camera_wrist_left": img1},
    state=proprio,
    task="put the bowl on the plate",
)  # [n_action_steps, action_dim]
Citation
@article{marrie2026reki,
  title   = {{REKI}: Registering Knowledge in {VLAs}},
  author  = {Marrie, Juliette and Pacaud, Paul and Ramanana Rahary, Adrien and Chen, Shizhe and B{\"o}hle, Moritz},
  journal = {arXiv:2610.22178},
  year    = {2026}
}
Similar Articles
Kimi K3: Open Frontier Intelligence
Kimi introduces Kimi K3, a 2.8 trillion parameter open model with native vision and 1M context, built on Kimi Delta Attention and Attention Residuals. It achieves frontier-level performance in coding and reasoning, with full weights to be released by July 2026.
@KaiZhang_CS: Check out one of the best open-source search agents trained by @jianxie_ !! glad to see early experience methods work o…
Yu Su's team trained a frontier Deep Research Agent on an academic budget using 8K synthetic samples and RL, releasing fully open training infrastructure and models from 2B to 35B parameters.
ReToken: One Token to Improve Vision-Language Models for Visual Retrieval
ReToken introduces a single learnable retrieval token that selects sparse query-relevant visual tokens from a pre-filled visual KV cache, improving long-context vision-language model performance on visual retrieval tasks. It yields consistent gains across image and video benchmarks while enabling efficient long-video inference on a single H100.
Kwai-Keye/Keye-VL-2.0-30B-A3B
Kwai-Keye releases Keye-VL-2.0-30B-A3B, a 30B-class vision-language model with advanced video understanding, sparse attention, and agent capabilities, achieving top benchmarks.
DeepReinforce releases Ornith-1.0 open-source coding models (2 minute read)
DeepReinforce open-sources Ornith-1.0, a family of self-improving coding models from 9B to 397B parameters, trained on Gemma 4 and Qwen 3.5 foundations, featuring a novel RL approach that learns to generate its own scaffolds.