@reprompting: reading about the NVIDIA hopper architecture today https://arxiv.org/pdf/2501.12084
Summary
这篇论文对 NVIDIA Hopper GPU 架构进行了多层级微基准测试分析,评估了 L2 分区缓存、第四代张量核心(FP8)、DPX 指令、分布式共享内存(DSM)和张量内存加速器(TMA)等新特性的性能表现,结果显示 TMA 异步编程可实现 1.5 倍矩阵乘法加速,FP8 性能接近 FP16 的两倍,DPX 指令可加速生物信息学算法至少 4.75 倍。
View Cached Full Text
Cached at: 10/01/26, 06:17 AM
reading about the NVIDIA hopper architecture today
https://t.co/CrPtjPkcId https://t.co/MIL0MUVG17
Dissecting the NVIDIA Hopper Architecture through Microbenchmarking and Multiple Level Analysis
Source: https://arxiv.org/html/2501.12084 ††footnotetext:This work is based on and extends “Benchmarking and Dissecting the Nvidia Hopper GPU Architecture” published in IPDPS 2024. This article expands previous work by adding new tests on L2 partitioned cache, energy consumption of tensor core instructions, comprehensive distributed shared memory evaluations, application-level DPX instruction tests, and benchmarking TMA performance under asynchronous programming on Hopper. The artifact is available onhttps://github.com/HPMLL/NVIDIA-Hopper-Benchmark.## Dissecting the NVIDIA Hopper Architecture through Microbenchmarking and Multiple Level AnalysisThanks:Qiang Wang and Xiaowen Chu are the corresponding authors.
DOI:XXXXXXX.XXXXXXXJournal:JACMVolume:3741118CCS:General and reference MeasurementCCS:General and reference EvaluationCCS:General and reference PerformanceCCS:Computer systems organization Parallel architecturesWeile LuoAffiliation:The Hong Kong University of Science and Technology (Guangzhou),Guangzhou,Chinaemail:[email protected]Ruibo FanAffiliation:The Hong Kong University of Science and Technology (Guangzhou),Guangzhou,Chinaemail:[email protected],Zeyu LiAffiliation:The Hong Kong University of Science and Technology (Guangzhou),Guangzhou,Chinaemail:[email protected],Dayou DuAffiliation:The Hong Kong University of Science and Technology (Guangzhou),Guangzhou,Chinaemail:[email protected],Hongyuan LiuAffiliation:The Hong Kong University of Science and Technology (Guangzhou),Guangzhou,Chinaemail:[email protected],Qiang WangAffiliation:Harbin Institute of Technology, Shenzhen,Shenzhen,Chinaemail:[email protected]andXiaowen ChuAffiliation:The Hong Kong University of Science and Technology (Guangzhou),Guangzhou,Chinaemail:[email protected]
Received 5 June 2009
Abstract.
This study presents a comprehensive multi-level analysis of the NVIDIA Hopper GPU architecture, focusing on its performance characteristics and novel features. We benchmark Hopper’s memory subsystem, highlighting improvements in the L2 partitioned cache and global memory access compared to Ampere and Ada Lovelace. The evaluation of Hopper’s fourth-generation tensor cores reveals the benefits of FP8 precision and asynchronouswgmmainstructions for matrix operations. Additionally, we investigate the performance of DPX instructions for dynamic programming, distributed shared memory (DSM) for inter-SM communication, and the Tensor Memory Accelerator (TMA) for asynchronous data movement. Through multi-level evaluation, we discover that the Hopper architecture demonstrates significant acceleration potential in real-world applications. For instance, the asynchronous programming model supported by TMA achieves a 1.5× speedup in matrix multiplication, FP8 delivers nearly double the performance of FP16, and DPX instructions accelerate a computational biology algorithm by at least 4.75×. Our findings provide actionable insights for optimizing compute-intensive workloads, from AI training to bioinformatics, on Hopper GPUs.
Keywords:
Instruction Benchmark, Tensor Core, PTX, Hopper, DPX, Tensor Memory Accelerator, Distributed Shared Memory, GEMM with TMA, Smith-Waterman Algorithm, Low-Precision Acceleration, Application-Level Benchmarking.
1.Introduction
The increasing prevalence of GPUs has significantly accelerated a diverse range of computational workloads, from scientific computing to artificial intelligence, particularly with the rise of large language models (LLMs) such as GPT-3, with over 150 billion parameters(Floridi and Chiriatti, 2020). Modern GPU architectures such as Ampere, Ada, and Hopper, incorporate specialized hardware like tensor cores and high-bandwidth memory systems, purpose-built for AI applications. As a result, GPUs have become indispensable components in high-performance computing clusters.
NVIDIA maintains a two-year release cycle for new GPU architectures, ensuring the continuous integration of novel architectural features. However, the scarcity of detailed micro-architectural specifications hinders precise performance analysis, necessitating deeper investigations to understand the impact of these advancements on application performance. Such comprehensive architectural understanding is fundamental for several critical applications: accurate performance and power modeling for energy-efficient computing(Hong and Kim, 2010;Braun et al., 2021;Wang et al., 2019;Wang and Chu, 2020;Mei et al., 2017;Arafa et al., 2020;van Stigt et al., 2022;Arafa et al., 2019), the development of robust GPU simulators that enable cost-effective research and development(Khairy et al., 2020;Bakhoda et al., 2009;Leng et al., 2013), and the effective optimization of applications across diverse domains from AI training to scientific computing(Bakhoda et al., 2009;Ho and Wong, 2017;Yan et al., 2020b). Without detailed microarchitectural insights, developers cannot fully exploit the potential of modern GPUs, leading to suboptimal performance and energy efficiency.
The evolution of tensor cores (TCs) exemplifies this trend. Introduced in the Volta architecture to accelerate deep neural networks using FP16/FP32 operations, TCs have been progressively enhanced. Ampere and Hopper continue to increase support for different precisions, providing more space for research on LLM. Thus, the reliance on assembly analysis and microbenchmarks from older architectures (Ampere and Turing) highlights the need for Hopper-specific TC research.
Beyond enhanced TCs, the Hopper architecture introduces several key innovations. Dynamic Programming X (DPX) instructions accelerate dynamic programming algorithms, which often rely on comparisons (min/max operations) between previously computed results. Distributed shared memory (DSM) enables direct communication between Streaming Multiprocessors (SMs), facilitating loads, stores, and atomic operations across their respective shared memory blocks. Finally, the Tensor Memory Accelerator (TMA) provides an asynchronous data movement mechanism between hardware components. However, the implementation details and performance characteristics of the TMA remain largely unexplored in the existing literature. A comprehensive understanding of these aspects is crucial for developers seeking to optimize compute-intensive workloads, enable accurate performance modeling, and design efficient algorithms that can fully exploit the potential of modern GPUs. Further research is needed to fully understand the interplay of these features and their combined effect on diverse workloads.
This article extends our previous conference paper(Luo et al., 2024), which explored the basic performance of the memory subsystem, a multi-level comparison of fourth-generation tensor cores with previous architectures, and a simple analysis of DPX and Distributed Shared Memory. In this work, we expand both the depth and breadth of our research. In terms of depth, we further analyze the memory subsystem. After various comparisons, we find that some traditional benchmarks are not suitable for Ampere and Hopper. We conduct new tests on the L2 partitioned cache for Ampere and Hopper, overturning previous data and conclusions. Additionally, we include energy consumption tests forwgmmain the tensor core, revealing the power impact of new instructions. We also perform a comprehensive evaluation of distributed shared memory (DSM), assessing DSM interface costs, expanding cluster numbers in latency tests, and testing throughput with different access patterns and thread block scheduling policies. Furthermore, we incorporate application-level testing to further demonstrate the advantages and limitations of DPX instructions. In terms of breadth, with the rise of asynchronous programming, we benchmark the TMA on Hopper to characterize its performance within asynchronous programming paradigms.
In this study, we conduct a comprehensive multi-level benchmarking of the latest GPU architectures (Ampere, Ada, and Hopper). Additionally, we test Hopper’s new features (DSM, TMA, and DPX). To our knowledge, this is the most comprehensive and in-depth benchmarking of the Hopper architecture. Our research presents a pioneering analysis of the new programming interfaces specific to the Hopper architecture, offering a unique horizontal performance comparison among these cutting-edge GPU architectures. Many of our findings are novel and being published for the first time, providing valuable insights. We highlight the contributions of our work as follows:
∙\bulletWe systematically benchmark the latency and throughput of Hopper GPUs, including the memory subsystem, tensor cores, distributed shared memory (DSM), tensor memory accelerator (TMA), and dynamic programming instructions (DPX). We compare the latency and throughput of these Hopper-specific units with their predecessors in Ampere and Ada Lovelace architectures, highlighting the performance improvements and trade-offs introduced in Hopper.
∙\bulletWe perform amulti-level analysisof Hopper’s critical components, benchmarking them at the instruction, library, and application levels. For the tensor core benchmark, we include tests at the library level of the transformer engine and real LLM generation applications. In DSM, we consider different access patterns in high-performance computing to provide valuable references for real applications. In both DSM and DPX, we employ real-world applications for evaluation to explore the practical potential of these new features.
∙\bulletOur research explores the unique features of the Hopper architecture comprehensively, including the L2 partitioned cache,wgmmainstructions, DPX, TMA, and DSM. These innovations have the potential to significantly enhance GPU programming methodologies. By evaluating their performance, our study contributes to performance modeling and algorithm design in dynamic programming and scientific computing, potentially unlocking the full performance potential of GPUs and driving advancements in the field.
The remainder of this paper is organized as follows. Section2reviews related work. Section3briefly introduces the Hopper architecture and its new features. In Section4, we delve into the latency and throughput of the GPU memory subsystem. Section5examines the latency and throughput of the tensor memory accelerator. Section6evaluates the tensor core at the instruction level, the transformer engine at the library level, and LLMs at the application level. Sections7and8respectively benchmark distributed shared memory and DPX instructions. Finally, Section 9 summarizes the findings.
2.Related Work
The rapid evolution of GPU architectures necessitates continuous investigation into their microarchitectural details, particularly at the instruction level. This understanding is fundamental for accurate performance and power modeling(Hong and Kim, 2010;Braun et al., 2021;Wang et al., 2019;Wang and Chu, 2020;Mei et al., 2017;Arafa et al., 2020;van Stigt et al., 2022;Arafa et al., 2019), the development of robust simulators(Khairy et al., 2020;Bakhoda et al., 2009;Leng et al., 2013), and the effective optimization of applications(Bakhoda et al., 2009;Ho and Wong, 2017;Yan et al., 2020b). Prior research has addressed these needs across different GPU generations, but the introduction of novel features in recent architectures, such as Hopper, demands a renewed focus.
Early efforts to dissect GPU microarchitecture primarily focused on older generations like Fermi, Kepler, and Maxwell(Wong et al., 2010;Mei et al., 2014;Mei and Chu, 2017). These studies, along with investigations into performance and power characteristics(Jia et al., 2018;Jia et al., 2019)and software-level scheduling frameworks(Shekofteh et al., 2020), laid the groundwork for understanding fundamental GPU behavior and informed subsequent investigations into more recent architectures like Volta and Turing. The emergence of tensor cores (TCs) in Volta, specialized hardware units designed to accelerate matrix operations crucial for AI workloads, marked a significant shift in GPU architecture and spurred a new wave of research.
The importance of fused matrix multiplication accumulation (MMA) in AI has driven extensive research into TCs. Initial studies on Volta’s TCs centered on the legacywmmaAPI and employed benchmarks using established libraries like CUBLAS and CUTLASS(Markidis et al., 2018;Martineau et al., 2019). Further work extended this analysis to Turing, incorporating preliminary assembly code analysis ofwmmainstructions(Jia et al., 2018;Jia et al., 2019). However, these initial explorations lacked the comprehensive instruction-level microbenchmarks needed to fully characterize TC performance and numerical behavior.
Subsequent research delved deeper into TC analysis on Volta and Turing, utilizing assembly-level (SASS) benchmarking to uncover optimization opportunities for matrix multiplication, particularly in half-precision(Yan et al., 2020a;Yan et al., 2020b;Raihan et al., 2019). The numerical intricacies of TCs, including rounding modes and subnormal number handling for various data types like TF32, BF16, and FP16, were also investigated(Fasi et al., 2021). However, the limitations of thewmmaAPI, particularly its inability to fully leverage new features like sparse matrix multiplication introduced in Ampere and later architectures, became increasingly apparent(Markidis et al., 2018;Fasi et al., 2021).
The introduction of themmaAPI with Turing addressed some of these limitations and evolved to support sparse matrix multiplication (mma.sp) on Ampere and beyond. Sun et al.(Sun et al., 2023)conducted a thorough analysis of themmaAPI on Turing and Ampere, exploring TC performance, numerical behavior, and sparse matrix multiplication capabilities. However, the arrival of Hopper introduced further complexity with the addition ofwgmmaand an expanded set ofmmainstructions supporting a broader range of precisions. This necessitates new research to understand the performance characteristics and optimal utilization of these new instructions, a gap addressed by our work.
Beyond TC-specific research, previous work has also addressed energy efficiency in GPUs using static(Hong and Kim, 2009;Hong and Kim, 2010;Braun et al., 2020;Fan et al., 2019)and dynamic(Wang and Chu, 2020;Guerreiro et al., 2018;Guerreiro et al., 2019)analysis techniques, as well as hybrid approaches(Wang et al., 2024). Application-level benchmarks have explored the impact of DVFS on deep learning workloads(Tang et al., 2019;Wang et al., 2020).
Table 1.The Comparison of the studies of GPGPU Microbenchmark. Items in parentheses indicate expansions over(Luo et al., 2024).StudyInstruction-levelMemory subsystemEnergy consumptionTensor coreApplication evaluationArchitectural featuresTarget architecture(Jia et al., 2018;Markidis et al., 2018;Martineau et al., 2019)✓✓✗✓✗✗Volta(Jia et al., 2019;Raihan et al., 2019;Yan et al., 2020a)✓✓✓✓✗✗Turing,Volta(Fasi et al., 2021;Svedin et al., [n. d.];Abdelkhalik et al., 2022;Sun et al., 2023)✓✓✗✓✗Asynchronous CopyAmpere,Turing(Luo et al., 2024)✓✓✓✓✓DSM, DPXAmpere, Ada, HopperThis study✓✓(L2 partitioned cache)✓(wgmma)✓✓(DSM, TMA, DPX)DSM, TMA, DPXAmpere, Ada, HopperTable1summarizes the existing microbenchmark studies across different GPU architectures and compares with our work. In contrast to previous research, our study provides a holistic analysis of Hopper, including its novel TCs, DPX instructions, DSM, and TMA. As Table1demonstrates, our work provides comprehensive benchmarks, offering valuable insights for developers seeking to optimize performance and energy efficiency on this latest architecture.
3.Overview of Hopper Architecture
Hopper, as a next-generation GPU architecture, offers enhancements in two areas. One involves strengthening traditional GPU functions such as peak performance, cache, memory, and tensor cores. The other focuses on designing new features to address evolving real-world tasks, such as the TMA, DSM, and DPX. In this section, we introduce these new aspects of Hopper and benchmark them in subsequent sections.
The new Hopper architecture features several key enhancements, as illustrated in Fig.1:
- •Hopper features a50MB partitioned L2 cache, a 25% increase compared to the 40MB in Ampere, retaining the partitioned design introduced in the previous generation.
- •Fourth-generation tensor coresoffer improved computational performance, introducing newwgmmainstructions on Hopper for asynchronous operations and FP8 format support, benefiting large-scale deep neural network models.
- •DPX instructions, supported by hardware acceleration on Hopper, facilitate dynamic programming algorithms by enabling fast max/min calculations with fused add operations and ReLU (clamping to zero).
- •A newthread block clusterlevel abstracts to the hardware Graphic Processing Cluster (GPC), allowing SM-to-SM communication via the SM-to-SM network within a GPC.
- •Newasynchronous execution featuresinclude the(TMA)and an asynchronous transaction barrier.
 Figure 1.Hopper architecture and new featuresIn this work, all the above new features will be benchmarked in multiple levels. We select the most representative GPUs of the Ampere, Ada Lovelace, and Hopper architectures, which are A100 PCIe, RTX 4090, and H800 PCIe respectively. Their basic hardware properties are shown in Table2. In terms of software configurations, the RTX 4090 utilized driver version 530.30.02 and CUDA version 12.1, while the A100 and H800 employed driver version 560.35.03 and CUDA version 12.6.
Table 2.Comparison of the Properties of the Ampere, Ada Lovelace and Hopper DevicesDeviceA100 PCIeRTX 4090H800 PCIeComp. Capability8.0(Ampere)8.9(Ada Lovelace)9.0(Hopper)SMs * cores per SM108 * 64128 * 128114 * 128Max Clock Rate1410 MHz2520 MHz1755 MHzMemory Size40 GB24 GB80 GBMemory TypeHBM2eGDDR6XHBM2eMemory Clock Rate1215 MHz10501 MHz1593 MHzMemory Bus5120-bit384-bit5120-bitMemory Bandwidth1555 GB/s1008 GB/s2039 GB/sL2 Cache40 MB72 MB50 MBCombined L1 Cache& Shared Memory per SM192 KB128 KB256 KB# of Tensor Cores432(3rd Gen.)512(4th Gen.)456(4th Gen.)Hopper-Specific FeaturesDPX hardwareNoNoYesDistributed Shared MemoryNoNoYesTensor Memory AcceleratorNoNoYes
4.Memory Subsystem
Figure 2.Latency clocks of different memory scopesIn the Hopper architecture, as shown in Fig.1, the memory subsystem design closely follows the previous generation, featuring L1 and L2 caches and programmable shared memory. Global memory has the highest latency among all GPU memory types but offers the largest capacity. In this section, we benchmark the conventional memory hierarchies and focus on two memory performance metrics: latency and throughput. Below we will introduce how we test these two metrics. The newly introduced Tensor Memory Accelerator and Distributed Shared Memory will be discussed in Sections5and7, respectively.
4.1.Latency
This section presents latency measurements for the L1 cache, shared memory, L2 cache, and global memory. We find that traditional latency testing methodologies are insufficient for characterizing the performance of partitioned L2 caches. Our fine-grained analysis reveals the specific latency characteristics of this cache architecture.
Traditional P-chase benchmarking.We begin by employing the traditional P-chase microbenchmarking method(Saavedra and Smith, 1995;Saavedra-Barrera, 1992)with random strides(te42kyfo, [n. d.])to investigate fundamental memory hierarchy characteristics. This includes examining the range of latencies observed and identifying the array size that triggers the latency inflection points. We read data in 64-byte chunks, which corresponds to the size of a generic address. For the L1 cache, L2 cache and global memory, we progressively increase the data volume and capture the inflection points in data access latency. In both Ampere††https://images.nvidia.cn/aem-dam/en-zz/Solutions/data-center/nvidia-ampere-architecture-whitepaper.pdfand Hopper††https://resources.nvidia.com/en-us-data-center-overview/gtc22-whitepaper-hopperarchitectures, the L2 cache is divided into two partitions interconnected by high-speed channels. The GPCs are also partitioned in the same way as the L2 cache. Compared to the commonly used uniform stride in previous work(Luo et al., 2024;Wong et al., 2010), random stride better reflects the existence of two L2 cache partitions.
Fig.2shows the access latencies of different memory levels, which are the average values of more than one million accesses. Before the first inflection point, the access latency reflects L1 cache, around 32-33 clocks for all three devices. Between the first and final inflection points, the latency can be attributed to L2 cache. For RTX 4090, L2 cache latency is approximately 284.8 clocks. At the RTX 4090’s third inflection point, the data size roughly equals its L2 cache capacity. As the chain data volume increases, the latency stabilizes around 571 clocks. However, in A100 and H800, we observe two inflection points corresponding to two different latencies for L2 cache. For A100, it is about 202.8 to 408 clocks. In the H800, L2 cache latency is around 264.5 to 502 clocks. In the A100 and H800, the third and fourth points are approximately half of the L2 cache size and the full L2 cache size, respectively. The stable latency after the fourth point, reflecting global memory latency, is 566 clocks for A100 and 656 clocks for H800. Table3concludes the memory access latency at different memory levels. For shared memory, we initialize the P-chase array with uniform 4-byte strides and then access this array using a thread to measure latency. Since shared memory and the L1 cache are physically the same memory component on GPU hardware, we observe similar latency results, approximately 29∼\sim31 cycles. When comparing latency across different memory levels, we observe that, on all three devices, the average latency of the L2 cache is approximately 6.5 times higher than that of the L1 cache, while the global memory latency is about 2.1 times higher than that of the L2 cache, with slight variations across devices.
The differing L2 cache latencies observed in the A100 and H800 GPUs arise from their partitioned architectures, which traditional P-chase benchmarking methods cannot fully characterize. To address this limitation, we conduct a subsequent fine-grained analysis.
Table 3.Latency in clock cycles for different memory scopes using traditional P-chaseTypeRTX4090A100H800L1 Cache32.033.032.0Shared Memory30.129.029.0L2 Cache273.0202.8∼\sim408264.5∼\sim502Global Memory571566656Fine-grained P-chase benchmarking.We employ fine-grained P-chase(Mei and Chu, 2017)to measure the latency of each memory access, revealing patterns in GPU L2 cache and global memory latency. Our analysis is based on thefollowing assumptions: 1) Two L2 cache partitions have the same capacity. 2) When the size of the data allocated for benchmarking is significantly smaller than half of the total L2 cache capacity, we assume that all memory accesses remain within the cache partition, thus, the result of P-chase does not demonstrate global memory latency. 3) Due to the architectural layout of the GPU, there are differences in the physical proximity between streaming multiprocessors (SMs) and L2 cache partitions. Accessing an L2 partition closer to an SM results in lower latency compared to accessing a farther partition; 4) Any measured latency significantly higher than what can be explained by cache capacity, data size being fully cached, or SM proximity to L2 partitions should be attributed to global memory access due to cache misses. The access sequence of fine-grained P-chase aligns with a uniform 32-byte stride.
On the A100, with an array length of 30MB, four distinct latency groups emerged, corresponding to the four categories in the Table4. In the H800, an 8MB array exhibited two latency types: L2 cache hit near partition (“near hit”) and L2 cache hit far partition (“far hit”). With a 40MB array, three latency groups were observed: L2 cache near partition hit, L2 cache near partition miss (“near miss”), and L2 cache far partition miss (“far miss”). We apply the K-means clustering algorithm to each device’s four data groups, with cluster center results shown in Table4. We observe that the A100 and H800, with their dual-partitioned L2 caches, exhibit significantly different behavior compared to the RTX 4090, which has an unpartitioned L2 cache. Additionally, their global memory access latency is considerably higher than that of the RTX 4090.
We also compare the results between Tables3and4. In the traditional P-chase benchmarking, when the length of the array is less than half the capacity of the L2 cache (between the first and second inflection points), the latencies for A100 and H800 are 202.8 and 264.5 clocks, respectively, aligning with the L2 cache near hit values in Table4. Furthermore, the global memory latency in Table3approximates (L2 cache near miss + far miss) / 2 from Table4. This outcome aligns with the probabilistic distribution of data accesses across different L2 cache partitions.
Table 4.Latency in clock cycles for different memory scopes using fine-grained P-chaseTypeA100 PCIeH800 PCIeL2 Cache Near Hit208.0258.0L2 Cache Far Hit356.6414.1L2 Cache Near Miss474.9555.5L2 Cache Far Miss622.7743.7In summary, While the traditional P-chase analysis with random strides can partially reveal latency variations arising from accessing different L2 cache partitions (“near hit” and “far hit”), it fails to capture the potential mapping between global memory and these partitions, which could contribute to latency differences observed during L2 cache misses (“near miss” and “far miss”). However, fine-grained P-chase analysis revealed distinct latency groups on the A100 and H800 GPUs, attributable to their dual-partitioned L2 caches and varying distances between streaming multiprocessors and these partitions.
4.2.Throughput
In this subsection, we evaluate the throughput of L1 cache, shared memory, L2 cache, and global memory. While memory access modifiers may be unreliable (as demonstrated in the latency tests), we control the volume of accessed data to ensure measurements target the desired cache level.
For the L1 cache test, we also first load the memory into the L1 cache using thecamodifier. Since the L1 cache is exclusive to SM, we issue a block with 1024 threads to access the L1 cache repeatedly.
Since shared memory can only be accessed within a block (distributed shared memory is not considered in this subsection), we use a block with 1024 threads to access the shared memory repeatedly.
For the L2 cache test, we first load the memory into the L2 cache using thecgmodifier. Since the L2 cache is shared by all SMs, the number of blocks we used is twice the number of SMs.
For the global memory test, we allocate significantly more memory space than the capacity of L2 to bypass the hardware-level cache prefetch mechanism, as detailed in(Mei and Chu, 2017). In order to reduce the number of memory access instructions, we set up each thread to use vectorized memory access to readfloat4. Each thread reads 5 times and writes 1 time. The number of blocks we used is four times the number of SMs. The number of blocks has little effect on L2 performance testing, requiring only enough instructions to saturate the hardware units.
For the first three units, data is accessed as both single-precision floating-point values (float) and four-element vectors (float4). While the float type is more common, float4 allows for data transfer with fewer instructions. For global memory accesses, we exclusively employ vectorized (float4) reads and writes to minimize instruction overhead and maximize memory bandwidth utilization(Luitjens, 2013). We record the cycles or time consumed and the amount of data accessed to calculate the throughput of different units.
Table5shows the memory access throughput at different memory levels. In the cache throughput test, we use different data types for memory access. We observe that using vectorized memory access (FP32.v4, equivalent to CUDA’sfloat4) can always achieve better performance. Notably, on the consumer-grade RTX 4090, using FP32 to access L1 cache and shared memory yields only half the throughput achieved with FP32.v4. This performance discrepancy is attributed to memory input/output throttling on the RTX 4090. Utilizing wider data types or increasing the number of blocks can mitigate this bottleneck.
The maximum throughput of L1 cache and shared memory of the three devices are similar because they share the same hardware design. However, in terms of L2 cache throughput, the H800 is 2.6 times and 2.2 times higher than the RTX 4090 and A100, respectively.††Note that for the L1 cache, the amount of data they transfer per clock is almost the same. However, since the order of clock frequency from high to low is RTX4090, H800, and A100, the order of throughput per unit time from high to low is also RTX4090, H800, and A100. The same calculation method also applies to L2 cache.In the memory throughput test, our results reach 92%, 90%, and 91% of the theoretical performance on RTX4090, A100, and H800 respectively. In the comparison of L2 and Global, the L2 cache throughput of RTX4090, A100, and H800 is 4.67, 2.01, and 4.23 times the global memory throughput, respectively.
Table 5.Throughput at different memory levels. The unit for L1 cache and shared memory throughput is (byte/clk/SM). The unit for L2 cache throughput is (byte/clk). The unit for global memory throughput is GB/s.TypeRTX4090A100H800FP32FP32.v4FP32FP32.v4FP32FP32.v4L1 Cache63.7121.299.5106.8125.8124.1Shared Memory63.7126.5127.9126.2127.4127.9L2 Cache1622.21708.01853.72007.94472.33942.4Global Memory929.81407.21861.5L2 vs. Global4.67×2.01×4.23×Insight1. Hopper’s L1 cache and shared memory performance remain consistent with the previous generation.2. The L2 cache architecture in both Ampere and Hopper features a dual-partition design, where partitions communicate through high-bandwidth interconnection channels. GPCs are similarly organized into two partitions that align with the L2 cache structure, exhibiting optimal performance when accessing proximate L2 cache partitions.
5.Tensor Memory Accelerator
The asynchronous copies introduced by NVIDIA Ampere GPU architecture provide more flexibility for programming. Hopper provides a more sophisticated asynchronous copy engine: the Tensor Memory Accelerator (TMA). As shown in Fig.1, TMA can be used in two scenarios: (1) transfers between global memory and shared memory in both directions; (2) transfers between shared memory regions of different SMs within a cluster (distributed shared memory). Ampere’s asynchronous copies require all threads to calculate the address of their own memory accesses. However, Hopper’s TMA takes care of everything. We can assign one thread to create a copy descriptor before launching the TMA. After that, TMA can automatically handle addressing and data transfer.
We attempt to expose the address translation efficiency of TMA, which is claimed as the key advantage by the hopper whitepaper.
5.1.Latency
The TMA latency test aligns with the random stride test from Section4.1††The only difference is that the minimum load size of TMA is 16 bytes, but we have actually measured that in the latency test, the results obtained with this very small load size are basically the same.. Our TMA test measures the complete latency, including the issuance of asynchronous TMA instructions, initialization of expected transactions forMbarrier, and theMbarrierarrive and wait processes. The results are shown in Fig.2. We observe that TMA access has one fewer inflection point compared to regular memory access, suggesting that TMA operations are influenced by L2 cache rather than L1 cache. After the first inflection point of regular memory access, TMA latency trends similarly to global memory access. However, TMA access is approximately 170 cycles higher than regular access, which can be attributed to the overhead of TMA units and synchronization waits.
5.2.Throughput
We test the throughput of TMA, as its performance in various scenarios can directly impact our program’s efficiency. In this subsection, we load 4GB of data from global memory into shared memory using TMA. We evaluate one-dimensional loads, 1D Tensor, 2D Tensor, and 3D Tensor operations. We focused on the impact of transfer size per TMA instruction and the number of launched CTAs on throughput. For non-tensor (one-dimensional) transfers, TMA instructions can be issued without creating a tensor map. However, for 1D, 2D, and 3D tensor copies, a Copy Descriptor (Tensor Map) as shown in Fig.1is required, specifying different dimensions.
For the number of thread blocks, we select 114, 228, 342, and 456, corresponding to 1, 2, 3, and 4 times the number of SMs, respectively. In non-tensor tests, we evaluate load sizes of 1KB, 2KB, 4KB, 8KB, 12KB, and 16KB. For 1D Tensors, the tensor map limits each dimension of the shared memory box to a maximum of 256 elements. Thus, even withint64as the data type, the maximum load is 2KB. We tested 0.5KB, 0.75KB, 1KB, 1.25KB, 1.5KB, and 2KB. In 2D Tensor tests, we use the same sizes as non-tensor tests, with floating-point data types, and shapes of 16×16, 32×16, 32×32, 64×32, 96×32, 64×64. For 3D Tensors, the sizes are also the same as non-tensor tests, with floating-point data types, and shapes of 8×8×4, 8×8×8, 16×8×8, 16×16×8, 16×16×12, 16×16×16. We examine how different combinations of block numbers and TMA load sizes affect global memory utilization.
Figure 3.Global memory throughput of different combinations of block numbers and TMA load sizesThe results, shown in Fig.3, indicate that larger load sizes and more thread blocks generally achieve higher memory bandwidth. In non-tensor, 2D tensor, and 3D tensor scenarios, we reach over 1800GB/s, similar to Section4.2. However, in 1D tensors, the limitations imposed by the tensor map on the shared memory box size prevent further increases in load size. Therefore, for one-dimensional loads, using a non-tensor approach is recommended for better performance. Additionally, in 3D tensors, we observed an unusual phenomenon: when the load size exceeds 8KB, more thread blocks result in lower performance, likely due to the shared memory box constraints.
We compare the performance of different shared memory box shapes with a TMA load size of 16KB and floating-point data type. The configurations tested are 16×16×16, 32x128x1, 64×64×1, 256×16×1, 16×256×1, and 4×4×256. The results, shown in Fig.4, reveal a clear trend: with the same load size, larger x-axis dimensions yield higher throughput without negative effects from increasing thread blocks. However, increasing the y-axis and z-axis dimensions significantly reduces throughput, which may decrease further with more thread blocks. Therefore, when using TMA to handle tensors with dimensions greater than 3D, it’s important to carefully select appropriate parameters to achieve optimal performance.
Figure 4.16KB per TMA load with different shapes
5.3.Application-level
For the application-level evaluation of TMA, we select one of the most impactful and widely used applications: General Matrix Multiply (GEMM). GEMM is defined as𝐃m×n=α𝐀m×k×𝐁k×n+β𝐂m×n\mathbf{D}_{m\times n}=\alpha\mathbf{A}_{m\times k}\times\mathbf{B}_{k\times n}+\beta\mathbf{C}_{m\times n}. GEMM is extensively applied in fields such as artificial intelligence and scientific computing. GPUs, with their high degree of parallelism, have become the preferred hardware for GEMM computations. To achieve high efficiency on GPUs, GEMM implementations employ tiling strategies, which divide the computational workload into smaller submatrices (tiles) that fit into the memory hierarchy of the GPU. Each tile is assigned to a Cooperative Thread Array (CTA), which consists of threads that collaboratively load data from global memory, perform computations in shared memory, and write results back to global memory. This tiling approach minimizes memory latency and maximizes data reuse, ensuring efficient utilization of GPU resources.
Our implementation is based on the official example provided by CUTLASS††https://github.com/NVIDIA/cutlass/tree/main/examples/cute/tutorial/hopper. To minimize the influence of other factors (e.g., Hopper’s more powerful Tensor Cores and itswgmmainstructions), this subsection focuses exclusively on comparisons conducted on the Hopper architecture. In the GEMM implementation without TMA, the programming model follows the same approach as Volta and Ampere, employing pipelining by interleaving stages and instructions. In the TMA-enabled version, explicit producer-consumer synchronization is utilized for purely asynchronous instructions, such as TMA and Tensor Core operations. To maintain high performance for larger matrices, we set the CTA tile sizes for theMM,NN, andKKdimensions to 128, 256, and 64, respectively. At this point, the TMA load shapes are configured as 128×256 and 64×256 (with the𝐁\mathbf{B}matrix being transposed), which are equivalent to 64×256 and 32×256 in FP32. Based on the instruction-level results, these configurations allow for effective utilization of TMA’s performance capabilities. To fully utilize the performance of Tensor Cores (as discussed in Table9of Section6.2, where it is shown that theNNdimension needs to be sufficiently large to ensure tensor core performance), we set theMM,NN, andKKdimensions for Tensor Core instructions to 64, 128, and 16, respectively. Additionally, we configure the pipeline depth to 2. All other parameters remain consistent with the CUTLASS example.
Figure 5.GEMM Performance Comparison in FP16: With and Without TMAFig.5illustrates the performance impact of enabling and disabling TMA in the GEMM application. The horizontal axis represents the dimensions of square matrices(n×n)(n\times n), while the vertical axis shows the performance in FP16 TFLOPS (Tera Floating-point Operations Per Second). For smaller matrices(n<2000)(n<2000), the performance difference between “With TMA” (blue line) and “Without TMA” (orange line) is minimal, as the smaller workload does not fully leverage GPU’s capabilities. As the matrix size increases(n≥2000)(n\geq 2000), the performance with TMA shows a significant advantage, growing faster than the case without TMA. For larger matrices(n>7000)(n>7000), TMA-enabled performance stabilizes at close to 600 TFLOPS, significantly outperforming the non-TMA case, which levels off at approximately 450 TFLOPS. This demonstrates that TMA provides substantial benefits for large-scale matrix multiplication by optimizing memory access and data movement, enabling higher computational efficiency and better utilization of hardware resources.
Insight1. TMA, as an independent asynchronous memory access unit, enhances the programming flexibility of the Hopper architecture. Utilizing warp specialization can more fully exploit the performance potential of the Hopper architecture.2. TMA load shapes require careful selection to achieve good performance, ensuring the x-axis dimension is sufficiently large while fully considering memory-compute overlap in the pipeline.
6.Tensor Core
6.1.Tensor Core’s Evolution
Table6illustrates the progression of TCs, encompassing enhancements in precision, operand shapes, programming modes, and execution modes. In the initial Volta Architecture, first-generation TCs exclusively supported FP16 as the input data type. Subsequent architectures, including Ampere, Ada, and Hopper, introduced support for a broader range of data types such as BF16, TF32, FP64, INT8, INT4, Binary, and more. The programming of TCs has also seen continuous improvement. Ampere and Ada Lovelace GPUs provide users with the flexibility to utilize either the legacy C-levelwmmaAPIs or PTX-levelmmainstructions. Notably, thewmmaAPIs had limitations in fully harnessing TCs’ capabilities, whereasmmainstructions could leverage advanced sparse matrix multiplication capabilities introduced since Ampere. In the case of Hopper GPUs, new warp-group-levelwgmmainstructions were introduced. BothwmmaandmmaAPIs remain supported in Hopper, but we find that the complete potential of Hopper TCs can only be realized throughwgmmainstructions.
Anmmainstruction computes𝐃m×n=𝐀m×k×𝐁k×n+𝐂m×n\mathbf{D}_{m\times n}=\mathbf{A}_{m\times k}\times\mathbf{B}_{k\times n}+\mathbf{C}_{m\times n}and is executed synchronously by one CUDA warp (i.e., 32 threads). In contrast,wgmmafor Hopper computes𝐃m×n=𝐀m×k×𝐁k×n+𝐃m×n\mathbf{D}_{m\times n}=\mathbf{A}_{m\times k}\times\mathbf{B}_{k\times n}+\mathbf{D}_{m\times n}and is executed asynchronously by one CUDA warp group (i.e., four CUDA warps). Here,𝐀m×k\mathbf{A}_{m\times k}denotes a matrix𝐀\mathbf{A}withmmrows andkkcolumns, and similarly for the other matrices. The matrix shapes formmainstructions can bem16n8k16m16n8k16orm16n8k8m16n8k8, whilewgmmasupportsm64nNk16m64nNk16, whereNNcan be 16, 32, 64, 128, 256, and so on(Corporation, 2023). Notably,wgmmahas the advantage of directly loading matricesAAandBBfrom shared memory, unlikemma, which requires storing all matrices in the register file before execution. We use the term “SS“ to denote thewgmmainstruction that loads bothAAandBBfrom shared memory, while “RS“ is used for the instruction that loadsAAfrom the register file. Additionally,wgmmaoffers support for certain useful arguments not required formma. Further details are provided in(Corporation, 2023). Notably, wgmma instructions are specific to the Hopper architecture, whereas mma instructions offer backward and forward compatibility across generations.
Table 6.Properties of the latest generations of Tensor CoresArchPrecisionProgrammabilityModeAmpereFP16,BF16,TF32,FP64,INT8,INT4,BinarySyncAdaFP16,BF16,FP8,TF32,FP64,INT8,INT4,BinarySyncHopperFP16,BF16,FP8,TF32,FP64,INT8,BinarySyncPTX: wgmma, wgmma.spASync
6.2.Instruction-level
We conduct micro-benchmarking of TCs at the PTX level, as it strikes a suitable balance between granularity and complexity. Additionally, we disassemble PTX instructions to SASS codes to achieve a deeper understanding of the operations. SASS analysis is provided in the supplementary materials, which are available online.
We focus on assessing two critical metrics: latency and throughput. Latency signifies the elapsed time, measured in clock cycles, starting from the initiation of instruction issuance to the execution pipeline and concluding when the results become accessible for subsequent usage. This measurement is specifically labeled as “completion latency.“ To elaborate further, we issue a single synchronous TC instruction (i.e.,mma) using one CUDA warp per SM, whereas one asynchronous TC instruction (i.e.,wgmma) is issued utilizing four CUDA warps (comprising a warp group) on one SM. We execute the instruction 1024 times within a CUDA kernel. Throughput is quantified as𝑇𝑜𝑡𝑎𝑙_𝑂𝑃𝑆/𝐷𝑢𝑟𝑎𝑡𝑖𝑜𝑛\mathit{Total\_{OPS}}/\mathit{Duration}, where𝑂𝑃𝑆\mathit{OPS}represents multiplication or addition operations. It’s important to emphasize that, unlike the approach described in(Sun et al., 2023), we abstain from utilizing total clock cycles to compute throughput due to potential variations in GPU frequencies during the execution of different TC instructions.
mmaresults.Table7provides an overview of the latency and throughput measurements formmainstructions across A100, RTX4090, and H800 Tensor Cores GPUs. Note that the sparse shapes in the table represent compressed shapes. In other words, thekkof the actual instruction modifier is twice that in the table.
Table 7.Different dense and sparsemmainstructions on A100, RTX4090 and H800 Tensor Cores. Latency (LAT) is measured in clock cycles. Throughput is measured in TFLOPS or TOPS/s. Peak performance (A100): FP16 (312 TFLOPS); TF32 (156 TFLOPS); INT8 (624 TOPS). Peak performance (RTX4090): FP16 (330.3 TFLOPS); TF32 (82.6 TFLOPS); INT8 (660.6 TOPS). Peak performance (H800): FP16 (756.5 TFLOPS); TF32 (378 TFLOPS); INT8 (1513 TOPS).A/BC/DShapeLAT/ThroughputA100RTX4090H800DenseSparseDenseSparseDenseSparseFP16FP16m16n8k817.7/310.017.3/408.417.7/355.317.3/713.216.0/368.616.0/493.8FP16FP16m16n8k1624.6/310.624.5/622.824.6/357.624.5/711.824.1/494.424.0/722.8FP16FP32m16n8k817.5/299.618.0/394.118.8/177.818.8/357.416.0/363.716.0/488.7FP16FP32m16n8k1626.0/303.424.5/603.333.0/178.933.0/356.024.1/490.724.0/721.8TF32FP32m16n8k417.8/149.518.2/196.819.2/89.019.0/178.016.5/180.616.4/240.7TF32FP32m16n8k826.3/151.526.7/301.533.4/89.033.3/178.724.5/246.424.4/363.3INT8INT32m16n8k1617.6/594.818.0/788.517.3/707.617.3/141216.1/730.316.1/970.0INT8INT32m16n8k3226.0/607.626.6/121024.5/711.724.6/142324.0/977.924.2/1435For A100 and H800, the same-precisionmmainstructions with the larger shapes commonly achieve better throughputs. But this phenomenon disappears on RTX4090. Sparse and densemmainstructions exhibit equivalent latency, with sparsemmainstructions achieving higher throughputs. On the RTX4090, sparsemmainstructions can achieve up to double the throughput compared to their corresponding dense counterparts, aligning with the speedup claims stated in the vendor’s documentation. However, for the A100, only the sparsemmainstructions with larger shapes can realize the theoretical speedups. In the case of the H800, sparsemmainstructions can only achieve an average speedup of 1.42 times over the dense ones. This highlights that on Hopper Tensor Cores, sparsemmainstructions may not fully harness the capabilities of the sparse tensor cores.
The achieved throughput on A100 exceeds 95% of their theoretical peak performance. The achieved throughput of RTX4090 is higher than the official theoretical peak performance. This is because our RTX4090 runs at a higher frequency (2710 MHz) than the officially announced boost frequency. However, on Hopper Tensor Cores,mmainstructions can only attain an average of 62.9% of the theoretical peak performance. It indicates that themmainstructions should be used carefully as they cannot fully utilize the tensor cores’ potential in some cases.
wgmmaresults.As a set of warp-group-level Tensor Core instructions designed specifically for Hopper GPUs,wgmmainstructions are the pioneering instructions to be executed asynchronously. Table8show the measured latency and throughput of dense instructions. When initializing matrices with zeros, we achieve throughputs exceeding 95% of the theoretical peak performance. We observe a decrease in Tensor Core performance when initializing matrices with random values, especially pronounced when utilizing FP16 as the computation type and FP32 for accumulation. This phenomenon is primarily attributed to the power consumption nearing the 350 W power limit of the H800-PCIe, subsequently causing a reduction in frequency. Users working with Tensor Cores on the H800-PCIe GPU should take into full consideration the power constraints when performing computations.
Table 8.Variations in DensewgmmaInstructions for H800 Tensor Cores. Latency (LAT) is quantified in clock cycles, while throughput is expressed in TFLOPS or TOPS. The peak throughputs for FP16, TF32, FP8, and INT8 are 756.5, 373, 1513, and 1513, correspondingly. “Zero“ or “Rand“ signifies that all matrices are initialized with either zero or randomly generated values. “SS“ implies that both matrix A and B are stored in shared memory, while “RS” signifies that matrix A is stored in the register file, whereas B is stored in shared memory. “Rand“ has the same latency as “Zero“.A/BC/DInstructionLAT/Throughput(SS,Zero)LAT/Throughput(RS,Zero)Throughput(SS,Rand)Throughput(RS,Rand)FP16FP16m64n256k16128.0/729.3128.0/729.2704.5703.7FP16FP32m64n256k16128.0/728.5128.0/731.9665.4667.5TF32FP32m64n256k8128.0/364.4128.0/364.6357.1357.3FP8FP16m64n256k32128.0/1448.4128.0/1448.01439.21440.3FP8FP32m64n256k32128.0/1447.5128.0/1455.01417.21419.8INT8INT32m64n256k32128.0/1448.7128.0/1447.91442.31442.2In the case of densewgmma, withNNset to 128, we observe that the latency for all data types corresponding to the instructions is 128.0. Interestingly, under both “RS” and “SS” modes, the latency and throughput for the same instruction remain relatively consistent. This is due to the effective hiding of shared memory latency through high computational workload and asynchronous operations.
In the context of sparsewgmmainstructions, the latencies for “RS” and “SS” modes are 128.0 and 144.0, respectively. Additionally, we observe that in the “SS” mode (Rand), sparsewgmmaachieves approximately 1.8x performance improvement compared to densewgmma. In the “RS” mode (Rand), the performance improvement exceeds 1.9x. However, the performance of sparsewgmmain the “SS” mode is lower than in the “RS” mode, which is notably different from the behavior of densewgmma. We find that in sparsewgmma, the “SS” mode retrieves data from the shared memory of sizem×km\times kand performs a 2:4 sparse pruning based on metadata during the execution of the sparsewgmmainstruction. In contrast, the “RS” mode directly accesses data from the pruned register file of sizem×k/2m\times k/2. The high shared memory access demand (twice as much) may lead to latency that cannot be effectively concealed by Tensor Core computation, resulting in sparsewgmmainstructions in “SS” modes failing to achieve the expected peak performance.
wgmmaresults with differentNNvalues.We conduct tests using the example ofwgmma.m64nNk16.f32.f16.f16, varying the value ofNN, and the results are presented in Table9. WhenNNis greater than or equal to 64, allwgmmainstructions can achieve throughputs that closely approach peak performance. However, whenNNis less than 64, the achieved throughput decreases, and the “SS” mode of instructions exhibits higher latency than the “RS” mode, while the achieved throughputs are lower than those of the “RS” mode. AsNNdecreases, the computational density ofwgmmainstructions gradually diminishes, making it challenging to conceal the latency associated with shared memory access, leading to the aforementioned phenomena. Therefore, when utilizing wgmma instructions, it is advisable to opt for larger values ofNN(>=64>=64) whenever possible to attain superior performance.
Table 9.Differentwgmmainstructions with differentNNvalues on H800 tensor cores. The definitions of LAT and throughput can be found in the caption of Table8. “Rand“ has the same latency as “Zero“.NDenseSparseLAT/Tput(SS,Zero)LAT/Tput(RS,Zero)Tput(SS,Rand)Tput(RS,Rand)LAT/Tput(SS,Zero)LAT/Tput(RS,Zero)Tput(SS,Rand)Tput(RS,Rand)256128.0/728.5128.0/731.9665.4667.5144.0/1312.3128.0/1476.21194.31277.512864.0/728.564.0/725.4659.8661.780.0/1176.464.0/1463.31109.61270.56432.0/719.632.0/719.7648.3649.948.0/977.432.0/1450.1969.91263.43224.0/477.316.0/710.3471.5634.432.0/727.118.0/1272.4723.41135.71620.0/287.013.0/434.2283.5426.224.0/482.318.0/638.6479.8636.3818.0/158.213.0/216.7157.6215.220.0/289.016.0/359.4286.1356.7Energy efficiency.Although Tensor Cores have impressive performance, their energy efficiency should also be considered. The training of GPT-3 consumes approximately 1,287 megawatt-hours of electricity in a single training run(Maslej et al., 2023). Since tensor core instructions constitute the primary computational workload in AI training, analyzing their energy consumption is essential for developing green AI solutions(Tang et al., 2019;Wang et al., 2020;Nabavinejad et al., 2022). Therefore, we conduct comprehensive energy efficiency analysis to understand the power characteristics of different tensor core instructions.
In our benchmarks, we define energy efficiency as performance per watt, measured in TFLOPS(TOPS)/watt. Bothmmaandwgmmaare considered in this work. Our methodology involves repeatedly executing eithermmaorwgmmainstructions across all SMs, with a minimum of two billion repetitions. We utilize the tools provided in(Wang and Chu, 2020)to monitor both frequency and performance. The energy efficiency of each instruction is determined by calculating the ratio of performance to power consumption once steady-state operation is achieved during these repetitive executions.
Formmainstructions, we test the largest operational shape in Table7. The energy efficiency ofmmainstructions is shown in Table10. In terms of dense instructions, the average energy efficiency of H800 is 1.60 times and 1.69 times that of A100 and RTX4090 respectively. In terms of sparse instructions, the average energy efficiency of H800 is 1.33 times and 1.39 times that of A100 and RTX4090 respectively. We find that the H800 has significantly higher energy efficiency.
Table 10.Power consumption and energy efficiency of maximum shape undermmainstructions. Energy is measured in Watts. Efficiency is measured in TFLOPS(TOPS)/Watt.A/BC/DTypeA100H800RTX4090EnergyEfficiencyEnergyEfficiencyEnergyEfficiencyFP16FP16Dense173.41.79188.62.62189.11.89Sparse198.83.13187.23.86214.03.33FP16FP32Dense188.51.61196.72.49154.11.16Sparse216.12.79194.93.70165.92.15TF32FP32Dense214.70.71254.90.97174.30.51Sparse235.71.28232.51.56187.90.95INT8INT32Dense178.43.41165.35.92201.43.53Sparse193.96.24163.38.79219.86.47Forwgmmainstructions, we focus on both the frequency and efficiency when these instructions are executed continuously. The instruction formats are consistent with those described in Table8. The results are presented in Table11. It is observed that, during continuous execution ofwgmmainstructions, the core frequency drops below 1620 MHz specified in the whitepaper, as it reaches the 350-watt power limit. Furthermore, the initialization of inputs significantly impacts both power consumption and frequency. When inputs are set to zero, power consumption remains below 200 watts. However, with random inputs, the power consumption rapidly hits the 350-watt threshold. Consequently, the performance results in Table11are inferior to those in Table8. Notably, sparse instructions cause a substantial reduction in frequency, explaining why their performance is not twice that of dense instructions. Regarding energy efficiency,wgmmadense and sparse instructions achieve average 0.67 times and 0.78 times the efficiency ofmmadense and sparse instructions, respectively. Compared to different architectures, the energy efficiency of Hopperwgmmais on average 1.05 times and 1.10 times that of Amperemmaand Adammainstructions, respectively.
Based on these results, we conclude thatwgmmainstructions can fully utilize the GPU’s potential to achieve maximum performance, but they do not exhibit good energy efficiency. If extreme performance is desired,wgmmainstructions should be chosen. However, if greater emphasis is placed on energy efficiency and compatibility,mmainstructions are the better choice.
Table 11.Power consumption and energy efficiency of maximum shape underwgmmainstructions. Frequency is measured in MHz. Performance is measured in TFLOPS (TOPS). Efficiency is measured in TFLOPS (TOPS)/watt.A/BC/DTypeFreq/Perf(SS,Zero)Freq/Perf(RS,Zero)Freq/Perf/Effi(SS,Rand)Freq/Perf/Effi(RS,Rand)FP16FP16Dense1560/7291590/7431275/595/1.701275/600/1.71Sparse1440/11921380/12901200/997/2.851185/1102/3.15FP16FP32Dense1485/6881530/7141260/583/1.671290/594/1.70Sparse1380/11421320/12341230/998/2.851170/1081/3.09TF32FP32Dense1755/3831755/3841425/322/0.921425/327/0.93Sparse1560/6441515/7071320/553/1.581245/581/1.66FP8FP16Dense1590/14841620/15121305/1213/3.471320/1239/3.54Sparse1455/24141395/26051275/2122/6.061200/2256/6.45FP8FP32Dense1500/14011530/14261290/1202/3.431260/1180/3.37Sparse1395/23161335/25201245/2052/5.861185/2205/6.30INT8INT32Dense1755/15331755/15341380/1285/3.671395/1306/3.73Sparse1755/25801725/28991290/2144/6.131215/2275/6.50
6.3.Library-level
The Transformer Engine (TE)(NVIDIA, 2022)is a library specifically designed to accelerate Transformer models(Vaswani et al., 2017), following the introduction of the Hopper architecture. It is capable of leveraging the FP8 precision offered by both the Hopper and Ada architectures. In particular, it provides a variety of optimized modules for Transformer layers that can be utilized within the widely-used deep learning framework, PyTorch(Paszke et al., 2019). In this subsection, we benchmark two modules of the Transformer Engine to explore their potential as key components in large language models.
6.3.1.Linear Layer
In the Transformer architecture, most of the computational overhead comes from the linear layers, specifically matrix multiplication while the Transformer Engine provides thete.Linearimplementation to perform matrix multiplication with higher throughput on FP8 Tensor Cores. When employing the Transformer Engine withte.Linearfor matrix multiplication in FP8 precision, TE converts both the input and weights in the linear layer to FP8. This conversion process involves data transformation and quantization operations. For example, as the dynamic range of FP8 may not encompass the maximum value of the input tensor, TE identifies the maximum absolute value of the input data as the scaling factor. It then adjusts the input data to fit the representation range of FP8 using𝑖𝑛𝑝fp8=𝑖𝑛𝑝fp16/𝑠𝑐𝑎𝑙𝑒\mathit{inp_{fp8}}=\mathit{inp_{fp16}}/\mathit{scale}, followed by matrix multiplication in FP8 Tensor Core𝑜𝑢𝑡fp8=𝑖𝑛𝑝fp8×wfp8\mathit{out_{fp8}}=\mathit{inp_{fp8}}\times\mathit{w_{fp8}}. Finally, it scales the result with𝑜𝑢𝑡fp16=𝑜𝑢𝑡fp8×𝑠𝑐𝑎𝑙𝑒\mathit{out_{fp16}}=\mathit{out_{fp8}}\times\mathit{scale}. This operation would introduce some overhead.
When performing FP8 matrix multiplication usingte.Linear, kernel execution time significantly increases with matrix size. For smaller matrices (N=4096), kernel time accounts for only 25.3% of the execution, while for larger matrices (N=16384), it dominates at 84.7%. To evaluate Tensor Engine (TE) optimization for linear layers, we measure the throughput (GFLOPS) ofte.Linearusing square matrices𝐃n×n=𝐀n×n×𝐁n×n\mathbf{D}_{n\times n}=\mathbf{A}_{n\times n}\times\mathbf{B}_{n\times n}, effectively showcasing its performance characteristics.
 Figure 6.Comparison of throughput for matrix multiplication with two same-size matrices𝐃n×n=𝐀n×n×𝐁n×n\mathbf{D}_{n\times n}=\mathbf{A}_{n\times n}\times\mathbf{B}_{n\times n}in different hardware configurations and data types usingte.Linear.We extensively assess the Linear performance across diverse shapes, data types, and hardware setups (Fig.6). Leveraging the Transformer Engine, we expedite matrix multiplications for the Linear layer using FP8 Tensor Cores. Our findings reveal an increase in GPU utilization and throughput with larger matrix sizes. FP8 performance is influenced by the overhead from data format conversion and quantization operators. For smaller matrix sizes, FP8 throughput is lower compared to FP16 or FP32. However, withNN=8192, FP8’s performance gains become evident. WhenNN=16384, H800 and 4090 utilizing FP8 achieve almost twice the throughput of FP16. This underscores FP8’s high throughput potential but underlines the need for specific conditions to attain optimal computing density.
6.3.2.Transformer Layer
The TE capitalizes on the efficiency improvements provided by FP8 through specific operator fusion optimizations for transformer layer structures. For example,te.LayerNormMLPcombines layernorm and MLP within the transformer structure, allowing data transmission between layernorm and the subsequent MLP layer to adopt the FP8 format. This approach not only eliminates data format conversion overhead but also effectively leverages FP8 memory transfer advantages.
TE offers ate.TransformerLayermodule that encompasses all operator optimizations for transformer layer structures, facilitating the implementation of various Large Language Model (LLM) structures by adjusting its parameters. However, some operators, such asSoftmaxandGeLU, have not been quantized to FP8 by TE, resulting in significant data format conversion overhead. Additionally, the DotProductAttention operator, implemented with flash-attention(Dao et al., 2022), does not utilize FP8 Tensor Cores.
The computational overhead of the transformer layer’s linear layer primarily depends on the hidden size, raising the question of which hidden state (dimension of embedding) will yield better performance for TE with FP8 compared to FP16. We investigate this by examining the open-source LLM, Llama(Touvron et al., 2023a;Touvron et al., 2023b), modifying the activation function to SwiGLU(Shazeer, 2020)and normalization to RMSNorm(Zhang and Sennrich, 2019). We set layer structure parameters based on the hidden state’s size, with hidden states 4096, 5120, and 8192 corresponding to Llama configurations 7b, 13b, and 70b, respectively.
Table 12.Parameter settings ofte.TransformerLayerfor varioushidden_sizevalueshidden_size10242048409651208192ffn_hidden_size28165632110081382422016num_attention_heads816324064We fixed the input as (4, 512,hidden_sizehidden\_size), where 4 is thebatch_sizebatch\_size, 512 is thesequence_lengthsequence\_length, and the attention mask is set to None. We then calculated the latency (ms) required for encoding a single layer once, focusing on the encoding task for a single layer.
 Figure 7.Comparison of latency for the same input text in different hardware configurations and data types usingte.TransformerLayer.The Transformer Engine condenses the entire Transformer Layer structure intote.TransformerLayer. Fig.7illustrates the latency for the same input text, offering a performance comparison across various hardware setups and data types withte.TransformerLayer. As computational density increases, the advantage of H800 in computation becomes evident. Notably, FP16 shows nearly twice the speed compared to FP32. FP8 outperforms FP16 for hidden_size>>4096 but does not achieve double FP16 performance. This is because some modules within the Transformer Layer still do not utilize FP8 precision for calculations and data movement.
6.4.Application-level
Currently, the Transformer Engine has not provided optimal support for mainstream decode-only casual language models. In order to test the inference performance of the Transformer Engine on this type of model like, Llama(Touvron et al., 2023a), we replaced thenn.LinearandRMSNormin the original model structure withte.Linearandte.RMSNorm, respectively, to ensure that most modules in the model utilize the Transformer Engine.
To evaluate the effectiveness of TE in generating text for Llama, we follow(Kwon et al., 2023)using the ShareGPT dataset as input for the LLM. The ShareGPT dataset comprises conversations between users and ChatGPT(OpenAI, [n. d.]), which have been shared by the users. We tokenize these datasets and, based on their input and output lengths, generate synthesized client requests.
In order to test and ensure compatibility with different hardware architectures (different memory capacities), we set the maximum input length to 128 and the maximum text generation length to 128. Furthermore, to meet the dimension requirements ofte.Linear, we set the batch size to 8.
We use throughput as the evaluation metric, which represents the total text length that can be processed per second:Throughput=(input_len+output_len)/timeThroughput=(input\_len+output\_len)/time.
Table 13.Inference Throughput (Tokens/s) for different model sizes on different GPUs and different data typesGPUModelFP32BF16FP84090llama-3B653.33638.19641.19llama-2-7BOOM526.65OOMA100llama-3B507.67539.82-llama-2-7B309.93488.06-llama-2-13BOOM382.53-H800llama-3B546.55506.28505.74llama-2-7B359.69432.91428.15llama-2-13B214.06344.25343.25LLM inference throughput results.We test the state-of-the-art decode-only models on inference with different data types, as shown in Table13. We set the input length and text generation length to be relatively short, and the decode-only model is memory-bound during inference, so the computational advantages of FP8 Tensor Cores are not significant. Moreover, since the current Transformer Engine does not provide comprehensive support, data transmission between modules still occurs in FP16/FP32 without operator fusion. It is possible that when the model size and input data length increase, and with good operator fusion support, a certain improvement can be achieved.
Insight1.wgmmacan achieve 95% of Hopper’s theoretical peak performance, while the backward-compatiblemmacan only reach 62.9%.2. Usingwgmmarequires attention to power wall constraints, whereasmmademonstrates better energy efficiency.3. Utilizing 4th-generation Tensor Core low-precision formats (FP8) is beneficial for libraries and applications, but careful consideration must be given to problem size, precision conversion overhead and accuracy loss.
7.Distributed Shared Memory
The Hopper architecture features a direct SM-to-SM communication network within clusters, enabling threads from one thread block to access shared memory of another block, known as distributed shared memory (DSM). Additionally, for cases where shared memory demand restricts active block numbers on an SM, DSM can partition data within the same cluster, alleviating shared memory demand per block. The programmability of DSM is facilitated through the CUDA C function,cluster.map_shared_rank(SMEM, DST_BLOCK_RANK), returning the shared memory address of the target block. Here,SMEMrepresents the shared memory pointer, andDST_BLOCK_RANKis the target block rank in the cluster. This is compiled into PTX codemapa, which maps the address of the shared variable in the target block. We benchmark DSM using three aspects: DSM latency, throughput under various scheduling strategies and access patterns, and histogram applications. This multi-faceted testing approach helps uncover the programming performance of DSM.
7.1.Latency
To measure inter-SM data transfer latency, we launch multiple blocks, each with one thread. We utilizemov.u32 %0, %%smidPTX code to record the SM ID of each block, ensuring they run on different SMs. Our testing method is consistent with the uniform stride p-chase described in Section4.1.
As shown in Table3, when we directly access the shared memory, the latency is 29 cycles. However, when we access the block’s local shared memory by the distributed shared memory interface, the latency reaches 33 cycles. The results indicate that even if we access the local shared memory and it is not required to leverage SM-to-SM network, the distributed shared memory still introduces some overhead. When the cluster size increases to two, the access latency between SMs is 181 cycles, a 30% reduction compared to L2 cache. Notice that transferring data from one SM to another via global memory incurs a cost of 1110 cycles (one store and one load), utilizing DSM can reduce this latency by 6.13×\times, which is close to the 7×\timesreduction reported in NVIDIA’s official documentation. When the cluster size increases from two to sixteen (the maximum cluster size in Hopper), the access latencies between different blocks range from 184 to 213 cycles.
7.2.Throughput
In the DSM throughput test, we benchmark the performance for both intra-SM and inter-SM scenarios separately.
For the intra-SM case, the theoretical throughput of shared memory per SM is calculated as1755MHz×128Bytes=225GB/s1755\,\text{MHz}\times 128\,\text{Bytes}=225\,\text{GB/s}. Using the DSM interface to access the block’s own memory only reaches 205 GB/s, 80% of peak performance. It is noteworthy that intra-SM shared memory access can also be performed without using the DSM interface, achieving over 99.8% of theoretical performance, as illustrated in Table5. This indicates that there exists an additional overhead of accessing the block’s shared memory through DSM.
Figure 8.Scenarios for DSM throughput testingFor the inter-SM case, since DSM allows any block within a cluster to access another block, the access pattern significantly affects data movement throughput. Thus, as shown in Fig.8, we designed three different copy scenarios to evaluate DSM throughput. The first is a ring-based access scheme, which is common in high-performance computing (e.g., ring allreduce(Thakur et al., 2005;Sergeev and Del Balso, 2018), matrix multiplication(Cannon, 1969;Chtchelkanova et al., 1997)). In each cluster, threads in a block ranked byRRaccess the shared memory of the block ranked by(R+1)%CS(R+1)\%CS, whereCSCSis the cluster size. The second is pair-based, often used in butterfly communication scenarios in high-performance computing. The third is broadcast-based, a common access pattern in various parallel algorithms. In addition to above access pattern, we are also trying to explore the block scheduling policy within the cluster. There are three scheduling policies available in Hopper: default, Spread, and LoadBalancing. We explore the throughput of different access patterns under each scheduling policy. In the remaining experiments in this section, we launch 50160 blocks to ensure sufficient block residency on the SMs. Additionally, we allocate 16KB of shared memory for each block.
We observe the SM ID allocation for blocks within the same cluster. Under the Default and Spread scheduling policies, blocks from the same cluster are assigned to different SMs within a GPC. However, with LoadBalancing, blocks can be allocated to the same SM. As shown in Fig.9, LoadBalancing slightly outperforms the other two policies in most of cases. This may be because blocks on the same SM can access shared memory without using the SM-to-SM network, enhancing performance. Different access patterns exhibit significant throughput variations as cluster size increases. Ring-based and pair-based patterns show minimal differences, while Broadcast-based throughput decreases significantly with larger cluster sizes. In throughput tests, DSM does not achieve the original shared memory bandwidth.
 Figure 9.Performance of access pattern on different policiesWe explore the impact of various parameters on DSM throughput by tuning cluster size, block size, and ILP. These parameters can guide task division in programming. We used the ring-based access pattern to evaluate the impact of different parameters. As shown in Fig.10, SM-to-SM throughput is illustrated for varying cluster and block sizes. As typically observed in similar benchmarks, when the block size is too small (e.g., 64), DSM performance is not fully utilized. However, increasing ILP can enhance SM-to-SM network utilization. When the block size is sufficiently large, ILP does not improve DSM performance. A peak throughput of nearly 3.28 TB/s is observed with a cluster size of 2, reducing to 2.78 TB/s with a cluster size of 4. Interestingly, as more blocks in the cluster compete for SM-to-SM bandwidth, the overall throughput gets lower and lower. While a larger cluster size can share shared memory for more blocks, it intensifies throughput competition. Balancing this tradeoff by selecting optimal block and cluster sizes is an important direction for exploration.
 Figure 10.The data communication throughput of the SM-to-SM network. “ILP” refers to the number of parallelizable data movement instructions.
7.3.Application-level
We select histogram as an application-level benchmark. Histograms are frequently employed in image processing and data mining to analyze the distribution of data elements by displaying the occurrence frequency of each element’s value. While GPUs can accelerate histogram computation, achieving high computational efficiency is challenging. We redesign the histogram††https://github.com/NVIDIA/cuda-samples/Samples/2_Concepts_and_Techniques/histogramapplication using DSM, distributing bins across blocks in the same cluster. During histogram counting via shared memory, each thread loads the element and determines the DSM address for the target bin, followed by an atomic increment operation. The histogram application has the following two characteristics: 1) The data access flow is many-to-one similar to broadcasting (shared memory in each block is accessed by multiple blocks). 2) Due to the randomness of input data, writes to shared memory may generate unpredictable bank conflicts, which keeps ILP at a relatively low level. We adjust cluster size, block size, and bin count, measuring element processing throughput.
 Figure 11.Performance of the histogram application with distributed shared memory. The throughput is measured by the number of processing elements per second. “CS” refers to the cluster size. “Nbins” refers to the number of histogram bins.The results shown in Fig.11can be summarized in two points. First, in addition to cluster size from 1 to 2, as cluster size increases, performance actually decreases. This reflects the broadcast-like access pattern degrading performance with larger clusters, corresponding to the results in Fig.9. Second, increasing block size can significantly improve throughput. This demonstrates how higher block sizes can compensate for low ILP scenarios, which corresponds to the results in Fig.10. These findings demonstrate how the fundamental DSM behavior patterns we identified can be used to predict and understand real application performance, providing practical guidance for optimizing DSM-based applications.
Beyond the instruction-to-application analysis, we observe that the optimal cluster size differs for various block sizes (CS=4 for block size 128, CS=2 for block size 512). This suggests that kernel configuration parameters should be carefully selected to maximize performance. Additionally, when using DSM, we achieve over 30% performance improvement compared to not using it (CS=1 for block size 512). Overall, choosing an appropriate cluster size eases the on-chip shared memory traffic by leveraging the SM-to-SM network resource, ultimately improving overall performance.
Insight1. DSM reduces inter-SM communication latency by 6.1×.2. DSM performance is highly dependent on access patterns. For broadcast-style access patterns, contention on shared memory can drastically degrade performance.3. Kernel configuration parameters (e.g., cluster size and block size) significantly impact DSM performance, and should be carefully selected in practical applications.
8.Dynamic Programming Instructions
NVIDIA offers DPX functions††https://docs.nvidia.com/cuda/cuda-c-programming-guide/index.html##dpxfrom CUDA 12 onward to accelerate dynamic programming code, enhancing programming ease. On the latest Hopper architecture, these functions are hardware-accelerated. In this section, we conduct both instruction-level and application-level benchmarks to comprehensively evaluate the potential and real-world performance of DPX.
8.1.Instruction-level
Our instruction-level test of DPX functions focuses on the instruction latency and throughput. For latency assessment, we utilize a thread to iteratively issue DPX functions, calculating their average latency. In the throughput test, we employ a block to repeatedly issue DPX functions, determining the DPX instruction throughput for each SM. To pinpoint the location of DPX acceleration hardware, we vary the number of launched blocks and observed the relationship between DPX throughput and the launched block count.
Fig.12show the throughput of the DPX functions on three tested GPUs. The latency data is provided in the supplementary materials, which are available online. Since the DPX of RTX4090 and A100 are software emulation, their performance is almost the same. What can be observed is that forreluinstructions, the performance of H800 is significantly better than the other two. For 16-bit operations, H800 also has significant acceleration, up to 13 times.
However, not all functions have acceleration effects on Hopper. For some simple operations (e.g.__viaddmax_S32, which accepts 3 signed integers(s1, s2, s3)and returnsmax(s1+s2,s3)), we find that the performance of the three devices is close. In fact, by observing the SASS code, we find that new instructions (VIMNMX) are used on Hopper. Compared with previousIMNMX, performance does not seem to improve significantly. But in general, the Hopper architecture with DPX hardware acceleration has better performance than the previous generation architecture.
Additionally,__vibmax_S32data is not available on RTX4090 and A100. The reason is that compilation optimization optimizes this function into a max instruction. If we want to prevent this optimization, throughput measurements will be greatly affected.
Another finding is that on H800, when the number of launched blocks is less than the number of SMs, the throughput of DPX functions is proportional to the number of blocks. When the number of blocks just exceeds an integral multiple of the number of SMs, the throughput plummets, gradually returning to the maximum level as the number of blocks increases. Maximum throughput occurs when the number of blocks is an integer multiple of the number of SMs. Therefore, we have enough reason to infer that the DPX acceleration unit is located at the SM level.
 Figure 12.Throughput of DPX functions on different devices
8.2.Application-level
This case study explores the application of DPX instructions to the Smith-Waterman algorithm(Smith et al., 1981), a classic dynamic programming algorithm used in bioinformatics. The Smith-Waterman algorithm finds optimal local alignments between two sequences and has wide-ranging applications in sequence alignment, genome analysis, and protein structure prediction. It employs dynamic programming by filling a two-dimensional matrix to compute the optimal local alignment score. Each matrix element represents the optimal local alignment score at corresponding positions within the two sequences. The matrix is filled recursively using a specific formula, ultimately yielding the optimal alignment.
The Smith-Waterman algorithm finds optimal local alignments between sequencesQ=(q0q1…qm−1)Q=(q_{0}q_{1}\dots q_{m-1})andS=(s0s1…sn−1)S=(s_{0}s_{1}\dots s_{n-1})using dynamic programming. The core recurrence relation, calculating the scoreH(i,j)H(i,j), is:
H(i,j)=max{H(i−1,j−1)+σ(qi−1,sj−1)E(i,j)F(i,j)0H(i,j)=\max\begin{cases}H(i-1,j-1)+\sigma(q_{i-1},s_{j-1})\\ E(i,j)\\ F(i,j)\\ 0\end{cases}whereσ\sigmais the substitution scoring function. Affine gap penalties are incorporated viaE(i,j)E(i,j)andF(i,j)F(i,j):
E(i,j)=max{E(i−1,j)−βH(i−1,j)−αE(i,j)=\max\begin{cases}E(i-1,j)-\beta\\ H(i-1,j)-\alpha\end{cases}F(i,j)=max{F(i,j−1)−βH(i,j−1)−αF(i,j)=\max\begin{cases}F(i,j-1)-\beta\\ H(i,j-1)-\alpha\end{cases}withα\alphaas the gap opening penalty andβ\betaas the gap extension penalty. The matrixHHis initialized with zeros along the first row and column. The optimal local alignment score is the maximum value inHH. This computation requiresO(mn)O(mn)time andO(min(m,n))O(\min(m,n))space.
We can see that the computation ofH(i,j)H(i,j)is well-suited for the__vimax3_datatype_reluinstruction. This instruction takes three numbers(s1, s2, s3)as input and returnsmax(s1, s2, s3, 0). The calculation ofE(i,j)E(i,j)andF(i,j)F(i,j)can benefit from the__viaddmax_datatypeinstruction, which takes three numbers(s1, s2, s3)and returnsmax(s1 + s2, s3). The Smith-Waterman algorithm primarily involves repeatedly calculatingHH,EE, andFF. Therefore, these DPX instructions can accelerate these key operations, making them highly suitable for optimizing the algorithm’s performance.
Our testing methodology is based on(Schmidt et al., 2024). We use the same code, data, and testing parameter configuration as described in(Schmidt et al., 2024). We use 20 protein sequences, with lengths ranging from 144 to 5478, as queries against a simulated databases. The database contains one million sequences, with fixed lengths 1024. Our results represent the average performance across all twenty queries. The performance metric for our experiments is GCUPS (Giga Cell Updates Per Second), representing the number of dynamic programming matrix cell updates performed per second.
Figure 13.Performance of the Smith-Waterman algorithm across various data typesTo further investigate the hardware acceleration benefits of DPX, we compare performance not only across different devices but also on the H800 running under both Ampere and Hopper virtual architectures. This comparison highlights Hopper’s dedicated acceleration support for DPX instructions. In addition to the 16-bit and 32-bit integer types supported by DPX, we also considered half-precision (half2) and single-precision (float) floating-point types. As shown in Figure13, best performance is achieved on the RTX 4090 using half-precision data, reaching 4987.4 GCUPS. This superior performance is attributable to the RTX 4090’s higher core clock speeds and greater number of SMs. A similar trend is observed for bothhalf2andfloatdata types, neither of which leverage DPX instructions.
For the data types supported by DPX, the performance with signed 32-bit integers (S32) follows a similar pattern: RTX 4090 > H800 > A100. ThisS32performance aligns with our instruction-level benchmark results, indicating a limited or even no performance gain from DPX for some 32-bit instructions. Furthermore, compiling the DPX function forcompute_80(without hardware acceleration) versuscompute_90(with hardware acceleration) shows no significant difference in performance forS32. However, for signed 16-bit integers (S16), the code generated withcompute_90performs significantly better, benefiting from Hopper’s hardware acceleration support for DPX instructions. This advantage over computecompute_80, A100, and RTX4090, is consistent with our instruction-level benchmarks, which demonstrate a significant performance improvement for 16-bit integer instructions on the Hopper architecture.
In summary, this application-level testing provides several insights into performance optimization for dynamic programming applications: 1) Using lower-precision data types, whether integer or floating-point, offers significant performance advantages on the Hopper architecture. Where the reduced precision satisfies the application’s data representation requirements, its use should be prioritized. 2) For architectures prior to Hopper, avoid usingS16as a data type unless memory constraints dictate otherwise. Due to the greater availability of hardware units for processing floating-point, prioritize floating-point data types when possible. 3) When considering DPX instructions, the results from instruction-level benchmarks can guide application performance optimization. Not all DPX instructions offer performance advantages on the Hopper architecture.
Insight1. More complex operations (e.g., those with more operands and ReLU operations) benefit more significantly from DPX instructions.2. The acceleration effect of 16-bit DPX instructions is more obvious, while some 32-bit operations have no acceleration effect.
9.Conclusion
This study presents a comprehensive evaluation of NVIDIA’s Hopper GPU architecture through multi-level benchmarking, revealing significant performance improvements and optimization opportunities. Our results demonstrate that Hopper’s memory subsystem achieves 2.6× higher L2 cache throughput compared to Ampere, while its innovative Distributed Shared Memory (DSM) reduces inter-SM communication latency by 6.1×. These enhancements are critical for memory-bound workloads in AI and high-performance computing.
The fourth-generation tensor cores show substantial gains when properly utilized. While backward-compatiblemmainstructions achieve only 62.9% of peak performance on average, the dedicatedwgmmainstructions fully unlock Hopper’s computational potential. Furthermore, the FP8 data type delivers 2× higher throughput than FP16 for large-scale operations, though its benefits diminish for smaller workloads due to conversion overhead.
Specialized hardware units like the TMA and DPX instructions further enhance performance. TMA enables efficient asynchronous execution, accelerating matrix multiplication by 50%, while DPX instructions improve dynamic programming workloads by up to 13× in microbenchmarks. Real-world applications, such as the Smith-Waterman algorithm, benefit significantly, achieving a 4.75× speedup with 16-bit integers.
These findings provide actionable insights for developers. To maximize Hopper’s performance, we recommend prioritizingwgmmaovermmainstructions, adopting FP8 for large-scale computations, leveraging DSM for efficient inter-SM communication, and utilizing DPX for dynamic programming tasks. Future work should explore optimal DSM configurations, precision-aware DPX optimizations, and the integration of TMA with other asynchronous execution features. Our research improves understanding of the latest architecture’s characteristics and performance, aiding in optimized algorithm design and application performance.
Acknowledgements.
This work was partially supported by the National Natural Science Foundation of China (No. 62302126), the Shenzhen Science and Technology Program (No. RCBS20221008093125065), Guangdong Provincial Key Laboratory of Novel Security Intelligence Technologies (2022B1212010005), the Hong Kong RIF grant (No. R6021-20), and the Hong Kong CRF grant (No. C2004-21G, No. C7004-22G).
References
- Abdelkhalik et al.(2022)Hamdy Abdelkhalik, Yehia Arafa, Nandakishore Santhi, and Abdel-Hameed A. Badawy. 2022.Demystifying the Nvidia Ampere Architecture through Microbenchmarking and Instruction-level Analysis. In2022 IEEE High Performance Extreme Computing Conference (HPEC). 1–8.
- Arafa et al.(2019)Yehia Arafa, Abdel-Hameed A Badawy, Gopinath Chennupati, Nandakishore Santhi, and Stephan Eidenbenz. 2019.Low overhead instruction latency characterization for nvidia gpgpus. In2019 IEEE High Performance Extreme Computing Conference (HPEC). IEEE, 1–8.
- Arafa et al.(2020)Yehia Arafa, Ammar ElWazir, Abdelrahman ElKanishy, Youssef Aly, Ayatelrahman Elsayed, Abdel-Hameed Badawy, Gopinath Chennupati, Stephan Eidenbenz, and Nandakishore Santhi. 2020.Verified instruction-level energy consumption measurement for nvidia gpus. InProceedings of the 17th ACM International Conference on Computing Frontiers. 60–70.
- Bakhoda et al.(2009)Ali Bakhoda, George L Yuan, Wilson WL Fung, Henry Wong, and Tor M Aamodt. 2009.Analyzing CUDA workloads using a detailed GPU simulator. In2009 IEEE international symposium on performance analysis of systems and software. IEEE, 163–174.
- Braun et al.(2020)Lorenz Braun, Sotirios Nikas, Chen Song, Vincent Heuveline, and Holger Fröning. 2020.A simple model for portable and fast prediction of execution time and power consumption of GPU kernels.*ACM Transactions on Architecture and Code Optimization (TACO)*18, 1 (2020), 1–25.
- Braun et al.(2021)Lorenz Braun, Sotirios Nikas, Chen Song, Vincent Heuveline, and Holger Fröning. 2021.A Simple Model for Portable and Fast Prediction of Execution Time and Power Consumption of GPU Kernels.ACM Transactions Architecture and Code Optimization18, 1, Article 7 (dec 2021), 25 pages.
- Cannon (1969)Lynn Elliot Cannon. 1969.A cellular computer to implement the Kalman filter algorithm.Montana State University.
- Chtchelkanova et al.(1997)Almadena Chtchelkanova, John Gunnels, Greg Morrow, James Overfelt, and Robert A van de Geijn. 1997.Parallel implementation of BLAS: General techniques for level 3 BLAS.Concurrency: Practice and Experience9, 9 (1997), 837–857.
- Corporation (2023)NVIDIA Corporation. 2023.CUDA Documentation: Parallel Thread Execution.https://docs.nvidia.com/cuda/parallel-thread-execution/index.html
- Dao et al.(2022)Tri Dao, Dan Fu, Stefano Ermon, Atri Rudra, and Christopher Ré. 2022.Flashattention: Fast and memory-efficient exact attention with IO-awareness.Advances in Neural Information Processing Systems35 (2022), 16344–16359.
- Fan et al.(2019)Kaijie Fan, Biagio Cosenza, and Ben Juurlink. 2019.Predictable GPUs frequency scaling for energy and performance. InProceedings of the 48th International Conference on Parallel Processing. 1–10.
- Fasi et al.(2021)Massimiliano Fasi, Nicholas J Higham, Mantas Mikaitis, and Srikara Pranesh. 2021.Numerical behavior of NVIDIA tensor cores.PeerJ Computer Science7 (2021), e330.
- Floridi and Chiriatti (2020)Luciano Floridi and Massimo Chiriatti. 2020.GPT-3: Its nature, scope, limits, and consequences.Minds and Machines30, 4 (2020), 681–694.
- Guerreiro et al.(2018)Joao Guerreiro, Aleksandar Ilic, Nuno Roma, and Pedro Tomas. 2018.GPGPU power modeling for multi-domain voltage-frequency scaling. In2018 IEEE International Symposium on High Performance Computer Architecture (HPCA). IEEE, 789–800.
- Guerreiro et al.(2019)João Guerreiro, Aleksandar Ilic, Nuno Roma, and Pedro Tomás. 2019.Modeling and decoupling the GPU power consumption for cross-domain DVFS.IEEE Transactions on Parallel and Distributed Systems30, 11 (2019), 2494–2506.
- Ho and Wong (2017)Nhut-Minh Ho and Weng-Fai Wong. 2017.Exploiting half precision arithmetic in Nvidia GPUs. In2017 IEEE High Performance Extreme Computing Conference (HPEC). IEEE, 1–7.
- Hong and Kim (2009)Sunpyo Hong and Hyesoon Kim. 2009.An analytical model for a GPU architecture with memory-level and thread-level parallelism awareness. InProceedings of the 36th annual international symposium on Computer architecture. 152–163.
- Hong and Kim (2010)Sunpyo Hong and Hyesoon Kim. 2010.An integrated GPU power and performance model. InInternational Symposium on Computer Architecture (ISCA).
- Jia et al.(2019)Zhe Jia, Marco Maggioni, Jeffrey Smith, and Daniele Paolo Scarpazza. 2019.Dissecting the NVidia Turing T4 GPU via microbenchmarking.arXiv preprint arXiv:1903.07486(2019).
- Jia et al.(2018)Zhe Jia, Marco Maggioni, Benjamin Staiger, and Daniele P Scarpazza. 2018.Dissecting the NVIDIA Volta GPU architecture via microbenchmarking.arXiv preprint arXiv:1804.06826(2018).
- Khairy et al.(2020)Mahmoud Khairy, Zhesheng Shen, Tor M. Aamodt, and Timothy G. Rogers. 2020.Accel-Sim: An Extensible Simulation Framework for Validated GPU Modeling. In2020 ACM/IEEE 47th Annual International Symposium on Computer Architecture (ISCA). 473–486.
- Kwon et al.(2023)Woosuk Kwon, Zhuohan Li, Siyuan Zhuang, Ying Sheng, Lianmin Zheng, Cody Hao Yu, Joseph E. Gonzalez, Hao Zhang, and Ion Stoica. 2023.Efficient Memory Management for Large Language Model Serving with PagedAttention. InProceedings of the ACM SIGOPS 29th Symposium on Operating Systems Principles.
- Leng et al.(2013)Jingwen Leng, Tayler Hetherington, Ahmed ElTantawy, Syed Gilani, Nam Sung Kim, Tor M. Aamodt, and Vijay Janapa Reddi. 2013.GPUWattch: Enabling Energy Optimizations in GPGPUs. InProceedings of the 40th Annual International Symposium on Computer Architecture(Tel-Aviv, Israel)(ISCA ’13). 487–498.
- Luitjens (2013)Justin Luitjens. 2013.CUDA Pro Tip: Increase Performance with Vectorized Memory Access.https://developer.nvidia.com/blog/cuda-pro-tip-increase-performance-with-vectorized-memory-access/.NVIDIA Technical Blog.
- Luo et al.(2024)Weile Luo, Ruibo Fan, Zeyu Li, Dayou Du, Qiang Wang, and Xiaowen Chu. 2024.Benchmarking and Dissecting the Nvidia Hopper GPU Architecture. In2024 IEEE International Parallel and Distributed Processing Symposium (IPDPS). 656–667.doi:10.1109/IPDPS57955.2024.00064
- Markidis et al.(2018)Stefano Markidis, Steven Wei Der Chien, Erwin Laure, Ivy Bo Peng, and Jeffrey S. Vetter. 2018.NVIDIA Tensor Core Programmability, Performance & Precision. In2018 IEEE International Parallel and Distributed Processing Symposium Workshops (IPDPSW). 522–531.
- Martineau et al.(2019)Matt Martineau, Patrick Atkinson, and Simon McIntosh-Smith. 2019.Benchmarking the NVIDIA V100 GPU and Tensor Cores. InEuro-Par 2018: Parallel Processing Workshops. Springer International Publishing, Cham, 444–455.
- Maslej et al.(2023)Nestor Maslej, Loredana Fattorini, Erik Brynjolfsson, John Etchemendy, Katrina Ligett, Terah Lyons, James Manyika, Helen Ngo, Juan Carlos Niebles, Vanessa Parli, et al.2023.Artificial intelligence index report 2023.arXiv preprint arXiv:2310.03715(2023).
- Mei and Chu (2017)Xinxin Mei and Xiaowen Chu. 2017.Dissecting GPU Memory Hierarchy Through Microbenchmarking.IEEE Transactions on Parallel and Distributed Systems28, 1 (2017), 72–86.
- Mei et al.(2017)Xinxin Mei, Qiang Wang, and Xiaowen Chu. 2017.A survey and measurement study of GPU DVFS on energy conservation.Digital Communications and Networks3, 2 (2017), 89–100.
- Mei et al.(2014)Xinxin Mei, Kaiyong Zhao, Chengjian Liu, and Xiaowen Chu. 2014.Benchmarking the memory hierarchy of modern GPUs. InNetwork and Parallel Computing: 11th IFIP WG 10.3 International Conference, NPC 2014, Ilan, Taiwan, September 18-20, 2014. Proceedings 11. Springer, 144–156.
- Nabavinejad et al.(2022)Seyed Morteza Nabavinejad, Sherief Reda, and Masoumeh Ebrahimi. 2022.Coordinated batching and DVFS for DNN inference on GPU accelerators.IEEE transactions on parallel and distributed systems33, 10 (2022), 2496–2508.
- NVIDIA (2022)NVIDIA. 2022.TransformerEngine.https://github.com/NVIDIA/TransformerEngine
- OpenAI ([n. d.])OpenAI. [n. d.].Introducing ChatGPT.https://openai.com/blog/chatgpt
- Paszke et al.(2019)Adam Paszke, Sam Gross, Francisco Massa, Adam Lerer, James Bradbury, Gregory Chanan, Trevor Killeen, Zeming Lin, Natalia Gimelshein, Luca Antiga, et al.2019.Pytorch: An imperative style, high-performance deep learning library.Advances in neural information processing systems32 (2019).
- Raihan et al.(2019)Md Aamir Raihan, Negar Goli, and Tor M. Aamodt. 2019.Modeling Deep Learning Accelerator Enabled GPUs. In2019 IEEE International Symposium on Performance Analysis of Systems and Software (ISPASS). 79–92.
- Saavedra and Smith (1995)R.H. Saavedra and A.J. Smith. 1995.Measuring cache and TLB performance and their effect on benchmark runtimes.*IEEE Trans. Comput.*44, 10 (Jan 1995), 1223–1235.doi:10.1109/12.467697
- Saavedra-Barrera (1992)RafaelHector Saavedra-Barrera. 1992.CPU performance evaluation and execution time prediction using narrow spectrum benchmarking.(Jan 1992).
- Schmidt et al.(2024)Bertil Schmidt, Felix Kallenborn, Alejandro Chacon, and Christian Hundt. 2024.CUDASW++ 4.0: ultra-fast GPU-based Smith–Waterman protein sequence database search.BMC bioinformatics25, 1 (2024), 342.
- Sergeev and Del Balso (2018)Alexander Sergeev and Mike Del Balso. 2018.Horovod: fast and easy distributed deep learning in TensorFlow.arXiv preprint arXiv:1802.05799(2018).
- Shazeer (2020)Noam Shazeer. 2020.GLU Variants Improve Transformer.arXiv: Learning,arXiv: Learning(Feb 2020).
- Shekofteh et al.(2020)S.-Kazem Shekofteh, Hamid Noori, Mahmoud Naghibzadeh, Holger Fröning, and Hadi Sadoghi Yazdi. 2020.cCUDA: Effective Co-Scheduling of Concurrent Kernels on GPUs.IEEE Transactions on Parallel and Distributed Systems31, 4 (2020), 766–778.doi:10.1109/TPDS.2019.2944602
- Smith et al.(1981)Temple F Smith, Michael S Waterman, et al.1981.Identification of common molecular subsequences.Journal of molecular biology147, 1 (1981), 195–197.
- Sun et al.(2023)Wei Sun, Ang Li, Tong Geng, Sander Stuijk, and Henk Corporaal. 2023.Dissecting Tensor Cores via Microbenchmarks: Latency, Throughput and Numeric Behaviors.IEEE Transactions on Parallel and Distributed Systems34, 1 (2023), 246–261.
- Svedin et al.([n. d.])Martin Svedin, Steven W. D. Chien, Gibson Chikafa, Niclas Jansson, and Artur Podobas. [n. d.].Benchmarking the Nvidia GPU Lineage: From Early K80 to Modern A100 with Asynchronous Memory Transfers. InProceedings of the 11th International Symposium on Highly Efficient Accelerators and Reconfigurable Technologies(Online, Germany)(HEART ’21). Article 9, 6 pages.
- Tang et al.(2019)Zhenheng Tang, Yuxin Wang, Qiang Wang, and Xiaowen Chu. 2019.The impact of GPU DVFS on the energy and performance of deep learning: An empirical study. InProceedings of the Tenth ACM International Conference on Future Energy Systems. 315–325.
- te42kyfo ([n. d.])te42kyfo. [n. d.].GPU benchmarks.https://github.com/te42kyfo/gpu-benches.
- Thakur et al.(2005)Rajeev Thakur, Rolf Rabenseifner, and William Gropp. 2005.Optimization of collective communication operations in MPICH.The International Journal of High Performance Computing Applications19, 1 (2005), 49–66.
- Touvron et al.(2023a)Hugo Touvron, Thibaut Lavril, Gautier Izacard, Xavier Martinet, Marie-Anne Lachaux, Timothée Lacroix, Baptiste Rozière, Naman Goyal, Eric Hambro, Faisal Azhar, et al.2023a.Llama: Open and efficient foundation language models.arXiv preprint arXiv:2302.13971(2023).
- Touvron et al.(2023b)Hugo Touvron, Louis Martin, Kevin Stone, Peter Albert, Amjad Almahairi, Yasmine Babaei, Nikolay Bashlykov, Soumya Batra, Prajjwal Bhargava, Shruti Bhosale, et al.2023b.Llama 2: Open foundation and fine-tuned chat models.arXiv preprint arXiv:2307.09288(2023).
- van Stigt et al.(2022)Rico van Stigt, Stephen Nicholas Swatman, and Ana-Lucia Varbanescu. 2022.Isolating gpu architectural features using parallelism-aware microbenchmarks. InProceedings of the 2022 ACM/SPEC on International Conference on Performance Engineering. 77–88.
- Vaswani et al.(2017)Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N Gomez, Łukasz Kaiser, and Illia Polosukhin. 2017.Attention is all you need.Advances in neural information processing systems30 (2017).
- Wang and Chu (2020)Qiang Wang and Xiaowen Chu. 2020.GPGPU Performance Estimation With Core and Memory Frequency Scaling.IEEE Transactions on Parallel and Distributed Systems31, 12 (2020), 2865–2881.
- Wang et al.(2024)Qiang Wang, Laiyi Li, Weile Luo, Yijia Zhang, and Bingqiang Wang. 2024.DSO: A GPU Energy Efficiency Optimizer by Fusing Dynamic and Static Information.arXiv preprint arXiv:2407.13096(2024).
- Wang et al.(2019)Xiebing Wang, Kai Huang, Alois Knoll, and Xuehai Qian. 2019.A Hybrid Framework for Fast and Accurate GPU Performance Estimation through Source-Level Analysis and Trace-Based Simulation. In2019 IEEE International Symposium on High Performance Computer Architecture (HPCA). 506–518.
- Wang et al.(2020)Yuxin Wang, Qiang Wang, Shaohuai Shi, Xin He, Zhenheng Tang, Kaiyong Zhao, and Xiaowen Chu. 2020.Benchmarking the performance and energy efficiency of AI accelerators for AI training. In2020 20th IEEE/ACM International Symposium on Cluster, Cloud and Internet Computing (CCGRID). IEEE, 744–751.
- Wong et al.(2010)Henry Wong, Misel-Myrto Papadopoulou, Maryam Sadooghi-Alvandi, and Andreas Moshovos. 2010.Demystifying GPU microarchitecture through microbenchmarking. In2010 IEEE International Symposium on Performance Analysis of Systems & Software (ISPASS). IEEE, 235–246.
- Yan et al.(2020a)Da Yan, Wei Wang, and Xiaowen Chu. 2020a.Demystifying Tensor Cores to Optimize Half-Precision Matrix Multiply. In2020 IEEE International Parallel and Distributed Processing Symposium (IPDPS). 634–643.
- Yan et al.(2020b)Da Yan, Wei Wang, and Xiaowen Chu. 2020b.Optimizing Batched Winograd Convolution on GPUs. InProceedings of the 25th ACM SIGPLAN Symposium on Principles and Practice of Parallel Programming(San Diego, California)(PPoPP ’20). 32–44.
- Zhang and Sennrich (2019)Biao Zhang and Rico Sennrich. 2019.Root Mean Square Layer Normalization.Neural Information Processing Systems,Neural Information Processing Systems(Dec 2019).doi:10.5167/uzh-177483
Appendix ASupplementary data and analysis
A.1.DPX instructions
 Figure 14.Latency of DPX functions on different devicesFig.14demonstrates the performance advantages of Hopper’s dedicated DPX hardware over software-emulated implementations. The H800 (Hopper) consistently shows the lowest latency across most DPX functions, while A100 and RTX4090 exhibit similar performance since both rely on software emulation. The most significant improvements occur in functions like__viaddmax_s16x2and certain vibmax operations, where Hopper achieves latency reductions of up to 70-80%. However, the performance gains vary across different functions and data types, with 16-bit operations generally showing more pronounced benefits. This is consistent with the throughput results presented in our main text.
A.2.Tensor Core
Difference betweenwgmmaandmma.Fig.15provides examples of bothmmaandwgmmainstructions, demonstrating mixed-precision capabilities.
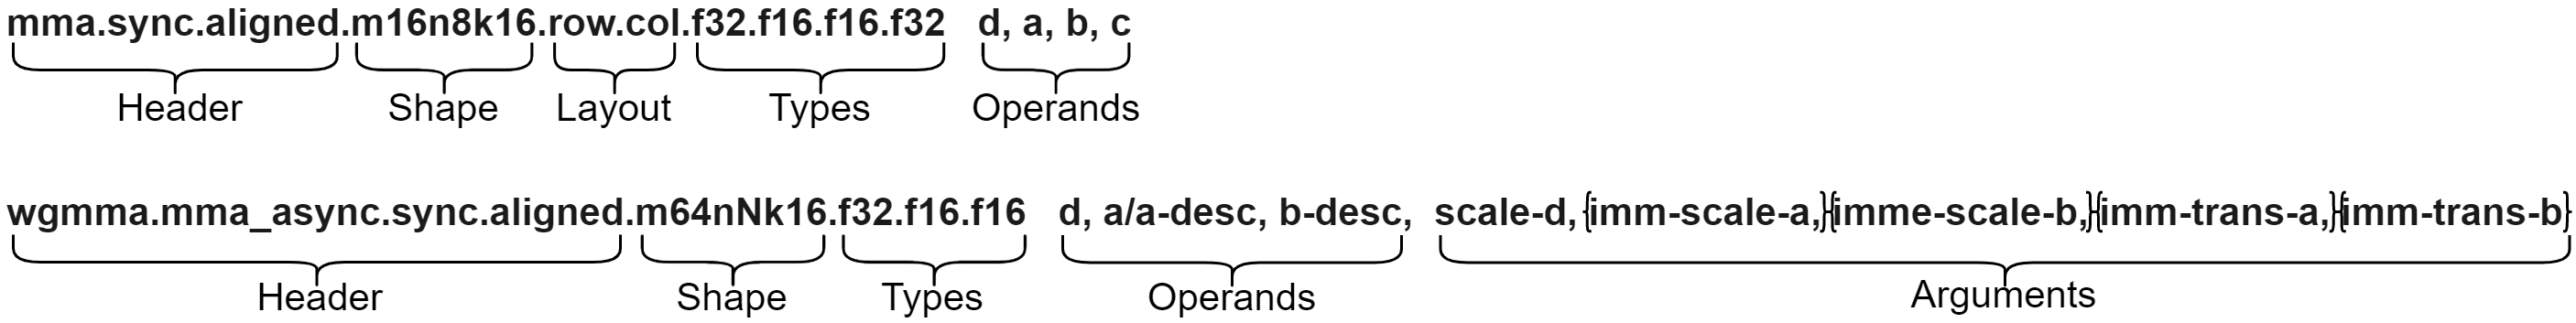 Figure 15.Themmaandwgmmainstructions that performD=A×B+CD=A\times B+CandD=A×B{+D}D=A\times B\{+D\}, respectively.Thewgmmainstructions implement warpgroup-level matrix multiply-and-accumulate operations through a structured six-step process shown in Listing1. First, matrices A, B, and D are loaded into registers or shared memory. Next, fence operations ensure memory consistency:wgmma.fenceindicates data availability across the warpgroup. The core computation involves issuing asynchronous matrix operations usingwgmma.mma_asyncinstructions, which execute within the async proxy framework. These operations are then grouped usingwgmma.commit_groupto create a unified synchronization point. Finally, the system waits for wgmma-group completion, ensuring asynchronous matrix operations have finished executing before proceeding with subsequent computations. The transition frommmatowgmmarepresents a fundamental shift in programming paradigms. Whilemmainstructions operate at warp-level (32 threads),wgmmaextends operations to warpgroup-level (128 threads), requiring careful consideration of thread synchronization and data distribution patterns. This architectural evolution demands updated programming practices to fully exploit hardware capabilities.
1__global__voidwgmma_ptx(datatype*data,datatype*result){
2
3
4
5
6wgmma.fence.sync.aligned;
7wgmma.mma_async...
8wgmma.commit_group.sync.aligned;
9wgmma.wait_group.sync.alignedremaining_group_num;
10
11}
Listing 1:Programming Approach ofwgmmaSASS analysis.We perform the disassembly ofmmaandwgmmainstructions specifically for Hopper Tensor Cores, and the results are presented in Table14. Themmainstructions undergo compilation into SASS instructions, with the naming convention following the established patterns: HMMA (for floating-point types), IMMA (for integer types), and BMMA (for binary types). Notably, there are two specialized types withinmma: INT4 and FP8.
For INT4, on Ampere and Ada Tensor Cores,mmainstructions are compiled intoIMMA.16832.S4.S4instructions. However, a noteworthy deviation occurs on Hopper, where INT4mmainstructions are compiled into a series of IMAD instructions, which eventually run on the CUDA cores. This deviation results in performance that may fall short of the expected performance levels achievable with Tensor Cores. Additionally, whilemmaoperations support FP32 accumulate when the data type of matrices A/B are FP8,mmado not support FP16 accumulate. The compiled SASS code remainsHMMA.16816.F32in both the FP8/FP32 and FP16/FP32 cases.
The latestwgmmainstructions are currently exclusive to Hopper Tensor Cores, despite NVIDIA’s assertion that both Ada and Hopper feature fourth generation Tensor Cores. Unlikemma,wgmmainstructions are compiled into the newGMMASASS instructions. Users can program two variations of FP8 (E5M2 and E4M3) Tensor Cores usingwgmma. Notably, aswgmmadoes not have forward compatibility requirements likemma, it does not support the INT4 data type.
Table 14.SASS Instructions for Different Hopper Tensor Core PTX InstructionsA/BC/DmmawgmmaFP16FP16HMMA.16816.F16HGMMA.64x256x16.F16FP16FP32HMMA.16816.F32HGMMA.64x256x16.F32TF32FP32HMMA.1688.F32.TF32HGMMA.64x256x8.F32.TF32FP8FP16×\timesQGMMA.64x256x32.F16.E5M2.E5M2QGMMA.64x256x32.F16.E4M3.E4M3FP8FP32HMMA.16816.F32QGMMA.64x256x32.F32.E4M3.E4M3QGMMA.64x256x32.F32.E5M2.E5M2INT8INT32IMMA.16832.S8.S8IGMMA.64x256x32.S8.S8INT4INT32IMAD.MOV.U32×\timesBinaryINT32BMMA.168256.AND.POPCBGMMA.64x256x256.AND.POPCSparsewgmmaInstructions Performance.Table15presents the detailed performance characteristics of sparse wgmma instructions on H800 Tensor Cores, complementing the dense wgmma results shown in main text. While the dense instructions demonstrated consistent 128-cycle latency, the sparse variants exhibit slightly higher latency at 144 clock cycles in “SS“ mode due to the additional overhead of handling sparsity patterns.
Table 15.Different sparsewgmmaInstructions on H800 Tensor Cores. Latency (LAT) is measured in clock cycles. Throughput is measured in TFLOPS or TOPS/s.A/BC/DSparseLAT/Throughput (Zero)Throughput (Rand)InstructionSSRSSSRSFP16FP16sp.m64n256k32144.0/1308.0128.0/1472.01257.81362.3FP16FP32sp.m64n256k32144.0/1312.3128.0/1476.21194.31277.5TF32FP32sp.m64n256k16144.0/656.8128.0/735.4644.9721.7FP8FP16sp.m64n256k64144.0/2619.9128.0/2945.02588.62782.4FP8FP32sp.m64n256k64144.0/2622.8128.0/2931.02588.72722.3INT8INT32sp.m64n256k64144.0/2612.4128.0/2933.02593.92898.3Matrix Size Scaling Analysis.Figure 2 illustrates the execution time breakdown for FP8 matrix multiplication using te.Linear across different matrix sizes, demonstrating the performance scaling characteristics of low-precision operations. For the smaller matrix size (N=4096), overhead components dominate the execution profile, with “Other” operations consuming 44.9% and memory operations (Memcpy) accounting for 29.4% of total time, while kernel execution represents only 25.3%. In contrast, the larger matrix size (N=16384) exhibits dramatically improved efficiency, with kernel execution dominating at 84.7% of total time while overhead components are significantly reduced to 8.2% for “Other” and 7.1% for memory operations. This scaling behavior highlights how increased computational intensity at larger problem sizes enables te.Linear to achieve better utilization of tensor cores and amortize the fixed overhead costs, making low-precision formats particularly advantageous for large-scale matrix operations where compute-bound performance can be fully realized.
 Figure 16.Proportion of execution time for different operators when performing FP8 matrix multiplication usingte.Linear.
Similar Articles
@ZhihuFrontier: GPU programming changed because Tensor Cores became too fast to feed Zhihu contributor THU-PACMAN实验室 shared a sharp bre…
A detailed analysis of how NVIDIA GPU programming evolved from Volta to Blackwell, highlighting the shift from synchronous thread models to asynchronous dataflow and the challenges of feeding Tensor Cores. The article discusses new hardware features like TMA, TMEM, and tcgen05 MMA, and shows how modern kernels like FlashAttention-3 and FlashMLA exploit these changes for higher utilization.
@MichaelGannotti: https://x.com/MichaelGannotti/status/2074486390432149979
A full-stack evaluation of NVIDIA's Nemotron-3 Mamba-Transformer hybrid models on DGX Spark hardware, including architecture analysis, quantization (NVFP4), benchmark results, and introduction of the open-source smf-bench testing suite.
https://www.youtube.com/watch?v=aE0onltJlOo
This lecture introduces the flexible evolution of GPU architecture as a SIMD (vector/array) processor, discusses data parallelism, memory bank grouping, bank conflicts, serial bottlenecks, and the history of SIMD instructions (such as MMX), emphasizing how GPUs leverage data parallelism and deal with serial bottlenecks.
@charles_irl: https://x.com/charles_irl/status/2069113412869914944
详细介绍了针对语音克隆模型的W4A4 CUDA内核优化,通过INT4量化和融合LoRA,实现了比FP16快2.6倍的推理速度。
I tested the CMP170HX
A hands-on benchmark of Nvidia CMP170HX mining cards repurposed as 64GB VRAM AI inference accelerators, showing they can run large local LLMs like DeepSeek V4-Flash and gpt-oss-120B at useful speeds, with caveats around Ampere-class throughput and PCIe Gen2 x4 connectivity.