@Gorden_Sun: Viggle JST-2:一秒生成可探索的3D虚拟世界、角色和动作的AI模型 市面上的很多世界模型只盯着画面像素去学习,只能拼凑出表面长什么样,很难真正理解真实世界里的三维空间和物理规律。 为了解决这个问题,Viggle团队开发了全新的J…
摘要
Viggle发布JST-2模型,采用“物理原生”的Joint Space-and-Time架构,将世界表示为带空间位置与物理属性的3D原子,可在约1秒内以不到1美分的成本生成可交互探索的3D场景、带骨骼的角色及全身动作,支持API调用但暂未开源。
查看缓存全文
缓存时间: 2026/10/19 19:28
Viggle JST-2:一秒生成可探索的3D虚拟世界、角色和动作的AI模型
市面上的很多世界模型只盯着画面像素去学习,只能拼凑出表面长什么样,很难真正理解真实世界里的三维空间和物理规律。
为了解决这个问题,Viggle团队开发了全新的JST-2模型。这个模型把世界拆解成一个个带有空间位置和物理属性的“3D原子”,直接从底层学习物体的空间结构和运动规律。
速度非常快,只需要1秒钟、花不到1美分,就能生成出一个完整的3D场景,生成的场景直接在浏览器里就能打开,你可以随便拖动视角在里面逛,一边逛还能一边实时向外扩建新的区域。如果上传几张真实房间的照片,它也能自动把照片里没拍到的死角补全,还原出一个完整的3D空间。
另外在做3D人物和动作上也很强:
· 角色自带骨骼,直接能动:你只需要输入文字或者传一张人物图(哪怕图片被裁切过或者有遮挡也没关系),JST-2就能直接生成3D角色。由于生成时已经把运动变形的规律写了进去,省去了传统3D制作里繁琐的“绑骨骼”步骤,造出来的人直接就能动。 · 文字和视频直接转3D动作:你可以用文字描述动作,或者上传一段真人视频,它就能生成对应的全身3D动作(连被遮挡的身体部位和精细的手指动作都能推算出来)。这些动作不用额外调整就能直接套在生成的角色身上,也能兼容标准的3D软件骨骼。
模型未开源,可以在线使用或API调用,实际应用于生产,还得再多些验证。
官方介绍:https://viggle.ai/jst2
Introducing Viggle JST-2
Source: https://viggle.ai/jst2
Worlds with scenes, characters, and motion
Scenes, characters, and motion generated with JST-2.
A physics-native architecture
JST, short for Joint Space-and-Time, models the world as persistent atoms in 3D space. Each atom represents a piece of matter or an object part and retains its identity as it moves and deforms. It has an explicit xyz position and learned vectors for its attributes and dynamics. We encode these atoms as Physics-Native Tokens.
We built the full stack for this fundamentally new architecture from the ground up, including its encoder, generator, and decoder, physics-native data synthesis engine, and pre- and post-training pipelines. The same world representation can be inferred from real-world observations or generated from a prompt.
Multimodal promptJST generatorJST decoderImage outputImage inputJST encoderPersistent atoms in 3D spaceMotion / force3D Gaussian splatsViewpointPhysics-Native TokenPositionExplicit xyz·0.46, 0.40, 0.34AttributesLearned vectorDynamicsLearned vectorStart with images
Start with one or more input images of a scene. Tap the images to explore the encoder path.
Encode images as tokens
The JST encoder maps images to Physics-Native Tokens representing persistent atoms in 3D space.
Persistent atoms in 3D space
Each persistent atom represents a piece of matter or an object part. Its Physics-Native Token contains:
Position(xyz)0.46, 0.40, 0.34AttributesLearned vectorDynamicsLearned vector
Or start from a prompt
The JST generator produces Physics-Native Tokens from a multimodal prompt. Tap the card to explore the generator path.
Pick a viewpoint
Drag the camera around the room. The JST decoder uses this viewpoint to produce an image of the decoded scene.
Decode, with motion or force
The decoder uses motion or force inputs to predict changes in position and attributes. Drag the puck to explore this input.
An image, or 3D splats
The JST decoder produces images or 3D Gaussian splats from the tokens. Tap either output to highlight its path.
The whole process
Everything at once. Drag the camera, push the puck, tap a source or an output.
Interactive architecture schematic. The JST encoder maps images to Physics-Native Tokens that represent persistent atoms in 3D space. The JST generator produces these tokens directly from multimodal prompts. The JST decoder uses the tokens, together with viewpoint and motion or force inputs, to produce images or 3D Gaussian splats.We founded Viggle in 2022 and spent the first two years developing JST-1. JST-1 validated the architecture on character generation and animation. It powered Viggle’s meme-making app, which has since reached 50M+ users.
We’ve loved seeing people use it to make each other laugh. Thank you for creating with us and sharing the feedback that helps us keep improving the model.
Building on that work, we developed JST-2 from 2024 to 2026. It demonstrates the generality of the JST architecture across scene, character, and motion generation. The representation supports both spatial structure and change over time.
Scene generation at interactive speed
JST-2 generates a 3D scene in about one second, at an inference cost below $0.01. Its feed-forward architecture produces the 3D representation directly, without per-scene optimization.
JST-2 generates a scene in about one second, enabling interactive world building and expansion.Timing covers model inference on NVIDIA B200, excluding network latency.### Explore and expand
JST-2 supports up to 64 input views as a spatial context window. As you expand a world one view at a time, each new view adds to the context for what comes next.
JST-2 decodes its Physics-Native Tokens into 3D Gaussian splats for local browser rendering. Once generated, the 3D scene can be explored repeatedly from different viewpoints without rerunning the model. Model inference is needed when new content is generated.
JST-2’s fast generation enables you to expand scenes from new viewpoints in real time.Try making your own### Modeling the real world
JST-2 reconstructs complete 3D environments from sparse real-world observations, preserving both their structure and appearance. This offers a way to build and expand robot simulation environments from real places, with potential applications in autonomous driving, mapping, and construction.
From sparse visual input, JST-2 reconstructs complete, visually faithful 3D worlds where point-cloud reconstructions capture only rough geometry. At novel viewpoints the model has never seen, the generated views closely match the real environment in both structure and appearance.Upcoming releases will let you use text prompts to guide what appears as you expand a scene. We are also preparing a version with more Gaussian splats per scene for finer visual detail.
Characters with motion built in
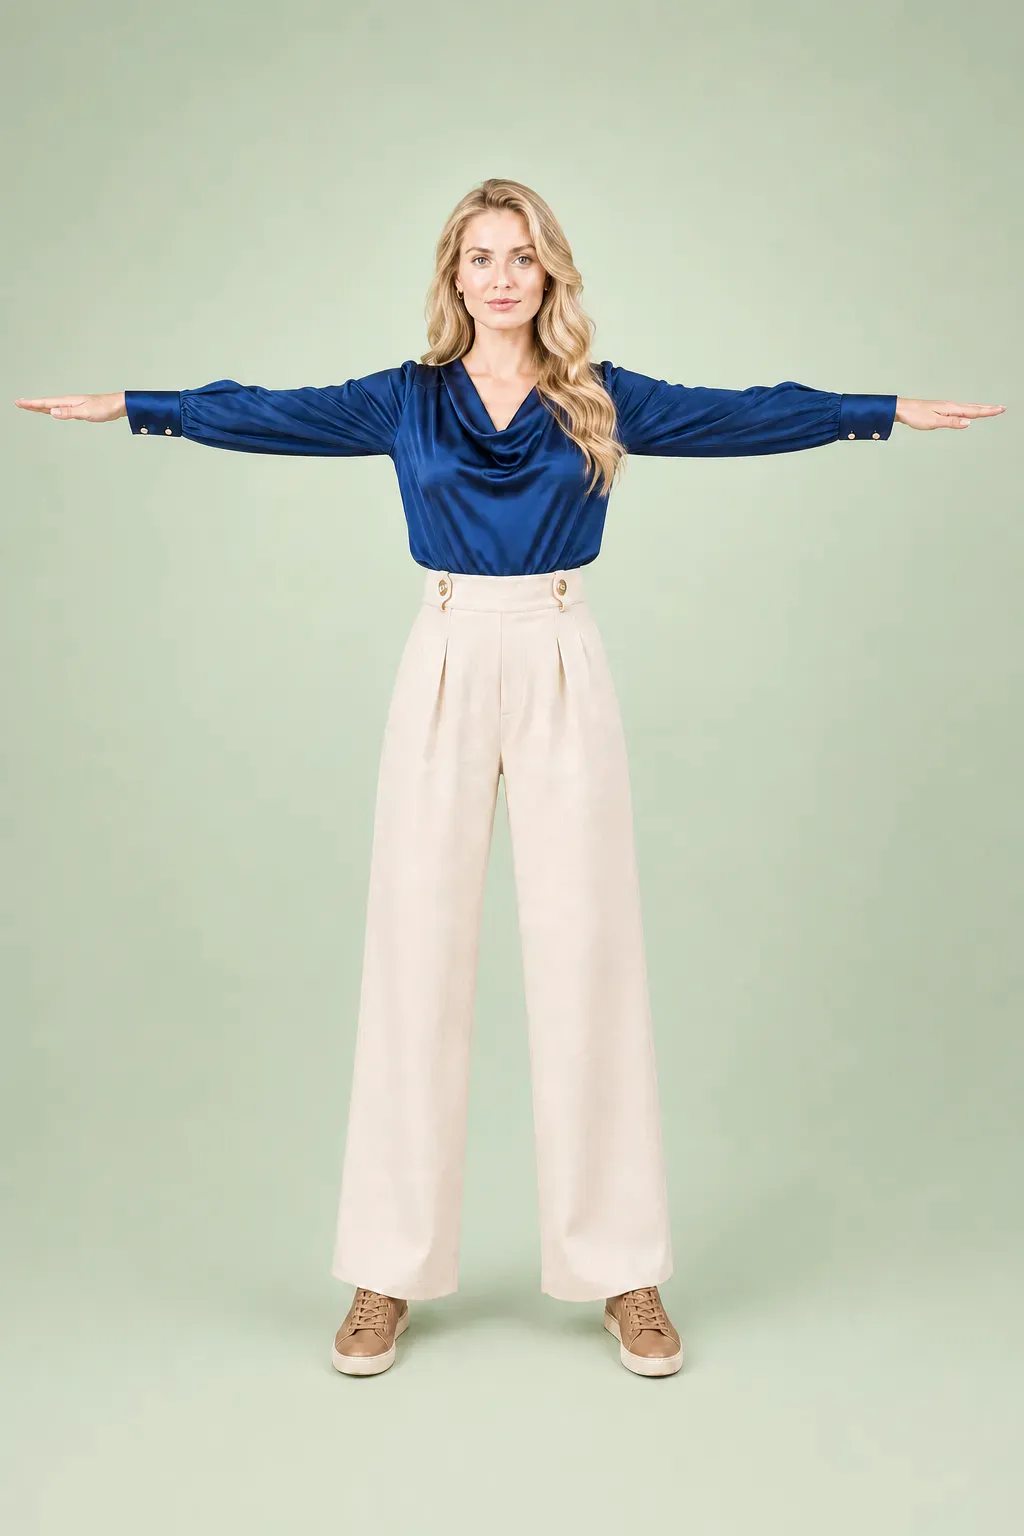
JST-2 generates 3D characters from a single image, ready to animate without a separate rigging step.Try making your own
JST-2 generates 3D characters from text or images with motion dynamics built in. The dynamics vectors in their Physics-Native Tokens encode how each part deforms under different motions. These dynamics are learned from data, so characters are ready to animate without separate rigging and skinning steps.
JST-2 can also generate complete characters from cropped or partially occluded images, across a wide range of visual styles.
Human evaluators compared JST-2 with Meshy 7.1 and Tripo H3.1 in blind tests.
JST-2 leads both baselines on character generation, with its strongest results on facial detail. These details help preserve the character’s identity in 3D.
Character generation
vsMeshy 7.1vsTripo H3.1Average Score58.4%
73.2%
Clothing quality55.7%
72.1%
Texture quality56.8%
70.8%
Body quality56.8%
74.2%
Face quality63.0%
82.0%
Overall Preference59.9%
66.9%
To evaluate animation readiness, we compared how each model’s generated characters move. JST-2 leads both baselines, particularly in hand articulation and how the body and clothing deform during motion.
Animation readiness
vsMeshy 7.1vsTripo H3.1Average Score73.8%
88.9%
Joint alignment65.6%
85.9%
Rig usability72.4%
86.2%
Deformation quality77.6%
93.2%
Hand rigging82.8%
89.3%
Overall Preference70.6%
89.6%
Average Score is the equal-weight mean of all criteria, including Overall Preference. Draws count as half a win. A score of 50% indicates equal preference between JST-2 and the comparison model.Upcoming releases will improve how complex clothing deforms during motion and how hair moves.
Read the Full Character Benchmark
Full-body 3D motion from text or video
Actions generated from text and full-body motion reconstructed from video.Prompt:“A person dodges quickly to the left, then ducks under an imaginary obstacle.”Try making your ownActions generated from text and full-body motion reconstructed from video.Prompt:“A person performs a quick forward roll and returns to standing.”Actions generated from text and full-body motion reconstructed from video.Prompt:“A person kicks forward with the right leg, retracts it, and regains balance.”Actions generated from text and full-body motion reconstructed from video.Prompt:“A person performs a simple hip-hop groove with shoulder bounces and footwork.”Actions generated from text and full-body motion reconstructed from video.Prompt:“A person performs a ballet pirouette and finishes with arms extended.”Actions generated from text and full-body motion reconstructed from video.Prompt:“A person performs a robot dance with stiff segmented arm and torso movements.”Actions generated from text and full-body motion reconstructed from video.Prompt:“A person boxes with quick footwork, throwing a jab and cross.”Actions generated from text and full-body motion reconstructed from video.Prompt:“A person walks in a small circle while scanning the surroundings.”Actions generated from text and full-body motion reconstructed from video.Prompt:“A person opens an imaginary door, steps through, and closes it behind them.”Actions generated from text and full-body motion reconstructed from video.Prompt:“A person brushes their teeth with small repeated arm movements.”Actions generated from text and full-body motion reconstructed from video.Prompt:“A person types rapidly on an imaginary keyboard while leaning forward.”Actions generated from text and full-body motion reconstructed from video.Prompt:“A person points straight ahead with the right index finger and leans into the gesture.”Actions generated from text and full-body motion reconstructed from video.Source video by@builtbyzay·TikTokActions generated from text and full-body motion reconstructed from video.Source video by@guavayogaa·TikTokActions generated from text and full-body motion reconstructed from video.Source video by@naruto0919·TikTokActions generated from text and full-body motion reconstructed from video.Source video by@aleks_kost·TikTokActions generated from text and full-body motion reconstructed from video.Source video by@crossfitjaakarhu·YouTubeActions generated from text and full-body motion reconstructed from video.Source video by@ericdaryl·YouTubeActions generated from text and full-body motion reconstructed from video.Source video by@mahdi.ibray·TikTokActions generated from text and full-body motion reconstructed from video.Source video by@jerseyyjoe·TikTokActions generated from text and full-body motion reconstructed from video.Source video by@official_giubti·TikTokActions generated from text and full-body motion reconstructed from video.Source video by@brookebuschkuehl·TikTokActions generated from text and full-body motion reconstructed from video.Source video by@glasseater286·TikTokActions generated from text and full-body motion reconstructed from video.Source video by@AdrienRaza·YouTube JST-2 generates full-body 3D motion from text or video. For video inputs, it reconstructs visible movement and uses learned dynamics to infer how unseen parts of the body move.
JST-2 motions can be applied directly to JST-2 characters, without a separate retargeting step. They are also natively compatible with standard 3D character rigs. Together with generated scenes, these characters and motions form the worlds shown above.
Human evaluators assessed both tasks in blind comparisons. All clips were played on the same untextured MetaHuman rig, keeping the comparison focused on motion rather than appearance.
For text-to-motion, JST-2 leads both baselines across the evaluated criteria. The model performs particularly well on hand gestures and dance, following the intent of the prompt while producing natural, continuous movement.
Text-to-motion
vsCartwheel SwingvsHY-Motion-1.0Average Score74.8%
80.0%
Prompt following65.8%
76.5%
Motion quality79.8%
80.2%
Foot contact73.0%
80.7%
Overall Preference80.7%
82.8%
JST-2 leads both video-to-motion baselines overall. The reconstructed 3D motion retains the source performance’s rhythm and changes of speed, along with fine hand and finger movements.
Video-to-motion
vsCartwheel Comic 4vsDeepMotion Animate 3DAverage Score58.1%
89.1%
Motion accuracy56.7%
90.9%
Complex / Fast56.0%
86.2%
Motion smoothness57.1%
82.8%
Hand tracking57.9%
95.0%
Overall Preference62.5%
90.6%
Average Score is the equal-weight mean of all criteria, including Overall Preference. Draws count as half a win. A score of 50% indicates equal preference between JST-2 and the comparison model.Upcoming releases will reconstruct a person’s path through the scene from video, alongside their body motion. We will also improve motion accuracy.
Read the Full Motion Benchmark
JST-3: toward learned physics
In JST-2, character motion is driven by learned dynamics. Scene collisions and object interactions still rely on rule-based physics. We are developing JST-3 to replace those rules with learned dynamics that predict how objects interact and how those interactions change the world.
Our goal is to build an experience engine for physical AI, where agents learn by acting in simulated worlds and observing the consequences.
ViggleAI (@ViggleAI): Today we are releasing JST-2, the world’s first full-stack physics-native world foundation model.
Many world models learn in pixel/video space. We went back to first principles and built the entire model stack in 3D.
Generate a 3D scene in seconds and expand it in real
相似文章
@Saccc_c:继 Jev 之后,我强烈建议大家密切关注这款新发布的大模型 Glimpse——它成功地……
Elorian AI 发布首个视觉思考大模型 Glimpse,主打视频/图像的空间结构与动态理解,作者实测其在游戏验收与漏洞检测中的表现显著优于 Astra,并已开放 API,可集成进 Codex 等开发流程。
@svpino:你可以给这个模型看一张图片或一段视频,它就能回答你关于它的任何问题。这远远超越了前沿模…
Andrew M. Dai 引用介绍了 Glimpse——首个视觉思考模型,能够理解图像与视频中的物体关系及随时间变化的动作,性能可与前沿模型 Astra 相媲美。
学习在三维世界中思考与探索
ACT3D 训练视觉-语言模型通过强化学习在 3D 环境中主动探索,仅凭单一第一人称视角即可在六个 3D 基准上达到 53.2% 平均准确率,较基座 Qwen 提升 22.0% 并超越 Gemini 3.6 Flash。
Meet Helix World: A Real-Time Audio-Visual World Model (13 minute read)
Noiz AI 与香港科技大学联合发布 Helix World,一个基于单张图像的实时交互式视听世界模型,可在单块 NVIDIA H800 GPU 上以 24fps 同时生成可探索的视频场景与空间立体声,代码、checkpoint 和在线 demo 均已开源。
Viggle/Viggle-Animate
Viggle-Animate 是一款 AI 模型,仅使用单张重绘帧即可替换视频中的角色,无需复杂的中间表示,即可实现高效准确的动作迁移。